
Datasets:

Access MM-Dia-Bench
Please review and accept the MM-Dia EULA to access this dataset.
By requesting access, you confirm that you have read and agree to the MM-Dia EULA and will use the dataset only for permitted non-commercial research or educational purposes.
Log in or Sign Up to review the conditions and access this dataset content.
MM-Dia-Bench

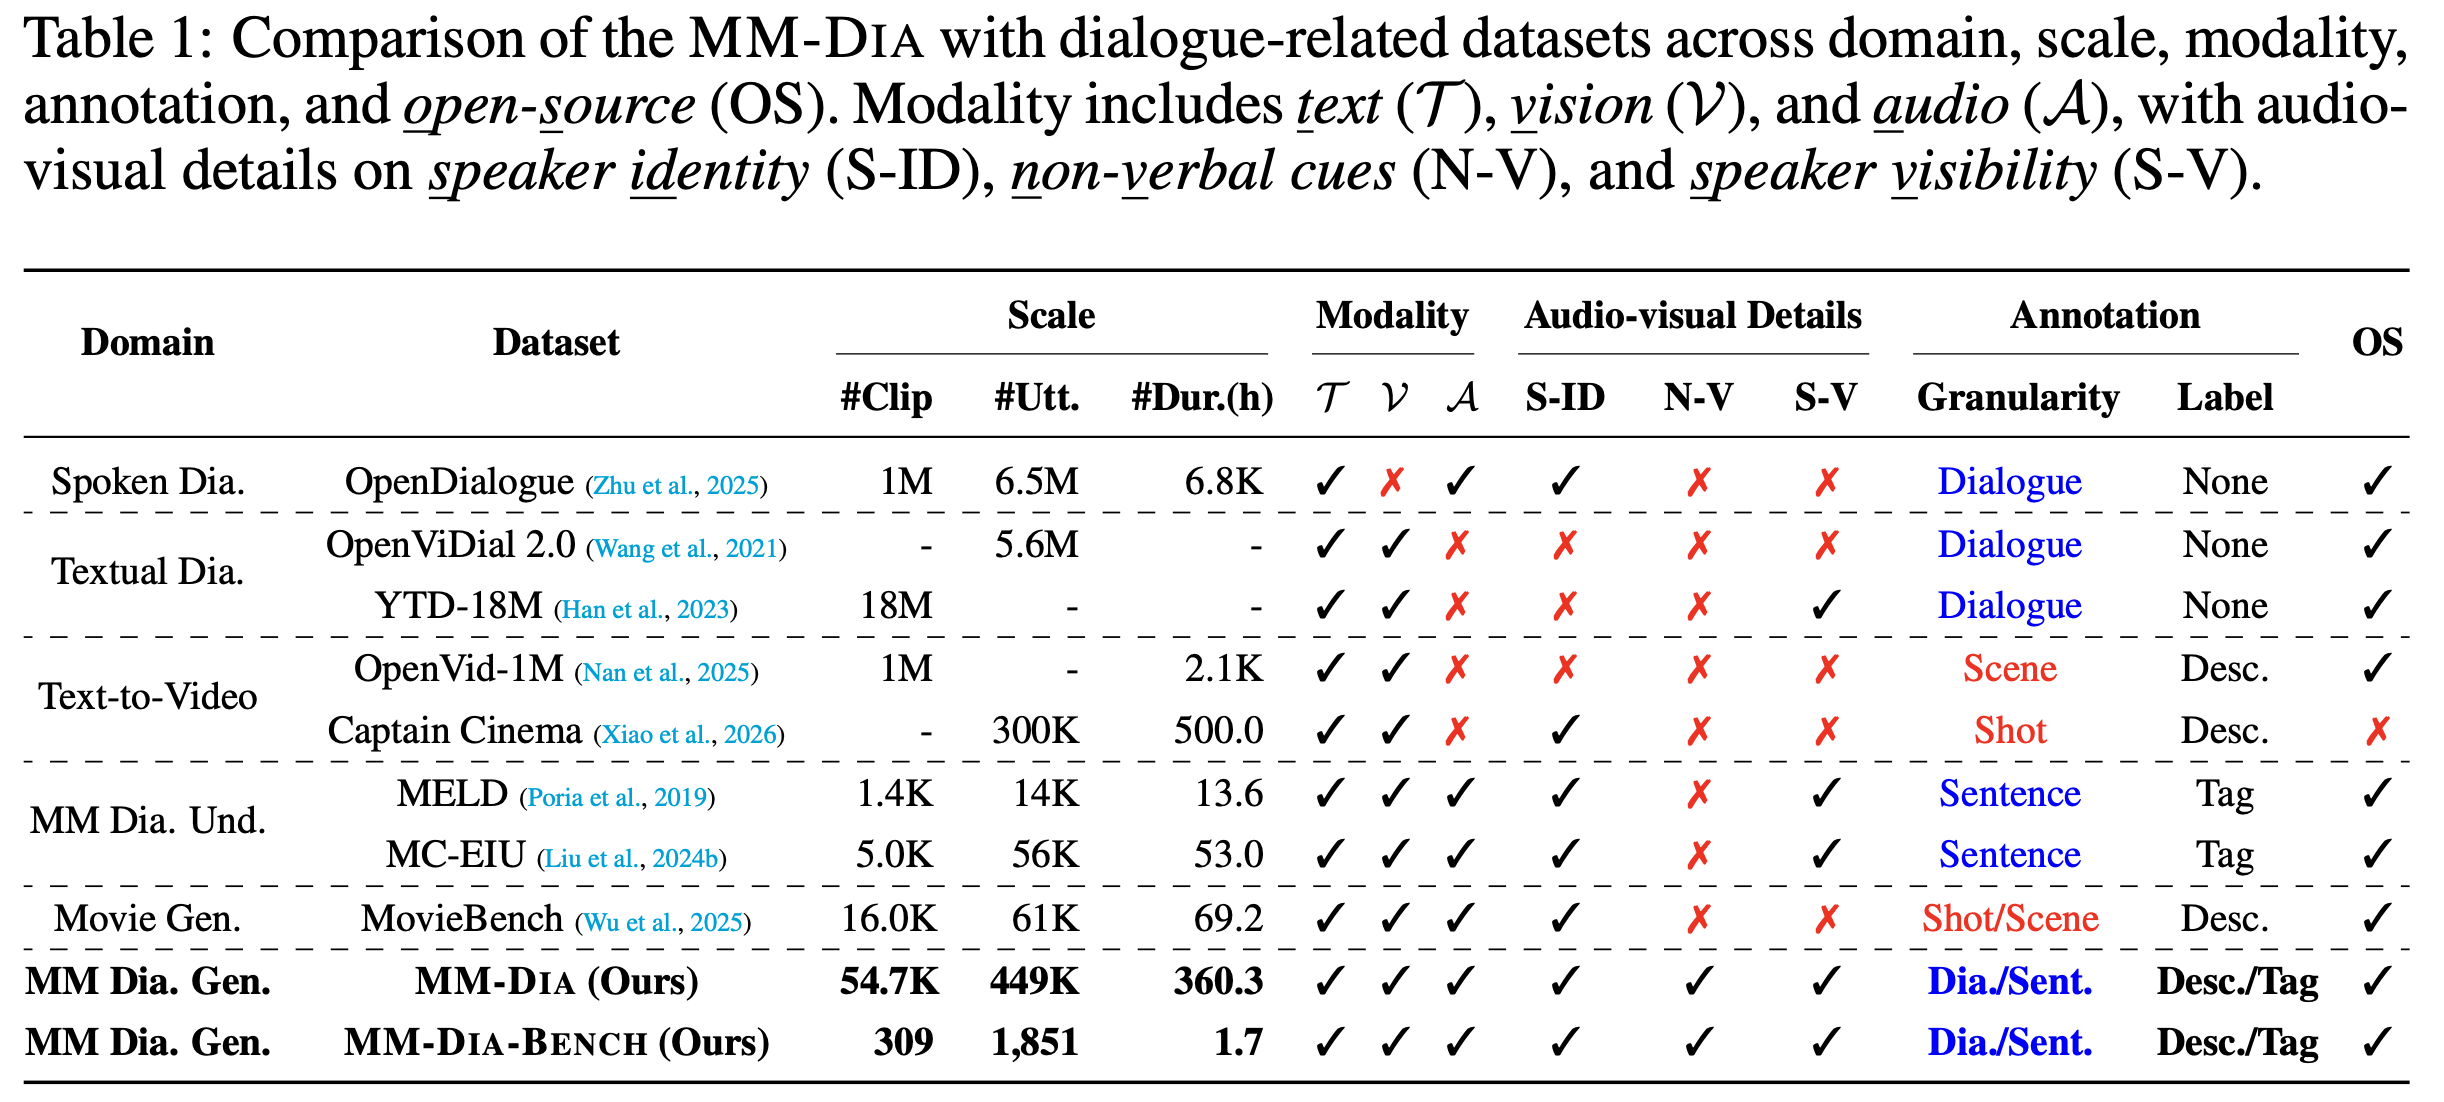
MM-Dia-Bench is the evaluation subset introduced with the ICLR 2026 paper “From Natural Alignment to Conditional Controllability in Multimodal Dialogue.” It contains 309 expressive dialogues with complete speaker visibility and directly provides aligned annotations, WAV audio, and MP4 video. It is backed by the larger MM-Dia dataset, which provides the full training resource.
Dataset Summary
| Statistic | MM-Dia-Bench |
|---|---|
| Dialogues | 309 |
| Speaking turns | 1,851 |
| Total duration | 1.69 hours |
| Average speakers per dialogue | 2.00 |
| Average duration per dialogue | 19.69 seconds |
| Average turns per dialogue | 5.99 |
| Speaker visibility | All |
Data Modalities
- Annotations: transcripts, timestamps, speakers, style descriptions, Affective Triplets, expressiveness scores, and visual alignment metadata.
- Audio: ready-to-use WAV dialogue clips.
- Video: aligned MP4 dialogue clips with visible speakers.
Annotation Contents
| Level | Main contents |
|---|---|
| Utterance | Text, timestamps, speaker identity, emotion, and non-verbal events |
| Dialogue | Style description, relationship, interaction mode, emotional tone, emotion intensity, and emotion-flow volatility |
| Visual alignment | Speaker visibility and audio-visual correspondence |
MM-Dia-Bench is designed for evaluating expressive multimodal dialogue systems, including cross-modal style consistency, vision-conditioned dialogue speech synthesis, and speech-driven dialogue video generation. It may also support related research in multimodal understanding and generation.
Benchmark Findings
Vision-Conditioned Dialogue Speech Synthesis
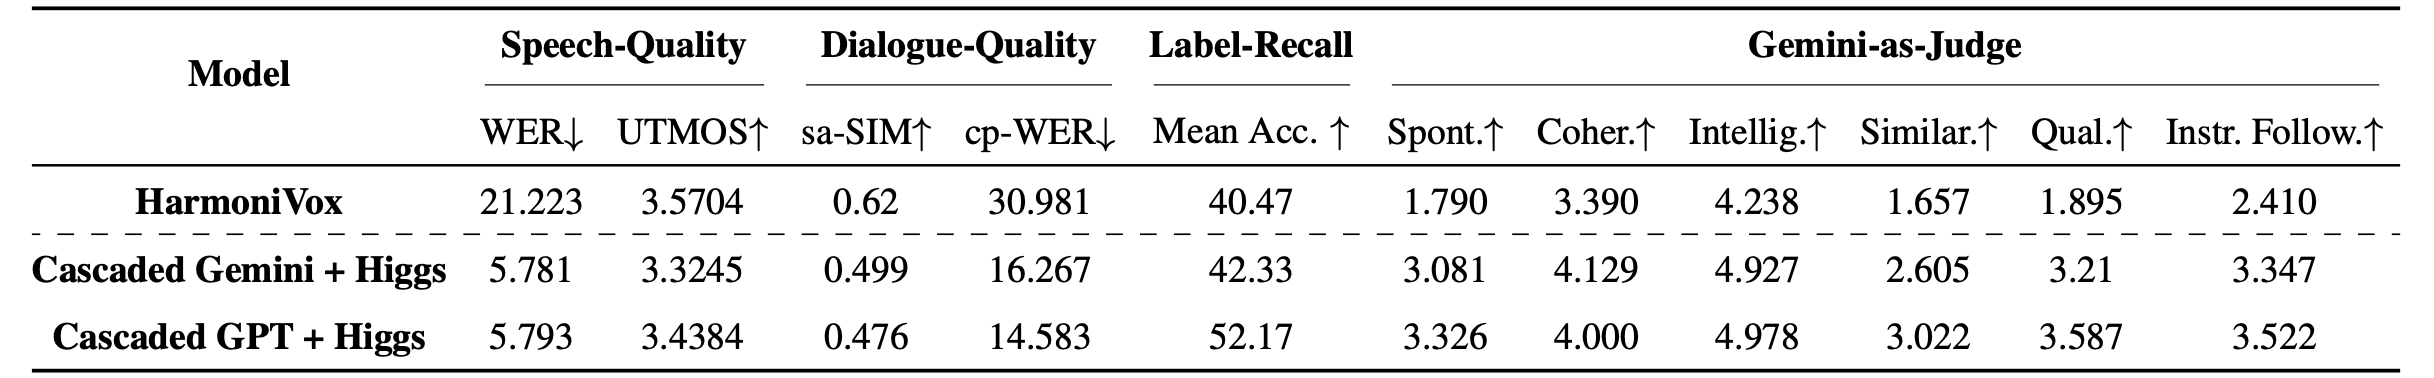
Cascaded systems substantially improve speech and dialogue quality, but style similarity and instruction-following scores remain limited, showing that fluent speech does not necessarily preserve the speaking style implied by visual context.
Speech-Driven Dialogue Video Generation
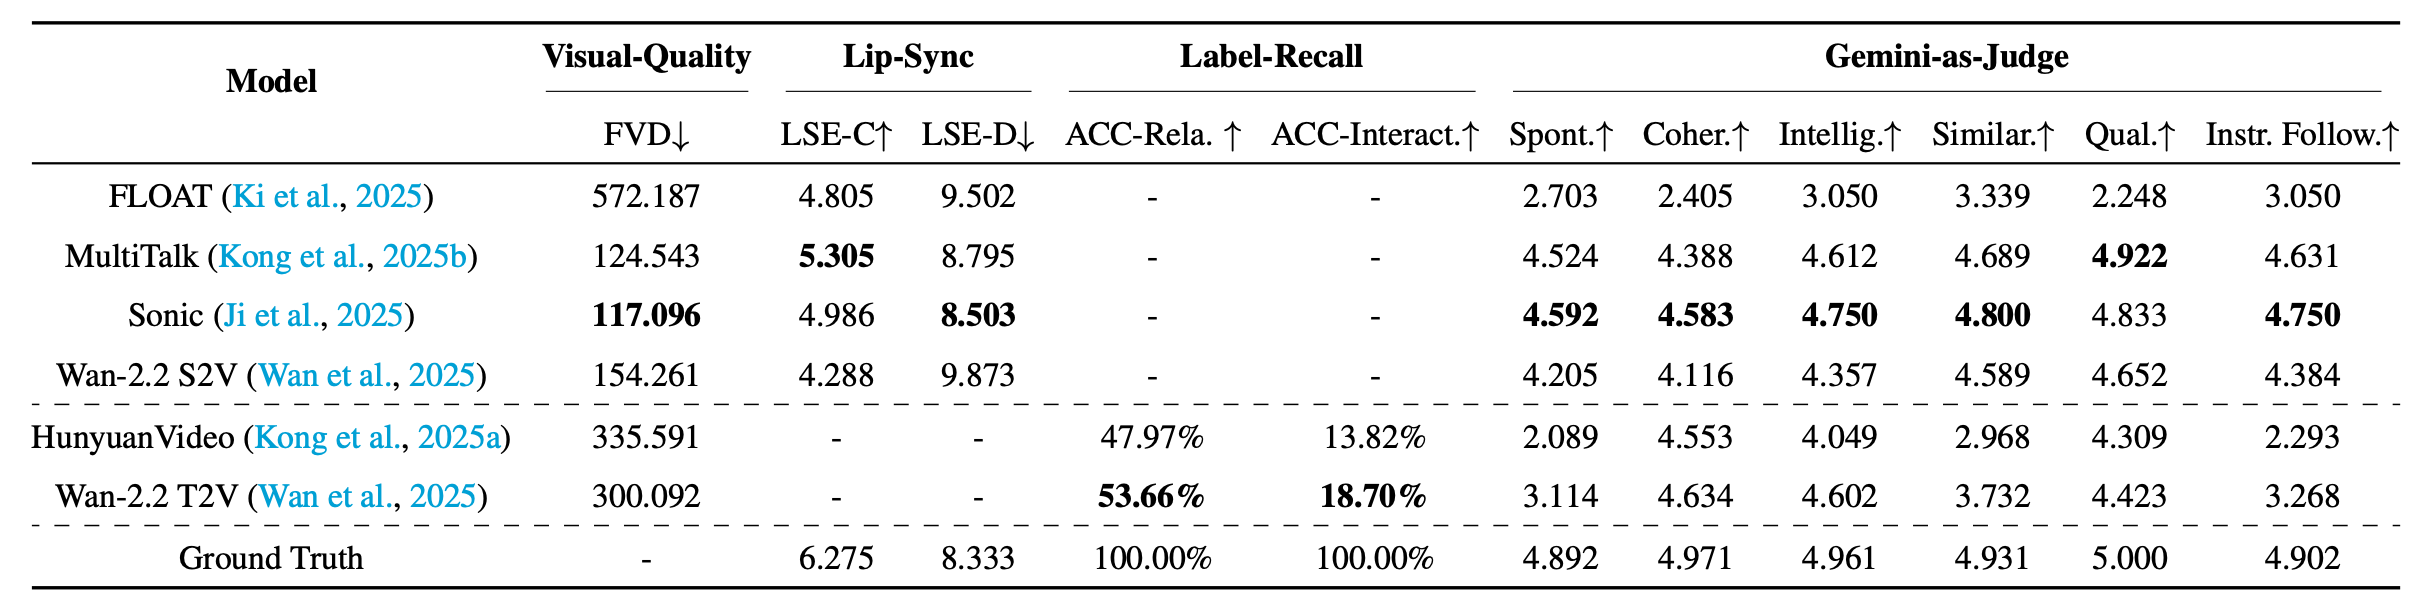
Current video-generation systems remain far from reproducing complete dialogue interactions. Visual quality alone does not ensure correct interpersonal dynamics or cross-modal style consistency.
Access and Download
MM-Dia-Bench is an automatically approved gated dataset. Before access is granted, users must accept the MM-Dia EULA. Use is limited to the purposes permitted by the EULA, including non-commercial research and education.
After approval, download the repository with:
hf auth login
hf download jessyjin/MM-Dia-Bench \
  --repo-type dataset \
  --local-dir MM-Dia-Bench
License and Responsible Use
Copyright in the underlying movies and TV series remains with their respective rights holders. We do not claim ownership of the source media. Rights holders may contact jinzeyu23@mails.tsinghua.edu.cn to request review and removal of affected material.
The dataset must not be used for identity impersonation, deceptive media generation, surveillance, harassment, or other harmful applications.
Citation
@inproceedings{jin2026mmdia,
  title     = {From Natural Alignment to Conditional Controllability in Multimodal Dialogue},
  author    = {Jin, Zeyu and Zhou, Songtao},
  booktitle = {International Conference on Learning Representations},
  year      = {2026}
}
For code and updates, visit the MM-Dia GitHub repository.
- Downloads last month
- 318