

Data Science and Technology Towards AGI Part I: Tiered Data Management
Paper • 2602.09003 • Published • 12
Parallel Constrained Decoding on unchanged openbmb/MiniCPM5-2B weights.
An experimental inference package for fast finite-choice classification and structured extraction.
No training, reinforcement learning, LoRA, quantization, or saved-weight modification was performed.
This is PCD inference, not TypeSafe/Jev RLCD training/calibration, DSpark, or a draft model.
On one L40S with FP32 inference, token PCD averaged 85.61 ms, versus 694.99 ms for direct-answer autoregressive JSON (8.1× faster) over 18 reused hand-authored cases. Token PCD achieved 88.9% field accuracy, versus 94.4% for AR JSON; exact-object accuracy was 72.2% versus 83.3%. Both produced 100% schema-valid objects on these cases. These are warm GPU request times, not network latency or an optimized-server comparison.
Accuracy equivalence is not established. On the six cases originally labeled audit, token accuracy was 77.8% versus 88.9% for AR JSON. Those cases are reused regression data, not a fresh MiniCPM holdout. Sequence PCD reached only 66.7% aggregate field accuracy. See all measurements, incorrect outputs, scaling probes, and limitations. Returned probabilities are uncalibrated; schema compliance does not mean the decision is true.
enable_thinking=False; prefill shared context once.token mode: one question branch per field, unique atomic option codes, and LM-head projection only onto allowed token rows. Map the chosen code back to the original enum string or Python boolean.sequence mode: score every complete serialized candidate with full-vocabulary normalized log-likelihood, including a newline terminator. Canonical token boundaries and shared-prefix factoring avoid first-token collisions. This mode retains length/wording bias and is not always faster or more accurate.Token mode normally uses two backbone calls for up to 32 fields. Sequence mode uses
1 + ceil(total_candidates / branch_batch_size). Parallelism reduces sequential steps;
it does not eliminate memory or compute costs. Fields are scored independently, not jointly.
Download code without immediately duplicating weight files:
GIT_LFS_SKIP_SMUDGE=1 git clone https://huggingface.co/monotykamary/MiniCPM5-2B-PCD
cd MiniCPM5-2B-PCD
uv venv --python 3.11
uv pip install --python .venv/bin/python -r requirements-pcd.txt
source .venv/bin/activate
from pcd.minicpm import MiniCPMEngine

schema = {
    "type": "object",
    "properties": {
        "topic": {
            "type": "string", "enum": ["billing", "technical", "shipping"],
            "description": "The main issue in the message",
        },
        "refund": {
            "type": "boolean", "description": "Whether a refund is explicitly requested",
        },
    },
    "required": ["topic", "refund"],
    "additionalProperties": False,
}
engine = MiniCPMEngine(device="cuda", dtype="float32", attention="sdpa")
result = engine.constrained("I was charged twice. Please refund the duplicate charge.", schema)
print(result["object"])  # Correct schema, but predictions can still be wrong.
print(result["fields"])  # Candidate scores, uncalibrated distributions, margins.
assert result["calibrated"] is False

# Optional slower scoring reference:
reference = engine.constrained("Please refund the duplicate charge.", schema, mode="sequence")
The default loads the pinned upstream commit
12a3808a956f869c767195e9266b59c4d21d92e2. To use the bundled weights, set
model_id="monotykamary/MiniCPM5-2B-PCD" and revision="main"; pin the public commit SHA
for reproducibility. A local snapshot path with revision=None also works.
Plain AutoModelForCausalLM.from_pretrained(...) remains the original generative model and
does not enable PCD. No trust_remote_code=True is needed.
Why FP32? BF16 and FP16 failed our cache/full-forward consistency checks on the actual model. We did not loosen the tolerances. FP32 passed, with candidate-score errors below 0.0001 on the validation example. Stored BF16 weights remain byte-for-byte unchanged; FP32 is a runtime cast. Typical measured allocated VRAM was approximately 9.6 GiB for three-field cases; larger schemas need more. This is a tested conservative configuration, not a claim that every low-precision generation workload is broken.
additionalProperties: false.Use a Modal account and the huggingface Secret for authenticated preparation/publication.
The supplied app uses the shared huggingface-cache Volume, a separate
minicpm5-2b-pcd-results Volume, at most one L40S, no minimum containers, and 30-second scale-down.
Preparation and upload run on CPU, not GPU. Nothing is deployed persistently by modal run.
modal run minicpm5_pcd_modal.py --task prepare
modal run --detach minicpm5_pcd_modal.py --task validate
modal run --detach minicpm5_pcd_modal.py --task benchmark --repeats 2
modal run --detach minicpm5_pcd_modal.py --task benchmark --suite stress --repeats 1
python -m pytest -q tests/pcd
The optional extract web endpoint requires Modal proxy authentication. Deploy explicitly only
if you want a service. The CPU publisher stages privately, verifies all files at a timestamped
preview tag, then makes the repository public only with --public. It refuses to overwrite an
existing repository. scripts/build_pcd_release.py --model minicpm5 checks report/source hashes.
Original model weights/config/tokenizer: Apache-2.0, copyright OpenBMB. The complete original
model documentation follows below and is preserved separately as UPSTREAM_README.md.
The HF snapshot did not contain a license file; LICENSE and
licenses/MiniCPM5-APACHE-2.0.txt contain the OpenBMB license linked by its original card.
Our inference/tooling code is MIT (LICENSE-CODE); cache/scoring attribution and license
provenance are in THIRD_PARTY_NOTICES.md. The source weights have not been retrained or changed.
BASE_MODEL_MANIFEST.json records upstream filenames, revision and SHA-256 hashes;
ARTIFACTS.json records the added source/docs/tests/evidence. No affiliation with OpenBMB,
LiquidAI, TypeSafe, or Jev is claimed. Upstream benchmark claims below refer to the original model,
not this PCD package.
The following upstream text is preserved verbatim. Its benchmarks describe the original model, not our PCD engine. Our measurements and limitations are documented above.
MiniCPM Tech Report | MiniCPM Wiki(Chinese) | GitHub Repo | UltraData | Online Demo
English | 中文
We are releasing MiniCPM5-2B, the second model in the MiniCPM5 series, following MiniCPM5-1B. It is a dense 2B Transformer that scales up the same training recipe, built for on-device, local deployment, and resource-constrained scenarios, reaching 2B-class open-source SOTA.
🏆 2B-class open-source SOTA: compared with strong open-source models of similar size, MiniCPM5-2B achieves SOTA performance within this comparison set. It remains competitive with 4B-class models overall, while showing its advantages over models of comparable size in coding, mathematics, long-context understanding, tool use, and agentic tasks.
📂 Open High-Quality Data: Alongside the model, we are releasing the high-quality training datasets behind it as part of the UltraData family: UltraX, a high-quality web pre-training dataset; UltraData-Code, featuring L0–L3 tiered code data management to drive a significant leap in coding capabilities; UltraData-SFT-Agent-2609, comprising 500K agent training samples to enhance comprehensive on-device agent capabilities; and UltraData-RL-2609, with 80K+ high-quality RL training samples covering mathematics, code, general knowledge, and long-context reasoning.
Use this directory to choose the model format that matches your runtime:
MiniCPM5-2B
MiniCPM5-1B
MiniCPM5-2B has the following features:
LlamaForCausalLMMiniCPM5-2B is the second model in the MiniCPM5 series. It is designed for local assistants, coding agents, tool-use workflows, and reasoning scenarios where a compact model is preferred. The model keeps a small deployment footprint while providing native long-context support.
We compare MiniCPM5-2B with strong open-source models in the same size class, including LFM2.5-2.6B, Qwen3.5-2B, and Gemma-4-E2B-it, while also listing larger models such as Qwen3.5-4B, granite-4.2-3B, Nemotron-3-Nano-4B, Gemma-4-E4B-it, and LFM2.5-8B-A1B for reference.
Within this comparison set, MiniCPM5-2B reaches 2B-class open-source SOTA with an average score of 53.9, and also exceeds all of the larger models included here (the highest is 51.1). Its advantages are most visible in code reasoning, math reasoning, long-context understanding, tool use, and multiple agentic tasks.
| MiniCPM5-2B | 2B-class Models | 4B-class Models | |||||||
|---|---|---|---|---|---|---|---|---|---|
| LFM2.5-2.6B | Qwen3.5-2B | Gemma-4-E2B-it | Qwen3.5-4B | granite-4.2-3B | Nemotron-3-Nano-4B | Gemma-4-E4B-it | LFM2.5-8B-A1B | ||
Average | 53.9 | 33.2 | 28.0 | 24.6 | 51.1 | 42.7 | 32.6 | 31.2 | 28.4 |
| Code Reasoning | |||||||||
LiveCodeBench v6 | 69.1 | 42.1 | 20.2 | 42.9 | 56.4 | 58.9 | 50.7 | 53.9 | 39.8 |
LCB-Pro 25Q2 (Easy) | 68.0 | 30.9 | 10.3 | 27.1 | 58.3 | 54.6 | 51.6 | 45.8 | 27.8 |
LCB-Pro 25Q2 (Medium) | 17.5 | 0.0 | 0.0 | 0.0 | 7.0 | 5.3 | 5.3 | 1.8 | 0.0 |
OJBench | 32.5 | 11.2 | 2.6 | 11.6 | 24.8 | 21.8 | 20.0 | 19.0 | 8.2 |
SciCode (wbg) | 26.3† | 14.2† | 2.8† | 20.9† | 16.1† | 24.9† | 16.4† | 24.4† | 7.8† |
| Math Reasoning | |||||||||
AIME 2025 | 86.5 | 41.9 | 29.6 | 31.7 | 78.8 | 79.4 | 56.3 | 37.1 | 46.0 |
AIME 2026 | 86.5 | 45.2 | 29.0 | 39.8 | 82.7 | 83.5 | 62.1 | 45.0 | 56.7 |
HMMT Feb 2026 | 63.8 | 33.7 | 20.5 | 17.8 | 64.0 | 60.8 | 51.3 | 30.1 | 38.5 |
MATH-500 | 94.6 | 89.6 | 85.8 | 85.4 | 99.0 | 97.0 | 91.6 | 88.2 | 93.2 |
| Instruction Following | |||||||||
IFBench | 66.3 | 59.0 | 46.0 | 25.7 | 59.0 | 73.0 | 58.3 | 28.3 | 51.0 |
IFEval | 86.7 | 93.4 | 77.5 | 31.4 | 90.2 | 93.7 | 88.0 | 44.4 | 90.8 |
Multi-IF | 71.8 | 76.8 | 57.1 | 40.3 | 73.6 | 75.9 | 65.9 | 45.9 | 71.4 |
| General Knowledge | |||||||||
MMLU-Pro | 70.8 | 65.2 | 64.3 | 56.0 | 78.0 | 65.8 | 65.7 | 68.3 | 63.1 |
MMLU-Redux | 84.7 | 80.0 | 80.0 | 71.8 | 88.7 | 78.9 | 79.8 | 83.7 | 80.0 |
HLE | 8.9† | 6.2† | 2.6† | 4.8† | 9.9† | 6.6† | 4.9† | 3.8† | 6.9† |
GPQA-Diamond | 70.2† | 55.8† | 45.6† | 43.3† | 77.1† | 55.9† | 51.3† | 57.6† | 51.3† |
SuperGPQA | 40.8 | 26.2 | 38.6 | 30.3 | 52.8 | 39.9 | 37.8 | 38.7 | 34.5 |
| Long Context | |||||||||
AA-LCR | 59.0† | 5.3† | 28.7† | 17.0† | 61.0† | 24.3† | 17.3† | 33.0† | 0.0† |
NoLiMa | 68.1 | 0.7 | 17.1 | 3.9 | 43.5 | 5.1 | 1.1 | 2.3 | 0.5 |
LongBenchPro | 44.8 | 23.7 | 8.2 | 42.2 | 58.4 | 34.8 | 27.9 | 53.5 | 19.6 |
LongBench v2 | 43.7 | 30.3 | 24.9 | 33.2 | 47.3 | 36.0 | 32.0 | 42.7 | 30.4 |
| Tool Use | |||||||||
τ³-Bench Banking | 20.8† | 7.2† | 2.1 | 3.9 | 6.8† | 5.6† | 1.2 | 4.1 | 3.4 |
τ²-Bench Telecom | 97.1 | 90.4 | 69.0† | 20.8† | 92.1† | 40.9 | 28.1† | 20.8† | 16.1† |
BFCL v4 | 66.6 | 61.1 | 43.6 | 36.6 | 56.8 | 52.2 | 43.7 | 47.0 | 49.2 |
| Coding Agent | |||||||||
SWE-bench Verified | 46.4 | 6.0 | 5.0 | 2.0 | 33.6 | 36.8 | 3.0 | 15.0 | 0.4 |
SWE-bench Pro | 14.4 | 0.6 | 0.8 | 0.0 | 28.2 | 12.3 | 0.1 | 3.3 | 0.4 |
Terminal-Bench v2.1 | 8.6† | 4.5† | 3.0† | 0.4† | 25.8† | 13.9† | 3.8† | 1.9† | 1.9 |
| Search Agent | |||||||||
BrowseComp-ZH | 43.5 | 9.8 | 18.2 | 4.7 | 39.6 | 21.1 | 3.3 | 7.0 | 13.2 |
BrowseComp Top100 | 39.7 | 13.7 | 19.3 | 6.0 | 33.3 | 19.0 | 4.7 | 6.3 | 9.7 |
GAIA Text-103 | 88.7 | 49.5 | 47.9 | 30.1 | 78.6 | 57.3 | 26.5 | 39.5 | 41.1 |
| General Agent | |||||||||
GDPval-AA v2 | 19.6† | 4.5 | 0.0 | 0.0 | 11.7 | 0.0† | 0.0 | 0.0 | 0.0 |
Claw-Gym | 59.2 | 19.3 | 25.5 | 31.3 | 51.6 | 60.0 | 33.7 | 37.9 | 2.7 |
WildClaw | 23.9 | 10.2 | 9.2 | 8.9 | 17.0 | 20.0 | 8.9 | 14.3 | 4.5 |
QwenClaw | 42.9 | 19.3 | 18.2 | 14.5 | 37.1 | 36.4 | 16.8 | 16.7 | 4.5 |
1. Blue bold indicates the best result across all models in the row (including 4B-class models); Black bold indicates the best result among 2B-class models.
2. Scores marked † come from the official Artificial Analysis release; all others are reproduced internally.
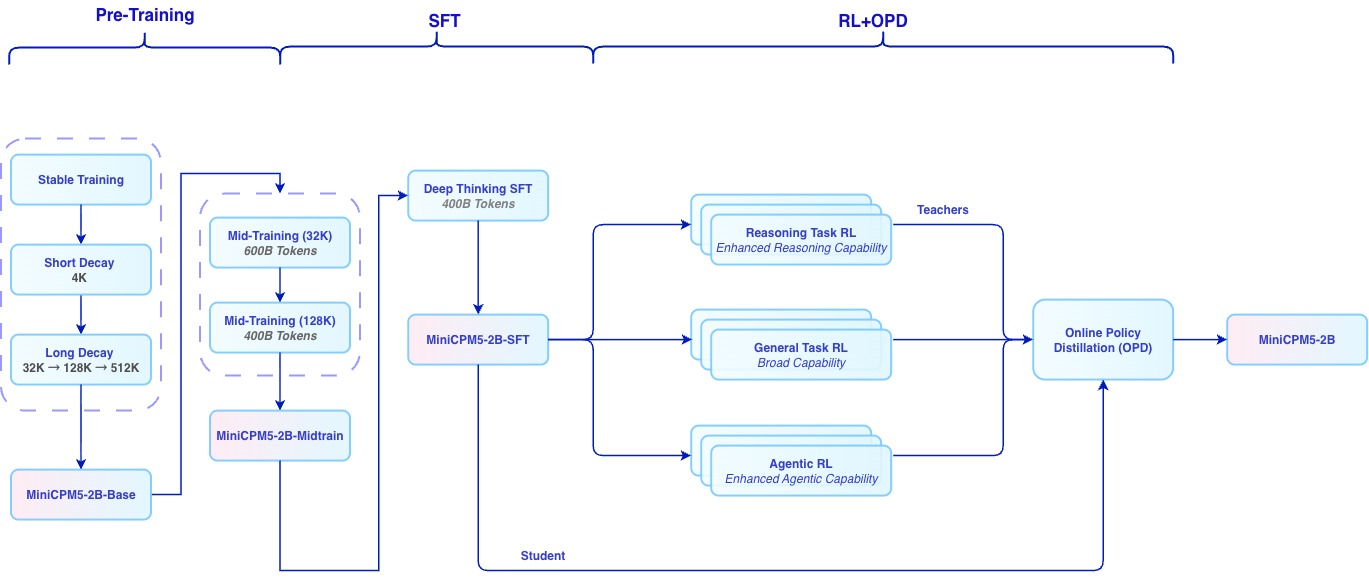
The training of MiniCPM5-2B is a full-stack practice of UltraData Tiered Data Management, covering three stages: base training, mid-training, and post-training.
During base training, the model goes through stable training and decay training to build core language capability and training stability. It then enters mid-training to further strengthen target capabilities and adapt to the target data distribution. The training corpus is released alongside the model as Ultra-FineWeb, Ultra-FineWeb-L3, UltraX, UltraData-Code and UltraData-Math.
During post-training, we proceed in three steps: SFT, RL, and OPD. We first use 400B tokens of deep-thinking SFT to establish deep-thinking and general chat abilities; the SFT data is released as UltraData-SFT-2605 and the Agent SFT data is released as UltraData-SFT-Agent-2609. We then train specialized RL teachers for math, code, agentic tasks, writing, and related domains (with the corresponding data also open-sourced as UltraData-RL-2609), and use On-Policy Distillation (OPD) to distill these teachers back into one release model.
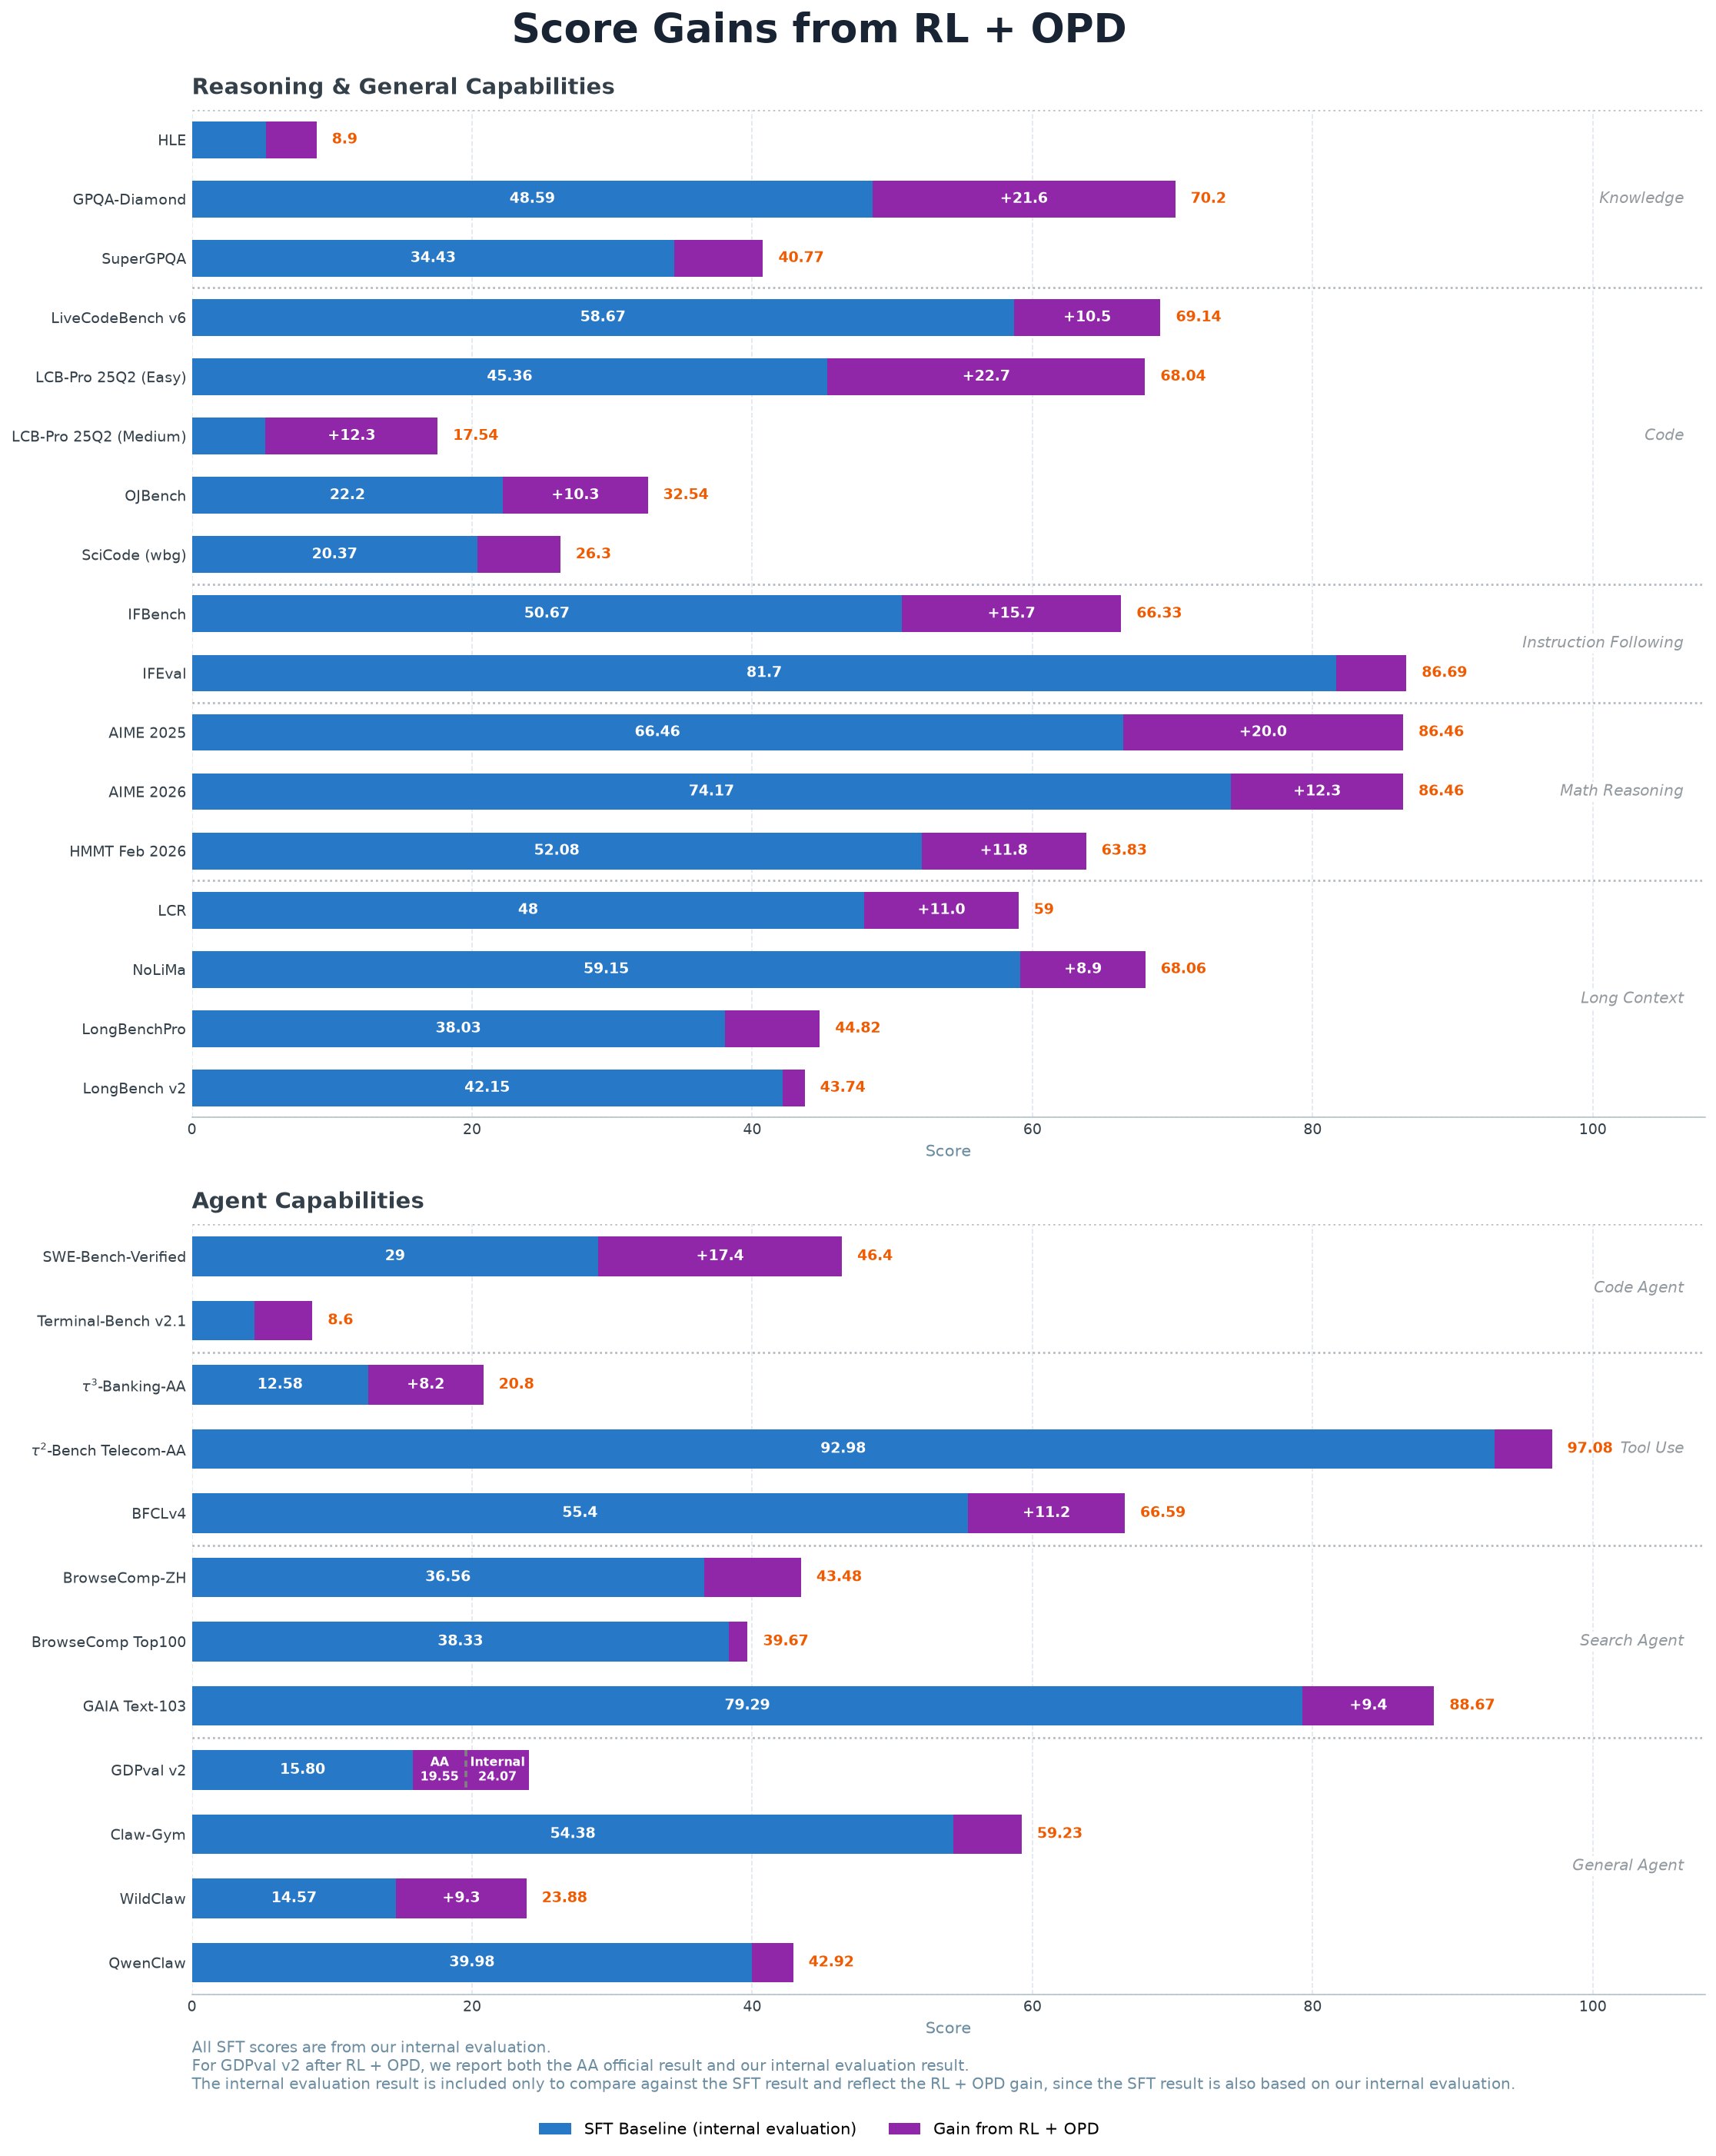
RL + OPD is a key part of MiniCPM5-2B post-training. During the RL stage, we adopted the critic-based algorithm described in JustRL II, substantially improving training stability and achieving significant gains across multiple domains. On the benchmarks listed below, RL + OPD improves reasoning and general capabilities by an average of ↑10.96 points, and agentic capabilities by ↑6.96 points.
OPD merges the capabilities of 16 expert models produced by RL training, including 5 agentic expert models. At each response position, we compute the full-vocabulary reverse KL divergence between student and teacher logits as the advantage estimate, replacing the original verification-based advantage. OPD directly reuses the prompts used to train each RL teacher as distillation data, so no additional corpus construction is required.
We recommend using the following sets of sampling parameters for generation:
temperature=1.0, top_p=0.95, min_p=0.0.If you encounter repetitive outputs, try:
temperature=1.0, top_p=0.95, min_p=0.0, repetition_penalty=1.05.Please note that the support for sampling parameters varies according to inference frameworks.
pip install "vllm>=0.21"
vllm serve openbmb/MiniCPM5-2B --port 8000
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "openbmb/MiniCPM5-2B",
    "messages": [{"role": "user", "content": "Who are you? Please briefly introduce yourself."}],
    "max_tokens": 128,
    "temperature": 1.0
  }'
pip install "sglang[srt]>=0.5.16"
python -m sglang.launch_server --model-path openbmb/MiniCPM5-2B --port 30000
curl http://localhost:30000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "openbmb/MiniCPM5-2B",
    "messages": [{"role": "user", "content": "Who are you? Please briefly introduce yourself."}],
    "max_tokens": 128,
    "temperature": 1.0
  }'
Speculative decoding (DSpark): we also release MiniCPM5-2B-DSpark, a DSpark draft model trained for MiniCPM5-2B. Enable it in SGLang to accelerate decoding while keeping the target model's outputs unchanged:
python -m sglang.launch_server \
  --model-path openbmb/MiniCPM5-2B \
  --trust-remote-code \
  --speculative-algorithm DSPARK \
  --speculative-draft-model-path openbmb/MiniCPM5-2B-DSpark \
  --speculative-dspark-block-size 7 \
  --port 30000
llama-server -m MiniCPM5-2B-F16.gguf -a MiniCPM5-2B --port 8080 -ngl 99 -c 8192 --jinja
-c 8192 sets the context length. You can adjust this value as needed.
curl http://localhost:8080/v1/chat/completions \
    -H "Content-Type: application/json" \
    -d '{
        "model": "MiniCPM5-2B",
        "messages": [{"role": "user", "content": "1+1=?"}],
        "temperature": 1.0, "top_p": 0.95, "min_p": 0.0, "max_tokens": 256
    }'
In llama.cpp, the default min_p=0.05 can lead to repetitive output: it filters out tokens whose probability is below 5% of the highest-probability token, potentially discarding the exact tokens needed to break out of a repetition loop. To prevent this, we set min_p=0.0.
pip install -U "transformers>=5.6" accelerate torch
from transformers import AutoModelForCausalLM, AutoTokenizer
model_id = "openbmb/MiniCPM5-2B"
tokenizer = AutoTokenizer.from_pretrained(model_id)
model = AutoModelForCausalLM.from_pretrained(
    model_id,
    torch_dtype="auto",
    device_map="auto",
)
messages = [{"role": "user", "content": "Who are you? Please briefly introduce yourself."}]
inputs = tokenizer.apply_chat_template(
    messages,
    tokenize=True,
    add_generation_prompt=True,
    enable_thinking=True,
    return_dict=True,
    return_tensors="pt",
).to(model.device)
outputs = model.generate(**inputs, max_new_tokens=128)
print(tokenizer.decode(outputs[0][inputs["input_ids"].shape[-1]:], skip_special_tokens=True))
For tool / function calling, SGLang is the recommended backend. MiniCPM5-2B emits XML-style tool calls and SGLang's built-in minicpm5 parser converts them to OpenAI-compatible tool_calls natively:
python -m sglang.launch_server --model-path openbmb/MiniCPM5-2B --port 30000 \
    --tool-call-parser minicpm5      # or: --tool-call-parser auto
MiniCPM5-2B uses the standard LlamaForCausalLM architecture, so mainstream inference engines can load it directly: no custom kernels, no model-code fork. For step-by-step deployment and fine-tuning instructions, use the GitHub cookbooks below. Agent Skills are linked as GitHub resources for users working with Cursor / Claude Code style coding agents.
| Backend | Model format / use case | Cookbook | Agent Skill |
|---|---|---|---|
| Transformers | BF16 / FP16 local Python inference, GPU + CPU | transformers.md | minicpm5-deploy-transformers |
| vLLM | BF16 / FP16 OpenAI server | vllm.md | minicpm5-deploy-vllm |
| SGLang | BF16 / FP16 OpenAI server, recommended for tool calling | sglang.md | minicpm5-deploy-sglang |
| llama.cpp | GGUF local inference, CPU/GPU | llama_cpp.md | minicpm5-deploy-llama-cpp |
| Ollama | GGUF local on-device runtime | ollama.md | minicpm5-deploy-ollama |
| LM Studio | GGUF Mac desktop app and OpenAI server | lmstudio.md | minicpm5-deploy-lmstudio |
| MLX | MLX / 4bit local inference on Apple Silicon | mlx.md | minicpm5-deploy-mlx |
| ArcLight | GGUF local on-device, CPU, Desktop & Server | arclight.md | minicpm5-deploy-arclight |
| vLLM Ascend | BF16 / FP16 OpenAI server | vllm_ascend.md | minicpm5-deploy-vllm-ascend |
| LiteRT-LM | .litertlm on-device runtime: Android / iOS / desktop / IoT, CPU + GPU |
litert.md | minicpm5-deploy-litert |
| Framework | Use case | Cookbook | Agent Skill |
|---|---|---|---|
| TRL + PEFT | LoRA / SFT fine-tuning | trl.md | minicpm5-finetune-trl |
| LLaMA-Factory | Fine-tuning | llamafactory.md | minicpm5-finetune-llamafactory |
| ms-swift | Fine-tuning | ms_swift.md | minicpm5-finetune-ms-swift |
| unsloth | Fine-tuning | unsloth.md | minicpm5-finetune-unsloth |
In addition to the deployment and fine-tuning frameworks listed above, MiniCPM5-2B is also supported by FlagOS for multi-chip deployment.
To enable large-scale deployment across different AI chips, Beijing Zhiyuan Research Institute, together with numerous research institutions, chip manufacturers, system vendors, and algorithm and software organizations both domestically and internationally, jointly initiated and established the FlagOS Open Source Community.
The FlagOS community is dedicated to building a unified, open-source system software stack for various AI chips, encompassing core open-source projects such as a large-scale operator library, a unified AI compiler, parallel training and inference frameworks, and a unified communication library. It aims to create an open technology ecosystem connecting the “model-system-chip” layers. By enabling “develop once, deploy across chips”, FlagOS unlocks the computational potential of hardware, breaks down the ecosystem silos between different chip software stacks, and effectively reduces migration costs for developers.The FlagOS community fosters an AI hardware and software ecosystem, overcomes single-vendor closed-source monopolies, promotes widespread deployment of AI hardware technologies, and is committed to rooted in China while embracing global collaboration.
Official website express: https://flagos.io
Thanks to FlagOS’s unified multi-chip AI system software stack, MiniCPM5-2B was adapted to 9 different AI chips in an extremely short time. Currently, the multi-chip version of MiniCPM5-2B has been released on FlagRelease, FlagOS’s platform for automatic migration, adaptation, and deployment of large models across multi-architecture AI chips. Details are as follows:
| Vendor | ModelScope | Huggingface |
|---|---|---|
| Nvidia | MiniCPM5-2B-nvidia-FlagOS | MiniCPM5-2B-nvidia-FlagOS |
| Hygon | MiniCPM5-2B-hygon-FlagOS | MiniCPM5-2B-hygon-FlagOS |
| Metax | MiniCPM5-2B-metax-FlagOS | MiniCPM5-2B-metax-FlagOS |
| Iluvatar | MiniCPM5-2B-iluvatar-FlagOS | MiniCPM5-2B-iluvatar-FlagOS |
| Zhenwu | MiniCPM5-2B-zhenwu-FlagOS | MiniCPM5-2B-zhenwu-FlagOS |
| Mthreads | MiniCPM5-2B-mthreads-FlagOS | MiniCPM5-2B-mthreads-FlagOS |
| Kunlunxin | MiniCPM5-2B-kunlunxin-FlagOS | MiniCPM5-2B-kunlunxin-FlagOS |
| Ascend | MiniCPM5-2B-ascend-FlagOS | MiniCPM5-2B-ascend-FlagOS |
| ARM-v9 | MiniCPM5-2B-Armv9-FlagOS | MiniCPM5-2B-Armv9-FlagOS |
FlagRelease is a platform developed by the FlagOS team for automatic migration, adaptation, and deployment of large models across multi-architecture AI chips. The multi-chip version of MiniCPM5-2B has already been released on FlagRelease. All necessary software packages are pre-installed on the platform, so users do not need to install anything.
| Vendor | ModelScope | Huggingface |
|---|---|---|
| Nvidia | MiniCPM5-2B-nvidia-FlagOS | MiniCPM5-2B-nvidia-FlagOS |
| Hygon | MiniCPM5-2B-hygon-FlagOS | MiniCPM5-2B-hygon-FlagOS |
| Metax | MiniCPM5-2B-metax-FlagOS | MiniCPM5-2B-metax-FlagOS |
| Iluvatar | MiniCPM5-2B-iluvatar-FlagOS | MiniCPM5-2B-iluvatar-FlagOS |
| Zhenwu | MiniCPM5-2B-zhenwu-FlagOS | MiniCPM5-2B-zhenwu-FlagOS |
| Mthreads | MiniCPM5-2B-mthreads-FlagOS | MiniCPM5-2B-mthreads-FlagOS |
| Kunlunxin | MiniCPM5-2B-kunlunxin-FlagOS | MiniCPM5-2B-kunlunxin-FlagOS |
| Ascend | MiniCPM5-2B-ascend-FlagOS | MiniCPM5-2B-ascend-FlagOS |
| ARM-v9 | MiniCPM5-2B-Armv9-FlagOS | MiniCPM5-2B-Armv9-FlagOS |
Official Repository: https://github.com/flagos-ai/FlagGems
pip install flag-gems==4.2.1rc0
pip install triton==3.5.1
You can enable flagGems acceleration by adding the import of flagGems in the source code of vllm where inference is performed.
import flag_gems
flag_gems.enable(record=True, once=True, path="/root/gems.txt")
vllm serve ${model_path} \
--trust-remote-code \
--dtype bfloat16 \
--enforce-eager \
--port ${Port} \
--served-model-name ${model_name} \
--gpu-memory-utilization 0.85
vllm-plugin-FL is a plugin built for the vLLM inference/service framework. Developed on top of FlagOS’s unified multi-chip backend, it is designed to extend vLLM’s capabilities and performance across a variety of hardware environments.
| Vendor | From Scratch | From FlagRelease | |
|---|---|---|---|
| Nvidia | vllm-plugin-FL/MiniCPM5-2B | MiniCPM5-2B-ModelScope | MiniCPM5-2B-nvidia-FlagOS |
This model has no autonomous intent or legal personhood; its outputs are text generated from statistical patterns and may be inaccurate, biased, or offensive, and may be manipulated by carefully crafted prompts ("jailbreaks") into producing unintended content. Its responses on sensitive topics such as politics, health, finance, and law are not reviewed by experts and should not be treated as professional advice.
This model is provided "AS IS", without warranty of any kind, express or implied, and the developers are not liable for any damages arising from its use. Users must employ the model only for lawful, compliant, and ethical purposes, configure their own safeguards, and label AI-generated content where required; deliberate jailbreaking, injection attacks, or inducing harmful output is prohibited, and any such testing is at the user's own risk.
This repository and MiniCPM model weights are released under the Apache-2.0 License.
Please cite our paper if you find our work valuable:
@article{minicpm4,
  title={Minicpm4: Ultra-efficient llms on end devices},
  author={MiniCPM, Team},
  journal={arXiv preprint arXiv:2506.07900},
  year={2025}
}
Base model
openbmb/MiniCPM5-2B