

TRIM: Scalable 3D Gaussian Diffusion Inference with Temporal and Spatial Trimming
Paper • 2511.16642 • Published

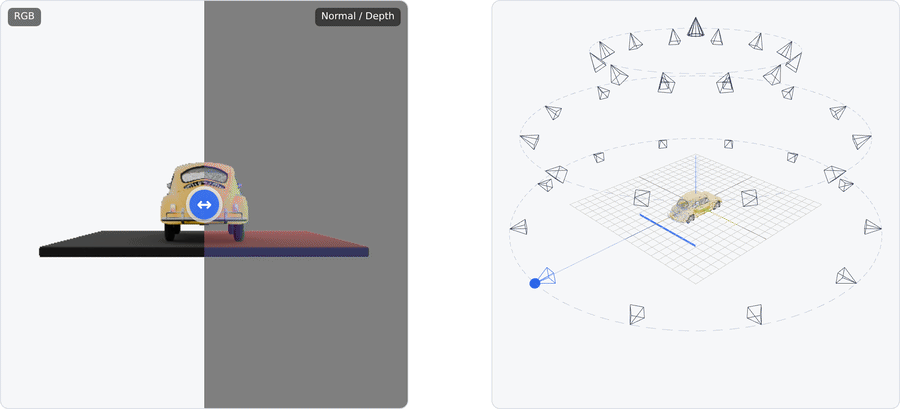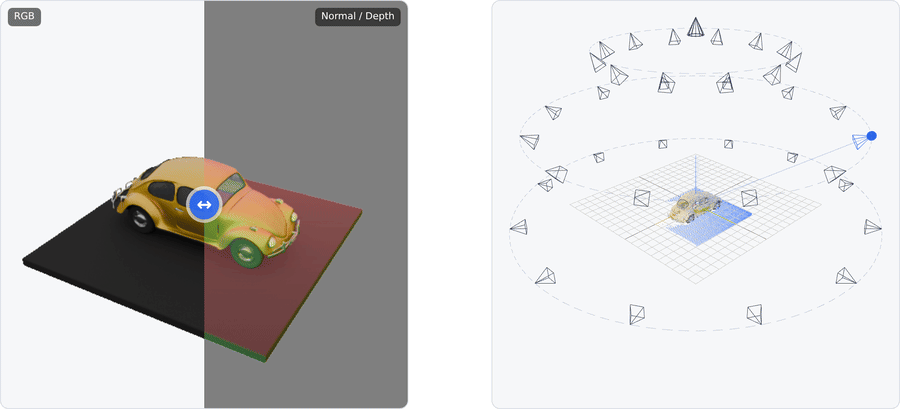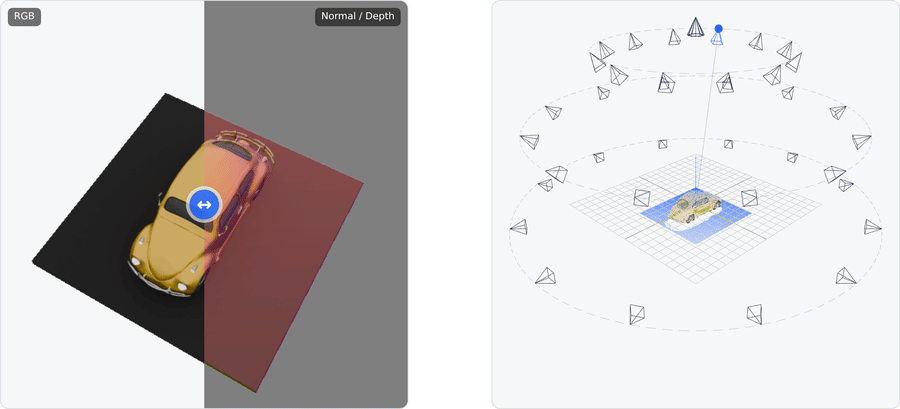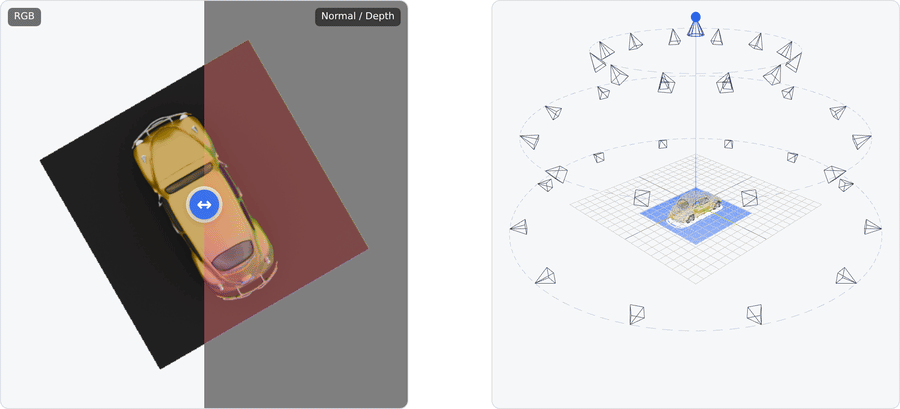
The 48 views in order: three azimuth rings at elevations 0°, 30° and 60°, plus a top-down ring at 90°. The highlighted camera on the dome is the one that took the image on the left.
Rendering is the computationally demanding bottleneck of multi-view 3D datasets — typically over 100,000 CPU core hours for 83k objects. Our rendered pixels already exist: 512×512 RGBA plus per-view normal and depth maps, ~1.5 TB for the primary split and freely downloadable, each object paired with its Objaverse UID and a Cap3D caption. Dome is literal for the primary dome_objaverse split: all cameras sit on the upper hemisphere (elevations 0° to 90°). The accompanying gobjaverse_parquet split preserves GObjaverse's original trajectory, which dips to elevation −90° (see "Splits & Metadata" below).
| Dataset | Objects | Views / object | Elevation coverage | Rendered pixels published |
|---|---|---|---|---|
| Zero123++ v1.2 | — | 6 | two values (20° / -10°) |
n/a (model output config) |
| MVDream | — | 4 | single fixed elevation | n/a (model output config) |
| SV3D | 150K | 21 | static [-5°, 30°] or dynamic |
— |
| TRELLIS-500K | 500K | 150 | dense | No (metadata + render script only) |
| G-buffer Objaverse | 280K | 40 | side rings ≤30° (varies/object) + top/bottom |
Yes (~1.1 TB, original source renders) |
| Dome-Objaverse | 83,296 | 48 | four rings: 0°, 30°, 60°, 90° |
Yes (~1.5 TB primary split, free download) |
Two things distinguish Dome-Objaverse: a regular, fully-specified camera grid (four rings of identical 12-step azimuth sweeps, every view addressable by view_id), and the fact that the pixels are actually published rather than left to the user to render.
Both splits cover the exact same 83,296 objects with zero missing objects.
| Split | Description & Source | Views | Elevation | Azimuth |
|---|---|---|---|---|
dome_objaverse (Primary) |
Our custom dome render pass (1.4 TB) | 48 | 0°, 30°, 60°, 90° (4 rings) |
0°, 30°, ..., 330° (12 steps/ring) |
gobjaverse_parquet |
Re-packed from original G-buffer Objaverse renders for baseline supervision (1.1 TB) | 40 | Side rings ≤30° (varies/object) + ±90° poles |
Mixed 15° / 30° steps |
dome_objaverse: view_id 0–11 / 12–23 / 24–35 / 36–47 are elevation 0° / 30° / 60° / 90° respectively, each a 12-step azimuth sweep 0°, 30°, ..., 330°.gobjaverse_parquet: camera parameters are read dynamically per-view from the embedded 00000.json ... 00039.json metadata files.metadata/objects.parquet (5 MB, ships in this repo) is the join table, 83,296 rows with 100% coverage. The columns you'll actually use: object_id (e.g. "0/10228"), objaverse_uid, glb_path, caption, camera_distance. It also carries group_id/index_id (the two halves of object_id) and sheet_id/sheet_pos (internal thumbnail-sheet coordinates used only by the web viewer) — safe to ignore for training. Legacy per-field JSON files (camera_distances.json, gobjaverse_index_to_objaverse.json, text_captions_cap3d.json, cobj_done_list.json) are also included; their content is already consolidated into objects.parquet.
Full config in pipeline/2-render/blender_script.py; a decode example is in pipeline/4-usage/load_views.py. Two things that will silently produce wrong results if assumed otherwise:
1.50–2.00 (see camera_distance in objects.parquet), not a fixed constant.nd_png (16-bit normal + depth) channel order is reversed: R = normal z, G = normal y, B = normal x, alpha = depth (alpha / 65535 × 5.0, planar along the camera axis). Use cv2.imdecode(..., cv2.IMREAD_UNCHANGED), not PIL — it silently downcasts to 8-bit.Code in this repository is Apache-2.0 (see LICENSE), matching AI2's objaverse-rendering,
which render/ derives from. The rendered image data on Hugging Face is CC-BY-4.0. Individual
Objaverse source meshes carry their own licenses — use objaverse_uid in
metadata/objects.parquet to look them up.
pipeline/2-render/LICENSE).Please also cite the original Objaverse / GObjaverse sources and state which split(s) you used.
This dataset is an extension of our NeurIPS 2025 publication, TRIM: Scalable 3D Gaussian Diffusion Inference with Temporal and Spatial Trimming. If you find it helpful, please consider citing:
@inproceedings{
    Yin2025TRIM,
    title={{TRIM}: Scalable 3D Gaussian Diffusion Inference with Temporal and Spatial Trimming},
    author={Yin, Zeyuan and Liu, Xiaoming},
    booktitle={The Thirty-ninth Annual Conference on Neural Information Processing Systems (NeurIPS)},
    year={2025}
}