

The dataset viewer is not available for this subset.
Need help to make the dataset viewer work? Make sure to review how to configure the dataset viewer, and open a discussion for direct support.
Infinigen 2023-10 Nature Preview
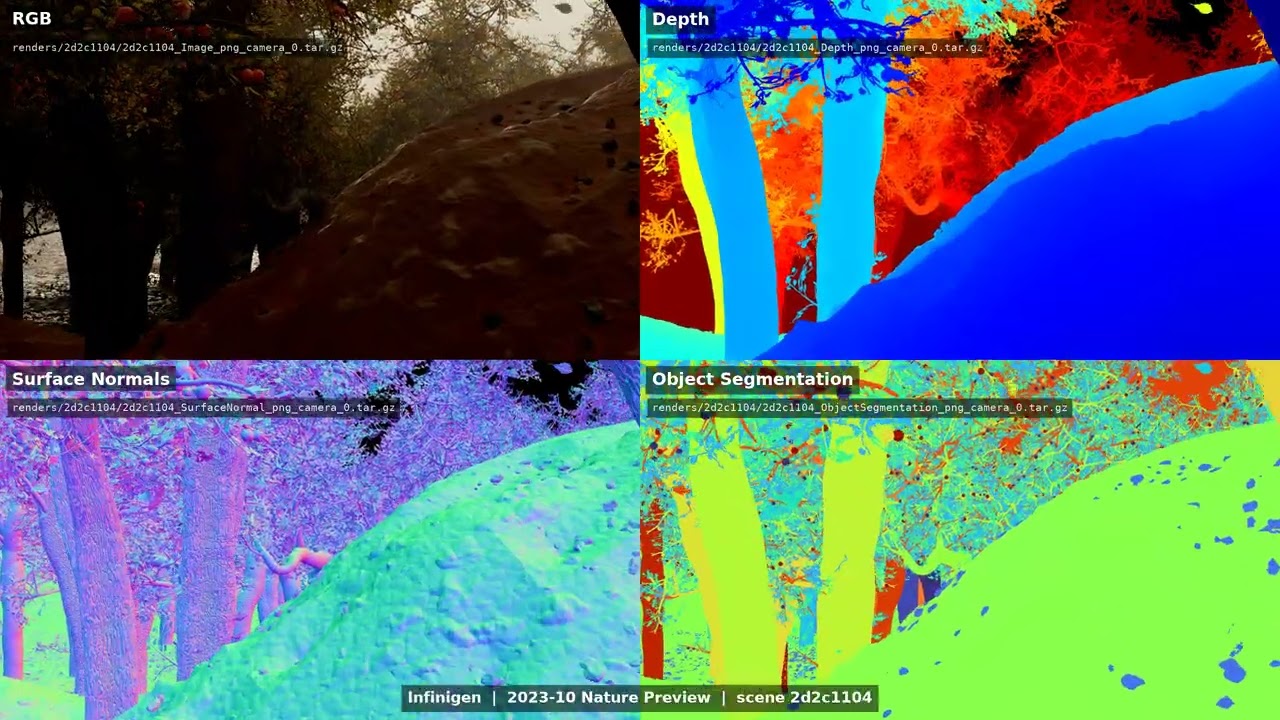 |
An 80-second preview of the RGB and ground-truth passes in this release.
New! Compressed Version
As of 2026-08-19, we provide a copy of this dataset compressed with CVDPack, making it much easier to download and unpack. To download and unpack one scene, one camera, and a useful subset of passes:
uvx --from 'cvdpack[hf]' cvdpack unpack \
  --input https://huggingface.co/datasets/infinigen/2023-10-nature-preview/tree/main/packed \
  --output nature_preview \
  --tmp_folder nature_preview_tmp \
  --hf_staging per_job \
  --subset scene=f020c43 gt_type=Image,Depth,Flow3D,SurfaceNormal,ObjectSegmentation,Objects cam=0
To download and unpack the complete compressed copy with four local workers:
uvx --from 'cvdpack[hf]' cvdpack unpack \
  --input https://huggingface.co/datasets/infinigen/2023-10-nature-preview/tree/main/packed \
  --output nature_preview \
  --tmp_folder nature_preview_tmp \
  --hf_staging per_job \
  --n_workers 4 --parallel_mode multiprocess
The compressed copy is 97 GB rather than 249 GB. It reduces Flow3D and Depth by about 90%, and most other encoded ground-truth passes by 20–60%. For finite values inside the configured ranges, quantization introduces less than 0.016 pixels of error per 2D flow component and less than 0.0048 meters of depth error at 20 meters. Surface normals are also quantized; RGB, masks, object metadata, and camera metadata retain their codec-defined lossless semantics.
The compressed copy contains the primary numeric ground truth, RGB PNGs, masks, and object/camera
metadata. It omits Image_exr and the visualization-only Depth_png, Flow3D_png,
ObjectSegmentation_png, and SurfaceNormal_png passes; those remain available in the original
release below.
Original 2023-10-13 Version
Pre-generated video data from Infinigen, a procedural
generator of photorealistic 3D natural worlds. This is the 2023_10_13_preview release, previously
distributed from infinigen-data.cs.princeton.edu; the
files under renders/ are byte-identical to that release.
Preliminary test video release. This release contains only a small sample of 10 videos. Please stay tuned for more, and post any feedback on our GitHub Issues page.
InstanceSegmentationandTagSegmentationmasks are not included in this release; they will be included in future releases.
Summary
| Scenes | 10 |
| Cameras | 2 (camera_0, camera_1; a stereo pair) |
| Frames per camera | 192 (numbered 0001–0192) |
| Images | 3,840 |
| Ground-truth passes | 27 |
| Resolution | 1280x720 (Depth_npy / Depth_png are 2560x1440) |
| Total size | 249 GB, ~25 GB per scene |
| Infinigen version | 1.2_rc_0 |
| Data-release format version | 0.2.0 |
Downloading
Download only the passes you need. All 27 passes for all 10 scenes is 249 GB; RGB plus depth, normals and camera poses for one scene is under 8 GB.
from huggingface_hub import snapshot_download

snapshot_download(
    "infinigen/2023-10-nature-preview",
    repo_type="dataset",
    local_dir="my_download",
    allow_patterns=[
        "metadata.json",
        "renders/1a1f2004/*_Image_png_camera_0.tar.gz",
        "renders/1a1f2004/*_Depth_npy_camera_0.tar.gz",
        "renders/1a1f2004/*_camview_npz_camera_0.tar.gz",
    ],
)
Or from the command line:
hf download infinigen/2023-10-nature-preview --repo-type dataset --local-dir my_download \
    --include "renders/1a1f2004/*_Image_png_camera_0.tar.gz"
Then extract the tarballs in place:
cd my_download
find renders -name '*.tar.gz' -exec tar -xzf {} -C . \;
Repository layout
metadata.json                                      # scene / camera / pass manifest
renders/{scene}/{scene}_{Pass}_camera_{c}.tar.gz   # 540 tarballs = 10 scenes x 27 passes x 2 cameras
thumbnails/{scene}_thumbnail.png                   # one preview image per scene
Each tarball holds all 192 frames of one pass for one camera of one scene, and extracts to:
{scene}/frames/{Pass}/camera_{c}/{Pass}_0_0_{frame:04d}_{c}.{ext}
The two numeric fields after the pass name are the camera-rig index and the resample index, both 0
throughout this release; the trailing field is the sub-camera, matching the camera_{c} directory.
Scene seeds: 1a1f2004, 1d8d6f8e, 1f25974d, 2d2c1104, 2e962781, 4bbdd3e0, 5be1f943,
22ca3b8b, 560a8258, f020c43.
Ground-truth passes
Sizes are totals across all 10 scenes and both cameras.
| Pass | Size | Description |
|---|---|---|
Image_png |
6.2 GB | RGB image as a .png. |
Image_exr |
40.8 GB | RGB image as an .exr. Full dynamic range, before tonemapping. |
camview_npz |
0.02 GB | Camera intrinsic & extrinsic matrices, i.e. camera calibration and poses. |
Depth_npy |
40.2 GB | Depth. |
Depth_png |
3.9 GB | Color-mapped PNG of Depth_npy. FOR VISUALIZATION ONLY. |
SurfaceNormal_npy |
35.3 GB | Surface normals. |
SurfaceNormal_png |
7.0 GB | Color-mapped PNG of SurfaceNormal_npy. FOR VISUALIZATION ONLY. |
Flow3D_npy |
29.5 GB | Optical flow and depth change. |
Flow3D_png |
1.0 GB | Color-wheel visualization of the 2D part of Flow3D_npy. FOR VISUALIZATION ONLY. |
Flow3DMask_png |
0.4 GB | Flow occlusion mask. |
OcclusionBoundaries_png |
3.1 GB | Occlusion boundaries. |
ObjectSegmentation_npz |
0.2 GB | Semantic segmentation mask, compressed using a lookup table. |
ObjectSegmentation_png |
0.4 GB | Color-mapped PNG of ObjectSegmentation_npz. FOR VISUALIZATION ONLY. |
Objects_json |
36.3 GB | Names, poses and bounding boxes of objects in the scene. Required for 2D/3D bounding boxes. |
AO_png |
3.6 GB | Ambient occlusion. |
DiffCol_png |
5.0 GB | Diffuse color, a.k.a. albedo. |
DiffDir_png |
5.6 GB | Diffuse direct pass. |
DiffInd_png |
5.7 GB | Diffuse indirect pass. |
Emit_png |
1.3 GB | Emission pass. |
Env_png |
1.5 GB | Environment pass. |
GlossCol_png |
3.0 GB | Glossy color. |
GlossDir_png |
4.8 GB | Glossy direct pass. |
GlossInd_png |
5.5 GB | Glossy indirect pass. |
TransCol_png |
1.4 GB | Transmission color. |
TransDir_png |
1.3 GB | Transmission direct pass. |
TransInd_png |
2.0 GB | Transmission indirect pass. |
VolumeDir_png |
3.9 GB | Volume direct pass. |
Where both a .png and a .npy/.npz file exist for the same quantity, use the .png only for
visualization and the array file for training.
Data formats
Full documentation is in GroundTruthAnnotations.md. In brief, with H and W the height and width of the RGB image:
- Depth — 2H x 2W float32 array.
- Surface normals — H x W x 3 float32 array, coordinate system +X right, +Y up, +Z backward.
- Occlusion boundaries — >= 2H x 2W png, 255 on a boundary and 0 otherwise.
- Flow3D — H x W x 3 float32 array. Channels 1 and 2 are standard optical flow, in pixels at the resolution of the original image; channel 3 is the depth change to the next frame. Values are not meaningful on the final frame of a sequence.
- Flow3DMask — H x W png, 255 for a co-visible pixel and 0 for an occluded one. Computed by comparing triangle face-ids at either end of each flow vector, which yields frequent false negatives distributed like salt-and-pepper noise; max-pooling the mask down to image resolution reduces them.
- camview —
.npzwithK, the 3x3 intrinsic matrix (pinhole model);T, the 4x4 camera-to-world extrinsic matrix; andHW, the image height and width. The world coordinate system is the computer-vision convention, +X right, +Y down, +Z forward — not Blender's internal convention, which flips Y and Z. - ObjectSegmentation — H x W int32 array, index-compressed into the
.npzasvals(the distinct object indices),indices(one uint8 lookup per pixel) andshape. Reconstruct withvals[indices].reshape(shape). Each integer maps to the entry inObjects_jsonwith the sameobject_index. "Object" is whatever Blender treats as one object: large or complex assets such as terrain, trees or animals are a single object, while many small instanced assets (grass, coral) may be grouped together. - Objects_json — per object:
object_index,name,children,num_verts,num_faces,materials,unapplied_modifiers,tags, bounding-box cornersminandmaxin object coordinates, andmodel_matrices, the 4x4 object-to-world transforms of every instance. A 3D bounding box per instance follows frommin,maxandmodel_matrices.
Loading
Infinigen ships a PyTorch-style dataset class, dataset_loader.py:
from infinigen.tools.dataset_loader import get_infinigen_dataset

dataset = get_infinigen_dataset("my_download", data_types=["Image_png", "Depth_npy"])
print(len(dataset))
print(dataset[0].keys())
dataset_loader.py is designed to be separable from the main Infinigen codebase — you can copy it
into your own project, but you must also copy its dependency suffixes.py.
License
BSD 3-Clause. Copyright (c) 2023, Princeton University.
Citation
@inproceedings{infinigen2023infinite,
  title={Infinite Photorealistic Worlds Using Procedural Generation},
  author={Raistrick, Alexander and Lipson, Lahav and Ma, Zeyu and Mei, Lingjie and Wang, Mingzhe and Zuo, Yiming and Kayan, Karhan and Wen, Hongyu and Han, Beining and Wang, Yihan and Newell, Alejandro and Law, Hei and Goyal, Ankit and Yang, Kaiyu and Deng, Jia},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
  pages={12630--12641},
  year={2023}
}
- Downloads last month
- 732