

WAFT-Stereo: Warping-Alone Field Transforms for Stereo Matching
Paper • 2603.24836 • Published • 3
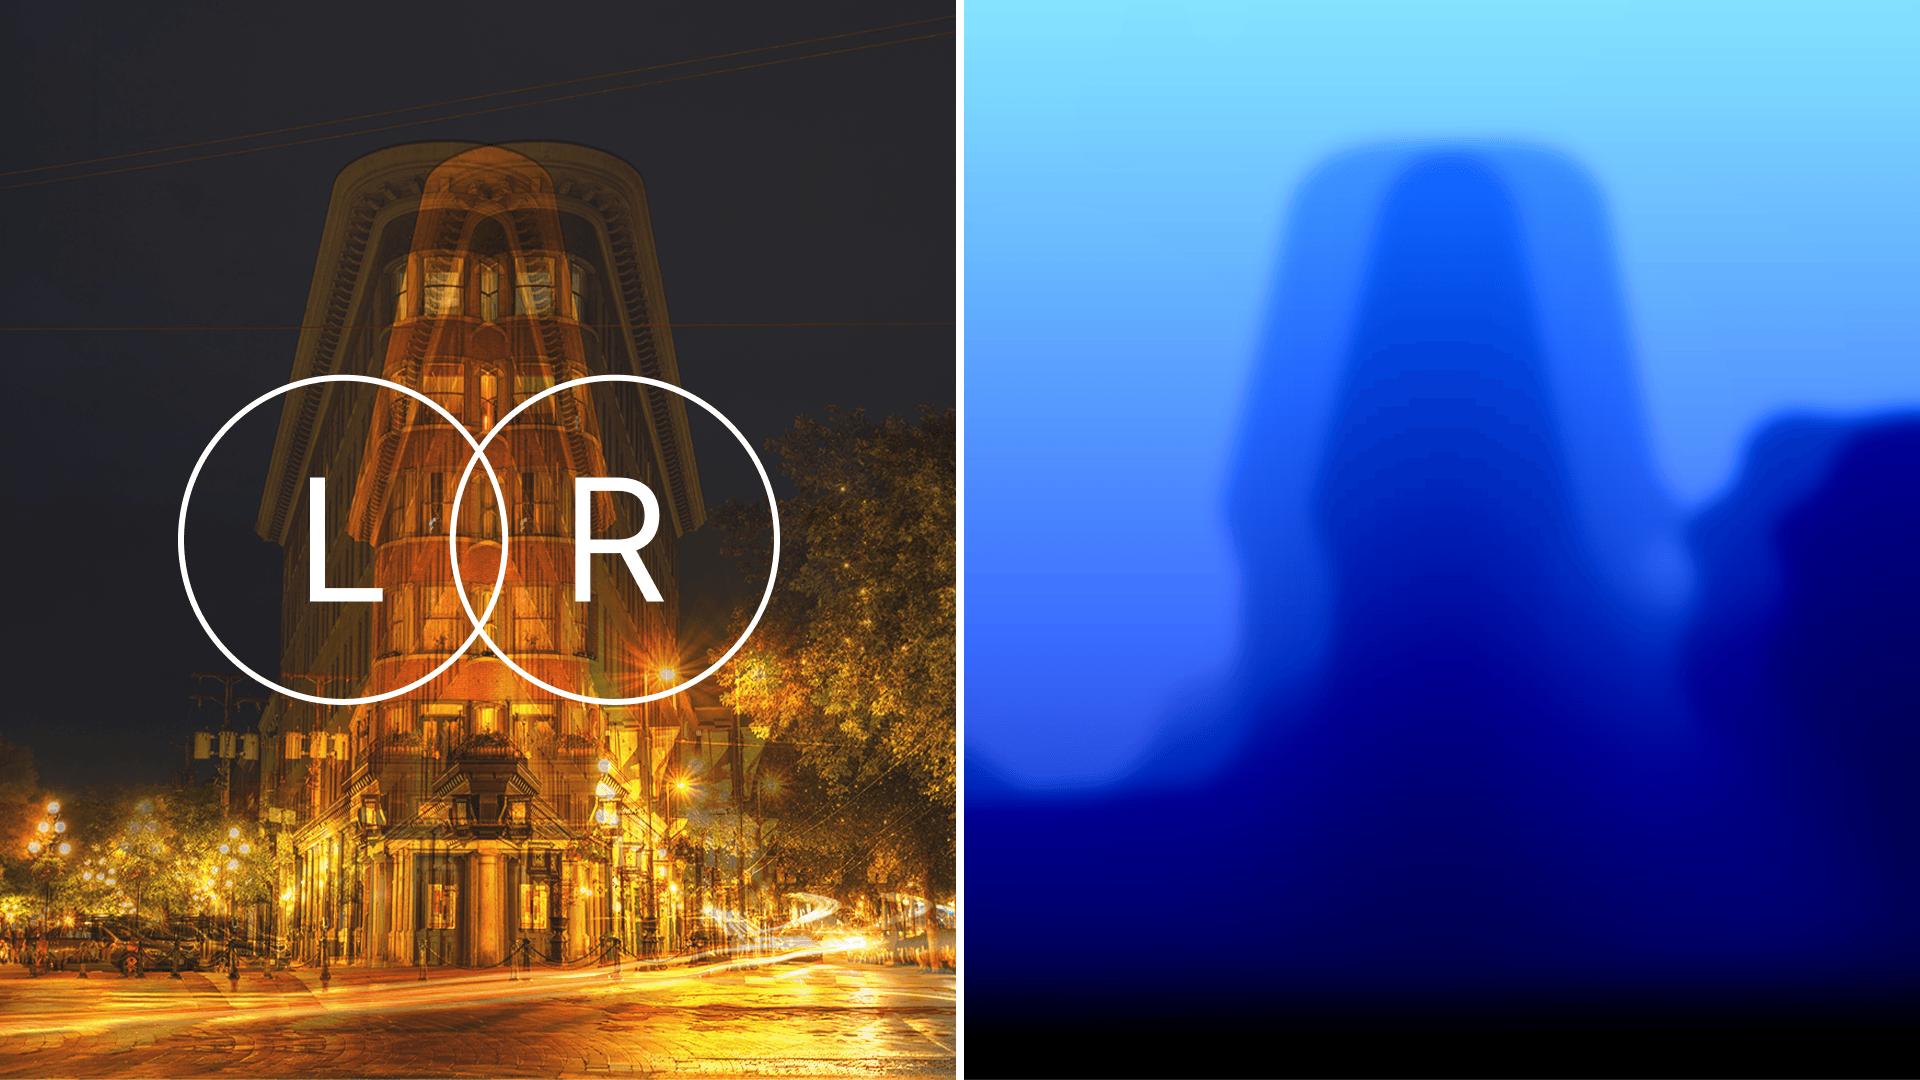
WAFT-Stereo estimates per-pixel disparity from a rectified stereo pair using warping-based iterative refinement instead of a 4D cost volume.
This is based on the implementation of WAFT-Stereo found here. This repository contains pre-exported model files optimized for Qualcomm® devices. You can use the Qualcomm® AI Hub Models library to export with custom configurations. More details on model performance across various devices, can be found here.
Qualcomm AI Hub Models uses Qualcomm AI Hub Workbench to compile, profile, and evaluate this model. Sign up to run these models on a hosted Qualcomm® device.
There are two ways to deploy this model on your device:
Below are pre-exported model assets ready for deployment.
| Runtime | Precision | Chipset | SDK Versions | Download |
|---|---|---|---|---|
| ONNX | float | Universal | QAIRT 2.51, ONNX Runtime 1.30.0 | Download |
For more device-specific assets and performance metrics, visit WAFT-Stereo on Qualcomm® AI Hub.
Use the Qualcomm® AI Hub Models Python library to compile and export the model with your own:
This option is ideal if you need to customize the model beyond the default configuration provided here.
See our repository for WAFT-Stereo on GitHub for usage instructions.
Model Type: Model_use_case.depth_estimation
Model Stats:
| Model | Runtime | Precision | Chipset | Inference Time (ms) | Peak Memory Range (MB) | Primary Compute Unit |
|---|---|---|---|---|---|---|
| classification | ONNX | float | Snapdragon® 8 Elite Gen 5 For Galaxy Mobile | 5.676 ms | 3 - 262 MB | NPU |
| classification | ONNX | float | Snapdragon® 8 Elite For Galaxy Mobile | 8.22 ms | 3 - 255 MB | NPU |
| classification | ONNX | float | Snapdragon® X2 Elite | 6.134 ms | 7 - 7 MB | NPU |
| classification | ONNX | float | Snapdragon® X Elite | 14.824 ms | 46 - 46 MB | NPU |
| classification | ONNX | float | Snapdragon® 8 Gen 1 Mobile | 26.583 ms | 1 - 340 MB | NPU |
| classification | ONNX | float | Qualcomm® Dragonwing™ IQ-8275 | 17.434 ms | 7 - 18 MB | NPU |
| classification | ONNX | float | Qualcomm® Dragonwing™ QCS8550 (Proxy) | 14.232 ms | 0 - 274 MB | NPU |
| classification | ONNX | float | Qualcomm® QCS8450 | 26.583 ms | 1 - 340 MB | NPU |
| classification | ONNX | float | Qualcomm® Dragonwing™ IQ-9075 | 18.196 ms | 7 - 17 MB | NPU |
| classification | ONNX | float | Qualcomm® Dragonwing™ IQ-X7181 | 14.824 ms | 46 - 46 MB | NPU |
| classification | ONNX | float | Qualcomm® Dragonwing™ Q-8750 | 8.22 ms | 3 - 255 MB | NPU |
| classification | ONNX | float | Snapdragon® 8 Elite Extreme Gen 6 Mobile | 4.724 ms | 7 - 263 MB | NPU |
| classification | ONNX | float | Snapdragon® 8 Elite Gen 6 Mobile | 7.329 ms | 0 - 246 MB | NPU |
| encoder | ONNX | float | Snapdragon® 8 Elite Gen 5 For Galaxy Mobile | 9.78 ms | 22 - 347 MB | NPU |
| encoder | ONNX | float | Snapdragon® 8 Elite For Galaxy Mobile | 13.58 ms | 25 - 342 MB | NPU |
| encoder | ONNX | float | Snapdragon® X2 Elite | 10.625 ms | 34 - 34 MB | NPU |
| encoder | ONNX | float | Snapdragon® X Elite | 24.457 ms | 53 - 53 MB | NPU |
| encoder | ONNX | float | Snapdragon® 8 Gen 1 Mobile | 36.427 ms | 1 - 413 MB | NPU |
| encoder | ONNX | float | Qualcomm® Dragonwing™ IQ-8275 | 27.64 ms | 22 - 28 MB | NPU |
| encoder | ONNX | float | Qualcomm® Dragonwing™ QCS8550 (Proxy) | 23.56 ms | 0 - 328 MB | NPU |
| encoder | ONNX | float | Qualcomm® QCS8450 | 36.427 ms | 1 - 413 MB | NPU |
| encoder | ONNX | float | Qualcomm® Dragonwing™ IQ-9075 | 28.98 ms | 24 - 29 MB | NPU |
| encoder | ONNX | float | Qualcomm® Dragonwing™ IQ-X7181 | 24.457 ms | 53 - 53 MB | NPU |
| encoder | ONNX | float | Qualcomm® Dragonwing™ Q-8750 | 13.58 ms | 25 - 342 MB | NPU |
| encoder | ONNX | float | Snapdragon® 8 Elite Extreme Gen 6 Mobile | 7.773 ms | 25 - 342 MB | NPU |
| encoder | ONNX | float | Snapdragon® 8 Elite Gen 6 Mobile | 11.657 ms | 5 - 310 MB | NPU |
| regression | ONNX | float | Snapdragon® 8 Elite Gen 5 For Galaxy Mobile | 22.557 ms | 13 - 442 MB | NPU |
| regression | ONNX | float | Snapdragon® 8 Elite For Galaxy Mobile | 31.632 ms | 12 - 425 MB | NPU |
| regression | ONNX | float | Snapdragon® X2 Elite | 23.062 ms | 23 - 23 MB | NPU |
| regression | ONNX | float | Snapdragon® X Elite | 50.047 ms | 45 - 45 MB | NPU |
| regression | ONNX | float | Snapdragon® 8 Gen 1 Mobile | 85.479 ms | 1 - 655 MB | NPU |
| regression | ONNX | float | Qualcomm® Dragonwing™ IQ-8275 | 59.165 ms | 10 - 25 MB | NPU |
| regression | ONNX | float | Qualcomm® Dragonwing™ QCS8550 (Proxy) | 49.099 ms | 18 - 22 MB | NPU |
| regression | ONNX | float | Qualcomm® QCS8450 | 85.479 ms | 1 - 655 MB | NPU |
| regression | ONNX | float | Qualcomm® Dragonwing™ IQ-9075 | 60.144 ms | 11 - 25 MB | NPU |
| regression | ONNX | float | Qualcomm® Dragonwing™ IQ-X7181 | 50.047 ms | 45 - 45 MB | NPU |
| regression | ONNX | float | Qualcomm® Dragonwing™ Q-8750 | 31.632 ms | 12 - 425 MB | NPU |
| regression | ONNX | float | Snapdragon® 8 Elite Extreme Gen 6 Mobile | 19.349 ms | 24 - 439 MB | NPU |
| regression | ONNX | float | Snapdragon® 8 Elite Gen 6 Mobile | 26.566 ms | 19 - 405 MB | NPU |