

NetVLAD: CNN architecture for weakly supervised place recognition
Paper • 1511.07247 • Published
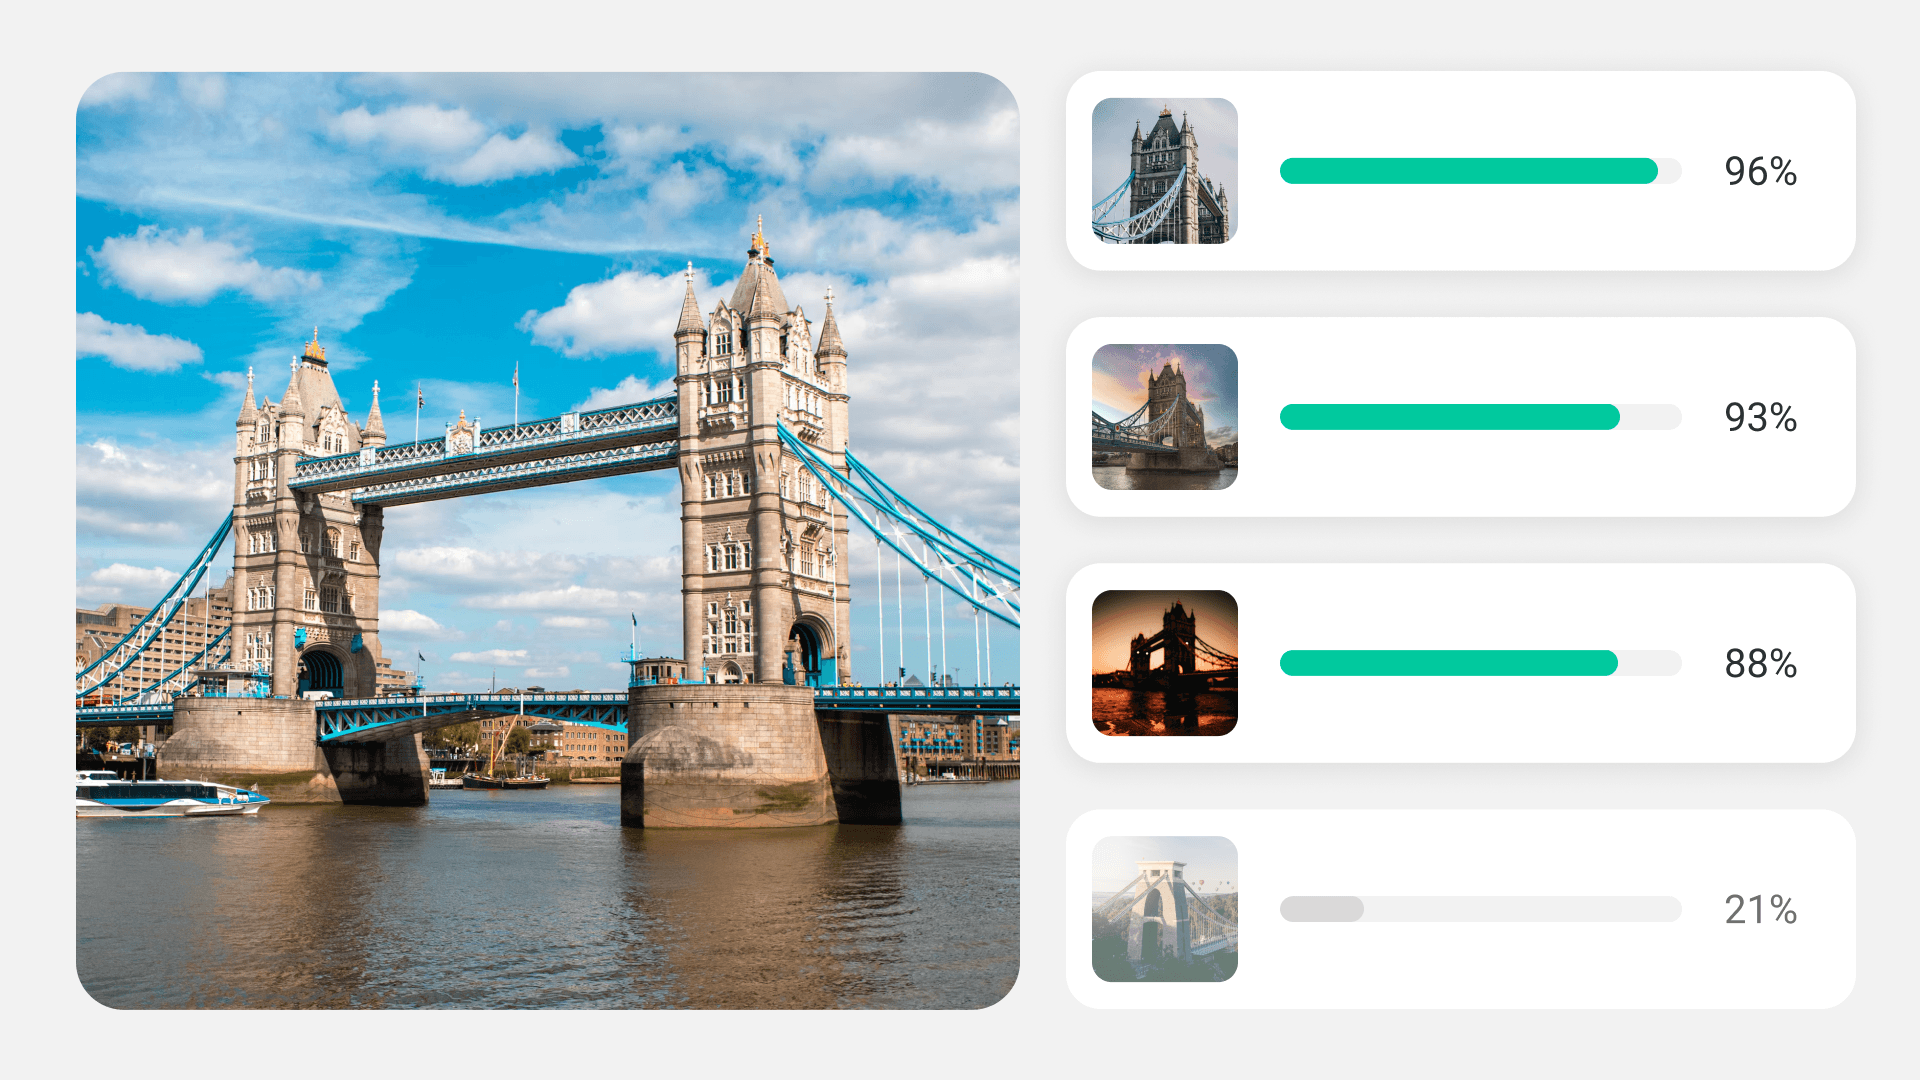
NetVLAD is a CNN-based visual place recognition model that aggregates dense local descriptors into a compact VLAD descriptor using a differentiable soft assignment to learned cluster centroids. Built on a VGG-16 backbone, it produces a 32,768-d L2-normalized descriptor suitable for nearest-neighbour place retrieval across images taken under varying conditions.
This is based on the implementation of NetVLAD found here. This repository contains pre-exported model files optimized for Qualcomm® devices. You can use the Qualcomm® AI Hub Models library to export with custom configurations. More details on model performance across various devices, can be found here.
Qualcomm AI Hub Models uses Qualcomm AI Hub Workbench to compile, profile, and evaluate this model. Sign up to run these models on a hosted Qualcomm® device.
There are two ways to deploy this model on your device:
Below are pre-exported model assets ready for deployment.
| Runtime | Precision | Chipset | SDK Versions | Download |
|---|---|---|---|---|
| ONNX | float | Universal | QAIRT 2.50, ONNX Runtime 1.30.0 | Download |
| ONNX | w8a8_mixed_int16 | Universal | QAIRT 2.50, ONNX Runtime 1.30.0 | Download |
| QNN_DLC | float | Universal | QAIRT 2.50 | Download |
| QNN_DLC | w8a8_mixed_int16 | Universal | QAIRT 2.50 | Download |
| TFLITE | float | Universal | QAIRT 2.50 | Download |
For more device-specific assets and performance metrics, visit NetVLAD on Qualcomm® AI Hub.
Use the Qualcomm® AI Hub Models Python library to compile and export the model with your own:
This option is ideal if you need to customize the model beyond the default configuration provided here.
See our repository for NetVLAD on GitHub for usage instructions.
Model Type: Model_use_case.image_classification
Model Stats:
| Model | Runtime | Precision | Chipset | Inference Time (ms) | Peak Memory Range (MB) | Primary Compute Unit |
|---|---|---|---|---|---|---|
| NetVLAD | ONNX | float | Snapdragon® 8 Elite For Galaxy Mobile | 11.288 ms | 0 - 141 MB | NPU |
| NetVLAD | ONNX | float | Qualcomm® Dragonwing™ Q-8750 | 11.288 ms | 0 - 141 MB | NPU |
| NetVLAD | ONNX | w8a8_mixed_int16 | Snapdragon® 8 Elite For Galaxy Mobile | 3.211 ms | 0 - 144 MB | NPU |
| NetVLAD | ONNX | w8a8_mixed_int16 | Qualcomm® Dragonwing™ Q-8750 | 3.211 ms | 0 - 144 MB | NPU |
| NetVLAD | QNN_DLC | float | Snapdragon® 8 Elite For Galaxy Mobile | 12.49 ms | 4 - 143 MB | NPU |
| NetVLAD | QNN_DLC | float | Qualcomm® Dragonwing™ Q-8750 | 12.49 ms | 4 - 143 MB | NPU |
| NetVLAD | QNN_DLC | w8a8_mixed_int16 | Snapdragon® 8 Elite For Galaxy Mobile | 3.16 ms | 0 - 142 MB | NPU |
| NetVLAD | QNN_DLC | w8a8_mixed_int16 | Qualcomm® Dragonwing™ Q-8750 | 3.16 ms | 0 - 142 MB | NPU |
| NetVLAD | TFLITE | float | Snapdragon® 8 Elite For Galaxy Mobile | 11.272 ms | 0 - 145 MB | NPU |
| NetVLAD | TFLITE | float | Qualcomm® Dragonwing™ Q-8750 | 11.272 ms | 0 - 145 MB | NPU |