

PILOT: RoboCasa-GR1 340000
Physical Inference for Latent Optimized Trajectories
Built on NVIDIA Cosmos.
Model and simulation resources accompanying Motion Chain of Thought: Disentangling Motion Semantics from Visual Appearance for Robotic Manipulation, an anonymous ICLR 2027 submission under review.
Code | Project | Evaluation guide | Training guide | Evaluation logs | Validation status
Start Here
| Goal | Guide |
|---|---|
| Download, verify hashes, or supplement a GitHub checkout | Download and access |
| Evaluate one episode or the 24-task benchmark | Evaluation |
| Supply training data, fine-tune or resume | Training |
| Inspect the original results without GPUs | Recorded logs and CPU audit |
The repository ID remains mxk1998/WM4A. The project and the current
artifact are named PILOT. This snapshot selects the 340000-step
RoboCasa-GR1 checkpoint.
Model
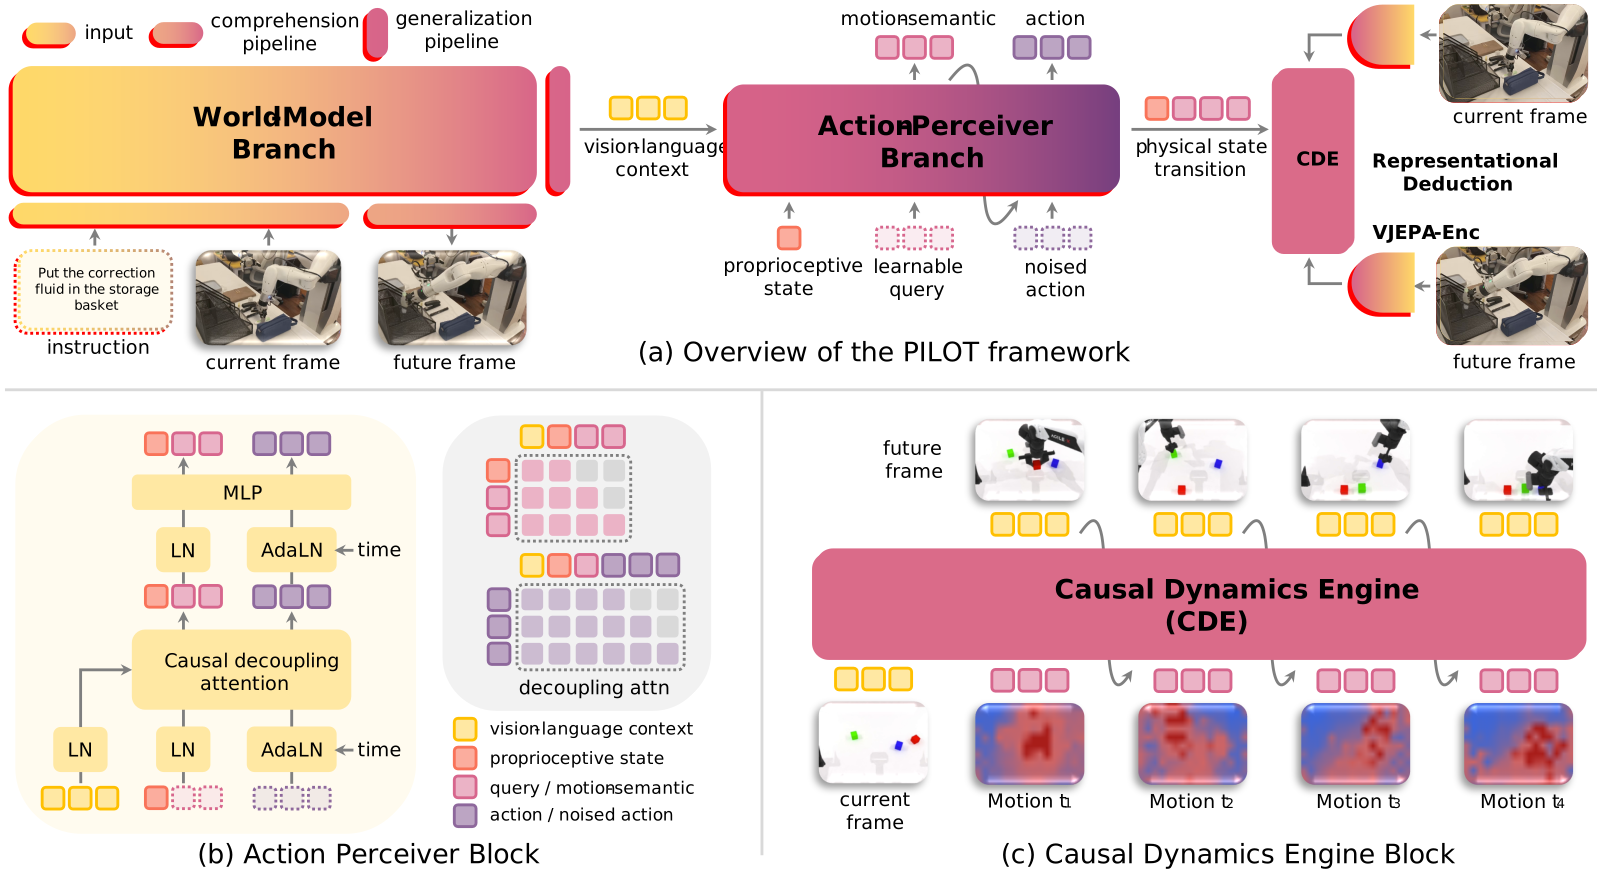
PILOT combines Cosmos-Predict2.5 context features, a Perceiver-style flow-matching action head with learned Motion-CoT queries, and training-time Representational Deduction using VJEPA2-AC future features. The action head uses current observation, instruction, and robot state. Generated future RGB images are optional diagnostics, not required intermediate inputs to the action policy.
This resource contains the selected checkpoint, compatible framework and training code, evaluation scripts, tokenizer/model metadata, GR1 retargeting data, environment setup, and sanitized results. Training demonstrations and other benchmark checkpoints are not included.
The simulator archive is archives/simulation_assets.tar.gz
(4,526,090,391 bytes, 45,853 files when unpacked), including
RoboCasa/RoboSuite sources, robot/object assets and GR1 retargeting data.
Environment variables are provided in environment/activate_paths.sh;
Linux dependency environments must still be installed.
| Property | Value |
|---|---|
| Architecture | CosmoPredict25PerceiverVJEPA2AC |
| Checkpoint step | 340000 |
| File | checkpoints/steps_340000_pytorch_model.pt |
| Bytes | 23,913,608,021 |
| Tensor entries | 2596 |
| Latent coordinates | legacy |
| Policy action horizon / executed chunk | 16 / 12 |
| Action integration | 20 steps |
| Optional visualization | 5 frames |
| Platform | Linux x86_64, NVIDIA CUDA, EGL |
SHA-256:
34bf115c1c99a33b12c79e1dca20e596cd510f006060687c2f145fecea58e60e
Download And Install
python -m pip install huggingface_hub
hf download mxk1998/WM4A --local-dir PILOT
cd PILOT
python -m release.unpack_assets  # If assets were distributed as an archive.
python -m release.verify --assets

bash environment/create_linux_envs.sh /absolute/new/pilot-envs
export POLICY_PYTHON=/absolute/new/pilot-envs/policy/bin/python
export SIM_PYTHON=/absolute/new/pilot-envs/simulation/bin/python
source environment/activate_paths.sh
"$POLICY_PYTHON" -m release.doctor --role policy
"$SIM_PYTHON" -m release.doctor --role simulation
"$POLICY_PYTHON" -m release.prepare
The policy and simulator have separate Python 3.10 environments.
release.prepare reconstructs constructor-compatible components directly
from the original checkpoint without changing tensor values. Its cache
requires roughly another checkpoint's worth of disk space. Plan for
120 GiB free disk and 128 GiB host RAM. macOS is supported as an archive
location, not as a native simulation/inference platform.
Evaluation Usage
Inspect your assigned GPUs with nvidia-smi. Replace the example physical
GPU IDs below with devices actually allocated to you.
# One-task, one-episode smoke test.
"$POLICY_PYTHON" -m release.evaluate \
  --gpus 0 --render-gpu 0 \
  --policy-python "$POLICY_PYTHON" --sim-python "$SIM_PYTHON" \
  --episodes 1 --seed 9000 \
  --task gr1_unified/PosttrainPnPNovelFromCuttingboardToPanSplitA_GR1ArmsAndWaistFourierHands_Env \
  --output /absolute/new/pilot-smoke

# Complete 24-task protocol, 50 episodes per task.
"$POLICY_PYTHON" -m release.evaluate \
  --gpus 0,1 --render-gpu 1 \
  --policy-python "$POLICY_PYTHON" --sim-python "$SIM_PYTHON" \
  --episodes 50 --seed 9000 --workers-per-policy 4 \
  --output /absolute/new/pilot-full-evaluation
The fixed contract uses Task: prompts, legacy latent coordinates,
20 action-sampling steps, chunk 12, and 720 physical steps per episode.
Success is the native task predicate satisfied at any executed physical
step; successful episodes are not terminated early. Seeded scene
initialization, per-request policy sampling seeds, and per-environment
IK-cache clearing are part of the contract.
The launcher writes policy logs, per-task simulation logs, episode records,
action-request seeds/hashes, physical-step diagnostics, task result.json
files, and aggregate summary.json. It fails rather than treating an
incomplete task as a completed evaluation. See the full guide.
Results And Limitations
The original checkpoint achieved 717/1200 (59.75%) in the completed repaired-protocol source evaluation. The manuscript reports 58.3% for its reported RoboCasa experiment. These are different measurements and must not be presented as the same run.
Per-task results are in results/robocasa_340000.json. The score belongs to the original 340000 checkpoint, not a later 1000-update training-validation export. A fresh-machine installation of this portable package has not itself been shown to reproduce the score.
Download the sanitized evaluation logs
or inspect 680 historical training metric records.
From this repository root, python3 -m release.audit_logs verifies archive/member
hashes and recomputes 717/1200 from all 24 task logs and 1200 diagnostics.
It needs no model weights or GPU. This checks recorded evidence, not
regenerated model actions; raw per-request streams are not bundled.
See provenance, redactions and limitations.
The auxiliary image predictor is not a validated long-video model. Matched latent coordinates remove the diagnosed scale mismatch, but held-out full-image MSE still does not establish superiority to copying the current image. Single-rank 1000-update training/resume checks do not establish long-horizon convergence or multi-GPU training reproducibility. See training details for the archived recipe and its differences from manuscript hyperparameters.
Training
"$POLICY_PYTHON" -m pip install -r environment/training.requirements.txt
export CUDA_VISIBLE_DEVICES=0
export PILOT_DATA_ROOT=/absolute/path/to/converted-datasets
export PILOT_OUTPUT_ROOT=/absolute/new/training-runs
bash run_training.sh --trainer.max_train_steps 1000 \
  --trainer.save_interval 500 --trainer.logging_frequency 50
This is weight-only fine-tuning with a fresh optimizer, not recovery of the historical optimizer. Full-state resume and original-pretrained initialization are documented in docs/TRAINING.md.
License, Attribution And Anonymity
Retain all third-party licenses and notices. Code, pretrained components, and simulation assets have component-specific terms; this repository does not relicense them as a single unrestricted model. See LICENSE.md and THIRD_PARTY_NOTICES.md.
The README omits first-party personal names and affiliations. Repository ownership and pre-existing history are not anonymized by editing files. Repository visibility must be managed separately.