

LiteGPT V2 Base
A 201M-parameter language model built from scratch, with every step on record.
LiteGPT V2 has its own architecture implementation, its own trained tokenizer and its own weights. It was pretrained in 37 hours on a single rented GPU, and every experiment behind it was registered before it ran. Results, charts and run records: github.com/kmkrofficial/LiteGPT.
Highlights
- A big step up from LiteGPT V1: clearly better on five benchmarks and clearly worse on none, and about three times better on code text (bits per byte 1.612 → 0.515).
- Strong code modelling for its size: the lowest code bits per byte of every model under 300M parameters we measured.
- Light to run: 0.59 GiB of GPU memory at batch 8 with LiteGPT's engine, and 1.66 GiB of RAM on CPU.
- Good at structured output once fine-tuned: 91.4% accuracy on Banking77 intents, and valid JSON on 99.99% of MASSIVE requests.
- Loads in Transformers with no remote code.
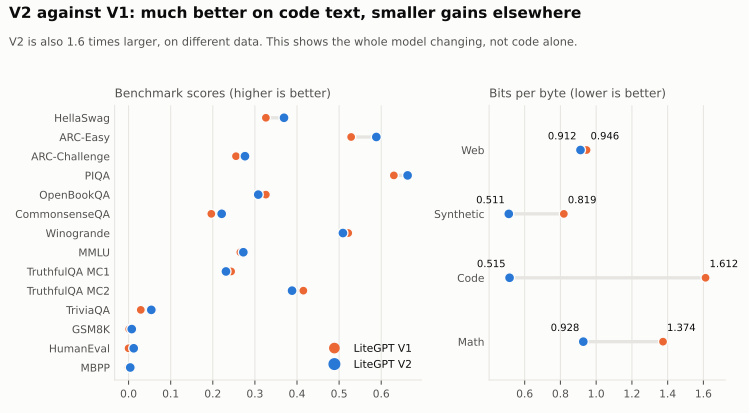
Results
| Benchmark | V2 | V1 |
|---|---|---|
| Zero-shot mean, 10 tasks | 0.383 | 0.371 |
| ARC-Easy | 0.588 | 0.529 |
| HellaSwag | 0.369 | 0.326 |
| PIQA | 0.663 | 0.630 |
| TriviaQA | 0.054 | 0.029 |
| Code, bits per byte (lower is better) | 0.515 | 1.612 |
| Math, bits per byte (lower is better) | 0.928 | 1.374 |
After fine-tuning on each task:
| Task | Score |
|---|---|
| Banking77, intent accuracy | 0.914 |
| MASSIVE, slot F1 | 0.775 |
| CUAD, contract field F1 | 0.711 |
Every benchmark, including comparisons with 16 other models: results.
How it compares
LiteGPT V2 doesn't reach the top score in these comparisons. What it brings is a model built entirely from scratch, light enough for a laptop, and open down to every run record.
Text-to-data, after fine-tuning each model the same way (mean of 3 seeds, higher is better):
| Model | Parameters | Score | Banking77 | MASSIVE | CUAD | Peak RAM on CPU |
|---|---|---|---|---|---|---|
| Qwen3-0.6B | 596M | 0.851 | 0.931 | 0.812 | 0.809 | 4.27 GiB |
| Gemma 3 270M | 268M | 0.822 | 0.919 | 0.778 | 0.768 | 2.62 GiB |
| SmolLM2-135M | 135M | 0.817 | 0.920 | 0.787 | 0.745 | 1.61 GiB |
| LiteGPT V2 | 201M | 0.800 | 0.914 | 0.775 | 0.711 | 1.66 GiB |
As a base model (higher is better, except bits per byte and memory):
| Model | Zero-shot mean, 10 tasks | Code bits per byte | GPU memory, batch 8 |
|---|---|---|---|
| Qwen3-0.6B-Base | 0.489 | 0.372 | 2.72 GiB |
| SmolLM2-135M | 0.403 | 0.559 | 0.73 GiB |
| Gemma 3 270M | 0.393 | 0.617 | 2.59 GiB |
| LiteGPT V2 | 0.383 | 0.515 | 0.59 GiB |
| LiteGPT V1 | 0.371 | 1.612 | 0.78 GiB |
V2's memory figures use its own engine and the others use Transformers.
Model
| Item | Value |
|---|---|
| Parameters | 201,373,952 |
| Shape | 28 layers, 768 wide, 12 heads, 4 KV heads |
| Parts | RoPE, RMSNorm, QK-norm, SwiGLU, grouped-query attention |
| Context | 4,096 tokens |
| Tokenizer | 32,768-token byte-level BPE, trained on our data with Hugging Face tokenizers |
Use
With Transformers:
from transformers import AutoModelForCausalLM, AutoTokenizer

name = "kmkrworks/LiteGPT-V2-Base"
tokenizer = AutoTokenizer.from_pretrained(name)
model = AutoModelForCausalLM.from_pretrained(name)
inputs = tokenizer("The capital of France is", return_tensors="pt")
print(tokenizer.decode(model.generate(**inputs, max_new_tokens=32)[0], skip_special_tokens=True))
With LiteGPT's own engine, from a clone of the repository:
uv sync --locked
uv run litegpt generate --model LiteGPT-V2-Base "The capital of France is"
Benchmarks were scored through LiteGPT's engine.
Intended use: research, learning, and fine-tuning for your own tasks. It is a base model with no safety tuning, so add your own safeguards before putting it in front of people.
Training data
Pretrained on a mix chosen in registered experiments. Mixture and exact revisions: data_sources.yaml. Attributions: the NOTICE file.
| Source | Licence | Main phase | Decay phase |
|---|---|---|---|
| FineWeb-Edu | ODC-By 1.0, Common Crawl terms | 72% | 50% |
| Cosmopedia v2 (generated by Mixtral-8x7B-Instruct) | ODC-By 1.0 | 13% | 20% |
| FineMath | ODC-By 1.0, Common Crawl terms | 7.5% | 13% |
| Code: Python, JS, TS, SQL, Shell from github-code-clean | Permissive repository labels | 7.5% | 12% |
| SmolTalk summarize, rewrite, constraints (generated by Qwen2.5-72B-Instruct) | Apache-2.0 per card, Qwen licence on the generator | 0% | 5% |
Contains information from FineWeb-Edu, Cosmopedia v2 and FineMath, which are made available under the ODC Attribution License.
Licence
Apache-2.0 for the weights, MIT for the code, with the NOTICE file.
Built with Qwen.
- Downloads last month
- 153