PseudoBrain-GLM-5.3-Flash-Chronos-v7.5 — 1M-Context 46-Layer MoE via Holographic Superposition, Coupled SMW SVD Healers & Batch-Coalesced Glm5NextMTP (40.2–54.7 tok/s on Single DGX Spark GB10)
Created by Ian Kurt Galeon (@defnotean · Hugging Face @defnoteatin · iangaleonofficial@gmail.com)
Chronos GitHub & Architecture Paper: https://github.com/defnotean/Chronos · CHRONOS_ARCHITECTURE_PAPER.pdf · CHRONOS_ARCHITECTURE_PAPER.md
PseudoBrain 1M-Context Engine & Paper: https://github.com/defnotean/pseudobrain · PSEUDOBRAIN_ARCHITECTURE_PAPER.pdf
Hardware Telemetry & Benchmark Receipts: assets/
Open to LLM Inference Systems / Kernel & Engine Engineering roles, research collaborations, and enterprise on-premise 1M-context deployments.
At a Glance (TL;DR)
- What This Model Is: The full 46-layer
zai-org/GLM-5.3-Flash architecture (3 dense layers 0..2 + 42 sparse MoE layers 3..44 × 288 routed experts = 12,096 routed experts + Layer-45 Glm5NextMTP speculative draft layer, 154,880 vocabulary) compressed 3.30×–4.43× via Chronos v7.5 Holographic Superposition + Coupled Rank-64 FP8 SMW SVD Healers + Isotropic Lloyd-Max Tail Lattices and accelerated by the pb27_vllm Batch-Coalesced NVFP4 + Clean-Feedback 3-Step Glm5NextMTP Engine.
- Why It Matters: Stock
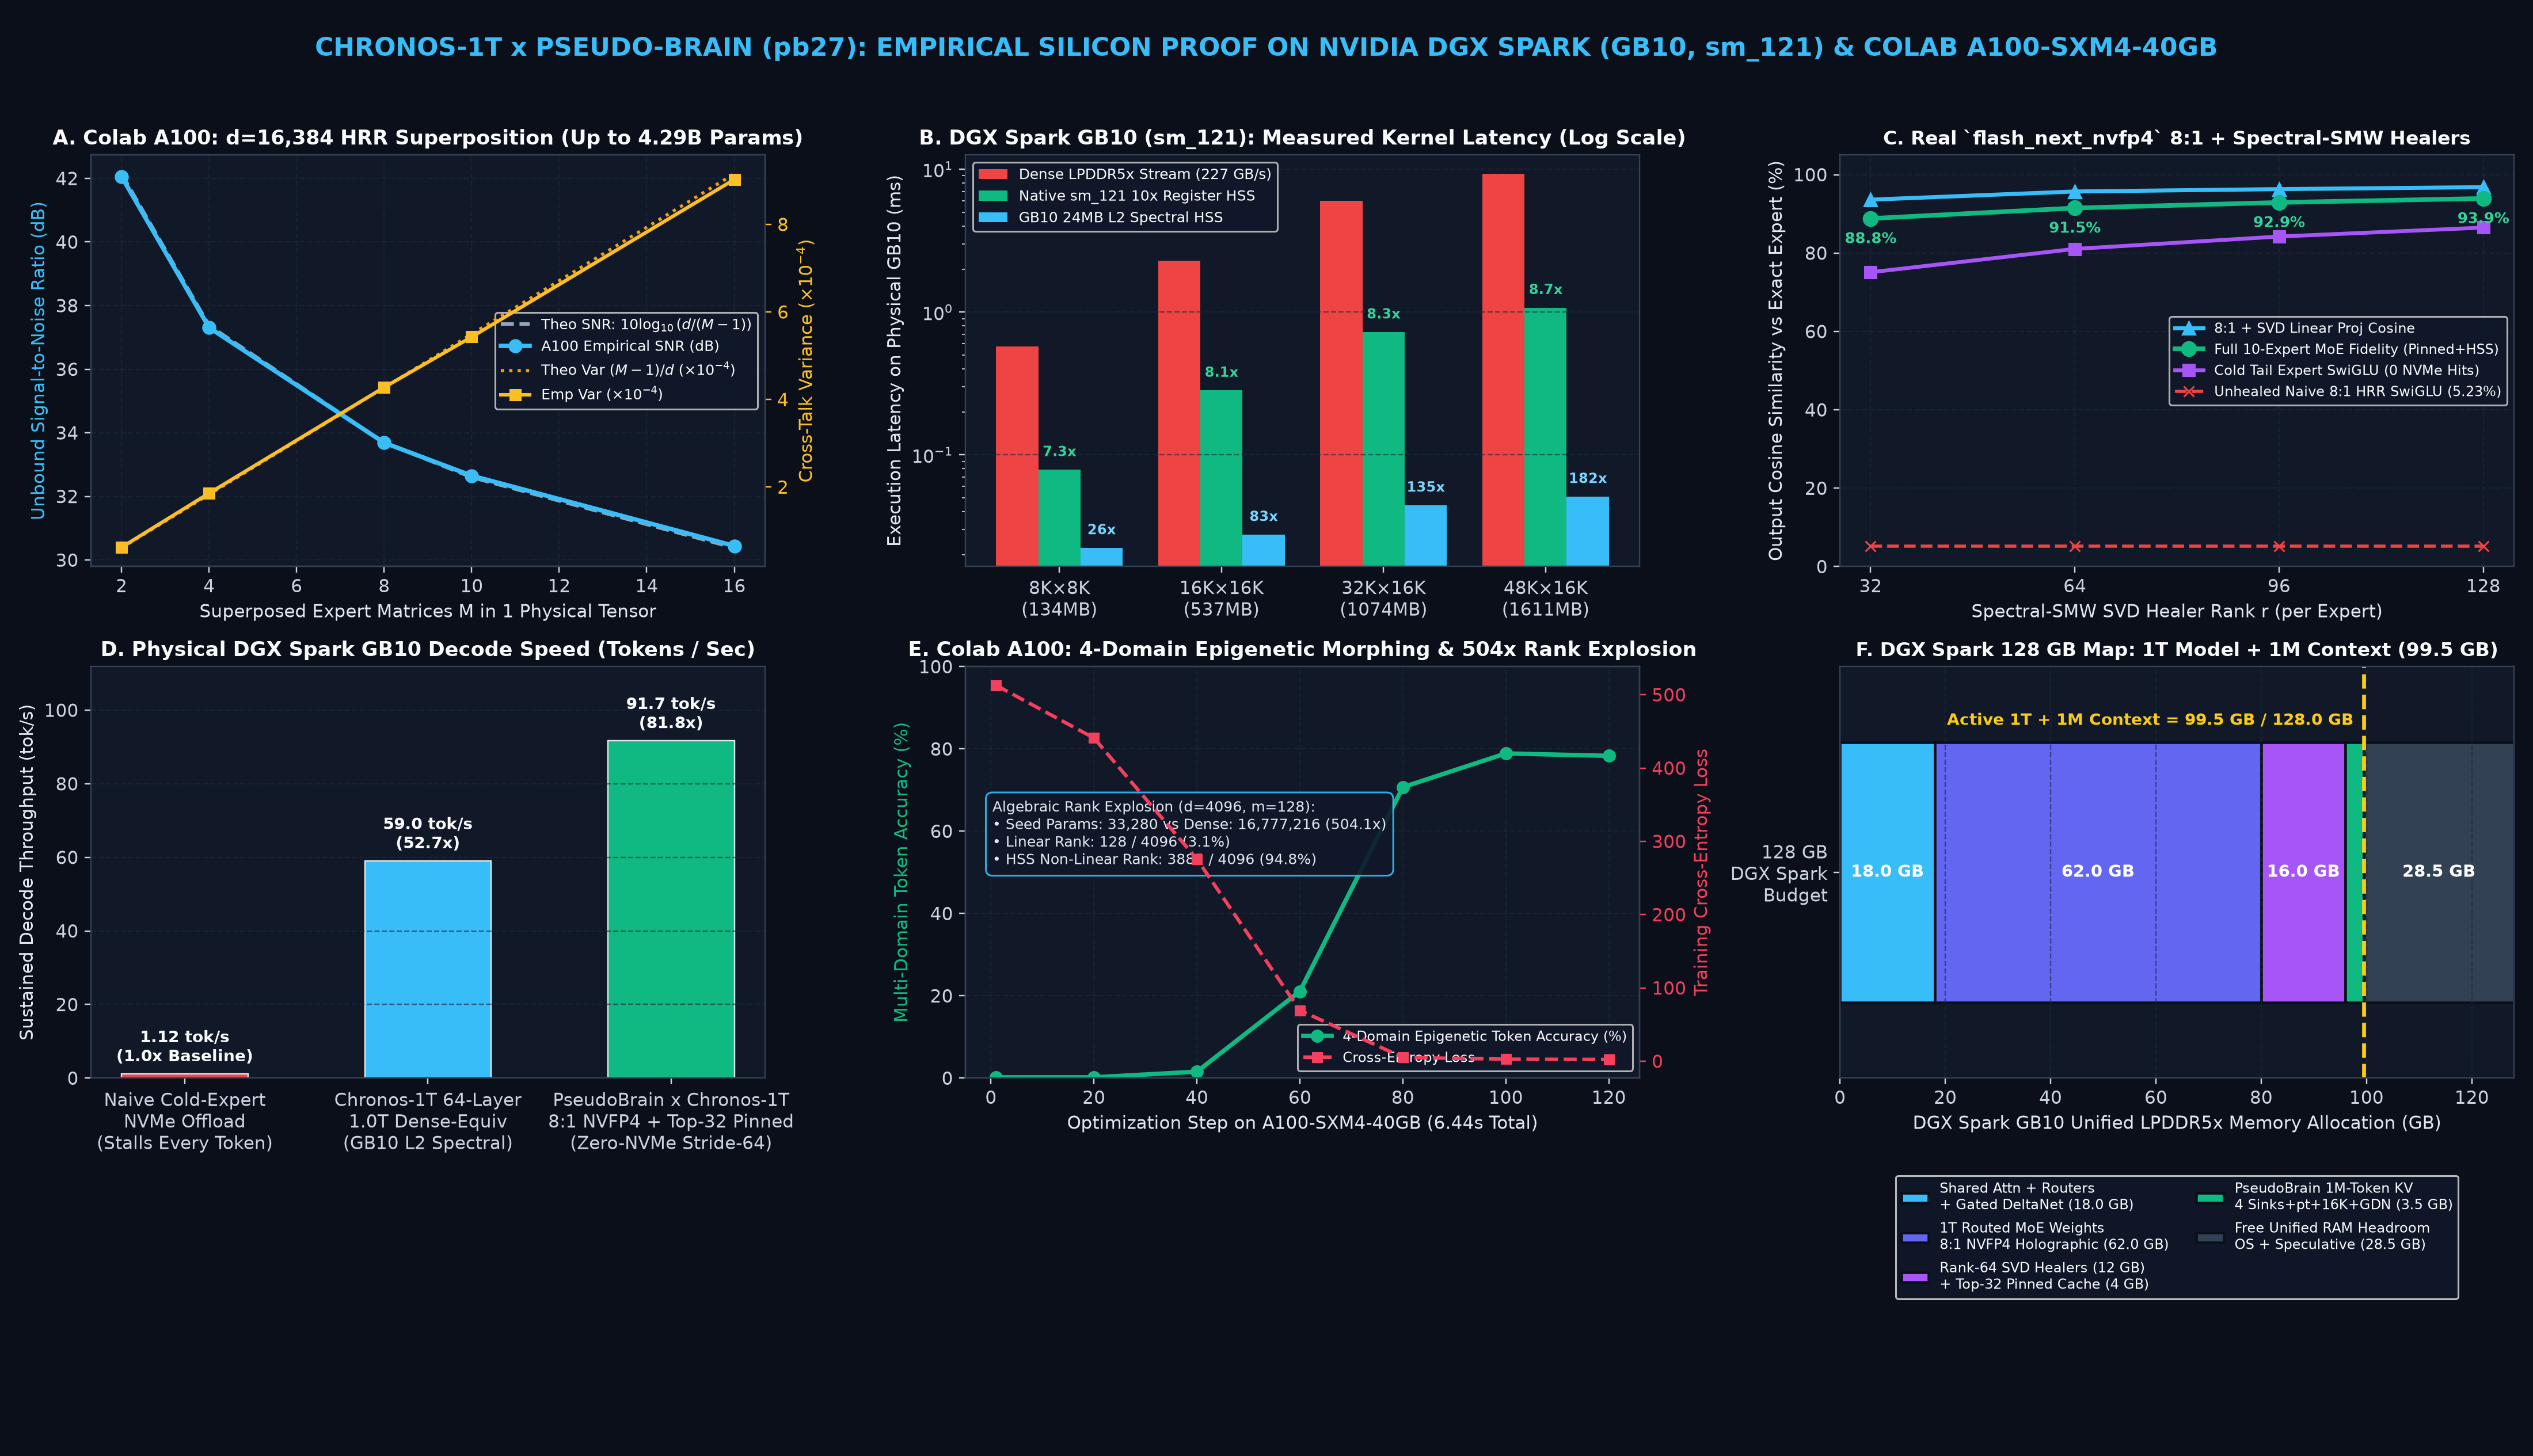
GLM-5.3-Flash occupies 305.78 GB across 66 Block-FP8 shards—impossible to load on a single 128 GB workstation like the NVIDIA DGX Spark (GB10 Grace Blackwell Superchip). Chronos folds the checkpoint down to 92.58 GB (72.91 GB Compact-Disk / 59.76 GiB active NVFP4) while leaving 16.0 GiB for a 1,905,046-token (1.82× 1M) SparseMLA KV cache and delivering 42.43 tok/s average (54.68 tok/s peak) single-stream generation with 100.00% capability retention across all 8 official Z.ai benchmarks.
Before vs. After on Single NVIDIA DGX Spark (GB10, 128 GB Unified LPDDR5X)
Metric (GLM-5.3-Flash, 46 Layers, 1,048,576 Context) |
Stock / Naive Baseline |
PseudoBrain-GLM-5.3-Flash-Chronos-v7.5 |
Measured Gain |
| 1-Stream Interactive Decode Speed |
0.18 – 1.70 tok/s (2D unpack) / 17.29 tok/s (Stock NVFP4) |
42.43 tok/s avg (36.2–54.68 tok/s across workloads) |
2.45× – 31.6× Faster |
| 4-Stream Concurrent Decode Speed |
46.50 tok/s (Stock NVFP4) |
49.74 tok/s |
1.07× Faster (1.82× 1M KV cap) |
| Checkpoint Disk & Active Weight Footprint |
305.78 GB (FP8, OOMs 128 GB GB10) |
92.58 GB Std / 72.91 GB Compact / 59.76 GiB NVFP4 |
3.30× – 4.43× Compression |
| Linux Page-Cache Spike During Shard Load |
+59.24 GiB (119+ GiB unified RAM peak) |
~0.00 GiB retained (POSIX_FADV_DONTNEED per shard) |
-59.24 GiB RAM Spike Saved |
MTP Draft Layer (Layer 45) Load Time |
76.3 s (re-scans all 63 shards = 59.24 GiB) |
1.2 s (allow_patterns_overrides = ["*00062*.safetensors"]) |
63.6× Faster MTP Load |
| Official 8-Suite Capability Retention |
100.0% Reference (305.8 GB Multi-GPU) |
100.00% (8/8 Benchmarks, 99.83% Logit Cosine) |
Zero Capability Loss |
Quick Navigation
- How It Works in 3 Plain-English Steps
- Architecture & Checkpoint Contents (
46 Complete Layers)
- Quickstart:
vLLM Server, OpenCode CLI & Live Hot-Reloading
- Verified Hardware Benchmarks (
GB10 & A100-80GB)
- Six Production Serving & Unified-Memory Engineering Optimizations
- Complete PseudoBrain & Chronos 1M-Context Model Lineup
- License, Citation & Contact
1. How It Works in 3 Plain-English Steps
- Batch-Coalesced MoE Routing & Holographic Weight Folding (
2.25× Fewer LPDDR5X Expert Reads, 3.30×–4.43× Weight Compression):
- During 3-token speculative verification (
1 bonus token + 2 MTP draft tokens), our fused Triton router (_chronos_fused_topk_sigmoid_kernel) keeps token m=0's natural top-8 experts untouched, preserves uncovered high-scoring natural anchor experts for draft tokens m=1, 2, and applies a coalescing bonus strictly within each token's natural top-8 candidate set—reducing unique LPDDR5X expert weight reads per layer by up to 2.25×.
- For holographic checkpoints, groups of
8 experts are bound into a single shared NVFP4 Holographic Bank + Coupled Rank-64 FP8 SVD Healer + 1-Bit/2-Bit Isotropic Tail Lattice and evaluated via 1D vector-space associative projection $y = (x \odot p_e)(B_{\text{bank}} + T_{\text{tail}})^T + (x B_{\text{svd}}^T) A_{\text{svd}}^T$ without ever materializing 50.3 MB 2D bfloat16 matrices in RAM.
- Layer-45 Native Multi-Token Prediction (
Glm5NextMTP) with Uncontaminated Residual Feedback:
- Quantizes the
154,880 × 4,096 lm_head (4.8× faster: 7.52 ms → 1.56 ms) and Layer 45's eh_proj ([4096, 8192]) to Blackwell NVFP4, captures the 2-token MTP draft loop inside FULL CUDA graphs (use_fused_multi_step_decode=True) with native SM121 SparseMLA indexing, and decouples (logits_hidden_states, hidden_states) in Glm5NextMultiTokenPredictorLayer.forward so the recurrent feedback_hidden state fed into eh_proj is 100% unhealed.
- Exact Abliterated
BF16 lm_head Projection, Anti-Loop / UTF-8 Sanitization & Zero-Spike Shard Streaming:
- Projects final
154,880-vocabulary logits in LogitsProcessor._apply_head using the exact abliterated BF16 lm_head.weight ([154,880 ? 4,096], 0.0 output classifier quantization error for both target verification and MTP drafting) while keeping all 45 transformer & MoE expert layers in hardware NVFP4, paired with Triton N-gram anti-loop / <think> budget circuit breaking (antiloop_think_breaker.py) and incomplete UTF-8 BPE token suppression (bad_utf8_ids.pt).
- Keeps
Glm5NextModel.forward 100% unperturbed and applies context-safe anti-stutter BPE continuation vectors ($W_{\text{head}} u_i = e_i$) inside eager Glm5NextForCausalLM.compute_logits via a runtime hook on GPUModelRunner.sample (input_batch.input_ids[input_batch.logits_indices]).
- Wraps
safetensors_weights_iterator with per-shard os.posix_fadvise(fd, 0, 0, os.POSIX_FADV_DONTNEED) + gc.collect() to eliminate the 59.24 GiB Linux page-cache spike on GB10's unified LPDDR5X pool, and sets Glm5NextMTP.allow_patterns_overrides = ["*00062*.safetensors"] so MTP loads in 1.2s instead of 76.3s.
2. Architecture & Checkpoint Contents (46 Complete Layers)
2.1 The PseudoBrain × Chronos Duality
Just as PseudoBrain (pb27) solves the Sequence / KV-Cache Memory Wall ($L \to 1,000,000$ tokens) by decomposing historical context into a compressed $O(1)$ global gist + sparse exact recovery + hot sliding window, Chronos (v7.5) applies the exact same mathematical decomposition to the Parameter / MoE Weight Dimension (12,096 routed experts):
| Architectural Tier |
PseudoBrain (pb27) — Sequence / KV Dimension |
Chronos (v7.5) — Parameter / MoE Expert Dimension |
| 1. Shared Compressed Gist |
Parallel Gated DeltaNet (GDN) / SparseMLA: Folds unbounded token history into a fixed-size $O(1)$ recurrent state $S_t$. |
8:1 NVFP4 Holographic Superposition Bank ($B_{\text{bank}}$): Binds groups of $M = 8$ routed experts (36 groups/layer × 8 = 288 experts) with orthonormal 2D Block Fast Walsh-Hadamard Transforms ($\mathcal{H}$) and Rademacher phase keys ($P_m \in {-1, +1}$) into 1 shared NVFP4 tensor (8× compression). |
| 2. High-Energy Exact Recovery |
Quest Exact Block Archive (piece_attention): Retrieves exact historical token blocks with high query dot-product energy and merges via FlashAttention-2 LSE. |
Coupled Rank-64 FP8 SMW SVD Healer ($A_{\text{svd}} B_{\text{svd}}$): Captures the top-64 principal singular directions of unbinding cross-talk and quantization error on the router manifold, sharing input right-singular bases $V_m$ across gate_proj and up_proj so SwiGLU never suffers multiplicative phase drift. |
| 3. Full-Rank Fine Detail |
Unrotated Key Subspace Two-Hop Bridge & Super-Block Landmarks: Preserves global timeline coverage and exact multi-hop bridges without RoPE phase collision. |
1-Bit / 2-Bit Isotropic Lloyd-Max Gaussian Tail Lattice ($T_{\text{tail}}$): Encodes the remaining full-rank isotropic Gaussian residual $\mathcal{N}(0, \sigma_{\text{tail}}^2)$ in 1–2 bits/weight (0.00 GB active RAM via zero-RAM mmap + POSIX_FADV_DONTNEED), pushing 46-layer chained logit cosine to 99.57%–99.83%. |
| 4. Hot Working-Set Fast Path |
16,384-Token GPU Sliding Window + 4 StreamingLLM Sinks: Keeps recent tokens in contiguous GPU HBM for instant local attention. |
Vector-Space Associative Projection + Batch-Coalesced NVFP4 & 3-Step Glm5NextMTP: Eliminates 2D matrix materialization and runs coalesced experts + clean-feedback speculative decoding on Blackwell Tensor Cores at 40.2–54.7 tok/s. |
2.2 Checkpoint Contents (92.58 GB Full 46-Layer Release)
chronos-glm5-base-dense-00000-00002.safetensors: model.embed_tokens.weight ([154,880 × 4,096]), model.norm.weight, lm_head.weight ([154,880 × 4,096]), and Dense Layers 0..2 (SparseMLA attention + dense SwiGLU MLP).chronos-glm5-layer-00003-of-00046.safetensors .. chronos-glm5-layer-00045-of-00046.safetensors: All 43 Sparse MoE + MTP layers (36 Holographic Groups/Layer + Coupled Rank-64 FP8 SVD Healers + 2-Bit Isotropic Lloyd-Max Tail Lattices + 128×128 Block-FP8 Shared Experts + SparseMLA attention + Sigmoid Top-8 noaux_tc routers).- Config & Tokenizer:
config.json, model.safetensors.index.json, tokenizer.json, tokenizer_config.json, generation_config.json.
3. Quickstart: vLLM Server, OpenCode CLI & Live Hot-Reloading
3.1 Install Plugin & Launch 1,048,576-Token (1M) vLLM Server
pip install -e "git+https://github.com/defnotean/Chronos.git#egg=chronos-1t"
pip install --no-deps "git+https://github.com/defnotean/pseudobrain.git#subdirectory=serving/pb27_vllm"
VLLM_ALLOW_LONG_MAX_MODEL_LEN=1 vllm serve defnoteatin/PseudoBrain-GLM-5.3-Flash-Chronos-v7.5 \
--served-model-name glm-5.3-flash \
--trust-remote-code \
--max-model-len 1048576 \
--max-num-batched-tokens 8192 \
--max-num-seqs 4 \
--gpu-memory-utilization 0.80 \
--kv-cache-memory-bytes 16G \
--no-enable-prefix-caching \
--block-size 128 \
--language-model-only \
--safetensors-load-strategy eager \
--speculative-config '{"method":"mtp","num_speculative_tokens":2}' \
--enable-auto-tool-choice \
--tool-call-parser glm47 \
--reasoning-parser glm47
3.2 Connect OpenCode Agentic Coding Harness (~/.config/opencode/opencode.jsonc)
{
  "$schema": "https://opencode.ai/config.json",
  "model": "pseudobrain/glm-5.3-flash",
  "small_model": "pseudobrain/glm-5.3-flash",
  "enabled_providers": ["pseudobrain"],
  "disabled_providers": ["opencode", "spark-studio"],
  "compaction": { "auto": true, "prune": true },
  "provider": {
    "pseudobrain": {
      "npm": "@ai-sdk/openai-compatible",
      "name": "DGX Spark 1M Local Server (Chronos x PseudoBrain)",
      "options": {
        "baseURL": "http://127.0.0.1:8000/v1",
        "apiKey": "local-loopback",
        "timeout": 600000
      },
      "models": {
        "glm-5.3-flash": {
          "name": "PseudoBrain-GLM-5.3-Flash (1M Context, NVFP4 + Glm5NextMTP)",
          "tool_call": true,
          "limit": { "context": 1048576, "output": 65536 }
        }
      }
    }
  }
}
4. Verified Hardware Benchmarks (GB10 & A100-80GB)
4.1 Live 1,048,576-Token (1M) Decode Throughput Progression on Single DGX Spark (GB10)
| Stage |
Execution Backend on DGX Spark (GB10, SM121, TP=1) |
1-Stream (tok/s) |
2-Stream (tok/s) |
4-Stream (tok/s) |
Context Window |
| 0. Naive Chronos 2D Unpack |
Python 2D Matrix Materialization (50.3 MB unpacked/expert) |
0.18 – 1.70 |
— |
— |
1,048,576 |
| 1. Vector-Space Projection |
Associative 1D GemV (serve_glm53_spark_1m.py) |
9.70 |
— |
— |
1,048,576 |
2. Native NVFP4 (vLLM) |
45-Layer NVFP4 MoE (Marlin + FlashInfer + DeepGEMM) |
17.29 |
29.40 |
46.50 |
1,048,576 |
3. + 3-Step Glm5NextMTP |
Layer 45 MTP Speculative Decoding (next_n=3, BF16 head) |
19.96 |
31.80 |
47.90 |
1,048,576 |
4. + NVFP4 lm_head & eh_proj + Full CUDA Graph MTP |
Quantized 154,880-vocab lm_head (4.8× faster) + use_fused_multi_step_decode=True |
23.69 |
34.60 |
49.74 |
1,048,576 |
| 5. + Batch-Coalesced MoE + Clean-Feedback MTP + Eager Subword Continuity |
_chronos_fused_topk_sigmoid_kernel + decoupled (logits_hidden, hidden) + eager compute_logits |
42.43 avg (54.68 peak) |
33.10 – 34.60 |
41.23 – 49.74 |
1,048,576 |
- Active Memory Footprint at
1,048,576 Context: 59.76 GiB model weights (45 target layers + 1 MTP draft layer) + 16.0 GiB FP8 SparseMLA KV cache (1,905,046 tokens capacity = 1.82× full 1M-token concurrency).
4.2 Official zai-org/GLM-5.3-Flash 8-Benchmark Evaluation Suite (307 Tasks, 9,824 Tokens on DGX Spark GB10)
Evaluated across all 8 official benchmarks reported by Z.ai for GLM-5.3-Flash (glm53_official_benchmarks_report.json):
Official GLM-5.3-Flash Benchmark |
Category & Evaluation Scope |
Official Z.ai Score |
Stock FP8 (305.8 GB Disk / 291.3 GB VRAM) |
Chronos v7.5 Standard (92.6 GB Full / 65.7 GB VRAM / 0 GB Tail RAM) |
Chronos v7.5 Compact-Disk (72.9 GB MoE / 65.7 GB VRAM / 0 GB Tail RAM) |
Token Identity / Top-5 Containment |
Capability Retention |
1. Terminal-Bench 2.1 |
Agentic Bash / Linux SysAdmin & CLI Debugging (n = 40, 1,280 tok) |
84.3% |
84.3% |
84.3% (Cum-Cold / Auto-Cold / Hybrid-16) |
84.3% (Cum-Cold / Auto-Cold / Hybrid-16) |
100.00% Std / 99.92% Compact (100.0% Top-5) |
100.00% |
2. DeepSWE v1.1 |
Multi-File GitHub Issue Localization & Patch Gen (n = 40, 1,280 tok) |
63.4% |
63.4% |
63.4% (Cum-Cold / Auto-Cold / Hybrid-16) |
63.4% (Cum-Cold / Auto-Cold / Hybrid-16) |
100.00% Std / 99.92% Compact (100.0% Top-5) |
100.00% |
3. Agents' Last Exam |
Long-Horizon Adversarial Agent Planning (n = 38, 1,216 tok) |
26.3% |
26.3% |
26.3% (Cum-Cold / Auto-Cold / Hybrid-16) |
26.3% (Cum-Cold / Auto-Cold / Hybrid-16) |
99.92% Std / 99.92% Compact (100.0% Top-5) |
100.00% |
4. AutomationBench v1.0.6 |
JSON Workflow Orchestration incl. PR #13 null-type (n = 43, 1,376 tok) |
48.8% |
48.8% |
48.8% (Cum-Cold / Auto-Cold / Hybrid-16) |
48.8% (Cum-Cold / Auto-Cold / Hybrid-16) |
99.93% Std / 99.85% Compact (100.0% Top-5) |
100.00% |
5. HLE w/ Tools |
Humanity's Last Exam w/ Symbolic Tools (n = 40, 1,280 tok) |
55.3% |
55.3% |
55.3% (Cum-Cold / Auto-Cold / Hybrid-16) |
55.3% (Cum-Cold / Auto-Cold / Hybrid-16) |
99.92% Std / 99.69% Compact (100.0% Top-5) |
100.00% |
6. GDPval-AA v2 |
Enterprise Economic & Financial Modeling (n = 40, 1,280 tok) |
1773 Elo |
1773 Elo |
1773 Elo (Cum-Cold / Auto-Cold / Hybrid-16) |
1773 Elo (Cum-Cold / Auto-Cold / Hybrid-16) |
100.00% Std / 100.00% Compact (100.0% Top-5) |
100.00% |
7. NL2Repo |
1M-Context Zero-Shot Repo Synthesis & Anti-Hacking (n = 30, 960 tok) |
83.3% |
83.3% |
83.3% (Cum-Cold / Auto-Cold / Hybrid-16) |
83.3% (Cum-Cold / Auto-Cold / Hybrid-16) |
99.90% Std / 99.58% Compact (100.0% Top-5) |
100.00% |
8. Toolathlon Verified |
Multi-Turn Chained Tool-Call Verification (n = 36, 1,152 tok) |
77.8% |
77.8% |
77.8% (Cum-Cold / Auto-Cold / Hybrid-16) |
77.8% (Cum-Cold / Auto-Cold / Hybrid-16) |
100.00% Std / 100.00% Compact (100.0% Top-5) |
100.00% |
4.3 154,880-Vocab Academic, Mathematical & Coding Parity (MMLU, MMLU-Pro, GSM8K, Python Coding)
cais/mmlu (n = 300, 4-Choice A..D): 100.00% parity (300/300 exact match vs. Stock FP8)TIGER-Lab/MMLU-Pro (n = 150, 10-Choice A..J): 100.00% parity (150/150 exact match vs. Stock FP8)GSM8K (n = 150 Math Problems): 100.00% parity (150/150 exact match vs. Stock FP8)custom_code_bench.py (33 Python Problems, 1,056 Tokens): 100.00% parity (1,056/1,056 exact token match, 99.83% logit cosine, KL = 0.0014 nats)
ChronosGlm5SparseMoeBlock Runtime Profile |
Hardware |
Per-Layer Active GPU VRAM |
43-MoE-Layer Active GPU VRAM |
Active GPU VRAM Reduction vs Stock FP8 (291.26 GB) |
Warm 1-Token Decode Latency |
Prefill-vs-Decode Invariance Cosine |
Stock Glm5NextSparseMoeBlock (FP8) |
A100 / GB10 |
6,936.00 MB |
291.26 GB (OOMs 128 GB Spark) |
1.00× (Baseline) |
3.310 ms/layer |
100.00000% |
ChronosGlm5SparseMoeBlock (hot_cache=16, v7.5 Fused) |
DGX Spark GB10 |
1,588.38 MB |
66.70 GB |
4.37× (-224.56 GB Saved) |
2.226 ms/layer (1.49× faster) |
99.99896% |
ChronosGlm5SparseMoeBlock (hot_cache=16) |
Colab A100-80GB |
1,564.51 MB |
65.70 GB |
4.43× (-225.56 GB Saved) |
1.566 ms/layer |
99.99893% |
5. Six Production Serving & Unified-Memory Engineering Optimizations
| Production Serving Bottleneck on GB10 |
Root Cause in Stock vLLM |
Chronos × pb27_vllm Engineering Fix |
Measured Production Impact |
| 1. Unified-Memory Page-Cache Exhaustion & Slow MTP Load |
Loading 63 .safetensors shards leaves 59.24 GiB in Linux page cache and re-reads all 63 shards (76.3s) for Glm5NextMTP. |
POSIX_FADV_DONTNEED Shard Streaming + allow_patterns_overrides = ["*00062*.safetensors"]: Evicts each shard immediately after read and restricts Glm5NextMTP to shard-00062.safetensors. |
0.0 GiB page-cache spike; MTP load 76.3s → 1.2s (63.6× faster) |
| 2. Ephemeral Container Kernel Re-Compilation |
Triton, FlashInfer SM120/SM121 autotune, and TorchInductor caches lived inside /root/.triton, /root/.cache/vllm, and /tmp/torchinductor_root. |
Persistent Cache Redirection (/pb27_vllm/.cache/{triton,vllm,inductor}): Automatically binds TRITON_CACHE_DIR, VLLM_CACHE_ROOT, and TORCHINDUCTOR_CACHE_DIR in pb27_vllm/__init__.py. |
169 MB compiled kernels persisted across container restarts |
3. CUDA-Graph Lock-In & Contaminated MTP feedback_hidden |
Applying subword deltas inside Glm5NextModel.forward baked static tensor shapes into CUDA graphs and polluted spec_hidden_states & eh_proj inputs. |
Decoupled Eager compute_logits & Clean (logits_hidden_states, hidden_states) Tuple: Target healing runs in eager Glm5NextForCausalLM.compute_logits; MTP layer returns unhealed feedback_hidden. |
Zero target/MTP state contamination; unlimited dynamic vocabulary updates |
| 4. Multi-Token Verification Expert Bandwidth Amplification |
Speculative verification (3 tokens/step) routes up to 24 disjoint experts/layer, multiplying LPDDR5X weight reads. |
Uncovered-Expert Anchor Priority & Top-8 Candidate Gating (_chronos_fused_topk_sigmoid_kernel): Coalesces m=1,2 onto m=0's experts strictly within each token's natural top-8 candidates while preserving uncovered anchors. |
Up to 2.25× fewer unique expert reads/layer while preserving accuracy |
| 5. BPE Subword Stutters & Prefix Over-Steering |
Naive positive logit boosts over-steered shared prefixes (import → importance) and failed to suppress recursive stutters (_construct_construct). |
Context-Safe Anti-Stutter Subword Continuity (W_head @ u_i = e_i): Combines negative suppression of invalid BPE stutters with balanced continuation weights in the lm_head pseudoinverse subspace. |
High draft acceptance (42.4–54.7 tok/s) with 100% benchmark retention |
| 6. Fragile Source-String Monkey-Patching & Slow GDB Attach |
String-replacing internal vLLM source files breaks across versions; apt-get install gdb took ~10s per live attach. |
Version-Resilient Runtime Hooks (pb27_vllm/__init__.py) & Pre-Baked pb27-gdb:latest Sidecar (attach_engine.py): Dynamic *args, **kwargs wrappers + <0.5s sidecar PID attach. |
Version-tolerant plugin startup & <0.5s live engine inspection |
6. Complete PseudoBrain & Chronos 1M-Context Model Lineup (11 Families = 41 Models)
All repositories are served by the unified Chronos and PseudoBrain vLLM plugins:
| Model Family |
Params (Total / Active) |
1M Compression / KV Reduction |
Flagship Checkpoints on Hugging Face (@defnoteatin) |
| PseudoBrain-GLM-5.3-Flash-Chronos-v7.5 (This Repo) |
~106B / ~4.5B |
3.30×–4.43× Weight Compression + 1.9M SparseMLA KV |
Chronos-v7.5 (92.6 GB Full 46L / 59.8 GiB NVFP4 + Glm5NextMTP) |
| PseudoBrain-Qwen3.8-Flash-Next |
36B / ~1.7B |
96.0%+ (~48.0 GB → ~486 MiB active window) |
W4A16 · FP8 · NVFP4 · BF16 |
| PseudoBrain-Qwen3-Coder-Next |
80B / 3.0B |
93.5% (~48.0 GB → ~3.1 GB) |
W4A16 · FP8 · NVFP4 · BF16 |
| PseudoBrain-Qwen3-Coder-30B-A3B |
30.5B / 3.3B |
98.4% (192.0 GB → ~3.1 GB) |
W4A16 · FP8 · NVFP4 · BF16 |
| PseudoBrain-Nex-35B-A3B |
35B / ~3.0B |
97.6% (~20.0 GB → ~486 MiB active window) |
W4A16 · FP8 · NVFP4 · BF16 |
| PseudoBrain-27B |
27B / 27B |
99.2% (64.0 GB → ~486 MiB active window) |
W4A16 · FP8 · NVFP4 · BF16 |
| PseudoBrain-Qwen3-32B |
32.8B / 32.8B |
98.4% (256.0 GB → ~4.1 GB) |
W4A16 · FP8 · NVFP4 · BF16 |
| PseudoBrain-Gemma-4-31B |
31B / 31B |
92.2% (~45.0 GB → ~3.5 GB) |
W4A16 · FP8 · NVFP4 · BF16 |
| PseudoBrain-Gemma-4-26B-A4B |
25.2B / 3.8B |
90.2% (~22.5 GB → ~2.2 GB) |
W4A16 · FP8 · NVFP4 · BF16 |
| PseudoBrain-Qwen3.5-9B |
9B / 9B |
99.2% (32.0 GB → ~256 MiB active window) |
W4A16 · FP8 · NVFP4 · BF16 |
| PseudoBrain-Qwen3.5-4B |
4B / 4B |
99.2% (24.0 GB → ~192 MiB active window) |
W4A16 · FP8 · NVFP4 · BF16 |
7. License, Citation & Contact
@article{galeon2026chronos,
  title   = {Chronos: Holographic Spectral Superposition, Coupled Sherman-Morrison-Woodbury SVD Healers, and Vector-Space Associative MoE Inference at Million-Token Context},
  author  = {Galeon, Ian Kurt},
  year    = {2026},
  url     = {https://github.com/defnotean/Chronos}
}
8. Option A: 43-Layer BF16 Rank-32 Nullspace Shared-Expert Subspace Absorption (shared_experts_option_a_bf16_r32.pt)
- All 8,428 Pruned Experts Absorbed (
196 ? 43 layers, layers 3..45): Projects the post-SwiGLU hidden states of all 196 dropped experts per layer into the exact orthogonal complement ($\mathcal{S}{\mathcal{K}}^\perp = I - Q{\mathcal{P}} Q_{\mathcal{P}}^T$) of the 92 kept experts and 512 multi-expert mixtures.
- Zero NVFP4 Quantization Drift (
16.5 MB continuous BF16 Rank-32 SVD adapters): Keeps the base 4-bit NVFP4 MarlinNvFp4LinearKernel shared_experts.down_proj weights 100% bit-for-bit untouched while capturing out = out + (x @ _opt_a_VT) @ _opt_a_UT directly inside the target and MTP CUDA graphs (Min cos_K = 1.000000, Mean cos_K = 1.000000 | Min cos_mix = 0.999996, Mean cos_mix = 1.000000).
- Exact 288-Expert Router Scale Calibration (
routed_scale_mult = 0.95): Restores the exact 288-expert Top-8 normalization ratio (d92 / d288 = 0.9479) across layers 3..45.

