

OCR, documents and scene text
Collection
Receipts, bills, labels, menus, signs, packaging, forms, native PDFs, handwriting and non-Latin scripts, photographed or contributed by their owners. • 29 items • Updated
Prefer email? Write to team@kled.ai with the dataset name in the subject line.
Kled delivers sample sets and licensed data by email, not through Hugging Face. Tell us a little about your work and the Kled data team will send a sample set and pricing. Your request goes to team@kled.ai.
Log in or Sign Up to review the conditions and access this dataset content.
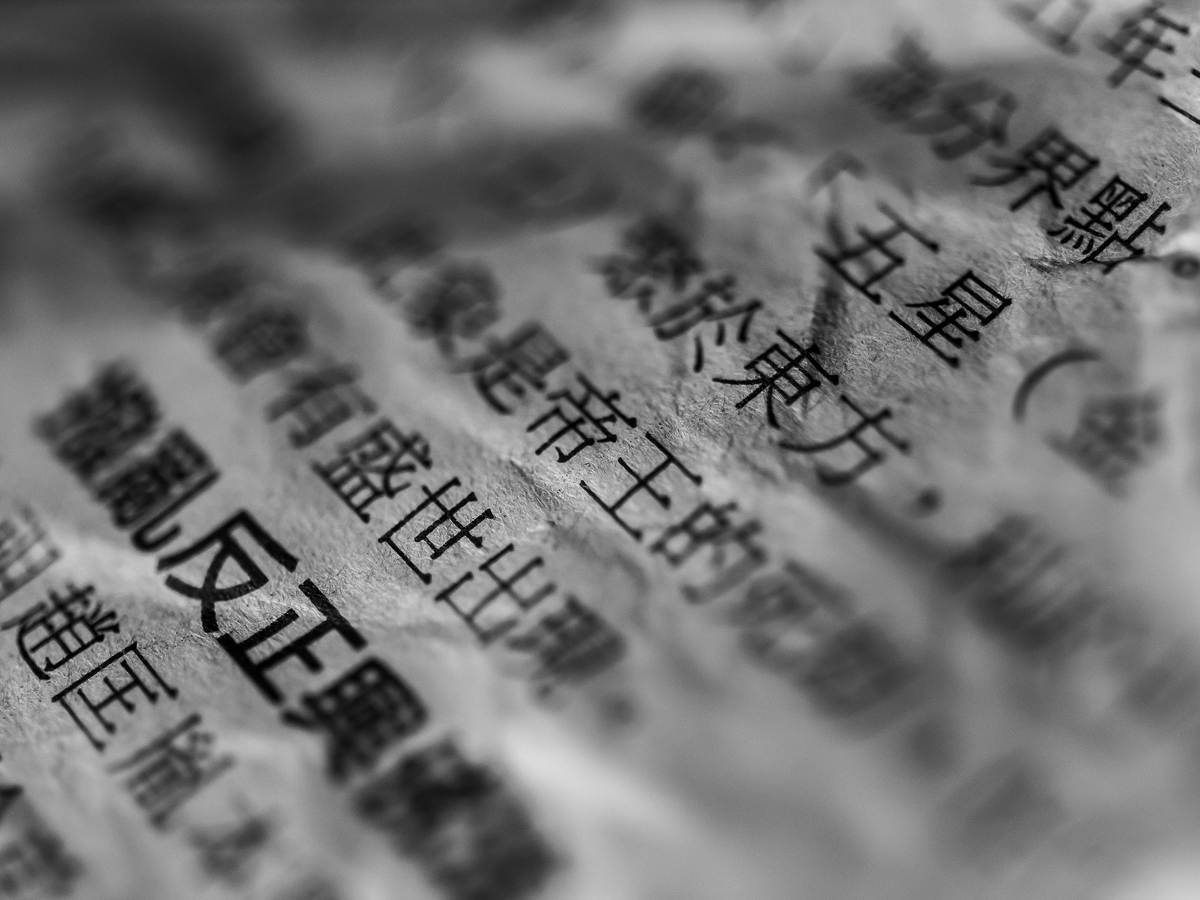
Sharp photos of real-world writing in Devanagari, Arabic, Thai, Cyrillic, Han and other non-Latin scripts, tagged.
Collected through the Kled app by consenting contributors and licensed for commercial training. The files are delivered by Kled under license, not downloaded from this repository. Use Request a sample set at the top of this page, or write to team@kled.ai. Catalog entry: kled.ai/datasets/non-latin-script-text.
Contributors in the 54 eligible countries, where everyday writing uses a non-Latin script, choose the script they are photographing, then shoot any text in it, on signs, packaging, documents or screens, close enough that the characters are sharp; Latin-only and unreadable shots are refused. The script tag is applied at capture by someone who reads the script; Devanagari, Arabic script, Thai, Cyrillic, Han, Bengali and Burmese are all in scope. No transcriptions are included. The non-Latin world is where scene-text models are weakest and training data thinnest: MTVQA covers nine languages, and HierText and TextOCR are Flickr-era and mostly English. Per-script counts are available on request.
Redistribution or resale of the files, use outside the terms of the commercial training license, and any attempt to identify or contact contributors or people who appear in the data. Uses that require labels this set does not carry should be scoped with the data team first.
One photo per record, delivered as JPG / PNG / HEIC. Volume: 25,000+ photos.
Field names and the manifest format are confirmed with the sample set.
Delivered as one set. Subsets by country, language or label, and custom splits, are available on request.
The dataset exists because the public alternatives named in the description are non-commercial, synthetic, small or collected elsewhere. Kled runs the task as a paid brief in its app so that the data is captured on purpose, under the capture rules above, by people who have opted in to commercial use.
Contributors complete the task in the Kled app. Capture tool: Phone camera (in app). Each submission is reviewed against the task brief; submissions that break the capture rules are rejected. QA review on every submission. Files are delivered as JPG / PNG / HEIC, in the resolution noted above.
Kled contributors, who complete paid data tasks on their own phones. This task was open to contributors in the 54 eligible countries where everyday writing uses a non-Latin script. Kled has 625,000+ contributors in 100+ countries, strongest in Southeast Asia, the United States and Europe.
Labeled (script tag). The label is entered by the contributor as part of the task and checked at review against the task brief; it is a contributor label, not an expert annotation, unless the description above says otherwise.
The contributors themselves, at the moment of capture. Kled reviewers check each submission against the task brief.
Every item was contributed by its owner, who opted in to this use at upload. The task brief states what may and may not appear in a submission, and reviewers reject submissions that break those rules. Kled's data handling practices are documented at trust.kled.ai; questions about handling requirements for your use go to team@kled.ai.
Coverage follows the contributor base: strongest in Southeast Asia, the United States and Europe, thinner elsewhere, and limited to the 54 eligible countries where everyday writing uses a non-Latin script for this task. Devices, settings and conditions vary by contributor, which is the point of the collection and also means no two items are captured under identical conditions. Where labels are contributor-entered, they are checked at review but are not expert annotations. Volumes are the current scope of the task and grow as collection continues.
Request a sample set and run it against your task before licensing. Ask for per-country or per-language counts where they matter to your use.
Non-exclusive commercial training license; exclusivity on request. Each contributor opted in to this use when they uploaded. The license terms are on the catalog page.
@misc{kled_non_latin_script_text_2026,
  title        = {Non-Latin Scene Text},
  author       = {Kled},
  year         = {2026},
  url          = {https://www.kled.ai/datasets/non-latin-script-text},
  note         = {Commercially licensed dataset collected through the Kled app. Sample sets on request.}
}
Kled data team: team@kled.ai