

The full dataset viewer is not available (click to read why). Only showing a preview of the rows.
Error code:   DatasetGenerationCastError
Exception:    DatasetGenerationCastError
Message:      An error occurred while generating the dataset

All the data files must have the same columns, but at some point there are 9 new columns ({'symbol_kind', 'in_old', 'from_version', 'to_version', 'confidence', 'detail', 'stratum', 'param', 'popularity_rank'}) and 1 missing columns ({'evidence'}).

This happened while the csv dataset builder was generating data using

hf://datasets/pushkar87dg/pypi-api-drift/validation/audit4/results_with_strata.csv (at revision f6c1bb16f709f776cd813dab504f3cfe4e92bc5a), ['hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/results_part1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/results_part2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/results_part3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/results_part4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/results_with_strata.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/sample_part1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/sample_part2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/sample_part3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/sample_part4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/benchmark_check/results.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/benchmark_check/sample.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/benchmark_check2/results.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/benchmark_check2/sample.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/judge_map.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/judge_out1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/judge_out2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/judge_out3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/judge_out4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/judge_out5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/judge_out6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/scored_tasks.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/scored_tasks_strict.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/tasks.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/downstream/cases.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/downstream/failures.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/downstream/masked.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/downstream2/cases.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/downstream2/failures.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/downstream2/masked.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/human_labeling/ai_key_DO_NOT_OPEN_BEFORE_LABELLING.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/human_labeling/items.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/human_labeling/labels_A.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/human_labeling/labels_B.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_a_batch1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_a_batch2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_a_batch3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_a_batch4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_a_batch5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_a_batch6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_b_batch1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_b_batch2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_b_batch3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_b_batch4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_b_batch5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_b_batch6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/qid_map.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/scored_items.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/judge_map.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/judge_out1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/judge_out2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/judge_out3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/judge_out4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/judge_out5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/judge_out6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/scored_tasks.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/scored_tasks_strict.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/versionprobe/answers_a_batch1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/versionprobe/answers_a_batch2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/versionprobe/answers_a_batch3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/versionprobe/answers_a_batch4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/versionprobe/answers_a_batch5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/versionprobe/answers_a_batch6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/judge_map.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/judge_out1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/judge_out2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/judge_out3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/judge_out4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/judge_out5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/judge_out6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/scored_tasks.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/scored_tasks_strict.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/versionprobe/answers_a_batch1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/versionprobe/answers_a_batch2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/versionprobe/answers_a_batch3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/versionprobe/answers_a_batch4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/versionprobe/answers_a_batch5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/versionprobe/answers_a_batch6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/judge_map.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/judge_out1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/judge_out2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/judge_out3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/judge_out4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/judge_out5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/judge_out6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/scored_tasks.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/scored_tasks_strict.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/versionprobe/answers_a_batch1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/versionprobe/answers_a_batch2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/versionprobe/answers_a_batch3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/versionprobe/answers_a_batch4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/versionprobe/answers_a_batch5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/versionprobe/answers_a_batch6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/recall/ground_truth.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/recall/pairs.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/recall/pairs_status.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/recall/recall_matched.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/results.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/results2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/results3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/sample.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/sample2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/sample3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/tool_comparison/aexpy_changes.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/tool_comparison/apidrift_extraction_times.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/tool_comparison/griffe_changes.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/tool_comparison/pairs.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/tool_comparison/runs.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/transfer_measurement_releases.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/v12_dropped_pairs.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/versioning_policy.csv']

Please either edit the data files to have matching columns, or separate them into different configurations (see docs at https://hf.co/docs/hub/datasets-manual-configuration#multiple-configurations)
Traceback:    Traceback (most recent call last):
                File "/usr/local/lib/python3.14/site-packages/datasets/builder.py", line 1856, in _prepare_split_single
                  writer.write_table(table)
                  ~~~~~~~~~~~~~~~~~~^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/arrow_writer.py", line 811, in write_table
                  self._write_table(pa_table, writer_batch_size=writer_batch_size)
                  ~~~~~~~~~~~~~~~~~^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/arrow_writer.py", line 822, in _write_table
                  pa_table = table_cast(pa_table, self._schema)
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 2381, in table_cast
                  return cast_table_to_schema(table, schema)
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 2309, in cast_table_to_schema
                  raise CastError(
                  ...<3 lines>...
                  )
              datasets.table.CastError: Couldn't cast
              id: int64
              project: string
              from_version: string
              to_version: string
              path: string
              symbol_kind: string
              change_type: string
              param: string
              detail: string
              confidence: string
              in_old: bool
              stratum: string
              popularity_rank: int64
              verdict: string
              method: string
              -- schema metadata --
              pandas: '{"index_columns": [{"kind": "range", "name": null, "start": 0, "' + 2008
              to
              {'id': Value('int64'), 'project': Value('string'), 'path': Value('string'), 'change_type': Value('string'), 'verdict': Value('string'), 'method': Value('string'), 'evidence': Value('string')}
              because column names don't match

              During handling of the above exception, another exception occurred:

              Traceback (most recent call last):
                File "/src/services/worker/src/worker/job_runners/config/parquet_and_info.py", line 1379, in compute_config_parquet_and_info_response
                  parquet_operations, partial, estimated_dataset_info = stream_convert_to_parquet(
                                                                        ~~~~~~~~~~~~~~~~~~~~~~~~~^
                      builder, max_dataset_size_bytes=max_dataset_size_bytes
                      ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
                  )
                  ^
                File "/src/services/worker/src/worker/job_runners/config/parquet_and_info.py", line 956, in stream_convert_to_parquet
                  builder._prepare_split(split_generator=splits_generators[split], file_format="parquet")
                  ~~~~~~~~~~~~~~~~~~~~~~^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/builder.py", line 1702, in _prepare_split
                  for job_id, done, content in self._prepare_split_single(
                                               ~~~~~~~~~~~~~~~~~~~~~~~~~~^
                      gen_kwargs=gen_kwargs, job_id=job_id, **_prepare_split_args
                      ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
                  ):
                  ^
                File "/usr/local/lib/python3.14/site-packages/datasets/builder.py", line 1858, in _prepare_split_single
                  raise DatasetGenerationCastError.from_cast_error(
                  ...<4 lines>...
                  )
              datasets.exceptions.DatasetGenerationCastError: An error occurred while generating the dataset

              All the data files must have the same columns, but at some point there are 9 new columns ({'symbol_kind', 'in_old', 'from_version', 'to_version', 'confidence', 'detail', 'stratum', 'param', 'popularity_rank'}) and 1 missing columns ({'evidence'}).

              This happened while the csv dataset builder was generating data using

              hf://datasets/pushkar87dg/pypi-api-drift/validation/audit4/results_with_strata.csv (at revision f6c1bb16f709f776cd813dab504f3cfe4e92bc5a), ['hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/results_part1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/results_part2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/results_part3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/results_part4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/results_with_strata.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/sample_part1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/sample_part2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/sample_part3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/audit4/sample_part4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/benchmark_check/results.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/benchmark_check/sample.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/benchmark_check2/results.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/benchmark_check2/sample.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/judge_map.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/judge_out1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/judge_out2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/judge_out3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/judge_out4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/judge_out5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/judge_out6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/scored_tasks.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/scored_tasks_strict.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/code_repair/tasks.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/downstream/cases.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/downstream/failures.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/downstream/masked.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/downstream2/cases.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/downstream2/failures.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/downstream2/masked.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/human_labeling/ai_key_DO_NOT_OPEN_BEFORE_LABELLING.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/human_labeling/items.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/human_labeling/labels_A.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/human_labeling/labels_B.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_a_batch1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_a_batch2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_a_batch3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_a_batch4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_a_batch5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_a_batch6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_b_batch1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_b_batch2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_b_batch3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_b_batch4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_b_batch5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/answers_b_batch6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/qid_map.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/model_baseline/scored_items.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/judge_map.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/judge_out1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/judge_out2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/judge_out3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/judge_out4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/judge_out5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/judge_out6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/scored_tasks.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/repair/scored_tasks_strict.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/versionprobe/answers_a_batch1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/versionprobe/answers_a_batch2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/versionprobe/answers_a_batch3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/versionprobe/answers_a_batch4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/versionprobe/answers_a_batch5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/fable/versionprobe/answers_a_batch6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/judge_map.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/judge_out1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/judge_out2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/judge_out3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/judge_out4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/judge_out5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/judge_out6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/scored_tasks.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/repair/scored_tasks_strict.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/versionprobe/answers_a_batch1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/versionprobe/answers_a_batch2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/versionprobe/answers_a_batch3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/versionprobe/answers_a_batch4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/versionprobe/answers_a_batch5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/haiku/versionprobe/answers_a_batch6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/judge_map.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/judge_out1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/judge_out2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/judge_out3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/judge_out4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/judge_out5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/judge_out6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/scored_tasks.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/repair/scored_tasks_strict.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/versionprobe/answers_a_batch1.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/versionprobe/answers_a_batch2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/versionprobe/answers_a_batch3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/versionprobe/answers_a_batch4.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/versionprobe/answers_a_batch5.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/multi_model/sonnet/versionprobe/answers_a_batch6.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/recall/ground_truth.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/recall/pairs.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/recall/pairs_status.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/recall/recall_matched.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/results.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/results2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/results3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/sample.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/sample2.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/sample3.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/tool_comparison/aexpy_changes.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/tool_comparison/apidrift_extraction_times.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/tool_comparison/griffe_changes.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/tool_comparison/pairs.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/tool_comparison/runs.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/transfer_measurement_releases.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/v12_dropped_pairs.csv', 'hf://datasets/pushkar87dg/pypi-api-drift@f6c1bb16f709f776cd813dab504f3cfe4e92bc5a/validation/versioning_policy.csv']

              Please either edit the data files to have matching columns, or separate them into different configurations (see docs at https://hf.co/docs/hub/datasets-manual-configuration#multiple-configurations)
Need help to make the dataset viewer work? Make sure to review how to configure the dataset viewer, and open a discussion for direct support.
id int64 | project string | path string | change_type string | verdict string | method string | evidence string |
|---|---|---|---|---|---|---|
3 | azure-mgmt-servicebus | azure.mgmt.servicebus.models.SBQueueListResult | removed | confirmed | runtime | SBQueueListResult importable from models in 9.0.0 (v2021_11_01); AttributeError in 10.0.0. |
25 | azure-mgmt-servicebus | azure.mgmt.servicebus.v2018_01_01_preview | removed | confirmed | runtime | Submodule v2018_01_01_preview imports in 8.2.1; not present in 9.0.0 (import fails). |
10 | netaddr | netaddr.core.a | removed | confirmed | runtime | netaddr.core.a (leaked module-level int, =42) exists in 0.9.0; AttributeError in 0.10.0. |
17 | xmlschema | xmlschema.resources.NormalizedLocationsType | removed | false_positive | runtime | Still accessible in 1.8.1: resources.py imports NormalizedLocationsType from new xmlschema.aliases (runtime placeholder alias outside TYPE_CHECKING). |
19 | azure-mgmt-containerinstance | azure.mgmt.containerinstance.models.Components10Wh5UdSchemasContainergroupidentityPropertiesUserassignedidentitiesAdditionalproperties | removed | confirmed | runtime | Class present in models in 9.2.0 (needs six installed); AttributeError on models in 10.0.0. |
21 | mkdocstrings | mkdocstrings.references | removed | confirmed | runtime | mkdocstrings.references module imports in 0.14.0; absent in 0.15.0. |
36 | ezdxf | ezdxf.sections.table.UCSTable | param_removed | confirmed | runtime | UCSTable signature (doc=None, entities=None) in 0.17.1 becomes () in 0.17.2. |
41 | ezdxf | ezdxf.math.rational_spline_from_ellipse | removed | confirmed | runtime | ezdxf.math.rational_spline_from_ellipse exported in 0.15.2; AttributeError in 0.16. |
37 | dynaconf | dynaconf.loaders.DynaBox | removed | confirmed | runtime | DynaBox importable from dynaconf.loaders in 3.2.13 (re-export of utils.boxing); AttributeError in 3.3.0. |
38 | jax | jax.experimental.shard_map.RepType | removed | confirmed | runtime | jax.experimental.shard_map.RepType (alias of typing.Any) present in 0.6.0; AttributeError in 0.6.1. |
51 | librosa | librosa.set_fftlib | removed | confirmed | runtime | librosa.set_fftlib present in 0.11.0; lazy loader raises AttributeError in 1.0.0. |
53 | choreographer | choreographer.Browser.run_output_thread | removed | confirmed | runtime | Browser.run_output_thread exists in 0.99.7; not on choreographer.Browser in 1.0.3 (only sync broker/BrowserSync keep it). |
62 | google-cloud-dlp | google.cloud.dlp_v2.types.dlp.SensitivityScore | removed | confirmed | runtime | SensitivityScore defined in dlp_v2.types.dlp in 3.8.1; moved to dlp_v2.types.storage in 3.9.0, so the types.dlp path raises AttributeError. |
63 | autopep8 | autopep8.fix_2to3 | removed | confirmed | runtime | autopep8.fix_2to3 present in 2.0.4; AttributeError in 2.1.0. |
66 | azure-mgmt-datafactory | azure.mgmt.datafactory.models.SqlPartitionOption | removed | confirmed | runtime | SqlPartitionOption enum exported from models in 9.3.0; AttributeError in 10.0.0. |
71 | mypy-boto3-cloudformation | mypy_boto3_cloudformation.type_defs.DescribeStacksInputStackCreateCompleteWaitTypeDef | removed | confirmed | runtime | TypedDict present in 1.35.64 type_defs; absent in 1.35.93 (consolidated into DescribeStacksInputWaitTypeDef). |
72 | metricflow | metricflow.errors.errors.ParsingException | removed | confirmed | source | class ParsingException defined in metricflow/errors/errors.py of 0.140.0 wheel; no occurrence in 0.200.0 errors.py (runtime install blocked by psycopg2 build). |
76 | peft | peft.tuners.oft.eetq.EetqOFTLinear | required_param_added | confirmed | source | EetqOFTLinear.__init__ gains required positional 'config: OFTConfig' in 0.20.0 (absent in 0.19.1); class only defined when eetq is installed; torch install exceeded disk. |
78 | jax | jax.numpy.typing | removed | false_positive | source | jax/numpy/__init__.py is identical in both versions and does 'del typing' (no typing submodule), so not accessible in either; only the 0.4.16 .pyi stub declared 'typing: Any' (jaxlib 0.4.16/17 wheels gone, no runtime). |
80 | types-aiobotocore-s3 | types_aiobotocore_s3.type_defs.NotificationConfigurationFilterOutputTypeDef | removed | confirmed | source | TypedDict defined and in __all__ in 2.5.2.post1 type_defs.py; renamed to NotificationConfigurationFilterBucketNotificationTypeDef in post2 (package import needs aiobotocore). |
84 | librosa | librosa.feature.chroma_cens | became_keyword_only | confirmed | runtime | 0.8.1 runtime signature has bins_per_octave POSITIONAL_OR_KEYWORD; 0.9.0 source declares chroma_cens(*, ..., bins_per_octave=36) with no positional shim (0.9.0 install hit disk limit, checked via wheel). |
90 | tensorflow | tensorflow.python.data.experimental.ops.snapshot.snapshot | param_removed | confirmed | source | snapshot() in 2.2.3 has pending_snapshot_expiry_seconds; 2.3.2 signature is snapshot(path, compression='AUTO', reader_func=None, shard_func=None) (checked tensorflow-cpu wheels, same Python code). |
157 | tensorflow | tensorflow.python.serialize_tensor_eager_fallback | removed | confirmed | source | 2.2.3 tensorflow/python/__init__.py wildcard-imports standard_ops -> parsing_ops -> gen_parsing_ops (no __all__), exposing serialize_tensor_eager_fallback; 2.3.2 __init__ has no wildcard imports. |
91 | azure-mgmt-trafficmanager | azure.mgmt.trafficmanager.models.ProfileListResult | removed | confirmed | runtime | ProfileListResult exported from models in 1.1.0; AttributeError in 2.0.0. |
92 | pyrate-limiter | pyrate_limiter.SQLITE_MAX_VARIABLE_NUMBER | removed | confirmed | runtime | pyrate_limiter.SQLITE_MAX_VARIABLE_NUMBER is an int in 2.10.0; AttributeError in 3.0.0 (with redis installed). |
94 | pyelftools | elftools.dwarf.callframe.DW_LANG_Python | removed | confirmed | runtime | DW_LANG_Python accessible via elftools.dwarf.callframe in 0.32 (star import of constants); AttributeError there in 0.33. |
95 | azure-batch | azure.batch.models.ImageReference | removed | confirmed | runtime | models.ImageReference present in 14.2.0; AttributeError in 15.1.0 (rewritten SDK, now BatchVmImageReference). |
97 | azure-synapse-artifacts | azure.synapse.artifacts.models.CloudErrorAutoGenerated | removed | confirmed | runtime | models.CloudErrorAutoGenerated present in 0.12.0 (needs six); 0.13.0 models only has CloudError. |
108 | azure-mgmt-managementgroups | azure.mgmt.managementgroups.operations.ManagementGroupsAPIOperationsMixin | removed | confirmed | runtime | operations.ManagementGroupsAPIOperationsMixin public in 1.0.0; 1.1.0 exposes only _ManagementGroupsAPIOperationsMixin. |
111 | xmlschema | xmlschema.converters.default | removed | confirmed | runtime | Submodule xmlschema.converters.default imports in 3.4.5; not present in 4.0.0. |
117 | diffusers | diffusers.schedulers.DPMSolverMultistepScheduler.dpm_solver_first_order_update | became_keyword_only | confirmed | source | noise was 5th positional in 0.21.4; 0.22.0 signature is (model_output, *args, sample=None, noise=None, **kwargs) so positional noise is swallowed by *args and ignored (AssertionError for sde variants) rather than TypeError. |
123 | azure-mgmt-billing | azure.mgmt.billing.models.ProductListResult | removed | confirmed | runtime | models.ProductListResult present in 7.0.0; AttributeError in 8.0.0. |
132 | azure-mgmt-billing | azure.mgmt.billing.models.Reservation.benefit_start_time | removed | confirmed | runtime | Reservation has benefit_start_time attribute in 7.0.0; 8.0.0 Reservation (TypeSpec model) has no such attribute on class or instance (moved under .properties). |
124 | prefect | prefect.server.services.scheduler.RecentDeploymentsScheduler | removed | confirmed | source | class RecentDeploymentsScheduler defined in prefect/server/services/scheduler.py 3.6.6; 3.6.7 replaced classes with functions (schedule_recent_deployments), no __getattr__ shim. |
129 | requests-cache | requests_cache.cache_control.try_int | removed | confirmed | runtime | cache_control.try_int present in 0.9.6; AttributeError in 0.9.7. |
133 | qdrant-client | qdrant_client.models.InitFrom | removed | confirmed | runtime | qdrant_client.models.InitFrom present in 1.15.1; AttributeError in 1.16.0. |
143 | azure-mgmt-recoveryservices | azure.mgmt.recoveryservices.models.VaultList | removed | confirmed | runtime | models.VaultList present in 3.1.0; AttributeError in 4.0.0. |
145 | google-ai-generativelanguage | google.ai.generativelanguage_v1beta.types.file.VideoMetadata | removed | confirmed | runtime | VideoMetadata defined in v1beta types.file in 0.6.18; in 0.7.0 it lives in types.content and types.file has no such attribute. |
148 | optree | optree.tree_reduce | became_positional_only | confirmed | runtime | func is POSITIONAL_OR_KEYWORD in 0.13.1 and POSITIONAL_ONLY in 0.14.0; tree_reduce(func=...) raises TypeError in 0.14.0. |
149 | diffusers | diffusers.utils.dynamic_modules_utils.COMMUNITY_PIPELINES_URL | removed | confirmed | runtime | COMMUNITY_PIPELINES_URL str constant present in 0.28.2; AttributeError in 0.29.0. |
153 | ag-ui-protocol | ag_ui.core.ThinkingStartEvent | removed | confirmed | runtime | ag_ui.core.ThinkingStartEvent present in 0.1.22; 1.0.0 ag_ui.core has no Thinking* names. |
154 | py7zr | py7zr.helpers.BufferOverflow | removed | confirmed | runtime | BufferOverflow defined in py7zr.helpers in 0.22.0; AttributeError in 1.0.0. |
4 | compressed-tensors | compressed_tensors.disable_offload | removed | confirmed | source | disable_offload defined/exported in utils/offload.py (star-imported into package) in 0.15.0.1; absent from all modules in 0.16.0. |
6 | timm | timm.models.CspNet | param_removed | confirmed | source | CspNet.__init__ has aa_layer=None in 0.5.4; 0.6.5 signature is (cfg, in_chans, num_classes, output_stride, global_pool, drop_rate, drop_path_rate, zero_init_last) with no aa_layer or **kwargs. |
11 | azure-mgmt-cdn | azure.mgmt.cdn.models.CookiesMatchConditionParametersTypeName | removed | confirmed | runtime | Enum importable from azure.mgmt.cdn.models in 13.1.1; AttributeError in 14.0.0. |
14 | discord-py | discord.ext.commands.Context | required_param_added | confirmed | runtime | 1.7.3 Context(**attrs) treated view as optional (attrs.pop('view', None)); 2.0.0 signature has required keyword-only view: StringView with no default. |
40 | discord-py | discord.Relationship | removed | confirmed | runtime | discord.Relationship is a class in 1.7.3; AttributeError on discord in 2.0.0. |
18 | rich-argparse | rich_argparse.MetavarTypeRichHelpFormatter | became_keyword_only | confirmed | runtime | console is 5th positional-or-keyword param in 1.7.0; keyword-only after * in 1.7.1 and positional call with 5 args raises TypeError. |
20 | pint | pint.testsuite.test_compat_downcast.test_array_quantity_creation_by_multiplication | required_param_added | confirmed | source | Installed source: 0.18 signature (op, unit, array); 0.20 signature (local_registry, q_base, op, unit, array) with local_registry a new required positional param (pytest fixture). |
24 | yt-dlp | yt_dlp.compat.passthrough_module | removed | false_positive | runtime | In 2023.9.24 the name is deleted from yt_dlp.compat namespace but still served lazily via the compat passthrough to ._deprecated (DeprecationWarning); attribute access succeeds. |
29 | apache-airflow | airflow.configuration.mkdir_p | removed | confirmed | source | def mkdir_p(path) exists at module level in 1.10.15 airflow/configuration.py; no definition or import of mkdir_p in 2.0.1. |
87 | apache-airflow | airflow.operators.generic_transfer.GenericTransfer | became_keyword_only | confirmed | source | 1.10.15 __init__(self, sql, destination_table, source_conn_id, destination_conn_id, ...) is positional; 2.0.1 puts all params after a bare * so destination_conn_id is keyword-only. |
30 | llama-index-workflows | workflows.utils.import_module_from_qualified_name | removed | confirmed | runtime | Function present in workflows.utils in 0.1.0; AttributeError on workflows.utils in 0.2.0 (moved to workflows.context.utils). |
34 | azure-mgmt-monitor | azure.mgmt.monitor.v2022_10_01 | removed | confirmed | runtime | Subpackage v2022_10_01 importable in 6.0.2; 7.0.0 dropped all versioned API subpackages and import fails. |
39 | azure-mgmt-containerregistry | azure.mgmt.containerregistry.models.PrivateEndpointConnectionListResult | removed | confirmed | runtime | Model class present in 14.0.0 models; AttributeError in 15.0.0. |
42 | jaxlib | jaxlib.triton.dialect.experimental_descriptor_scatter | removed | confirmed | runtime | Function present in 0.5.3; AttributeError in 0.6.0 (renamed to descriptor_scatter). |
45 | minio | minio.Minio.append_object | param_removed | confirmed | runtime | 7.2.19 append_object has keyword-only filename=None; 7.2.20 signature is (bucket_name, object_name, data, length, chunk_size, progress, extra_headers) with no filename or **kwargs. |
47 | types-boto3-s3 | types_boto3_s3.type_defs.GetBucketOwnershipControlsRequestRequestTypeDef | removed | confirmed | runtime | TypedDict present in 1.36.9 type_defs; absent in 1.36.15 (renamed GetBucketOwnershipControlsRequestTypeDef). |
49 | azure-mgmt-web | azure.mgmt.web.models.ScaleRule | removed | confirmed | runtime | ScaleRule model present in 10.1.0; AttributeError on azure.mgmt.web.models in 11.0.0. |
54 | pygit2 | pygit2.GIT_DIFF_FIND_ALL | removed | false_positive | runtime | pygit2.GIT_DIFF_FIND_ALL == 255 in both 1.13.3 and 1.14.0 (in 1.14.0 it comes from the _pygit2 C extension via star import). |
55 | aws-cdk-lib | aws_cdk.aws_cloudfront.VpcOriginReference | removed | confirmed | source | 2.223.0 defines class VpcOriginReference in aws_cloudfront/__init__.py; 2.224.0 only imports it from ..interfaces.aws_cloudfront under private alias _VpcOriginReference_e93e6a73 (no public binding, no module __getattr__). |
57 | faiss-cpu | faiss.knn_extra_metrics | required_param_added | false_positive | runtime | faiss.knn_extra_metrics is not exposed to Python at all in 1.8.0.post1 (no attr on faiss or any swigfaiss variant; only C++ symbols in the .so); it first appears in 1.9.0 as (x, y, d, nx, ny, mt, metric_arg, k, distances, indexes), so no existing call can break. |
70 | azure-mgmt-eventhub | azure.mgmt.eventhub.models.AuthorizationRuleListResult | removed | confirmed | runtime | Model present in 11.2.0 models; AttributeError in 12.0.0. |
73 | mypy-boto3-glue | mypy_boto3_glue.type_defs.EncryptionConfigurationExtraOutputTypeDef | removed | confirmed | runtime | TypedDict present in 1.35.3 type_defs; absent in 1.35.18. |
75 | azure-functions | azure.functions.decorators.openai.EmbeddingsInput | param_renamed | false_positive | runtime | 1.24.0 __init__ still has **kwargs so EmbeddingsInput(..., model='m') succeeds (model is even still emitted in get_dict_repr); the semantic successor is embeddings_model, not ai_connection_name, which merely took over the 4th positional slot. |
79 | bokeh | bokeh.server.tornado.BokehTornado | became_keyword_only | confirmed | runtime | stats_log_frequency_milliseconds is POSITIONAL_OR_KEYWORD in 3.1.0; 3.1.1 inserts a bare * after applications making it KEYWORD_ONLY. |
156 | bokeh | bokeh.models.Divider | removed | confirmed | runtime | bokeh.models.Divider model class present in 3.3.4; AttributeError on bokeh.models in 3.4.0. |
86 | pyairtable | pyairtable.orm.fields.LookupField | param_renamed | confirmed | runtime | 2nd param is model in 1.5.0 and validate_type in 2.0.0 (no **kwargs); LookupField('x', model=None) raises TypeError in 2.0.0 (semantically model was dropped rather than renamed, but the keyword break holds). |
88 | mkdocstrings-python | mkdocstrings_handlers.python.get_handler | became_keyword_only | confirmed | runtime | config_file_path is positional-or-keyword (3rd) in 1.6.2; 1.6.3 signature starts with bare * so it is keyword-only (verified with griffe<0.40 / mkdocstrings<0.24 so the module imports). |
89 | ortools | ortools.constraint_solver.pywrapcp.GlobalVehicleBreaksConstraint | removed | confirmed | runtime | Class present in pywrapcp 9.14.6206; AttributeError in 9.15.6755 (no *Break* names left in pywrapcp). |
93 | azure-mgmt-recoveryservicesbackup | azure.mgmt.recoveryservicesbackup.models.BMSBackupEnginesQueryObject | removed | confirmed | runtime | Model present in 10.0.0 models; AttributeError in 11.0.0. |
155 | azure-mgmt-recoveryservicesbackup | azure.mgmt.recoveryservicesbackup.operations.DeletedProtectionContainersOperations.list | became_keyword_only | confirmed | runtime | filter is POSITIONAL_OR_KEYWORD (3rd) in 10.0.0; KEYWORD_ONLY after bare * in 11.0.0. |
104 | yt-dlp | yt_dlp.extractor.googlepodcasts | removed | confirmed | runtime | Module yt_dlp.extractor.googlepodcasts importable in 2026.3.17; file and attribute absent in 2026.6.9. |
107 | ray | ray.util.state.state_manager.StateDataSourceClient.get_task_info | removed | confirmed | runtime | Method present on StateDataSourceClient in ray[default]==2.40.0; AttributeError on the class in 2.41.0 (only get_all_task_info remains). |
114 | ray | ray.thirdparty_files.psutil.long | removed | confirmed | runtime | Vendored psutil in ray 2.42.1 is 6.1.1 and exposes long (from ._compat); ray 2.43.0 vendors psutil 7.0.0 which has no _compat and no long attribute (checked by importing the extracted vendored package). |
110 | faiss-cpu | faiss.swigfaiss.RaBitQStats | removed | confirmed | runtime | RaBitQStats class present on faiss.swigfaiss in 1.13.2; AttributeError in 1.14.2 (and faiss.RaBitQStats is also absent there, so the detail note is wrong but the claim holds). |
113 | newrelic | newrelic.core.adaptive_sampler | removed | confirmed | runtime | Module newrelic.core.adaptive_sampler importable in 11.4.0; import fails in 11.5.0 (moved to newrelic.core.samplers). |
121 | jaxlib | jaxlib.mlir.dialects.arith.DenormalMode | removed | false_positive | runtime | DenormalMode is absent from jaxlib.mlir.dialects.arith in both 0.9.0.1 and 0.9.1 at runtime, and no .py file in the 0.9.0.1 wheel mentions it, so it was never accessible in from_version. |
128 | google-analytics-admin | google.analytics.admin_v1alpha.services.analytics_admin_service.transports.AnalyticsAdminServiceGrpcAsyncIOTransport.set_automated_ga4_configuration_opt_out | removed | confirmed | runtime | Property exists on the grpc asyncio transport class in 0.24.1; class (incl. MRO) has no such attribute in 0.25.0. |
130 | python-gitlab | gitlab.NOTIFICATION_LEVEL_WATCH | removed | confirmed | runtime | gitlab.NOTIFICATION_LEVEL_WATCH served by module __getattr__ (deprecated) in 3.15.0; AttributeError in 4.0.0. |
135 | azure-mgmt-servicefabric | azure.mgmt.servicefabric.models.Enum14 | removed | confirmed | runtime | Enum14 (Windows/Linux) present in 2.0.0 models (needs six installed to import); AttributeError in 2.1.0 where no Enum* names remain. |
140 | propcache | propcache.cached_property | removed | false_positive | runtime | propcache.cached_property resolves in both 0.1.0 and 0.2.0; in 0.2.0 it is served lazily by module __getattr__ (_import_facade) with no deprecation warning. |
150 | elementpath | elementpath.xpath31.xpath31_parser.infixr | removed | confirmed | runtime | Module-level alias infixr (bound classmethod of the parser) exists in 3.0.1; AttributeError on the module in 3.0.2. |
151 | harbor-rewardkit | rewardkit.agents.ClaudeCodeCLI | removed | confirmed | runtime | Class ClaudeCodeCLI present in rewardkit.agents in 0.1.7; AttributeError in 0.2.0. |
2 | robotframework | robot.running.arguments.CustomArgumentConverters.from_dict | param_renamed | confirmed | runtime | 6.0.2 signature (converters, error_reporter); 6.1 signature (converters, library), both positional-or-keyword. |
7 | pyhanko | pyhanko.cli.cli | removed | confirmed | runtime | 0.17.2 pyhanko/cli.py exposes click Group 'cli'; 0.18.0 pyhanko.cli is a package with cli_root and no 'cli' attribute or submodule. |
8 | rdkit | rdkit.Chem.PandasTools.patchPandasrepr | removed | confirmed | runtime | Function present in 2022.3.5 PandasTools; absent in 2022.9.1 (replaced by PandasPatcher module). |
9 | apache-airflow-providers-google | airflow.providers.google.cloud.triggers.kubernetes_engine.GKEJobTrigger | positional_reordered | confirmed | source | 16.1.0 order ...job_namespace, pod_name, pod_namespace, base_container_name...; 17.0.0 moves pod_name after base_container_name (detail omits the newly inserted required pod_names). |
12 | azure-mgmt-keyvault | generated_samples.managed_hsm_create_key | removed | confirmed | source | 12.1.0 wheel ships top-level generated_samples/managed_hsm_create_key.py (namespace pkg, importable with azure-identity); 12.1.1 wheel ships only 'azure' - accidental sample-code leak, not real API. |
32 | azure-mgmt-keyvault | azure.mgmt.keyvault.models.DeletedVaultListResult | removed | confirmed | runtime | Exported from models in 12.1.1 source; 13.0.0 (TypeSpec regen) models has no DeletedVaultListResult at runtime. |
16 | azure-mgmt-redis | azure.mgmt.redis.models.ErrorDetailAutoGenerated | removed | confirmed | runtime | Defined and exported in 14.2.0 models; absent from 14.3.0 at runtime (ErrorDetail remains). |
22 | lmnr | lmnr.opentelemetry_lib.opentelemetry.instrumentation.anthropic.WrappedAsyncMessageStreamManager | param_removed | confirmed | source | __init__ in 0.7.41 streaming.py takes token_histogram (plus metrics args); 0.7.42 takes only (stream_manager, span, instance, kwargs); class re-exported from the anthropic package in both. |
33 | etils | etils.array_types.typing_test | removed | confirmed | source | 0.6.0 ships etils/array_types/typing_test.py (imports jax+pytest; jax import failed in venv so verified by file); 0.7.0 runtime: No module named etils.array_types.typing_test. |
35 | azure-mgmt-network | azure.mgmt.network.models.NetworkRuleCondition | removed | confirmed | source | 27.0.0 models/__init__ exports NetworkRuleCondition; 28.0.0 wheel mentions it only in METADATA changelog, not in any module. |
46 | workos | workos.common.models.WaitlistUserStateLiteral | removed | false_positive | runtime | Name does not exist in 10.3.0 either (no occurrence anywhere in the installed package; only WaitlistUserState alias via lazy __getattr__), so nothing was removed. |
52 | azure-mgmt-authorization | azure.mgmt.authorization.v2021_12_01_preview.aio.operations.AlertDefinitionsOperations | removed | confirmed | source | 3.0.0 v2021_12_01_preview/aio/operations/__init__ exports AlertDefinitionsOperations; 4.0.0 has no _alert_definitions_operations.py and no export (alerts moved to v2022_08_01_preview). |
56 | pipenv | pipenv.PIPENV_ROOT | removed | confirmed | runtime | pipenv.PIPENV_ROOT is a str in 2023.6.11; AttributeError in 2023.6.12. |
61 | azure-monitor-query | azure.monitor.query.TimeSeriesElement | removed | confirmed | runtime | Exported class in 1.4.1; 2.0.0 dropped all metrics types (moved to azure-monitor-querymetrics), TimeSeriesElement absent. |
64 | flask-caching | flask_caching.BaseCache.get | removed | false_positive | runtime | In 1.11.0 BaseCache subclasses cachelib.BaseCache and inherits get(self, key) (same signature); 1.11.0 metadata omits cachelib so a bare install cannot import the module at all. |
69 | azure-mgmt-sql | azure.mgmt.sql.models.DataWarehouseUserActivitiesListResult | removed | confirmed | source | Exported from models/__init__ in 3.0.1; no occurrence in any 4.0.0 module, and 4.0.x changelog lists it under 'Deleted model'. |
YAML Metadata Warning:empty or missing yaml metadata in repo card
Check out the documentation for more information.
PyPI API Drift




How the public APIs of the 1,872 most-downloaded Python libraries changed, release by release: up to 80 recent final releases per library, drawn from 2021–October 2026.
Paper: https://doi.org/10.5281/zenodo.23648339 · Data: Hugging Face · Install: pip install pypi-api-drift
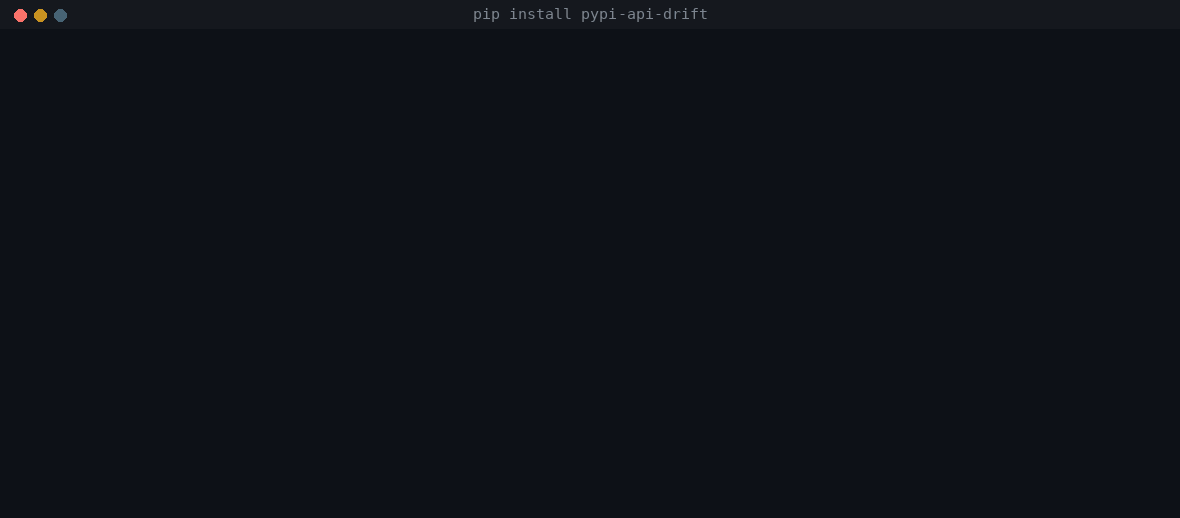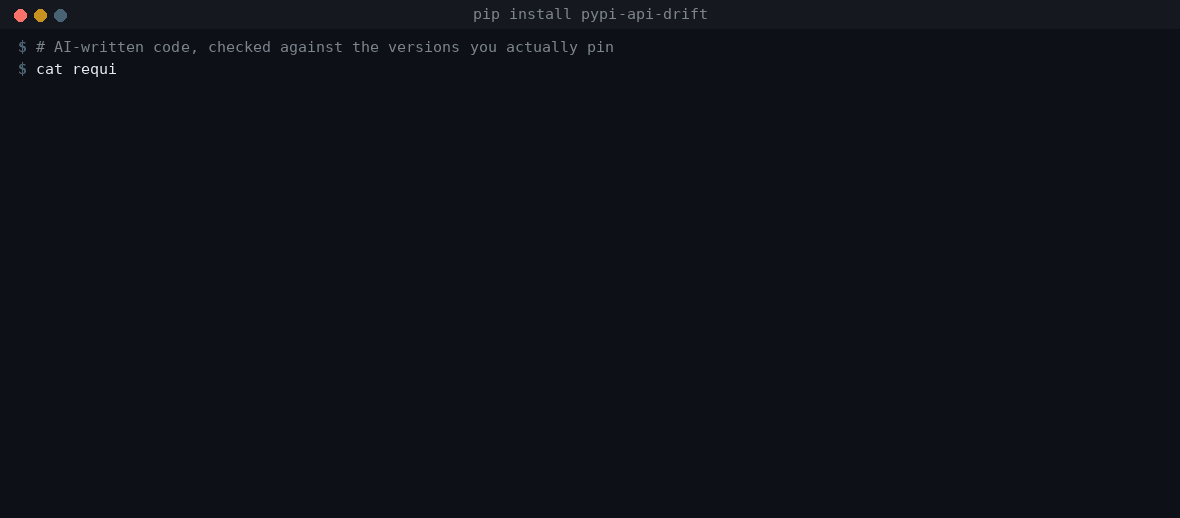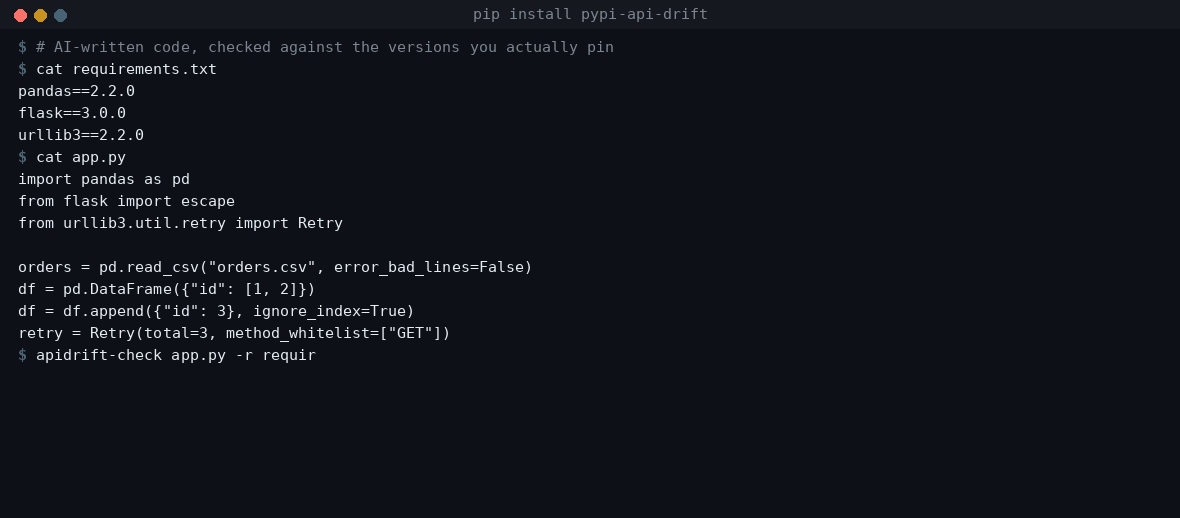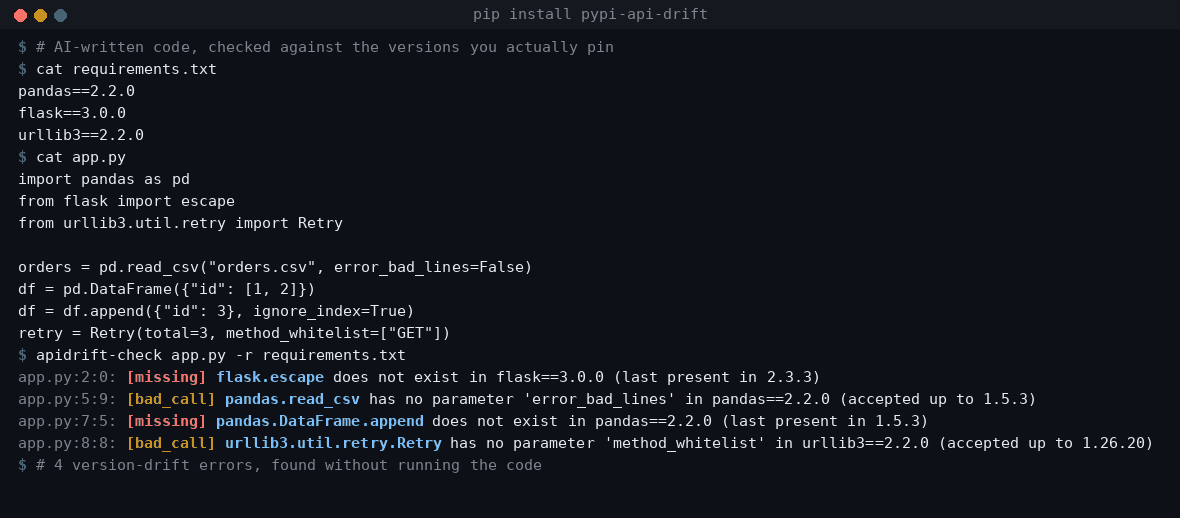
This is a v1 research release. Precision is measured and good; recall outside the dataset's static definition of public API is limited (see Validation). All validation was done by AI agents isolated from the pipeline, not by human annotators.
Code written against one version of a library often breaks on another. LLM code assistants hit this
constantly: they suggest df.append(...) for pandas 2, read_csv(error_bad_lines=...), Retry(method_whitelist=...)
for urllib3 2, from flask import escape for Flask 3. Existing version-aware benchmarks are small and frozen.
This dataset is a large, refreshable record of which public API existed in which release: high precision, with
known blind spots (names created at runtime are often missing), so treat it as evidence, not as complete truth.
It contains:
| Libraries | 1,872 selected from the top of PyPI by downloads (1,869 with at least one analysable release) |
| Releases analysed | 55,565 final releases, 2021–October 2026 (at most the 80 most recent per library, so not every release since 2021) |
| Python modules parsed | 7,209,790 |
| Public API symbols tracked | 12,571,586 distinct paths (functions, classes, methods, attributes) |
| API history rows | 15,634,142 (symbol × signature × version interval) |
| Change events | 15,258,652 between consecutive releases |
| Breaking changes (deduplicated) | 210,535 (181,023 high-confidence) |
| Measured precision of high-confidence breaking changes | 88.8% (95% CI 80.0–94.0%; n=80) on an audit of libraries never used for tuning. Removals: 98.1%; signature changes: 79.2% |
| Measured recall (runtime reference set, 30 release pairs) | 14/16 within the dataset's public-API definition; 16/99 of all runtime-visible changes |
| Precision re-audited on v1.2 (fresh libraries) | 91.9% (95% CI 86.6–95.2%; n=160); 90.0% on claims new in v1.2, 93.8% on unchanged ones |
| VersionProbe labels correct (fresh untouched sample) | 91.5% (95% CI 88.4–93.9%; n=400) |
| Code repair, 143 real breaks (preregistered; repeated on 4 models of one family) | success 56.6% unaided, 60.1% with docs, 68.5% with this dataset; API history best for 4 of 4 models |
apidrift-check on 32 unseen real upgrades |
findings 92.6% correct; 9 of 18 API-caused test failures predicted |
Plus tools built on it:
apidrift-check, which flags code that uses an API that doesn't exist, or a keyword argument that isn't accepted, in the library versions you pin. It works offline and never imports the libraries.apidrift-lookup, one-line queries:apidrift-lookup diff pandas 1.5.3 2.2.0(what breaks on upgrade),apidrift-lookup history pandas DataFrame.append(when it existed, with which signatures).apidrift-mcp, an MCP server exposing the lookups and the checker to coding agents (Claude Code, Claude Desktop and other MCP clients).- VersionProbe, a benchmark of 10,958 paired snippets that are valid in one release and invalid in the next. It tests whether a model knows which API works in which version.
Author: Pushkar Devanahalli Gopalakrishna (Independent Researcher, USA) · Data: CC BY 4.0 · Code: Apache-2.0 Code: https://github.com/pushkardg/pypi-api-drift · Data: https://huggingface.co/datasets/pushkar87dg/pypi-api-drift
What makes it work
- Cheap: range reads, not downloads. Wheels are ZIP files, so the extractor reads the central directory with HTTP
range requests and fetches only the
.py/.pyimembers whose CRC changed since the previous release. Replayed over the full histories of 300 random projects, this transfers 8.5% of the wheels' bytes (95% CI 5.7–14.7%): about 26 GB (17–44 GB) for the whole dataset instead of 300 GB. Large compiled wheels are where it pays off (5.3% of their bytes fetched); a small pure-Python wheel is mostly source and costs about as much as downloading it (validation/transfer_measurement.json,pipeline/measure_transfer.py). - Safe: nothing is imported or executed during extraction. Every module is parsed with
ast. Untrusted package code never runs, so the whole PyPI history can be processed on ordinary infrastructure without sandboxing each release. (Runtime environments are used only by the separate validation studies.) - Removed means unreachable, not merely missing from
__all__. A name that leaves the public API is labelledremovedonly when static analysis shows it can no longer be reached through any import path (re-exports, star and relative imports, module__getattr__). Names still reachable, or undecidable statically, are labelledleft_public_apiinstead, which removes the largest source of false removals in naive API diffs. - Audited, then fixed, then re-audited. Agents isolated from the pipeline installed both releases and checked claimed breaking changes at runtime. Each error pattern they found became a rule fix plus a regression test, and the next round audited libraries never used for tuning (91.9% precision on v1.2). The fixes were made by hand between rounds; this is an audit loop, not automatic self-correction, and no human adjudicated the audits.
- Pick your own strictness. Filter
changesonconfidence == "high"to keep only the strongest breaking changes, onrepresentativeto count each change once, andapi_historyoncoverage_status == "static"to keep only modules where a missing name is strong evidence of absence (details under "What's indata/"). - Useful to code models. In a preregistered repair experiment, API history from the dataset raised the share of migrations that were API-compatible with the new release from 58.7% (closed book) and 69.9% (documentation) to 80.4%, and the share that were also judged intent-preserving from 56.6% / 60.1% to 68.5%. Compatibility means names resolve and arguments bind; nothing is executed (see "Code repair").
Quick start
Requires Python 3.10 or newer.
pip install pypi-api-drift          # or: pip install -e . from a clone
export APIDRIFT_DATA=/path/to/data
apidrift-check my_script.py --pin pandas==2.2.0 --pin flask==3.0.0
apidrift-check my_script.py -r requirements.txt --json
Pins must match an analysed release exactly. Otherwise the package is skipped with a note on stderr; pass --nearest
to check against the closest earlier analysed release instead.
my_script.py:3:0: [missing] flask.escape does not exist in flask==3.0.0 (last present in 2.3.3)
my_script.py:7:5: [missing] pandas.DataFrame.append does not exist in pandas==2.2.0 (last present in 1.5.3)
my_script.py:11:6: [bad_call] pandas.DataFrame.to_csv has no parameter 'line_terminator' in pandas==2.2.0 (accepted up to 1.4.4)
my_script.py:12:8: [bad_call] urllib3.util.retry.Retry has no parameter 'method_whitelist' in urllib3==2.2.0 (accepted up to 1.26.20)
my_script.py:18:4: [bad_call] pandas.read_csv has no parameter 'error_bad_lines' in pandas==2.2.0 (accepted up to 1.5.3)
The checker's default mode only flags names and keyword arguments that were part of the library's public API
in some other release. Those are version-drift errors, and false alarms are rare. --strict also flags names that never
existed (useful for catching invented APIs) and checks arity, but it is noisier.
import pandas as pd
ch = pd.read_parquet("data/changes.parquet",
                     filters=[("project", "=", "pandas"), ("breaking", "=", True), ("confidence", "=", "high")])
ch[ch.representative & ~ch.parent_removed].groupby("to_version").size()
Look things up, or give a coding agent the same lookups
apidrift-lookup diff flask 2.3.3 3.0.0          # breaking changes on upgrade, each with its confidence label
apidrift-lookup history pandas DataFrame.append  # pandas.DataFrame.append  method  1.4.0 .. 1.5.3  [deprecation marker]
apidrift-lookup versions sklearn                 # analysed releases (distribution or top-level module name)
diff compares the two releases' API snapshots, so any two analysed releases work, not only adjacent ones. Each
change is listed once (subclass and re-export copies are folded; --every-path lists them all). For a removed name it
shows where the same name still exists in the new release, as a hint rather than a verified replacement.
pip install "pypi-api-drift[mcp]" adds apidrift-mcp, a stdio MCP server with four read-only tools: api_versions,
api_history, api_diff and check_code. Add it to a client with
{"mcpServers": {"apidrift": {"command": "apidrift-mcp", "env": {"APIDRIFT_DATA": "/path/to/data"}}}}
Answers carry the dataset's blind spots with them: every history interval and every removal in a diff has a
coverage_status (static, dynamic_module, compiled_boundary, stub_only) and, when it is not static, a
coverage_note; a name that is not found comes with a reminder that absence is weaker evidence than a recorded change.
integrations/mcp_smoke.py checks a running server end to end (initialize, list tools, call each one against known
facts), and smoke_test.py runs it against the installed apidrift-mcp.
Known limit of check_code and the checker: methods are tracked on objects assigned to a name
(df = pd.DataFrame(); df.append(...)), not on chained calls (pd.DataFrame().append(...)).
Use it in CI
- Lockfiles.
apidrift-check src/picks upuv.lock,poetry.lock,pylock.tomlorPipfile.lockin the current folder automatically. You can also pass--lock FILE,-r requirements.txtor--pin pkg==ver. Directories are scanned recursively. - GitHub code scanning.
--sarif apidrift.sarifwrites SARIF 2.1.0.integrations/github-action/has a composite action that downloads the data once (cached), runs the checker and uploads the findings. The example workflow runs it on pull requests that touch Python files or lockfiles. The action is experimental: it has not yet run on a live GitHub runner (.github/workflows/tests.ymlexercises it end to end, including hostile inputs, once the repo is on GitHub). Workflow inputs reach the checker only through environment variables, are validated byrun_action.py, and are passed as an argument list, never as shell text; extra flags are limited tooptions:(--strict,--nearest,--no-deprecations). Downloaded data (and data restored from the cache) is checked against the SHA-256 hashes inDATA_MANIFEST.jsonbefore the checker runs. - Cost. The checker reads only the Parquet row groups of the pinned libraries and the signatures they
reference. A cold start (one file, one pin) takes about 3.1 s of CPU and 326 MB of memory. Checking
all 1,421 files of pandas against its installed dependencies took 45.7 s of CPU
(47.2 s wall on a shared two-core machine). See
validation/checker_performance.json. - pre-commit.
.pre-commit-hooks.yamldefines anapidrift-checkhook. SetAPIDRIFT_DATAto the data folder. - Suppression. Add
# apidrift: ignoreto a line to silence findings on it.
VersionProbe benchmark
benchmark/versionprobe.parquet holds 10,958 pairs (583 libraries). versionprobe_lite.parquet
is a 983-pair subset with at most 3 pairs per library, spread across years. Each pair is one snippet that is
valid for the release before a real breaking change and invalid for the release after it. Both halves of every pair
were verified with apidrift-check. Each item has change_released, the date of the breaking release, so you can
split results at a model's training cutoff. A constant answer scores 50%; pair accuracy (both halves right) is the
stricter metric.
pip install openai anthropic pandas pyarrow
python eval_versionprobe.py --data benchmark/versionprobe_verified.parquet --provider openai --model <model> --cutoff 2024-10-01
# local models: --provider openai --base-url http://localhost:8000/v1 (vLLM, Ollama, llama.cpp server)
Results are appended to results/leaderboard.md.
VersionProbe-verified (the default evaluation split) and a first baseline
Use benchmark/versionprobe_verified.parquet to evaluate and rank models. It holds the 492 pairs
(984 items, 375 libraries) whose labels were confirmed at runtime by the two benchmark audits; the
evidence for every pair is in benchmark/versionprobe_verified_evidence.csv. The verification was done by AI agents
isolated from the pipeline (both releases installed, every name resolved and every keyword bound), without human
adjudication, and the pairs come from audited samples, so they may be slightly easier than the benchmark as a whole.
The full 10,958-pair benchmark is a larger, noisier research resource (about 8.5% label error measured).
Claude (claude-opus-5-5), one question at a time |
Item accuracy | Pair accuracy |
|---|---|---|
| From its own knowledge | 58.4% (CI 55.3–61.5%) | 26.6% |
| With API history retrieved from this dataset | 100.0% (CI 99.6–100.0%) | 100.0% |
| Constant answer | 50% | 0% |
Without help the model accepted most valid snippets (72.8%) but caught only 44.1% of invalid
ones, and did worse on changes released after its training cutoff (52.1%, n=96). The retrieved
history lists, for every name and keyword in the snippet, the releases in which it existed or was accepted; it gives no
label and doesn't say what changed. Because that evidence answers the question once read correctly, the second row is
close to an upper bound for retrieval; the code-repair experiment below measures the effect on writing code. Prompts, raw
answers and scores are in validation/model_baseline/.
Code repair: does the dataset help a model fix real breaks?
A preregistered experiment (validation/code_repair/PREREGISTRATION.md, task list hashed before any model output):
143 real breaking changes from 109 libraries, each given as code written for the old release with the
instruction to update it for the new release while keeping its purpose. Each answer was checked at runtime with
only the new release installed (every name resolves and every call's arguments bind to its signature; the call is not executed, and
missing required arguments are not checked), and a separate model, blind to the
condition, judged whether it preserved the snippet's intent. "Both" means API-compatible and intent-preserving
under this protocol; it is not a behavioural test, and the intent check is an AI judgement, not human verification.
Claude (claude-opus-5-5) |
Closed book | + documentation of the new release | + PyPI API Drift history |
|---|---|---|---|
| API-compatible with the new release | 58.7% | 69.9% | 80.4% |
| Intent preserved (AI judge) | 93.0% | 86.0% | 88.1% |
| Both | 56.6% (CI 48.5–64.5%) | 60.1% (CI 52.0–67.8%) | 68.5% (CI 60.5–75.6%) |
API history beat closed book (exact McNemar p=0.0115) and documentation (p=0.0428). The documentation
condition is an API reference page for the imported module(s), generated with griffe from the new release's wheel.
The gain is moderate and comes from validity; a few more history-guided answers were judged unfaithful, mostly where
a "still available as" hint pointed to a same-named but different object. One model, an AI judge, and a check of
names and signatures rather than behaviour are the main limits. Everything is in validation/code_repair/.
Full-binding sensitivity check (post hoc, not preregistered). The preregistered check uses bind_partial, so a call
missing a required argument could pass. We re-verified every answer in fresh environments with full binding
(inspect.signature(...).bind). The re-run reproduced every preregistered verdict; full binding removed 2
successes (1 closed book, 1 documentation, 0 API Drift), giving 55.9% / 59.4% / 68.5%
(exact McNemar p=0.0064 vs closed book, p=0.0294 vs documentation). See results_strict_binding.json; reproduce
with pipeline/verify_repair.py ... --strict and pipeline/score_repair_strict.py.
Replication across models. Both experiments were then repeated, unchanged, with three more Claude models (same items and tasks, same runtime check, same blind judge):
| Model | VersionProbe-verified item / pair accuracy | Repair: closed book | + docs | + PyPI API Drift | API Drift vs docs (exact McNemar) |
|---|---|---|---|---|---|
claude-opus-5-5 (preregistered) |
58.4% / 26.6% | 56.6% | 60.1% | 68.5% | p=0.043 |
claude-sonnet-5-5 |
54.3% / 18.3% | 42.0% | 56.6% | 69.2% | p=0.0029 |
claude-haiku-5-5 |
49.6% / 9.2% | 7.0% | 46.2% | 68.5% | p=<0.0001 |
claude-fable-5-1 |
56.5% / 22.4% | 49.7% | 62.2% | 69.9% | p=0.071 |
With API history every model reached 68.5%–69.9%, whatever its closed-book score (7.0%–56.6%;
without help the smallest model left 88.7% of snippets unchanged). API history beat documentation for all
4 models, significantly for 3 (the exception: p=0.071). The models are of one family,
so this replicates the protocol rather than establishing the effect across model families. Answers, judge verdicts and per-task scores are in validation/multi_model/.
What's in data/
The six tables are published separately from the code (they are too large for the repository), on Hugging Face: https://huggingface.co/datasets/pushkar87dg/pypi-api-drift. Download them with
pip install -U huggingface_hub     # provides the `hf` command
hf download pushkar87dg/pypi-api-drift --repo-type dataset --include "data/*" --local-dir .
export APIDRIFT_DATA=$PWD/data
and check them against the pinned hashes before use:
python verify_data.py /path/to/data # prints OK / MISMATCH / MISSING per file; exit 1 on any problem
python smoke_test.py /path/to/data goes one step further: it installs this release into a fresh virtual environment
(non-editable, declared dependencies only), runs the test suite including the data-level regression tests, verifies
the data and runs the installed apidrift-check on examples/llm_generated_example.py. The result of our own run is in
validation/clean_install.json.
| File | Rows | One row per |
|---|---|---|
releases.parquet |
55,839 | analysed release: wheel used, module/symbol counts, bump type, breaking counts |
api_history.parquet |
15,634,142 | public symbol path × (kind, signature, deprecation) × contiguous range of releases |
changes.parquet |
15,258,652 | change between consecutive releases (added, removed, parameter-level changes, …) |
signatures.parquet |
799,705 | distinct signature (JSON list of parameters with kind, default and annotation) |
top_level_modules.parquet |
211,244 | public module path → distribution (any analysed release), used to map imports to PyPI projects |
module_coverage.parquet |
289,735 | module × coverage state × contiguous range of releases (see below) |
Coverage: when absence is not proof
Static analysis cannot see everything, so a name missing from api_history does not prove that it does not exist.
module_coverage.parquet records, for every module and range of releases, its source (py, py+pyi, pyi = stub
only, compiled, unparseable), whether it is dynamic (an open module __getattr__, globals() injection or a
runtime __all__), whether it imports_compiled names, and which classes have decorator-generated constructors.
Every api_history row has a coverage_status summarizing its module over the row's range:
coverage_status |
Share of rows | Meaning |
|---|---|---|
static |
79.1% | parsed from Python source; absence is strong evidence |
compiled_boundary |
0.8% | the module is compiled or binds names from compiled code |
dynamic_module |
17.7% | the module can serve names the dataset does not list |
stub_only |
2.3% | only a .pyi stub ships; the stub may disagree with the runtime |
The coverage pass flags a module as dynamic on any use of globals(), which is broader than the extractor's rule, so
it errs toward warning.
Key columns of changes.parquet:
change_type:removed,added,param_removed,param_renamed,required_param_added,became_keyword_only,became_positional_only,default_removed,vararg_removed,varkw_removed,positional_reordered,kind_changed, plus non-breakingoptional_param_added,default_changed,annotation_changed,return_annotation_changed,deprecation_marker_added,became_dynamic,left_public_api.breaking: True when callers written for the old release can fail on the new one.confidence:high, ormediumwhen the evidence is weaker (a member missing from a class whose bases live in another package, symbols known only from type stubs, removed**kwargs).representative: one row per underlying change. The same method change shows up under every subclass and re-export path; filter on this to count real changes.parent_removed: True when the whole enclosing class or module was removed in the same release.deprecated_before: True when the symbol carried a deprecation marker in an earlier release.detail: e.g.old -> newfor renames,still available as Xwhen a removed path survives elsewhere.
Headline findings
13.4% of patch releases (29,409 analysed) and 29.3% of minor releases break their public API, compared with 64.4% of major releases. 840 libraries shipped at least one breaking patch release.
Only 4.8% of removed functions, classes and methods carried a detectable deprecation marker in an earlier release.
83,846 high-confidence breaking changes were released in 2025–2026, after the training cutoff of many current code models.
Among the 54 libraries whose PyPI description says they follow Semantic Versioning, 16.7% of stable (≥1.0) patch releases and 24.5% of stable minor releases contain a high-confidence breaking change (17 of 40 such projects at least once). These are candidate SemVer violations; rarely used members count too. 61 libraries use calendar versioning, 2 say they don't follow SemVer, and 1,755 state no policy on PyPI. The classification and every reviewed match are in
validation/versioning_policy.csv.
How it was built
- Selection. The top 2,000 projects by PyPI downloads (hugovk/top-pypi-packages, October 2026). For each one we take final releases uploaded since 2021-01-01, capped at the 80 most recent, using one wheel per release (pure-Python preferred, else CPython manylinux x86_64).
- Range reads. Only the ZIP central directory and the
.py/.pyimembers are downloaded, and members unchanged since the previous release (same CRC) are reused: 8.5% of the wheels' bytes in our measurement. - Static extraction. We parse with Python's
ast, without importing anything. We resolve__all__, re-exports, star imports, relative imports, inherited members from classes in the same package, conditional andtry/exceptimports, module__getattr__lazy loading (including names it explicitly rejects), PEP 484__xpositional-only parameters,@overloadstubs, and runtime source over.pyistubs. - Accessibility check. A symbol that leaves the public API is recorded as
removedonly when it is provably no longer reachable. If it's still reachable (dropped from__all__, re-exported from elsewhere, lazily served) or can't be decided statically (compiled modules, dynamically generated namespaces), it is recorded asleft_public_apiand kept in the history. - Coverage. A second pass records per-module coverage (above).
- Integrity.
pipeline/validate_dataset.pyruns 51 checks on every build (keys, version order, interval consistency, signature references, change/release consistency, label domains, benchmark provenance, and a recount of every number instats.json); this build passes all of them (validation/dataset_checks.json).tests/holds 158 regression tests, including every false-positive pattern the audits found. - Validation. Pipeline-isolated AI agents re-checked random samples of claimed breaking changes by installing both releases and inspecting them at runtime. See below.
Validation
All studies below are pipeline-isolated, AI-agent-conducted runtime audits. The independence comes from the agent never seeing the pipeline, the data or the checker, not from a separate human researcher, and disputed cases were not adjudicated by humans. The audits were carried out by an AI agent (an LLM with shell access), not by human reviewers. It had no access to the pipeline or the dataset files, only to a CSV of sampled claims. For each claim it installed both releases in fresh virtual environments and checked the claim at runtime, falling back to reading the released source when a release could not be installed. In round 3, 82 of 100 claims were checked at runtime and 18 from source. Treat these figures as a systematic, reproducible spot check, not as human-annotated ground truth.
| Audit | Sample | Result |
|---|---|---|
| 1 (first version of the pipeline) | 60 claims, 32 libraries | 37% false positives → fixed |
| 2 (after fixes) | 60 claims, 32 new libraries | 25% false positives → fixed |
| 3 (released pipeline, libraries never used for tuning) | 100 claims, 53 libraries | high confidence: 88.8% precision (92.5% incl. partially correct), n=80; medium: 45.0%, n=20 |
By category, round-3 high-confidence precision was 98.1% for removals (n=53, 95% CI 90.1–99.7%) and
79.2% for signature changes (n=24, 95% CI 59.5–90.8%). All 3 sampled kind changes were wrong, and they are now medium.
Medium-confidence precision was 45.0% (95% CI 25.8–65.8%, n=20).
After round 3, two rules moved to medium: removed *args/**kwargs, which are often only forwarded to a base class,
and classes turned into plain attributes, which are often Name = OtherClass aliases. Re-scored against the released
tables, 94.5% of the remaining high-confidence round-3 claims are confirmed (n=73).
That figure is partly in-sample, so the out-of-sample estimate stays 88.8%. Use confidence == "high" when
you need the most reliable claims, and treat medium as candidates. The audit samples, verdicts, evidence and protocol are in
validation/. Errors that remain usually involve names created at
runtime in ways static analysis can't see (decorators that rename parameters, attributes set via setattr).
VersionProbe labels, checked at runtime
Fresh sample (out of sample). After the benchmark was rebuilt, a new sample of 400 pairs was drawn from libraries never used in any audit, study or fix (265 libraries). 366 of the 400 decided pairs were labelled correctly: 91.5% (95% CI 88.4–93.9%); every pair was decided.
| Change type | n | Correct |
|---|---|---|
| Symbol removed | 292 | 90.8% (CI 86.9–93.6%) |
| Parameter removed | 54 | 96.3% (CI 87.5–99.0%) |
| Parameter renamed | 54 | 90.7% (CI 80.1–96.0%) |
"Invalid after" held 97.3% of the time and "valid before" 94.0%. Nearly every error is a name
that looks present statically but doesn't exist at runtime: removed with del after use (versioneer's
get_versions), defined only in a Python-2 or if False: branch, present only in a .pyi stub, or a class attribute
read as a module attribute. One came from a bogus 0.0.0 release ordered before real ones. The del case is fixed in
the extractor and applies from the next refresh. Per-pair results are in validation/benchmark_check2/.
First sample. A separate AI agent verified 200 randomly sampled VersionProbe pairs, one per library and from libraries not
used in the precision audits. It installed both releases and resolved every name and keyword in the snippet.
172 pairs (86.0%, 95% CI 80.5–90.1%) were labelled correctly. "Invalid after" held
99.0% of the time, but "valid before" only 87.0%. Most wrong labels came from snippets that read
instance-only attributes through the class (Class.attr), and from names that exist only for type checkers
(if TYPE_CHECKING: blocks, .pyi-only aliases). Both are now excluded and the benchmark was rebuilt. 22 of the 28 wrong pairs dropped out, and
130 of the 136 audited pairs still in the benchmark are correct (95.6%). That figure is in-sample, so the
out-of-sample estimate stays 86.0%.
Recall
A separate AI agent introspected both releases of 30 random release pairs at runtime and listed every breaking change it found (99 in total). The dataset contained:
| View | Before the fixes these studies prompted | After |
|---|---|---|
Changes within this dataset's public-API definition (excluding incidental imports and *args pass-throughs) |
87.5% (14/16, 95% CI 64.0–96.5%) | 87.5% (14/16) |
All runtime-visible changes except trio |
59.3% (16/27) | 59.3% (16/27) |
| All runtime-visible changes | 16.2% (16/99) | 16.2% (16/99) |
The third row is dominated by trio 0.23: 72 of its wrapper methods were generated at runtime in 0.22, which static
analysis can't see. The other misses are mostly names a module imported for its own use, such as
from .util import timedelta_seconds. They are reachable at runtime, but this dataset doesn't count them as public API.
Comparison with griffe and AexPy
The same 30 release pairs were analysed with griffe 2.4 (static) and AexPy 0.4.3 (imports both releases), and every
method was scored with the same matching rule against the runtime reference set
(validation/tool_comparison/):
| Ground-truth breaking changes detected | PyPI API Drift | griffe | AexPy |
|---|---|---|---|
| Within this dataset's public-API definition | 14/16 | 12/16 | 13/16 |
All runtime-visible except trio |
16/27 | 12/27 | 20/27 |
| All runtime-visible | 16/99 | 12/99 | 90/99 |
| Median time per pair (extract both releases) | 2.1 s (range reads, nothing installed) | 1.3 s (downloads wheels) | 62.7 s (installs both releases) |
AexPy sees runtime-generated API that static tools can't, at the cost of installing and importing every release (one
pair ran out of memory). Within the shared definition the three are close. The reference set turned out to be incomplete
(e.g. removed bs4 entity constants that this dataset and AexPy both report), so the tools' extra claims are
reported as agreement with it (17/55, 13/80,
102/121 public claims), not as precision.
Downstream pilot: real upgrade failures
A separate AI agent ran the test suites of 12 real projects before and after a dependency upgrade: 9 upgrades that
broke the project and 3 controls. Examples are requests-toolbelt on urllib3 2, Flask-Login on Werkzeug 3, lmfit on
numpy 2, dataset on SQLAlchemy 2 and jinjasql on Jinja2 3.1. It recorded 12 distinct API-caused failures.
apidrift-check was then run on the same code with the same pinned environments.
| Before the fixes | After | |
|---|---|---|
| Findings that point at a real break | 7/7 | 14/14 |
| Findings on the old environment or on the controls | 0 / 0 of 3 | 0 / 0 of 3 |
| API failures predicted | 4/12 | 8/12 |
| Breaking upgrades flagged | 3/9 | 5/9 |
3 of the 12 failures were caused by downstream code using private names (flask._app_ctx_stack,
click._bashcomplete, marshmallow.utils._Missing). These are outside the tracked public API by design. One more came
from a method call on a function parameter whose type the checker can't infer (df.iteritems()).
Unseen upgrades: the checker frozen, new cases
The checker and data were frozen (hashes in validation/downstream2/FROZEN_sha256.txt) before two agents, who never
ran the checker, collected 35 new upgrade cases: 25 expected breaks and 10 controls
over 27 libraries, including compiled packages (numpy, scipy, lxml, aiohttp, cryptography) and lazily loaded
APIs (pydantic 2, numpy 2, marshmallow 4). 32 could be scored; the other three pin releases the dataset never
analysed, and the checker said so instead of guessing.
| Frozen checker | Result |
|---|---|
| Findings that point at real incompatible code | 63/68 (92.6%, CI 83.9–96.8%) |
| API-caused test failures predicted (per failure) | 9/18 (50.0%, CI 29.0–71.0%) |
| Truly breaking upgrades predicted completely | 8/18 |
| Upgrades with no API failure that got findings | 3/14 (two of them real but untested incompatibilities) |
| Findings on the old environments | 4 |
Misses: names removed behind module __getattr__ deprecation shims (numpy.bool8, NetworkX), names only ever served
by such shims (numpy.float), a module that now re-exports a split-out package (lxml.html.clean), static misreads
(scipy.integrate.simps, matplotlib.cm.get_cmap), a dunder name (skipped by design), a call through a subclass's
super().__init__, and one checker bug: modules removed in later releases were not mapped to their distribution
(pkg_resources in setuptools 82). That bug is fixed; re-scored in-sample with the fix and the data corrections, the
checker predicts 14/18, and 93 of its 106 findings match what the agents observed at runtime
(most of the rest are uses of modules removed in the new release, such as pandas.util.testing in pandas 2.0, in test
code the agents did not list).
Corrections in this release
The new integrity checks, tests and studies found four defects in the first build, fixed here:
77 renames of positional-only parameters were marked breaking (callers can't pass them by name);
369 breaking constructor-signature events concerned classes whose constructor a decorator builds
(dataclasses, attrs, factories; 79,234 such class definitions were found). They used an inherited base-class
signature and are now medium, with the signature dropped from 9,373 history rows;
342,126 history rows of two projects extended over releases too large to analyse; and the module map used only each
library's latest release. validation/patch_log.json lists the counts.
Version 1.2 was re-audited on 160 fresh claims from 134 libraries never used before, stratified
into claims new in v1.2 and unchanged ones: 91.9% overall (CI 86.6–95.2%), 90.0% on new claims,
93.8% on unchanged ones, 93.6% weighted by stratum size (validation/audit4/). By verification
method: 92.0% (115/125) for claims checked at runtime and 91.4% (32/35) for claims checked from source. (In round 3:
97.1% at runtime, 67/69, and 36.4% from source, 4/11 — packages that could not be installed.)
Version 1.2. The unseen-upgrade misses traced to three over-cautious rules, now fixed: any use of globals(), even
a read inside __dir__, marked a module as dynamic and hid every removal in it (numpy 2.0's bool8, float); a
runtime-built __all__ blocked attribute checks although it only affects star exports (scipy's simps); and
star-import chains were abandoned instead of followed (networkx). With these and the del fix the whole dataset was
re-extracted: high-confidence breaking changes went from 175,221 to 181,950 (6,743
more removals found), 82 VersionProbe pairs whose change no longer holds were dropped (including
4 the fresh audit had judged wrong; validation/v12_dropped_pairs.csv), and the checker now
checks super().__init__(...) and other super() calls against library base classes. The round-3 audit re-scored on
the new tables keeps 94.5% precision (n=73); all after-fix figures are in-sample.
Version 1.3. Two more defects, found by the third review: 5 placeholder releases (deepmerge, duckdb, pystache, pytest-xdist, python-daemon;
version 0.0.0 or 0.0 uploaded after real releases) had been sorted first and diffed against unrelated builds, and
are removed (1,761 change events and 6 VersionProbe pairs dropped, including 2 the fresh benchmark
audit had judged wrong; validation/placeholder_releases.json), with selection and a new integrity check excluding
them. And names that a module __getattr__ serves from module-level containers (deprecation shims such as numpy's
__deprecated_attrs__, lazy-import maps) were invisible; they are now followed when the container's filling is static.
A name counts as served only where the lookup returns an object, and as removed only where __getattr__ explicitly
rejects it (numpy's __former_attrs__); a name merely leaving a lazy map is left_public_api. This re-extracted
56 libraries (public symbol paths +27,360) and exposed a dating problem: a name that becomes
statically undecidable is carried forward, and its removal is recorded where it becomes provable, which can be later
than the real removal (numpy dropped float in 1.24.0 but rejects it explicitly only from 1.24.2). The 1,123
distinct high-confidence removals with that history are now medium, with the earliest possible release in detail,
and 66 VersionProbe pairs built on them were dropped. High-confidence breaking changes:
181,935 → 181,023 (validation/v13_changes.json). The audits above were run on v1.2. Re-scored on
v1.3, the unseen-upgrade study is unchanged (14/18): the numpy case is exactly such an undecidable
release, so the checker still cannot flag numpy.float for numpy 1.24.0.
Limitations
- This is static analysis. Compiled extensions are only visible through their
.pyistubs, and dynamically generated namespaces are treated as unknown rather than guessed. - The history covers at most the 80 most recent final releases per library; it is not a complete history since 2021.
Release ordering trusts version numbers (one bogus
0.0.0upload was mis-ordered). 274 releases of very large packages (over 8,000 modules, e.g. ansible) were skipped. - Inherited members from classes in other packages aren't resolved, so these cases are marked
medium. - Behavioural changes with identical signatures aren't captured.
- Recall depends on what counts as public. Names a module imports for internal use and objects generated at runtime are not tracked (see Recall).
- The checker only infers types for objects created in the same scope (
df = pd.DataFrame(...)) and followssuper()calls into library base classes. Calls on function parameters and return values are not resolved, and private (_name) APIs are never flagged. - VersionProbe labels were generated from this dataset. Runtime checks of 600 pairs measured their correctness (see above); the rest have not been run.
- All audits were done by AI agents isolated from the pipeline, without human adjudication, on samples of 60–400 items, so figures carry the intervals shown.
- A tool that imports releases (AexPy) finds many more runtime-generated changes than this static dataset.
- The model experiments use one model; the code-repair study checks names and signatures at runtime and intent with an AI judge, not program behaviour.
- "No findings" does not mean an upgrade is safe: the checker is a conservative warning tool (see the unseen-upgrade study).
Citation
If you use the dataset, the tools or the benchmark, please cite the paper:
Pushkar Devanahalli Gopalakrishna. PyPI API Drift: A Release-Level Record of Public API Changes in 1,872 Popular Python Libraries, with a Checker and a Benchmark for Version-Aware Code Generation. Zenodo, 2026. https://doi.org/10.5281/zenodo.23648339
@misc{devanahalli2026apidrift,
  author    = {Devanahalli Gopalakrishna, Pushkar},
  title     = {{PyPI API Drift}: A Release-Level Record of Public {API} Changes in 1,872 Popular {Python} Libraries, with a Checker and a Benchmark for Version-Aware Code Generation},
  year      = {2026},
  publisher = {Zenodo},
  doi       = {10.5281/zenodo.23648339},
  url       = {https://doi.org/10.5281/zenodo.23648339}
}
CITATION.cff has the same information in machine-readable form (GitHub's "Cite this repository" button uses it).
License
Data: CC BY 4.0. Code: Apache-2.0. See LICENSE and LICENSE-DATA.md. Copyright 2026 Pushkar Devanahalli Gopalakrishna.
- Downloads last month
- 118