

Ancient-Bench: A Comprehensive Multi-millennial, Multi-medium, and Multi-script Benchmark for Ancient Chinese Artifact Text Recognition
Paper • 2608.27169 • Published
Error code: RowsPostProcessingError
Need help to make the dataset viewer work? Make sure to review how to configure the dataset viewer, and open a discussion for direct support.

[EN] Strictly for Academic Research Use Only.
The images in Ancient-Bench are curated from publicly accessible archives of official museums, libraries, and cultural heritage institutions. The dataset creators claim no copyright over the source images. Any commercial exploitation is strictly prohibited. Users must comply with the copyright guidelines of the originating institutions.[ZH] 本数据集仅限非商业学术研究使用。
Ancient-Bench 数据集所收录图像均源自各大国家级博物馆、图书馆等公开发布的数字化文博资源。作者团队不拥有亦不转让任何原始图像版权。严禁用于任何商业营利行为。
Ancient-Bench (Accepted by EMNLP 2026) is the first comprehensive benchmark for ancient Chinese artifact text recognition, featuring:
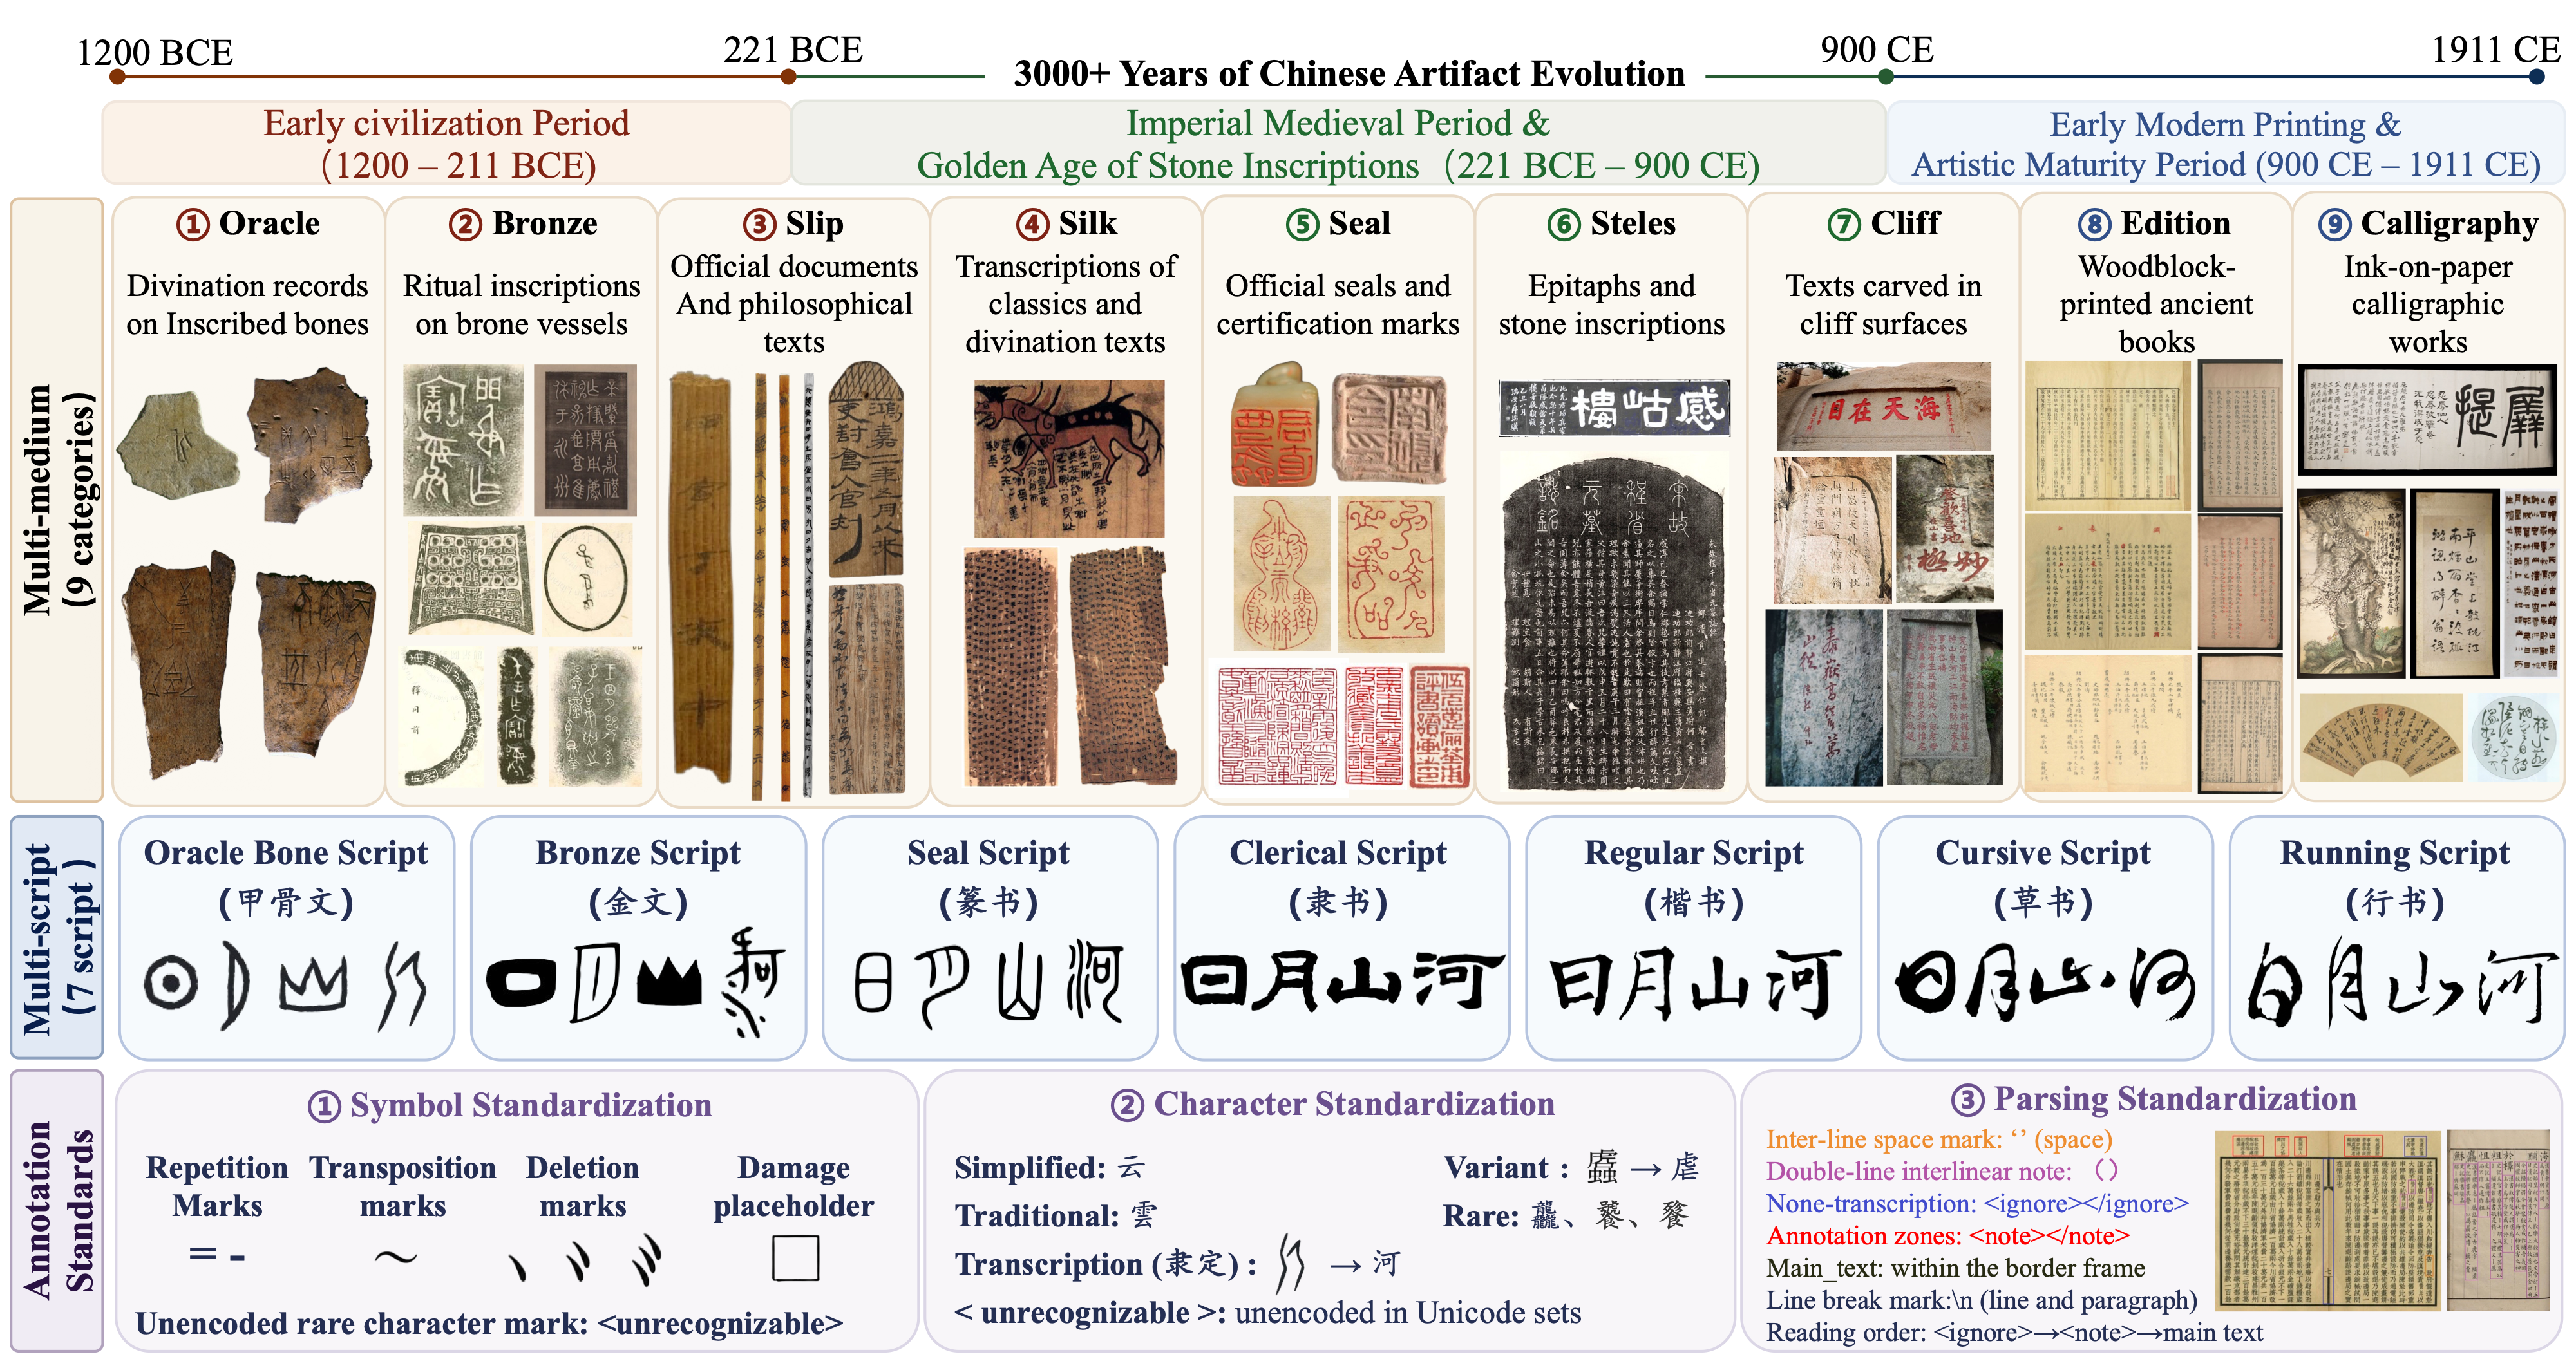
The benchmark contains 2,700 meticulously annotated high-resolution images from 14 national-level cultural institutions:
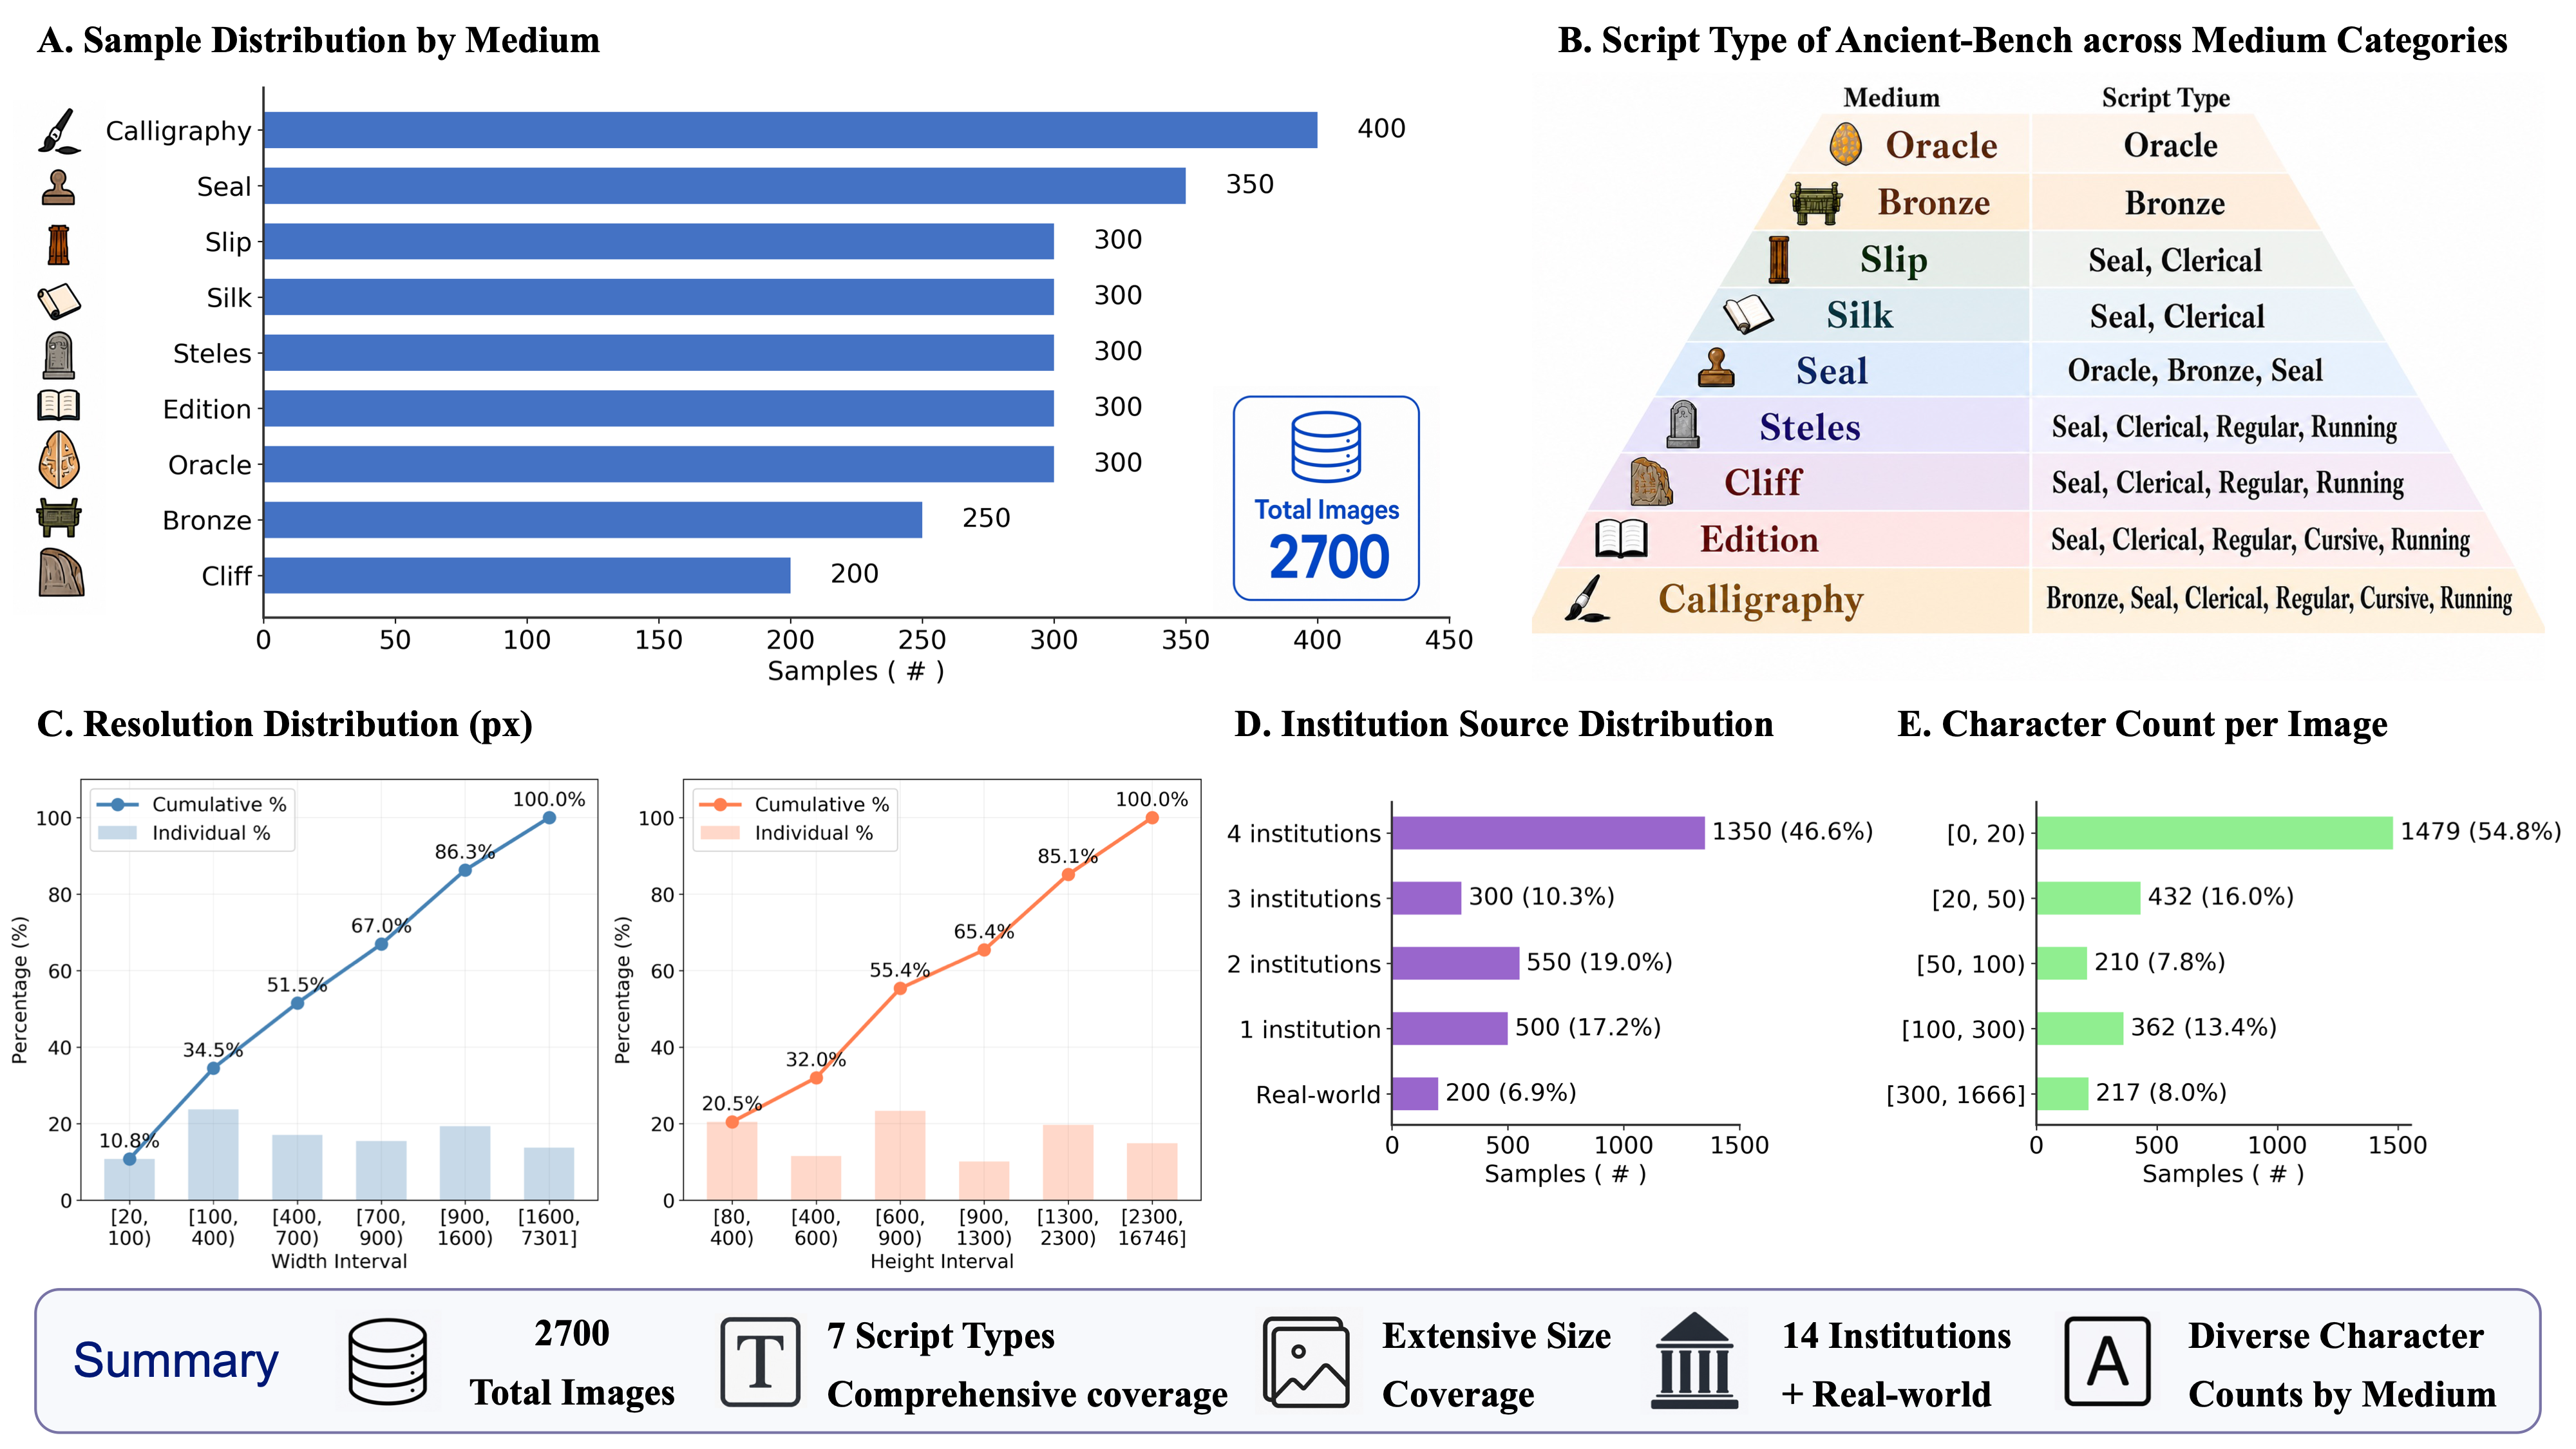
| Medium Category | Number of Images | Resolution Range (px) | Chars / Image | Covered Scripts |
|---|---|---|---|---|
| Oracle (甲骨) | 300 | 600×800 | 1–68 | Oracle Bone Script |
| Bronze (青铜器/金文) | 250 | 41×80 – 1024×1024 | 1–77 | Bronze Script |
| Slip (简牍) | 300 | 29×224 – 700×6820 | 1–107 | Seal, Clerical Script |
| Silk (帛书) | 300 | 46×124 – 1330×2067 | 1–784 | Seal, Clerical Script |
| Seal (印章) | 350 | 100×150 – 1333×1341 | 1–40 | Oracle, Bronze, Seal Script |
| Steles (碑帖墓志) | 300 | 85×155 – 5795×16745 | 4–816 | Seal, Clerical, Regular, Running |
| Cliff (摩崖石刻) | 200 | 183×113 – 7300×5760 | 2–216 | Seal, Clerical, Regular, Running |
| Edition (古籍刻本) | 300 | 751×506 – 970×2817 | 4–776 | Seal, Clerical, Regular, Cursive, Running |
| Calligraphy (书法手迹) | 400 | 303×509 – 4802×13385 | 2–1666 | Bronze, Seal, Clerical, Regular, Cursive, Running |
| Total | 2,700 | 41×80 – 5795×16745 | 1–1666 | All 7 Scripts |
You can download the dataset archive using the huggingface_hub Python library:
from huggingface_hub import hf_hub_download

zip_path = hf_hub_download(
    repo_id="hiuyi/Ancient-Bench",
    filename="Ancient-Bench.zip",
    repo_type="dataset",
    local_dir="./",
)

print(f"Dataset downloaded to: {zip_path}")