
Datasets:

You need to agree to share your Hugging Face information to access this dataset
This repository is publicly accessible, but you have to accept the conditions to access its files and content.
Access is granted only if you accept the terms below. In these terms, "EchoNova" means EchoNova AI L.L.C-FZ (Meydan Free Zone, Dubai, United Arab Emirates; licence 2650442.01). 1. You use the audio for research and evaluation only, under the terms on this card. 2. EchoNova makes no representation or warranty about the dataset. 3. You accept full responsibility for your use of the dataset and indemnify EchoNova against claims arising from it. 4. EchoNova may remove clips or end your access at any time.
Log in or Sign Up to review the conditions and access this dataset content.

EchoNova Arabic Dialect Benchmark (public subset)
مجموعة اختبار مفتوحة لقياس دقة تحويل الكلام العربي إلى نص: الفصحى وثماني لهجات، في 19.95 ساعة و8,925 مقطعًا، ولكل مقطع نص مرجعي كتبه إنسان.
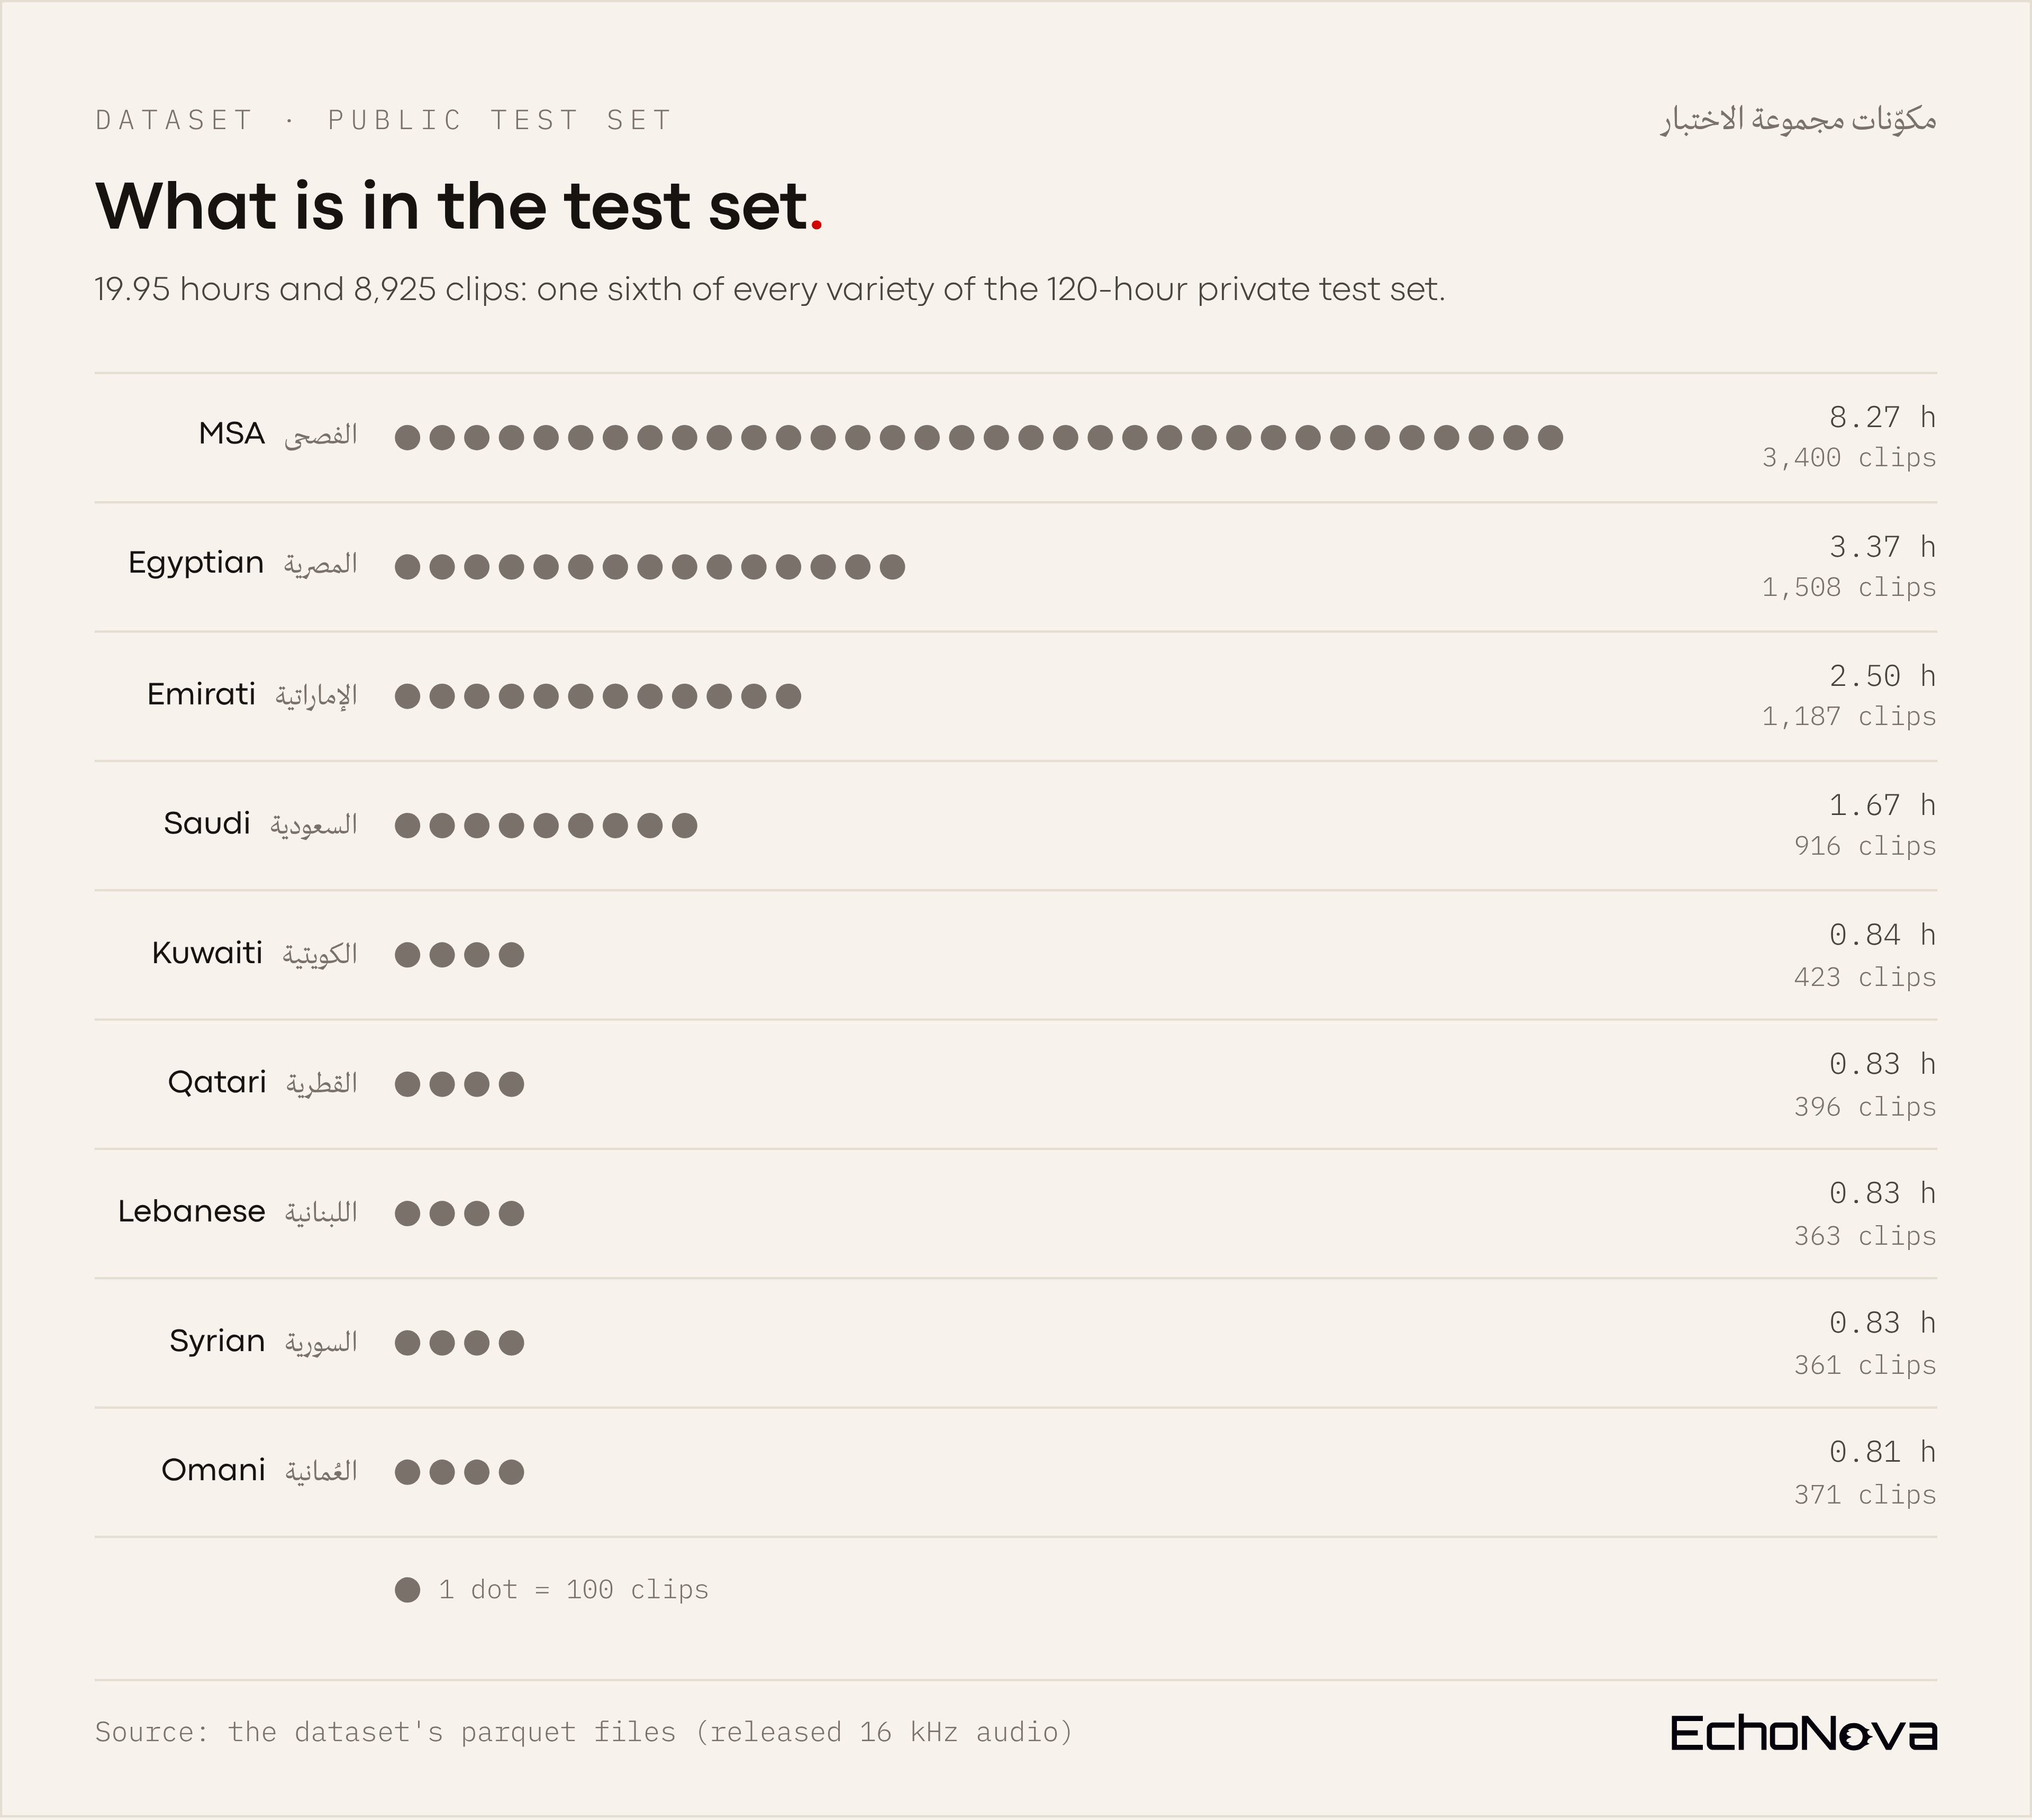
A 20-hour subset of the private test set used in the EchoNova Sada technical paper: Modern Standard Arabic and eight dialects (Egyptian, Emirati, Saudi, Kuwaiti, Qatari, Omani, Syrian, Lebanese), cut into clips of at most 30 seconds, each with a human reference transcript. Hours per dialect are listed below. Headline figures in the paper are computed on the full 120-hour test set, of which this subset is one sixth; the remaining 100 hours are not released.
Results on this subset
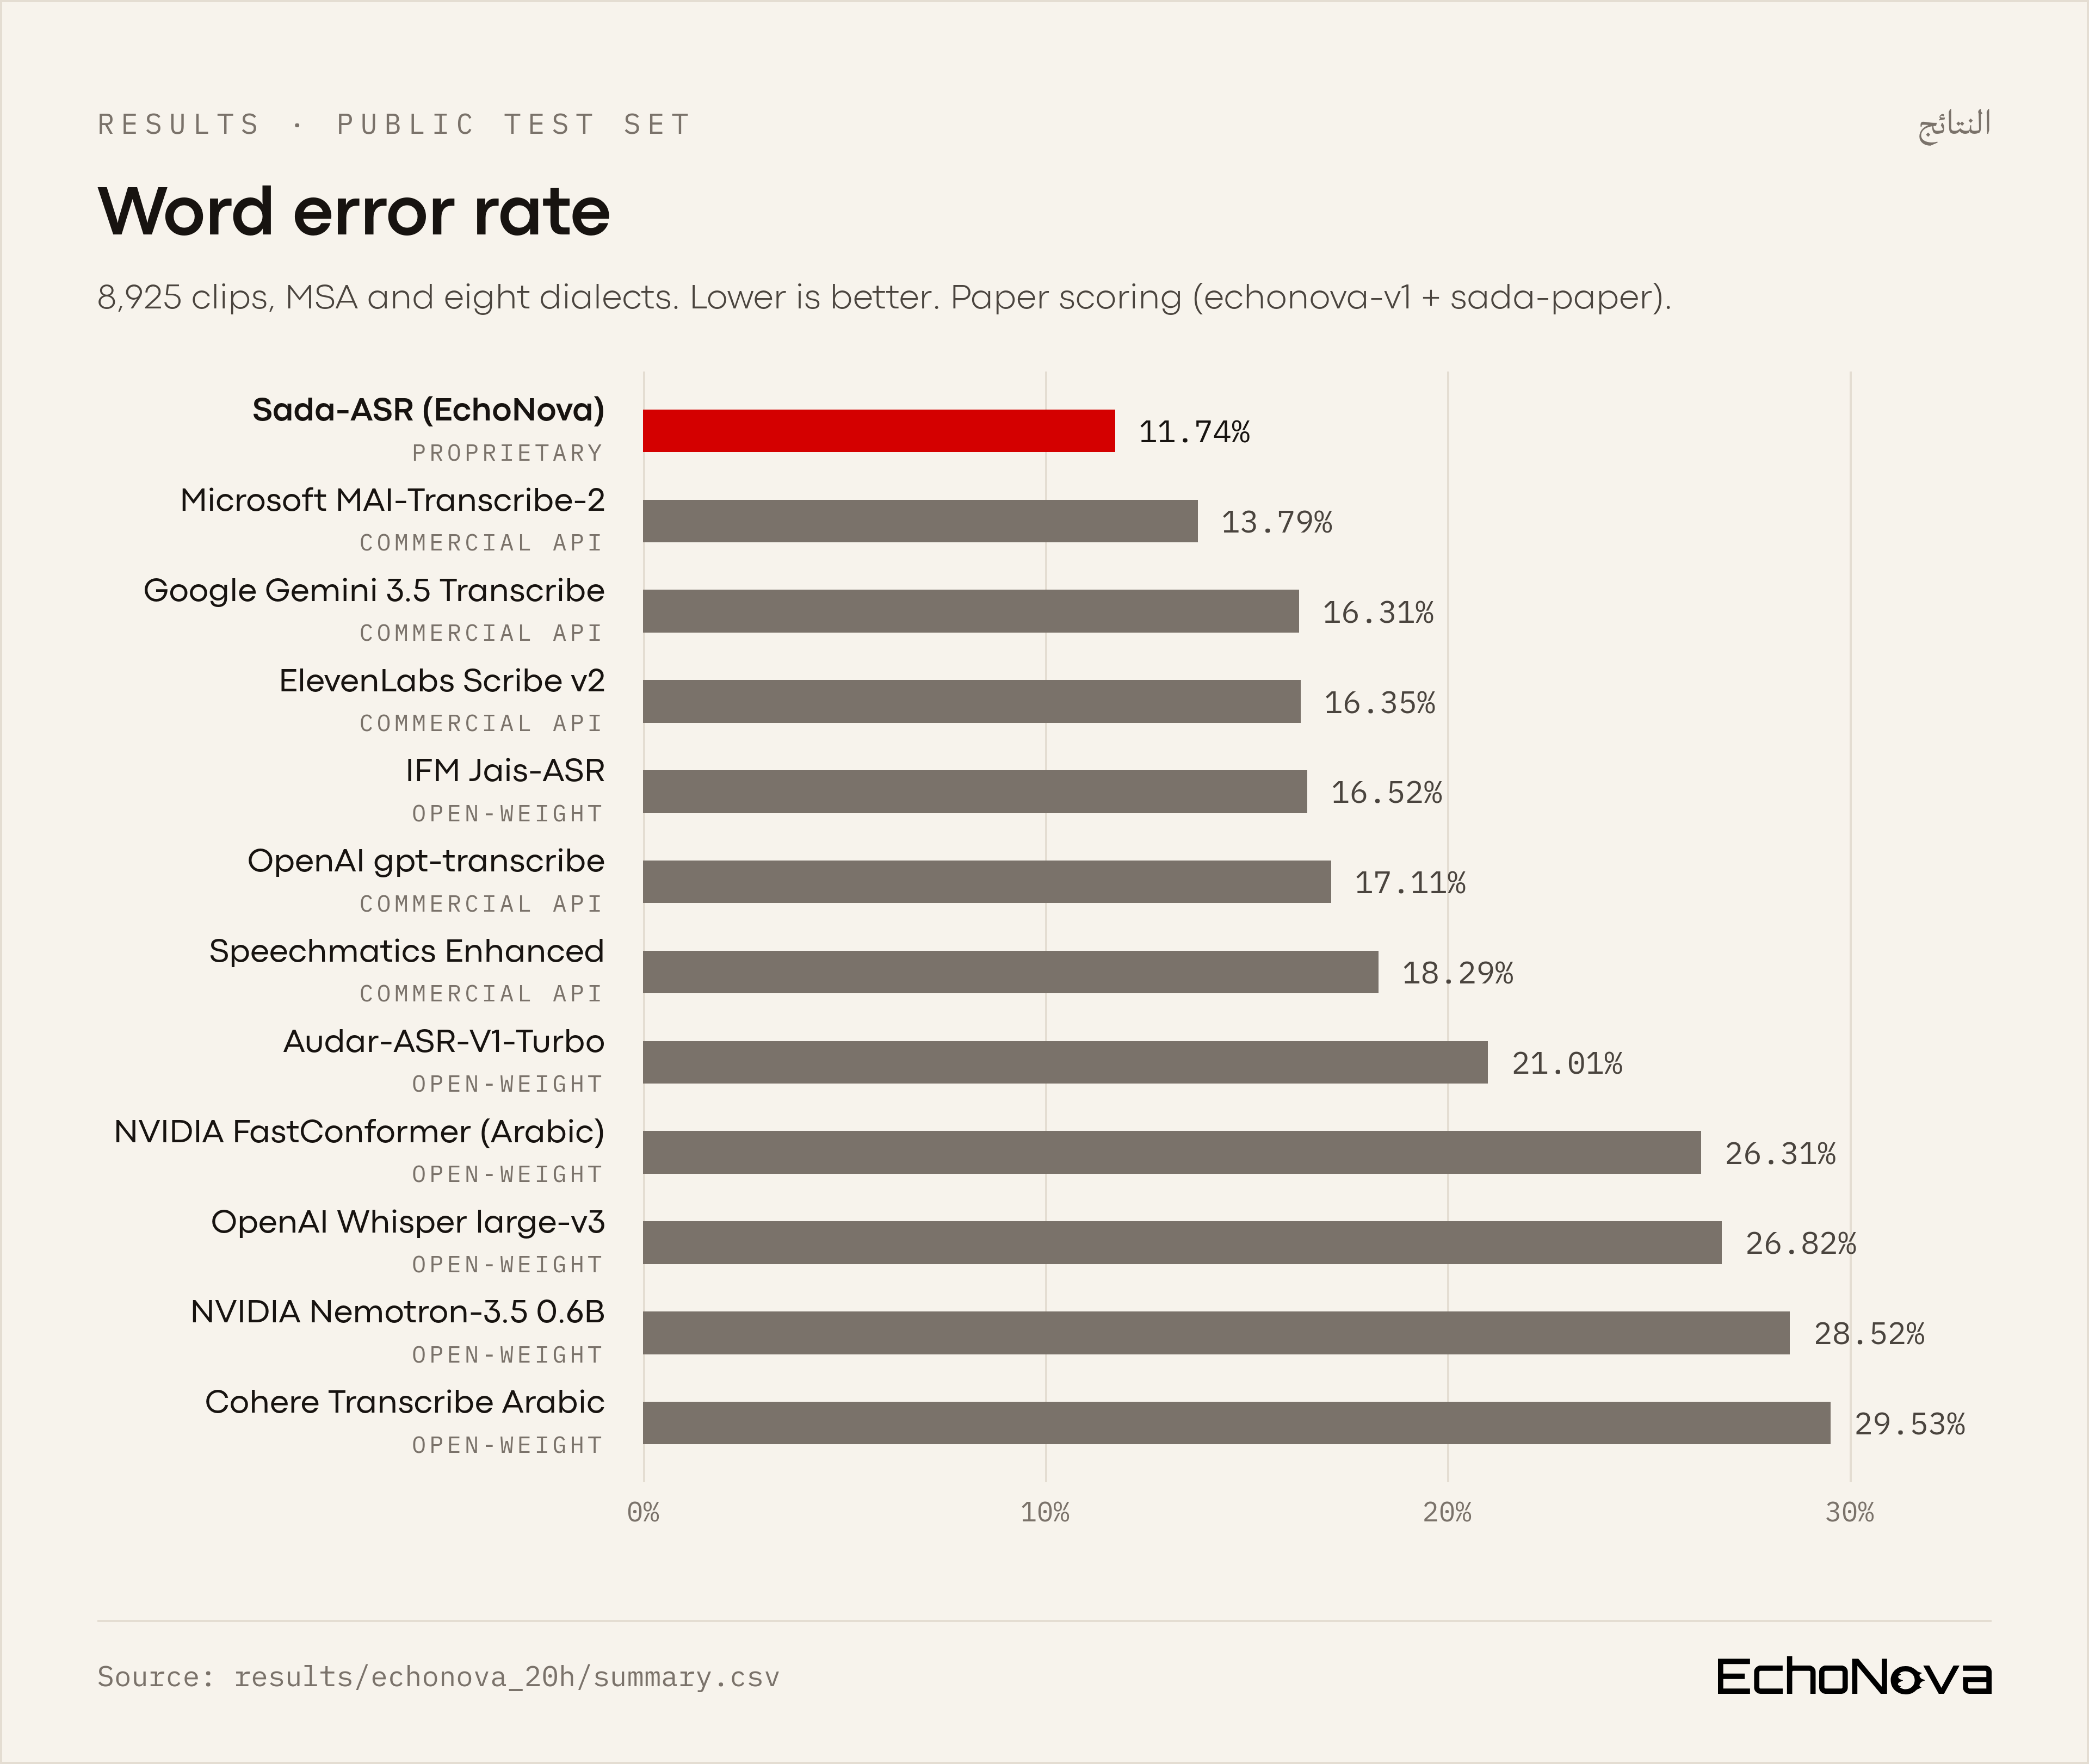
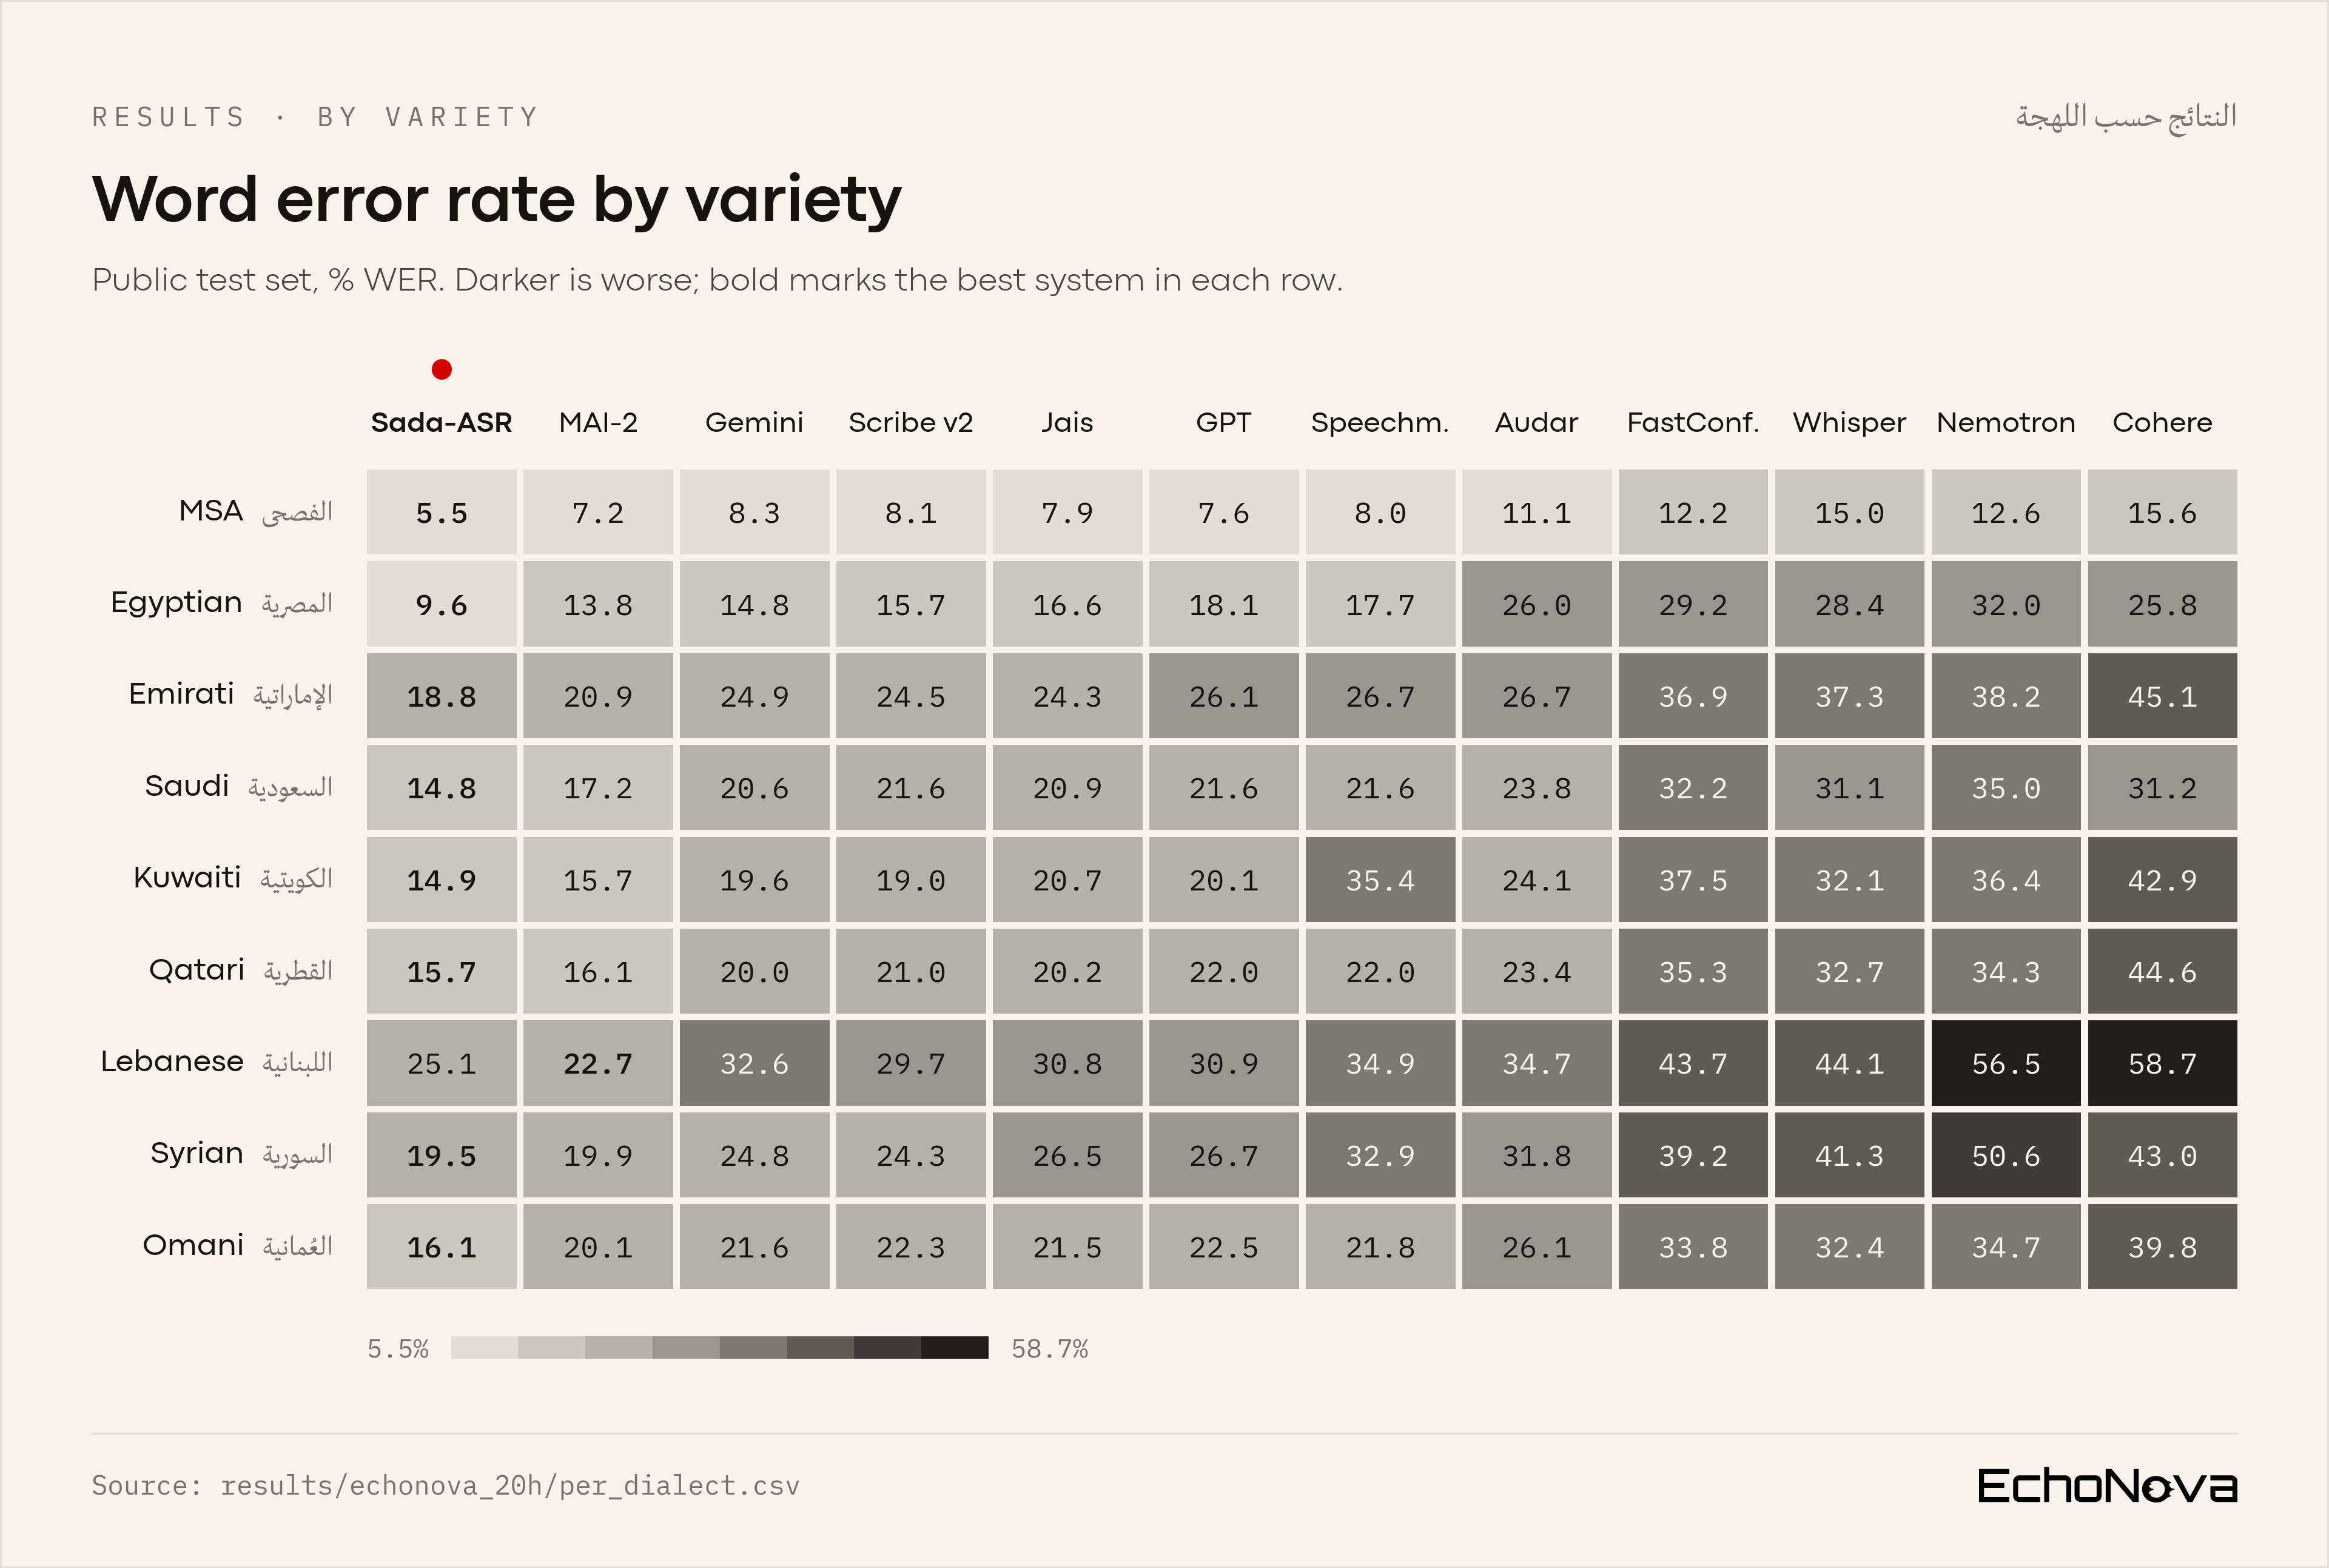
Word error rate of the twelve systems compared in the paper, scored on this subset with the paper's normalization and scoring. Per-variety tables, confidence intervals, the scorer and the steps to reproduce these numbers are in the GitHub repository.
| System | Type | WER | Macro WER | CER | Empty % |
|---|---|---|---|---|---|
| Sada-ASR (EchoNova) | proprietary | 11.74 | 15.56 | 4.72 | 0.00 |
| Microsoft MAI-Transcribe-2 | commercial API | 13.79 | 17.07 | 6.52 | 0.01 |
| Google Gemini 3.5 Transcribe | commercial API | 16.31 | 20.80 | 8.39 | 0.03 |
| ElevenLabs Scribe v2 | commercial API | 16.35 | 20.69 | 7.73 | 0.10 |
| IFM Jais-ASR | open-weight | 16.52 | 21.03 | 6.96 | 0.00 |
| OpenAI gpt-transcribe | commercial API | 17.11 | 21.72 | 8.61 | 0.01 |
| Speechmatics Enhanced | commercial API | 18.29 | 24.54 | 8.90 | 0.00 |
| Audar-ASR-V1-Turbo | open-weight | 21.01 | 25.29 | 10.09 | 0.00 |
| NVIDIA FastConformer (Arabic) | open-weight | 26.31 | 33.36 | 12.42 | 0.00 |
| OpenAI Whisper large-v3 | open-weight | 26.82 | 32.72 | 15.17 | 0.00 |
| NVIDIA Nemotron-3.5 ASR streaming 0.6B | open-weight | 28.52 | 36.71 | 11.65 | 0.06 |
| Cohere Transcribe Arabic | open-weight | 29.53 | 38.52 | 19.75 | 0.03 |
What is in the test set
| Variety | العربية | Hours | Clips |
|---|---|---|---|
| MSA | الفصحى | 8.27 | 3,400 |
| Egyptian | المصرية | 3.37 | 1,508 |
| Emirati | الإماراتية | 2.50 | 1,187 |
| Saudi | السعودية | 1.67 | 916 |
| Kuwaiti | الكويتية | 0.84 | 423 |
| Qatari | القطرية | 0.83 | 396 |
| Lebanese | اللبنانية | 0.83 | 363 |
| Syrian | السورية | 0.83 | 361 |
| Omani | العُمانية | 0.81 | 371 |
| Total | 19.95 | 8,925 |
Quick start
from datasets import load_dataset

# accept the access terms on this page and log in (huggingface-cli login) first
ds = load_dataset("echonova-ai/arabic-dialect-asr-benchmark", split="test")
clip = ds[0]  # clip["audio"]["array"] is 16 kHz mono; clip["text"] is the reference
Score your system's transcripts (one {"id": ..., "prediction": ...} JSON object per line) with the benchmark's scorer:
pip install "arabic-asr-benchmark[hf] @ git+https://github.com/echonova-ai-solutions/arabic-asr-benchmark"
asr-bench evaluate --predictions predictions.jsonl --system my-system --output my-system.json
Files
data/test-0000k-of-00004.parquet: the test split, one row per clip, with the columnsid,audio(16 kHz, mono, FLAC),text(reference transcript),dialect,duration(seconds),recording_id(opaque source-recording label) andoriginal_sampling_rate.
Scoring
Hypotheses and references are normalized as described in Section 5.2 of the paper. Raw outputs of the systems compared in the paper are not part of this release.
Terms of use
Source and ownership
The audio was collected from publicly available recordings on the internet. EchoNova does not own the copyright to the audio. Copyright remains with the original owners.
Licence
Transcripts, segmentation and metadata: CC BY 4.0. Audio: provided as found, for research and evaluation only. No commercial use of the audio, no redistribution of the audio outside this dataset.
Prohibited uses
Voice cloning, speaker identification or re-identification, and any attempt to identify, contact or profile the people recorded.
Access terms (gated)
In these terms, "EchoNova" means EchoNova AI L.L.C-FZ (Meydan Free Zone, Dubai, United Arab Emirates; licence 2650442.01).
- You use the audio for research and evaluation only, under the terms above.
- EchoNova makes no representation or warranty about the dataset.
- You accept full responsibility for your use of the dataset and indemnify EchoNova against claims arising from it.
- EchoNova may remove clips or end your access at any time.
Removal requests
Content owners or people recorded can request removal of any clip by emailing legal@echonova.ai with the clip ID. Clips are removed within 7 days and the dataset is re-versioned.
Citation
@misc{khaled2026sadaasr,
  title  = {Sada-ASR: A Production Multidialectal Arabic Speech Recognition System},
  author = {Khaled, Mahmoud and Abd-Elnaser, Mohammed and Mohsen, Mahmoud},
  year   = {2026},
  note   = {EchoNova technical report},
  howpublished = {\url{https://echonova.ai/research/pdf/EchoNova_Sada-ASR_Technical_Report.pdf}}
}

@misc{mohsen2026echonova,
  title        = {EchoNova Arabic Dialect ASR Benchmark},
  author       = {Mohsen, Mahmoud},
  year         = {2026},
  howpublished = {\url{https://huggingface.co/datasets/echonova-ai/arabic-dialect-asr-benchmark}},
  note         = {EchoNova. Code and results: \url{https://github.com/echonova-ai-solutions/arabic-asr-benchmark}}
}
- Downloads last month
- 76