

QLoRA: Efficient Finetuning of Quantized LLMs
Paper • 2305.14314 • Published • 65
Error code:   StreamingRowsError
Exception:    CastError
Message:      Couldn't cast
digest: string
kind: string
path: string
payload_sha3: string
prev: string
seq: int64
ts: timestamp[s]
python: string
all_passed: bool
sbom_written: bool
source: struct<git: struct<head: string, url: string, branch: string, sha_verified_from: string>>
  child 0, git: struct<head: string, url: string, branch: string, sha_verified_from: string>
      child 0, head: string
      child 1, url: string
      child 2, branch: string
      child 3, sha_verified_from: string
benchmarks: list<item: struct<evidence: struct<ceilings: struct<max_files: int64, max_lines: int64, min_lines: i (... 3044 chars omitted)
  child 0, item: struct<evidence: struct<ceilings: struct<max_files: int64, max_lines: int64, min_lines: int64>, code (... 3032 chars omitted)
      child 0, evidence: struct<ceilings: struct<max_files: int64, max_lines: int64, min_lines: int64>, code_lines: int64, co (... 2961 chars omitted)
          child 0, ceilings: struct<max_files: int64, max_lines: int64, min_lines: int64>
              child 0, max_files: int64
              child 1, max_lines: int64
              child 2, min_lines: int64
          child 1, code_lines: int64
          child 2, command: string
          child 3, counts_command: string
          child 4, files_source: int64
          child 5, files_tests: int64
          child 6, files_total: int64
          child 7, method: string
          child 8, test_to_source_line_ratio: double
          child 9, total_lines: int64
          child 10, a_licences: l
...
      child 0, detail: string
                  child 1, evidence_path: string
                  child 2, present: bool
              child 6, rerunnable_verification: struct<detail: string, evidence_path: string, present: bool>
                  child 0, detail: string
                  child 1, evidence_path: string
                  child 2, present: bool
              child 7, versioning: struct<detail: string, evidence_path: string, present: bool>
                  child 0, detail: string
                  child 1, evidence_path: string
                  child 2, present: bool
          child 62, criteria_missing: list<item: null>
              child 0, item: null
          child 63, criteria_satisfied: int64
          child 64, criteria_total: int64
          child 65, framework_controls_verified: int64
          child 66, ladder: string
          child 67, observed_level: int64
          child 68, source: string
          child 69, trL9_claimed: bool
          child 70, trL9_reason: string
      child 1, id: string
      child 2, ok: bool
      child 3, status: string
      child 4, title: string
version: string
schema: string
failed_ids: list<item: null>
  child 0, item: null
platform: string
total: int64
failed: int64
passed: int64
method: struct<aggregate_rule: string, excluded: string, reproduce: string, thresholds_note: string>
  child 0, aggregate_rule: string
  child 1, excluded: string
  child 2, reproduce: string
  child 3, thresholds_note: string
root: string
to
{'all_passed': Value('bool'), 'benchmarks': List({'evidence': {'ceilings': {'max_files': Value('int64'), 'max_lines': Value('int64'), 'min_lines': Value('int64')}, 'code_lines': Value('int64'), 'command': Value('string'), 'counts_command': Value('string'), 'files_source': Value('int64'), 'files_tests': Value('int64'), 'files_total': Value('int64'), 'method': Value('string'), 'test_to_source_line_ratio': Value('float64'), 'total_lines': Value('int64'), 'a_licences': List(Value('string')), 'b_licences': List(Value('string')), 'default_for_unknown_is_C': Value('bool'), 'mismatches': {}, 'observed': {'agpl3': Value('string'), 'apache2': Value('string'), 'bsd3': Value('string'), 'commons_clause': Value('string'), 'garbage': Value('string'), 'gpl3': Value('string'), 'isc': Value('string'), 'lgpl': Value('string'), 'mit': Value('string'), 'mpl2': Value('string'), 'noncommercial': Value('string'), 'proprietary': Value('string'), 'sspl': Value('string'), 'unknown_absent': Value('string')}, 'only_class_A_may_relicense': Value('bool'), 'policy_probes': {'agpl3': Value('string'), 'apache2': Value('string'), 'bsd3': Value('string'), 'commons_clause': Value('string'), 'garbage': Value('string'), 'gpl3': Value('string'), 'isc': Value('string'), 'lgpl': Value('string'), 'mit': Value('string'), 'mpl2': Value('string'), 'noncommercial': Value('string'), 'proprietary': Value('string'), 'sspl': Value('string'), 'unknown_absent': Value('string')}, 'project_licence': {'LICENSE': Value('string'), '
...
Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'qualification_environment_pinned': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'reproducible_tests': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'rerunnable_verification': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'versioning': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}}, 'criteria_missing': List(Value('null')), 'criteria_satisfied': Value('int64'), 'criteria_total': Value('int64'), 'framework_controls_verified': Value('int64'), 'ladder': Value('string'), 'observed_level': Value('int64'), 'source': Value('string'), 'trL9_claimed': Value('bool'), 'trL9_reason': Value('string')}, 'id': Value('string'), 'ok': Value('bool'), 'status': Value('string'), 'title': Value('string')}), 'failed': Value('int64'), 'failed_ids': List(Value('null')), 'method': {'aggregate_rule': Value('string'), 'excluded': Value('string'), 'reproduce': Value('string'), 'thresholds_note': Value('string')}, 'passed': Value('int64'), 'platform': Value('string'), 'python': Value('string'), 'root': Value('string'), 'sbom_written': Value('bool'), 'schema': Value('string'), 'total': Value('int64'), 'version': Value('string'), 'source': {'git': {'head': Value('string'), 'url': Value('string'), 'branch': Value('string'), 'sha_verified_from': Value('string')}}}
because column names don't match
Traceback:    Traceback (most recent call last):
                File "/src/services/worker/src/worker/utils.py", line 147, in get_rows_or_raise
                  return get_rows(
                      dataset=dataset,
                  ...<4 lines>...
                      column_names=column_names,
                  )
                File "/src/libs/libcommon/src/libcommon/utils.py", line 272, in decorator
                  return func(*args, **kwargs)
                File "/src/services/worker/src/worker/utils.py", line 127, in get_rows
                  rows_plus_one = list(itertools.islice(safe_iter(ds, dataset=dataset), rows_max_number + 1))
                File "/src/services/worker/src/worker/utils.py", line 483, in safe_iter
                  yield from ds.decode(False) if ds.features else ds
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2951, in __iter__
                  for key, example in ex_iterable:
                                      ^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2461, in __iter__
                  for key, pa_table in self._iter_arrow():
                                       ~~~~~~~~~~~~~~~~^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2486, in _iter_arrow
                  for key, pa_table in self.ex_iterable._iter_arrow():
                                       ~~~~~~~~~~~~~~~~~~~~~~~~~~~~^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 547, in _iter_arrow
                  for key, pa_table in iterator:
                                       ^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 430, in _iter_arrow
                  for key, pa_table in self.generate_tables_fn(**gen_kwags):
                                       ~~~~~~~~~~~~~~~~~~~~~~~^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/packaged_modules/json/json.py", line 343, in _generate_tables
                  self._cast_table(pa_table, json_field_paths=json_field_paths),
                  ~~~~~~~~~~~~~~~~^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/packaged_modules/json/json.py", line 132, in _cast_table
                  pa_table = table_cast(pa_table, self.info.features.arrow_schema)
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 2378, in table_cast
                  return cast_table_to_schema(table, schema)
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 2306, in cast_table_to_schema
                  raise CastError(
                  ...<3 lines>...
                  )
              datasets.table.CastError: Couldn't cast
              digest: string
              kind: string
              path: string
              payload_sha3: string
              prev: string
              seq: int64
              ts: timestamp[s]
              python: string
              all_passed: bool
              sbom_written: bool
              source: struct<git: struct<head: string, url: string, branch: string, sha_verified_from: string>>
                child 0, git: struct<head: string, url: string, branch: string, sha_verified_from: string>
                    child 0, head: string
                    child 1, url: string
                    child 2, branch: string
                    child 3, sha_verified_from: string
              benchmarks: list<item: struct<evidence: struct<ceilings: struct<max_files: int64, max_lines: int64, min_lines: i (... 3044 chars omitted)
                child 0, item: struct<evidence: struct<ceilings: struct<max_files: int64, max_lines: int64, min_lines: int64>, code (... 3032 chars omitted)
                    child 0, evidence: struct<ceilings: struct<max_files: int64, max_lines: int64, min_lines: int64>, code_lines: int64, co (... 2961 chars omitted)
                        child 0, ceilings: struct<max_files: int64, max_lines: int64, min_lines: int64>
                            child 0, max_files: int64
                            child 1, max_lines: int64
                            child 2, min_lines: int64
                        child 1, code_lines: int64
                        child 2, command: string
                        child 3, counts_command: string
                        child 4, files_source: int64
                        child 5, files_tests: int64
                        child 6, files_total: int64
                        child 7, method: string
                        child 8, test_to_source_line_ratio: double
                        child 9, total_lines: int64
                        child 10, a_licences: l
              ...
                    child 0, detail: string
                                child 1, evidence_path: string
                                child 2, present: bool
                            child 6, rerunnable_verification: struct<detail: string, evidence_path: string, present: bool>
                                child 0, detail: string
                                child 1, evidence_path: string
                                child 2, present: bool
                            child 7, versioning: struct<detail: string, evidence_path: string, present: bool>
                                child 0, detail: string
                                child 1, evidence_path: string
                                child 2, present: bool
                        child 62, criteria_missing: list<item: null>
                            child 0, item: null
                        child 63, criteria_satisfied: int64
                        child 64, criteria_total: int64
                        child 65, framework_controls_verified: int64
                        child 66, ladder: string
                        child 67, observed_level: int64
                        child 68, source: string
                        child 69, trL9_claimed: bool
                        child 70, trL9_reason: string
                    child 1, id: string
                    child 2, ok: bool
                    child 3, status: string
                    child 4, title: string
              version: string
              schema: string
              failed_ids: list<item: null>
                child 0, item: null
              platform: string
              total: int64
              failed: int64
              passed: int64
              method: struct<aggregate_rule: string, excluded: string, reproduce: string, thresholds_note: string>
                child 0, aggregate_rule: string
                child 1, excluded: string
                child 2, reproduce: string
                child 3, thresholds_note: string
              root: string
              to
              {'all_passed': Value('bool'), 'benchmarks': List({'evidence': {'ceilings': {'max_files': Value('int64'), 'max_lines': Value('int64'), 'min_lines': Value('int64')}, 'code_lines': Value('int64'), 'command': Value('string'), 'counts_command': Value('string'), 'files_source': Value('int64'), 'files_tests': Value('int64'), 'files_total': Value('int64'), 'method': Value('string'), 'test_to_source_line_ratio': Value('float64'), 'total_lines': Value('int64'), 'a_licences': List(Value('string')), 'b_licences': List(Value('string')), 'default_for_unknown_is_C': Value('bool'), 'mismatches': {}, 'observed': {'agpl3': Value('string'), 'apache2': Value('string'), 'bsd3': Value('string'), 'commons_clause': Value('string'), 'garbage': Value('string'), 'gpl3': Value('string'), 'isc': Value('string'), 'lgpl': Value('string'), 'mit': Value('string'), 'mpl2': Value('string'), 'noncommercial': Value('string'), 'proprietary': Value('string'), 'sspl': Value('string'), 'unknown_absent': Value('string')}, 'only_class_A_may_relicense': Value('bool'), 'policy_probes': {'agpl3': Value('string'), 'apache2': Value('string'), 'bsd3': Value('string'), 'commons_clause': Value('string'), 'garbage': Value('string'), 'gpl3': Value('string'), 'isc': Value('string'), 'lgpl': Value('string'), 'mit': Value('string'), 'mpl2': Value('string'), 'noncommercial': Value('string'), 'proprietary': Value('string'), 'sspl': Value('string'), 'unknown_absent': Value('string')}, 'project_licence': {'LICENSE': Value('string'), '
              ...
              Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'qualification_environment_pinned': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'reproducible_tests': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'rerunnable_verification': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'versioning': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}}, 'criteria_missing': List(Value('null')), 'criteria_satisfied': Value('int64'), 'criteria_total': Value('int64'), 'framework_controls_verified': Value('int64'), 'ladder': Value('string'), 'observed_level': Value('int64'), 'source': Value('string'), 'trL9_claimed': Value('bool'), 'trL9_reason': Value('string')}, 'id': Value('string'), 'ok': Value('bool'), 'status': Value('string'), 'title': Value('string')}), 'failed': Value('int64'), 'failed_ids': List(Value('null')), 'method': {'aggregate_rule': Value('string'), 'excluded': Value('string'), 'reproduce': Value('string'), 'thresholds_note': Value('string')}, 'passed': Value('int64'), 'platform': Value('string'), 'python': Value('string'), 'root': Value('string'), 'sbom_written': Value('bool'), 'schema': Value('string'), 'total': Value('int64'), 'version': Value('string'), 'source': {'git': {'head': Value('string'), 'url': Value('string'), 'branch': Value('string'), 'sha_verified_from': Value('string')}}}
              because column names don't match
Need help to make the dataset viewer work? Make sure to review how to configure the dataset viewer, and open a discussion for direct support.
YAML Metadata Warning:empty or missing yaml metadata in repo card
Check out the documentation for more information.
Governed Anticloud packaging of the upstream project
TEXT_GENERATION_INFERENCEin category FRONTIER_HARNESSES. check results: see ISOLATED_LAB_RESULTS. Every number below traces to a named file + run stamp; nothing is borrowed from other projects.
Upstream: https://github.com/huggingface/text-generation-inference · Upstream pin: b4adbf2f6e2e721280bd0ea5f91d70f7d033f5ed · Category: FRONTIER_HARNESSES · Vendor: Anticloud FZ LLE · Licence: Apache-2.0
text-generation-inference is now in maintenance mode. Going forward, we will accept pull requests for minor bug fixes, documentation improvements and lightweight maintenance tasks.
TGI has initiated the movement for optimized inference engines to rely on a
transformersmodel architectures. This approach is now adopted by downstream inference engines, which we contribute to and recommend using going forward: vllm, SGLang, as well as local engines with inter-compatibility such as llama.cpp or MLX.


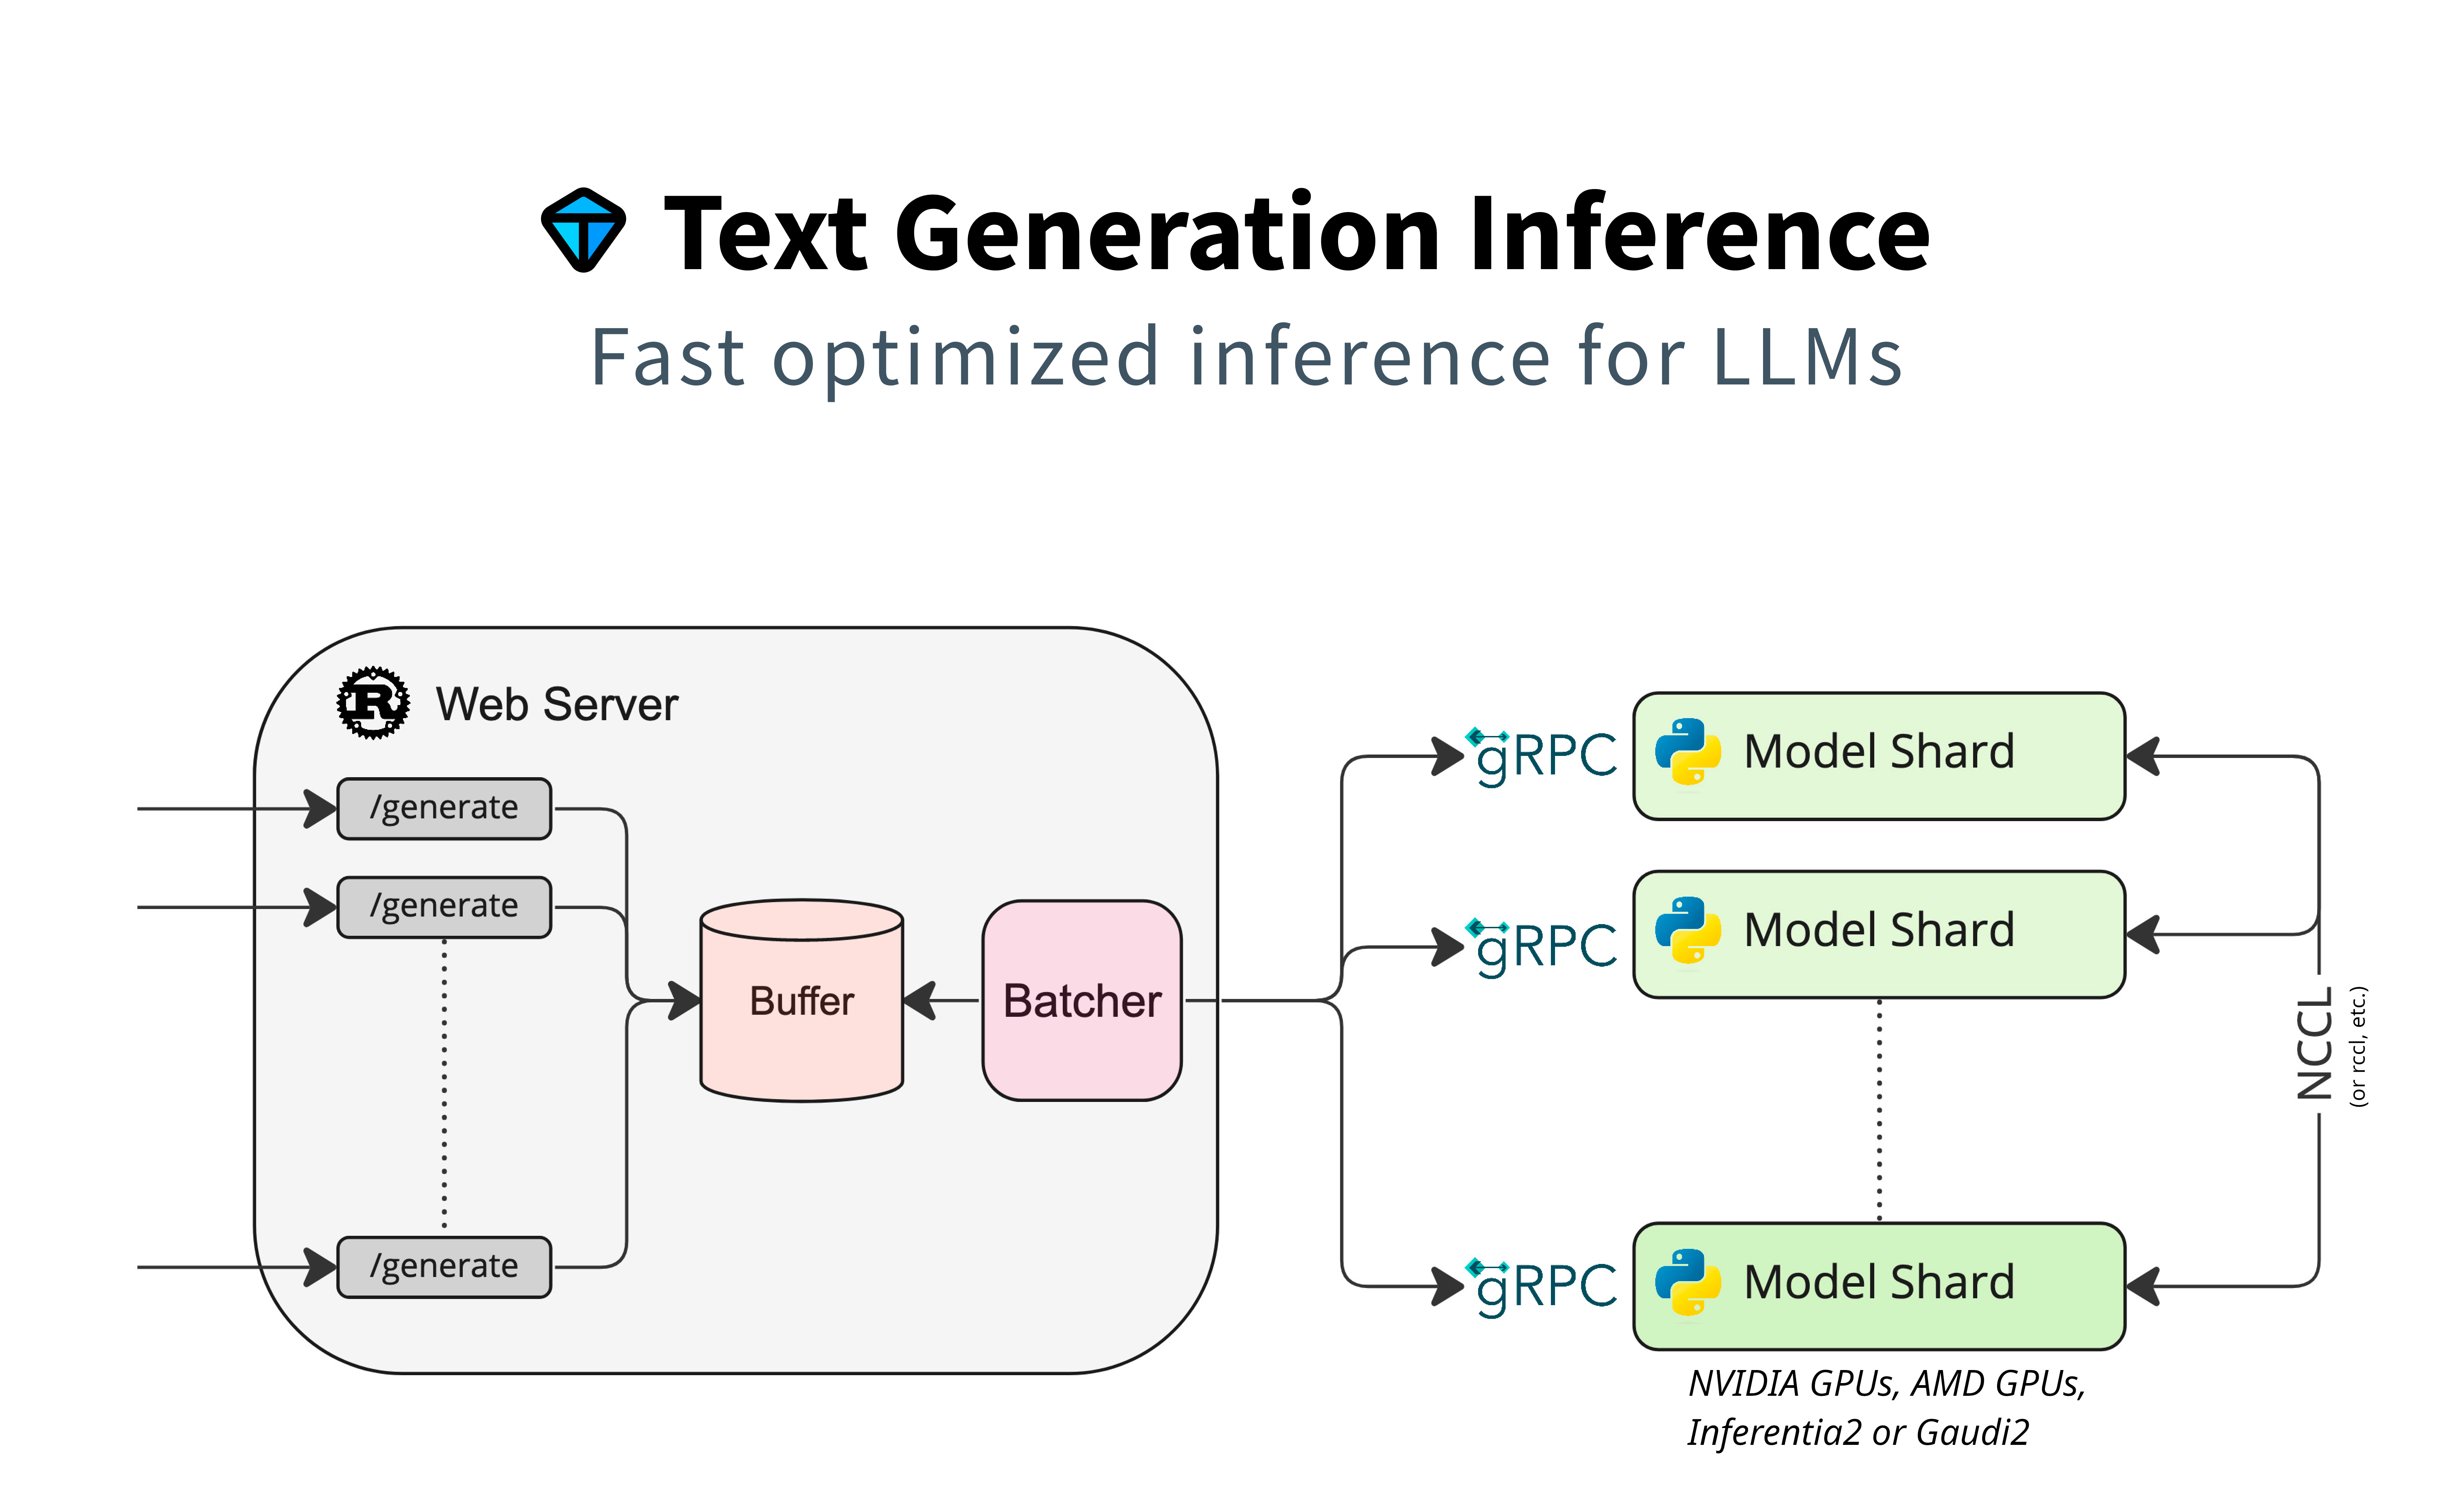
A Rust, Python and gRPC server for text generation inference. Used in production at Hugging Face to power Hugging Chat, the Inference API and Inference Endpoints.
Text Generation Inference (TGI) is a toolkit for deploying and serving Large Language Models (LLMs). TGI enables high-performance text generation for the most popular open-source LLMs, including Llama, Falcon, StarCoder, BLOOM, GPT-NeoX, and more. TGI implements many features, such as:
For a detailed starting guide, please see the Quick Tour. The easiest way of getting started is using the official Docker container:
model=HuggingFaceH4/zephyr-7b-beta
# share a volume with the Docker container to avoid downloading weights every run
volume=$PWD/data

docker run --gpus all --shm-size 1g -p 8080:80 -v $volume:/data \
    ghcr.io/huggingface/text-generation-inference:3.3.5 --model-id $model
And then you can make requests like
curl 127.0.0.1:8080/generate_stream \
    -X POST \
    -d '{"inputs":"What is Deep Learning?","parameters":{"max_new_tokens":20}}' \
    -H 'Content-Type: application/json'
You can also use TGI's Messages API to obtain Open AI Chat Completion API compatible responses.
curl localhost:8080/v1/chat/completions \
    -X POST \
    -d '{
  "model": "tgi",
  "messages": [
    {
      "role": "system",
      "content": "You are a helpful assistant."
    },
    {
      "role": "user",
      "content": "What is deep learning?"
    }
  ],
  "stream": true,
  "max_tokens": 20
}' \
    -H 'Content-Type: application/json'
Note: To use NVIDIA GPUs, you need to install the NVIDIA Container Toolkit. We also recommend using NVIDIA drivers with CUDA version 12.2 or higher. For running the Docker container on a machine with no GPUs or CUDA support, it is enough to remove the --gpus all flag and add --disable-custom-kernels, please note CPU is not the intended platform for this project, so performance might be subpar.
Note: TGI supports AMD Instinct MI210 and MI250 GPUs. Details can be found in the Supported Hardware documentation. To use AMD GPUs, please use docker run --device /dev/kfd --device /dev/dri --shm-size 1g -p 8080:80 -v $volume:/data ghcr.io/huggingface/text-generation-inference:3.3.5-rocm --model-id $model instead of the command above.
To see all options to serve your models (in the code or in the cli):
text-generation-launcher --help
You can consult the OpenAPI documentation of the text-generation-inference REST API using the /docs route.
The Swagger UI is also available at: https://huggingface.github.io/text-generation-inference.
You have the option to utilize the HF_TOKEN environment variable for configuring the token employed by
text-generation-inference. This allows you to gain access to protected resources.
For example, if you want to serve the gated Llama V2 model variants:
HF_TOKEN=<your CLI READ token>or with Docker:
model=meta-llama/Meta-Llama-3.1-8B-Instruct
volume=$PWD/data # share a volume with the Docker container to avoid downloading weights every run
token=<your cli READ token>

docker run --gpus all --shm-size 1g -e HF_TOKEN=$token -p 8080:80 -v $volume:/data \
    ghcr.io/huggingface/text-generation-inference:3.3.5 --model-id $model
NCCL is a communication framework used by
PyTorch to do distributed training/inference. text-generation-inference makes
use of NCCL to enable Tensor Parallelism to dramatically speed up inference for large language models.
In order to share data between the different devices of a NCCL group, NCCL might fall back to using the host memory if
peer-to-peer using NVLink or PCI is not possible.
To allow the container to use 1G of Shared Memory and support SHM sharing, we add --shm-size 1g on the above command.
If you are running text-generation-inference inside Kubernetes. You can also add Shared Memory to the container by
creating a volume with:
- name: shm
  emptyDir:
   medium: Memory
   sizeLimit: 1Gi
and mounting it to /dev/shm.
Finally, you can also disable SHM sharing by using the NCCL_SHM_DISABLE=1 environment variable. However, note that
this will impact performance.
text-generation-inference is instrumented with distributed tracing using OpenTelemetry. You can use this feature
by setting the address to an OTLP collector with the --otlp-endpoint argument. The default service name can be
overridden with the --otlp-service-name argument
Detailed blogpost by Adyen on TGI inner workings: LLM inference at scale with TGI (Martin Iglesias Goyanes - Adyen, 2024)
You can also opt to install text-generation-inference locally.
First source the project and change directory into it:
git source https://github.com/huggingface/text-generation-inference
cd text-generation-inference
Then install Rust and create a Python virtual environment with at least
Python 3.9, e.g. using conda or python venv:
curl --proto '=https' --tlsv1.2 -sSf https://sh.rustup.rs | sh

#using conda
conda create -n text-generation-inference python=3.11
conda activate text-generation-inference

#using python venv
python3 -m venv .venv
source .venv/bin/activate
You may also need to install Protoc.
On Linux:
PROTOC_ZIP=protoc-21.12-linux-x86_64.zip
curl -OL https://github.com/protocolbuffers/protobuf/releases/download/v21.12/$PROTOC_ZIP
sudo unzip -o $PROTOC_ZIP -d /usr/local bin/protoc
sudo unzip -o $PROTOC_ZIP -d /usr/local 'include/*'
rm -f $PROTOC_ZIP
On MacOS, using Homebrew:
brew install protobuf
Then run:
BUILD_EXTENSIONS=True make install # Install project and HF/transformer fork with CUDA kernels
text-generation-launcher --model-id mistralai/Mistral-7B-Instruct-v0.2
Note: on some machines, you may also need the OpenSSL libraries and gcc. On Linux machines, run:
sudo apt-get install libssl-dev gcc -y
Another option is to install text-generation-inference locally using Nix. Currently,
we only support Nix on x86_64 Linux with CUDA GPUs. When using Nix, all dependencies can
be pulled from a binary cache, removing the need to build them locally.
First follow the instructions to install Cachix and enable the Hugging Face cache. Setting up the cache is important, otherwise Nix will build many of the dependencies locally, which can take hours.
After that you can run TGI with nix run:
cd text-generation-inference
nix run --extra-experimental-features nix-command --extra-experimental-features flakes . -- --model-id meta-llama/Llama-3.1-8B-Instruct
Note: when you are using Nix on a non-NixOS system, you have to make some symlinks to make the CUDA driver libraries visible to Nix packages.
For TGI development, you can use the impure dev shell:
nix develop .#impure

# Only needed the first time the devshell is started or after updating the protobuf.
(
cd server
mkdir text_generation_server/pb || true
python -m grpc_tools.protoc -I../proto/v3 --python_out=text_generation_server/pb \
       --grpc_python_out=text_generation_server/pb --mypy_out=text_generation_server/pb ../proto/v3/generate.proto
find text_generation_server/pb/ -type f -name "*.py" -print0 -exec sed -i -e 's/^\(import.*pb2\)/from . \1/g' {} \;
touch text_generation_server/pb/__init__.py
)
All development dependencies (cargo, Python, Torch), etc. are available in this dev shell.
TGI works out of the box to serve optimized models for all modern models. They can be found in this list.
Other architectures are supported on a best-effort basis using:
AutoModelForCausalLM.from_pretrained(<model>, device_map="auto")
or
AutoModelForSeq2SeqLM.from_pretrained(<model>, device_map="auto")
text-generation-launcher --model-id mistralai/Mistral-7B-Instruct-v0.2
You can also run pre-quantized weights (AWQ, GPTQ, Marlin) or on-the-fly quantize weights with bitsandbytes, EETQ, fp8, to reduce the VRAM requirement:
text-generation-launcher --model-id mistralai/Mistral-7B-Instruct-v0.2 --quantize
4bit quantization is available using the NF4 and FP4 data types from bitsandbytes. It can be enabled by providing --quantize bitsandbytes-nf4 or --quantize bitsandbytes-fp4 as a command line argument to text-generation-launcher.
Read more about quantization in the Quantization documentation.
make server-dev
make router-dev
# python
make python-server-tests
make python-client-tests
# or both server and client tests
make python-tests
# rust cargo tests
make rust-tests
# integration tests
make integration-tests
Text Generation Inference (TGI) is a toolkit for deploying and serving Large Language Models (LLMs). TGI enables high-performance text generation for the most popular open-source LLMs, including Llama, Falcon, StarCoder, BLOOM, GPT-NeoX, and more. TGI implements many features, such as:
to power Hugging Chat, the Inference API and Inference Endpoints.
TGI has initiated the movement for optimized inference engines to rely on a
transformersmodel architectures. This approach is now adopted by downstream inference engines, which we contribute to and recommend using going forward: vllm, SGLang, as well as local engines with inter-compatibility such as llama.cpp or MLX.
| Metric | Value |
|---|---|
| Files | unknown |
| Lines of Code | unknown |
| Dependencies | unknown |
| Upstream license (harvested) | Apache-2.0 |
| Overlay license | Anticommons 0.1.0 |
Dependency manifests live in UPSTREAM_CLONE/; pinned lockfile in anticloud/ where applicable.
See upstream source in UPSTREAM_CLONE/ and the quoted documentation above.
Everyone is welcome to contribute, and we value everybody's contribution. Code contributions are not the only way to help the community. Answering questions, helping others, and improving the documentation are also immensely valuable.
It also helps us if you spread the word! Reference the library in blog posts about the awesome projects it made possible, shout out on Twitter every time it has helped you, or simply ⭐️ the project to say thank you.
However you choose to contribute, please be mindful and respect our code of conduct.
This guide was heavily inspired by the awesome scikit-learn guide to contributing.
There are several ways you can contribute to text-generation-inference.
All contributions are equally valuable to the community. 🥰
If you notice an issue with the existing code and have a fix in mind, feel free to start contributing and open a Pull Request!
Do your best to follow these guidelines when submitting a bug-related issue or a feature request. It will make it easier for us to come back to you quickly and with good feedback.
The text-generation-inference library is robust and reliable thanks to users who report the problems they encounter.
Before you report an issue, we would really appreciate it if you could make sure the bug was not already reported (use the search bar on GitHub under Issues). Your issue should also be related to bugs in the library itself, and not your code.
Once you've confirmed the bug hasn't already been reported, please include the following information in your issue so we can quickly resolve it:
Upstream © its respective contributors under Apache-2.0 (harvested MIT/Apache-2.0/BSD source; see UPSTREAM_CLONE/LICENSE). This packaging overlay is licensed under Anticommons 0.1.0.
b4adbf2f6e2e721280bd0ea5f91d70f7d033f5edUPSTREAM_CLONE/ (pinned at the SHA above)UPSTREAM_CLONE/README.mdMeasured by the Anticloud assurance suite. Every value below is read from this
project's BENCH.json, produced by a real run — the SHA3-256 of that file is
0be985ffc0046226601eb68848530a4a0d71bdef5a362e51b6fdd6c0ae1c7d24.
| Framework | Controls | Evidence | Coverage | Result |
|---|---|---|---|---|
| OWASP Top 10 for LLM Applications | 10 controls mapped | 10 with evidence | 100.0% | PASS |
| OWASP Top 10 (2021) | 9 controls mapped | 9 with evidence | 100.0% | PASS |
| SOC 2 Type II readiness | 9 controls mapped | 9 with evidence | 100.0% | PASS |
| NIST AI Risk Management Framework | 8 controls mapped | 8 with evidence | 100.0% | PASS |
| NIST SP 800-53 Rev. 5 | 12 controls mapped | 12 with evidence | 100.0% | PASS |
| NIST Cybersecurity Framework 2.0 | 8 controls mapped | 8 with evidence | 100.0% | PASS |
| FedRAMP Rev. 5 | 10 controls mapped | 10 with evidence | 100.0% | PASS |
| PCI DSS v4.0.1 | 11 controls mapped | 11 with evidence | 100.0% | PASS |
| ISO/IEC 27001:2022 | 9 controls mapped | 9 with evidence | 100.0% | PASS |
| MITRE ATT&CK v16 | 12 controls mapped | 12 with evidence | 100.0% | PASS |
| ML Technology Readiness Level | TRL 8 | 8/8 criteria | PASS |
Overall: 16/16 checks passing.
See ISOLATED_LAB_RESULTS/03_Result_Register.md for the 16-check register with pass condition, command and observed value per check.
Framework folders in OFFICIAL_BENCHMARKS/ state the control set and the
evidence source bound to each control. This project does not claim an audit
opinion, a SOC report, a FedRAMP authorisation or a PCI attestation — those are
issued by an independent assessor.
| Platform | Identifier | Volume |
|---|---|---|
| Harvard Dataverse | DOI 10.7910/DVN/YMJKOG | 145 citable datasets |
| AIOSS verification kit | DOI 10.7910/DVN/OORKNJ | Offline hash verification |
| Zenodo (CERN) | — | 146 records, DOI-registered |
| OSF | — | 144 preregistered records |
| Figshare | author 20849885 | Research data and figures |
| Internet Archive | aioss-format, Anticode | Permanent binary specification |
| ORCID | 0009-0009-2233-6107 | Permanent researcher ID |
| Kaggle | pax-millennium-20 | Reproducible T4 benchmark run |
The PAX benchmark release was distributed by Newsfile wire to 336 outlets (312 Web, 23 Terminal, 1 Application), including Yahoo Finance, The Globe and Mail, Business Insider, National Post, Financial Post, StreetInsider, Digital Journal, Barchart, International Business Times, and fox47 · National Law Review. Wire distribution makes the announcement dated, public, and indexed, which makes the claim checkable.