

DistilBERT Fine-Tuned for Named Entity Recognition (NER)
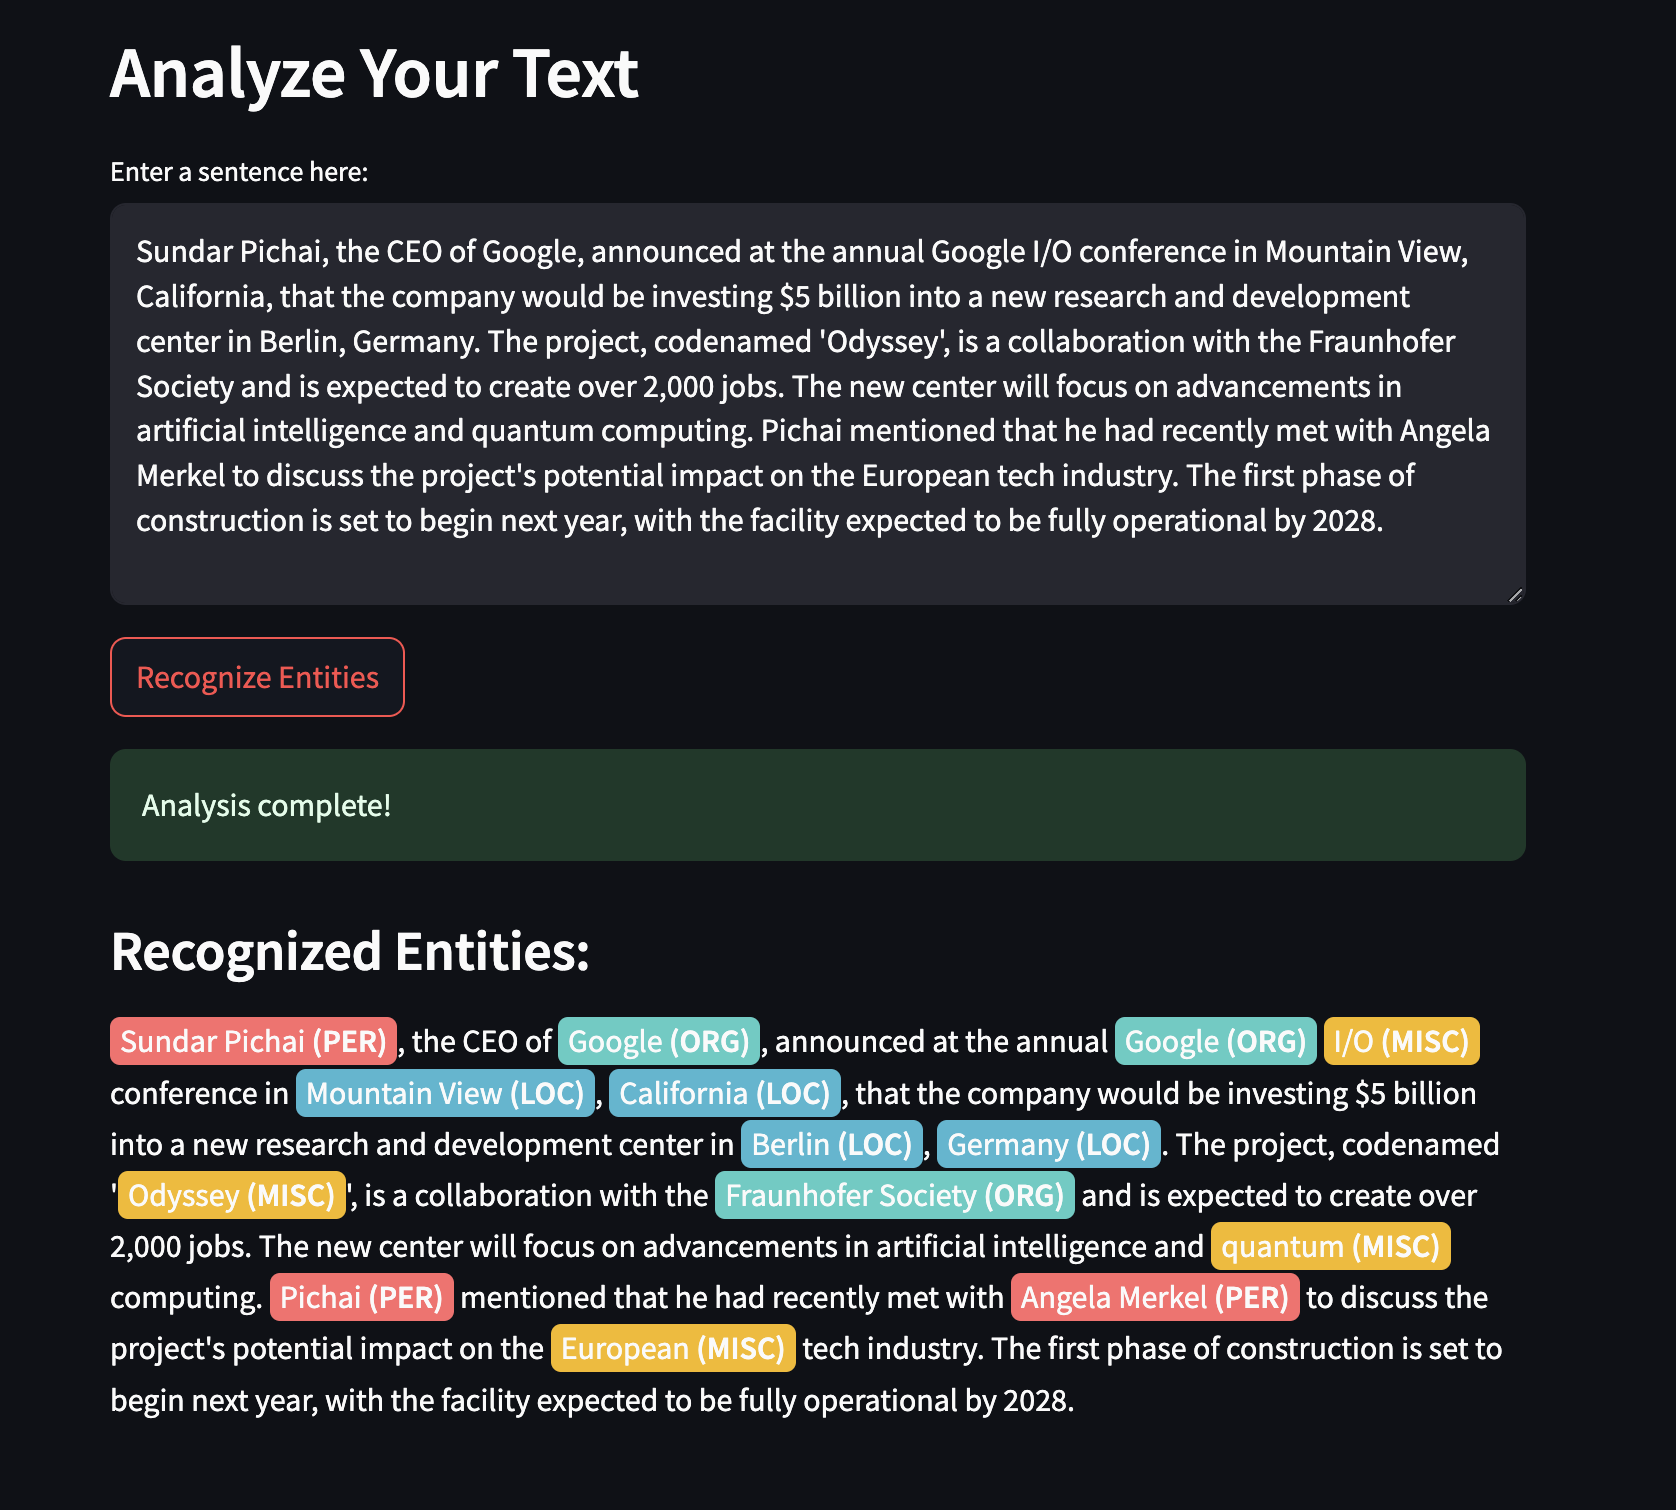
This is a distilbert-base-uncased model fine-tuned on the CoNLL-2023 dataset for the Named Entity Recognition (NER) task. It achieves a 94% F1-score on the validation set, demonstrating high accuracy in identifying persons, organizations, locations, and miscellaneous entities in text.
This model is lightweight (66M parameters), making it fast and efficient for production environments while maintaining high performance.
Model Description
- Model type: DistilBERT (a distilled version of BERT)
- Language: English
- Task: Named Entity Recognition (Token Classification)
- Fine-tuned on: CoNLL-2003
- Resources: The training was conducted on a standard consumer-grade GPU.
Intended Uses & Limitations
You can use this model to extract named entities from text. It is particularly effective for news articles and other formal text, similar to the CoNLL-2003 dataset.
How to Use
The model can be easily loaded from the Hub using the transformers library.
from transformers import pipeline

# Load the NER pipeline
ner_pipeline = pipeline("ner", model="your-username/your-repo-name") # Replace with your repo name

# Example text
text = "Sundar Pichai, the CEO of Google, announced a new project in Berlin."

# Get predictions
entities = ner_pipeline(text)
print(entities)
# Expected Output:
# [
#   {'entity_group': 'PER', 'score': ..., 'word': 'Sundar Pichai', 'start': 0, 'end': 13},
#   {'entity_group': 'ORG', 'score': ..., 'word': 'Google', 'start': 25, 'end': 31},
#   {'entity_group': 'LOC', 'score': ..., 'word': 'Berlin', 'start': 65, 'end': 71}
# ]
Training Procedure
The model was trained using the transformers library on a single GPU.
Hyperparameters
- Learning Rate: 2e-5
- Batch Size: 16
- Epochs: 3
- Optimizer: AdamW with weight decay of 0.01
Evaluation Results
The model achieved the following performance on the CoNLL-2003 validation set:
| Metric | Score |
|---|---|
| F1 | 0.9382 |
| Precision | 0.9345 |
| Recall | 0.9419 |
Citation
If you use this model in your work, please consider citing the original DistilBERT paper:
@inproceedings{sanh2019distilbert,
  title={DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter},
  author={Sanh, Victor and Debut, Lysandre and Chaumond, Julien and Wolf, Thomas},
  booktitle={Proceedings of the 5th Workshop on Energy Efficient Machine Learning and Cognitive Computing},
  year={2019}
}
- Downloads last month
- 6
Dataset used to train alexu8007/NER_BERT
Evaluation results
- F1 on conll2003validation set self-reported0.938
- Precision on conll2003validation set self-reported0.934
- Recall on conll2003validation set self-reported0.942
- Accuracy on conll2003validation set self-reported0.938