

SimVTA: Simulation-Grounded Video-Trajectory Alignment for Driving World Action Models
Paper • 2610.13781 • Published • 28

Changhui Jing, Haochen Tian, Hongchen Li, Tianyu Li, Caojun Wang, Zihao Zhang, Yanhao Liu, Chengen Xie, Bailin Li, Hao Zhao, Zhenjie Yang
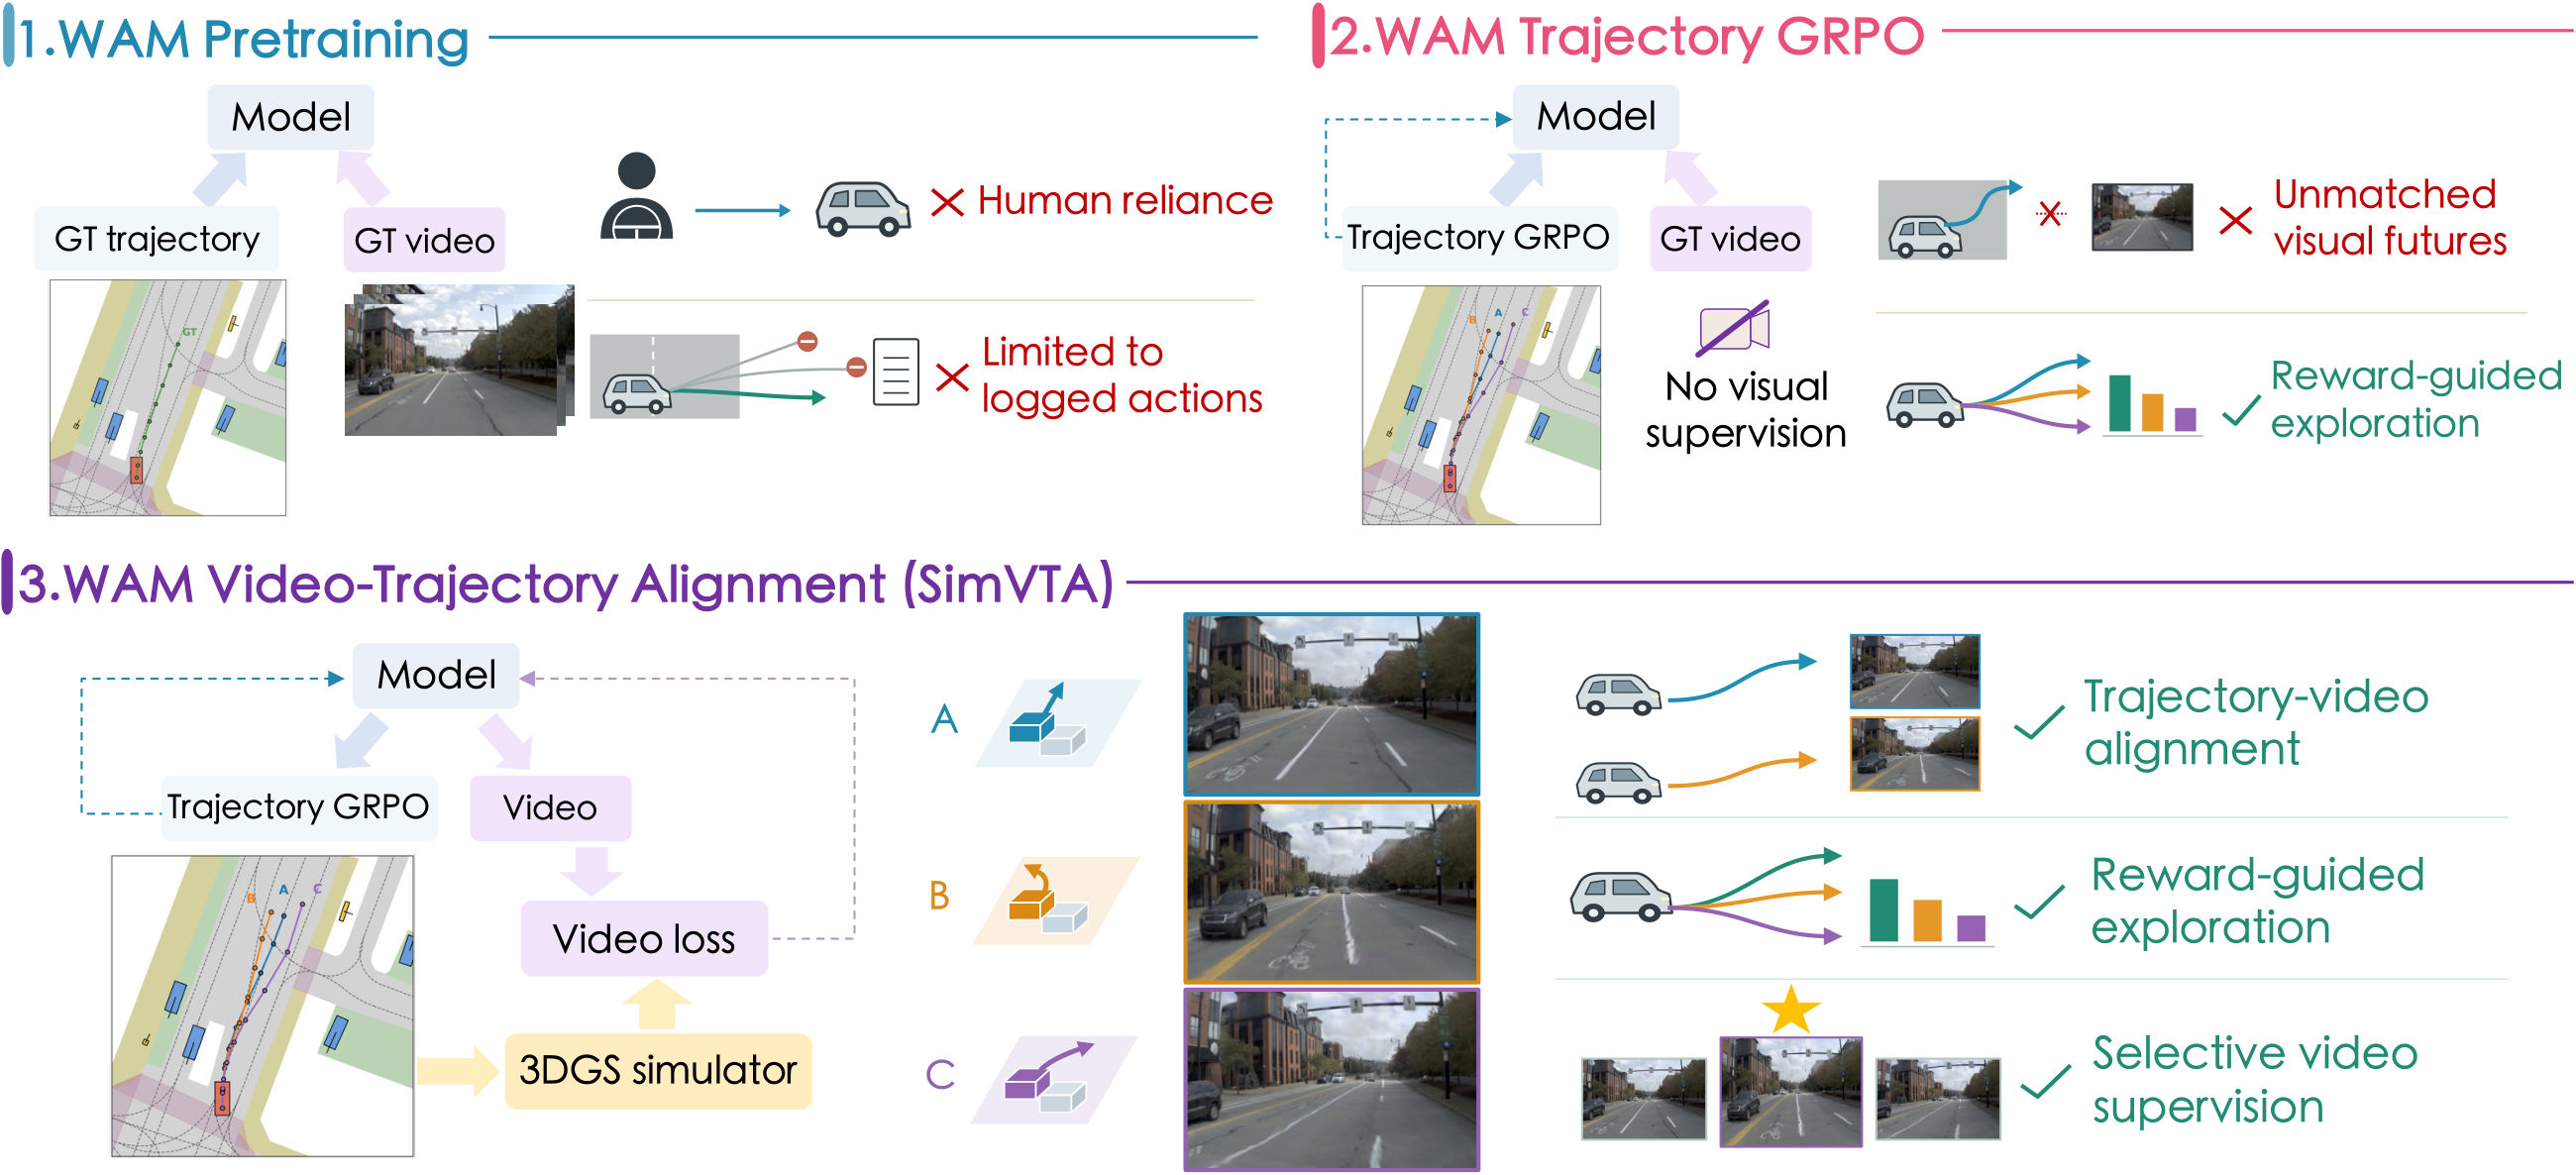
SimVTA is a simulation-grounded post-training framework for driving world action models. It extends supervision beyond logged trajectories using a 3D Gaussian Splatting simulator, combining trajectory GRPO with a flow-matching video loss that updates shared representations.
Reported results in the paper:
| Benchmark | Metric | SimVTA |
|---|---|---|
| NAVSIM v1 | PDMS | 91.3 (+5.1 over the 86.2 initialization) |
| NAVSIM v2 | EPDMS | 88.2 |
| HUGSIM | Average HD-Score | 38.8 |
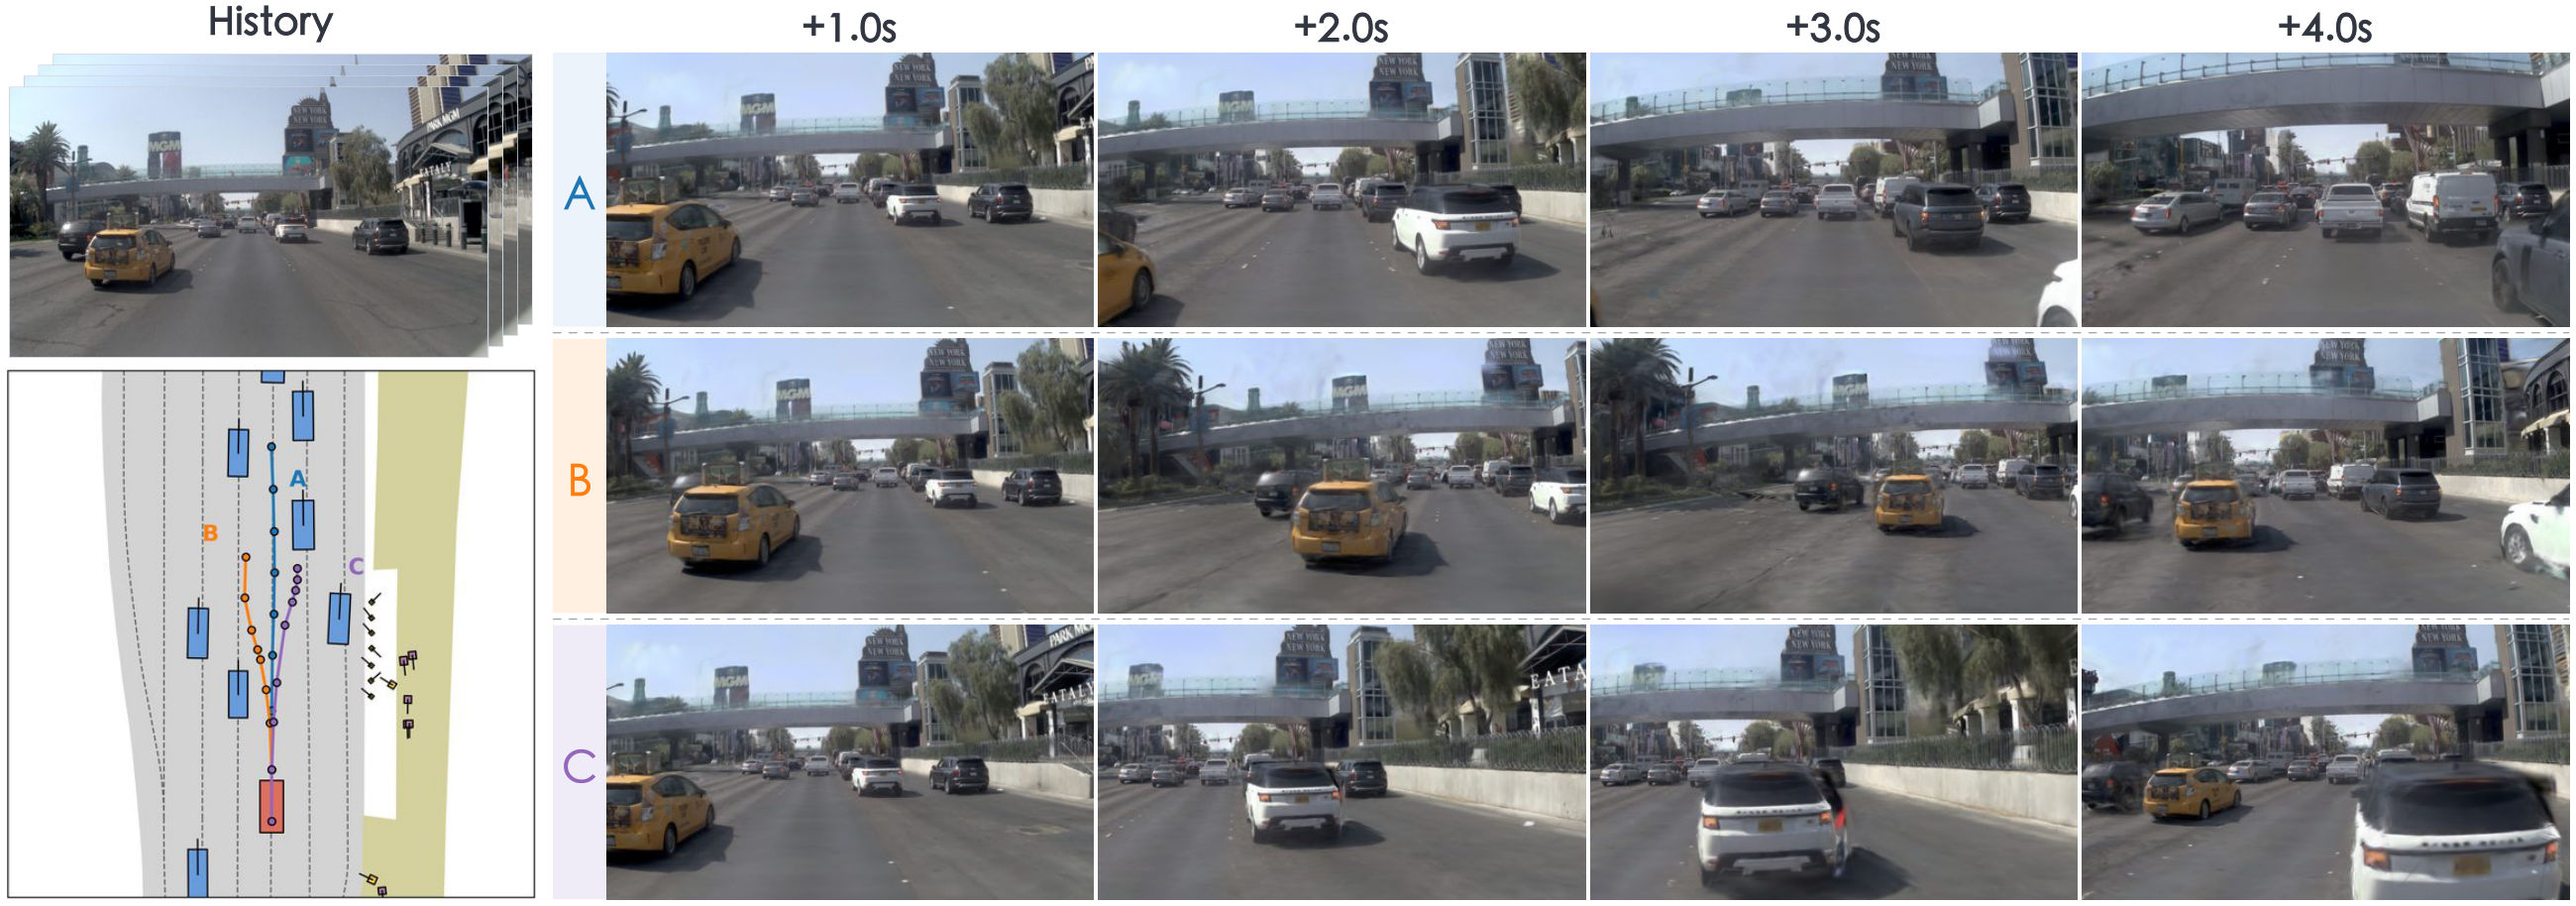
Simulator-rendered futures for going straight (A), changing lanes left (B), and changing lanes right (C).
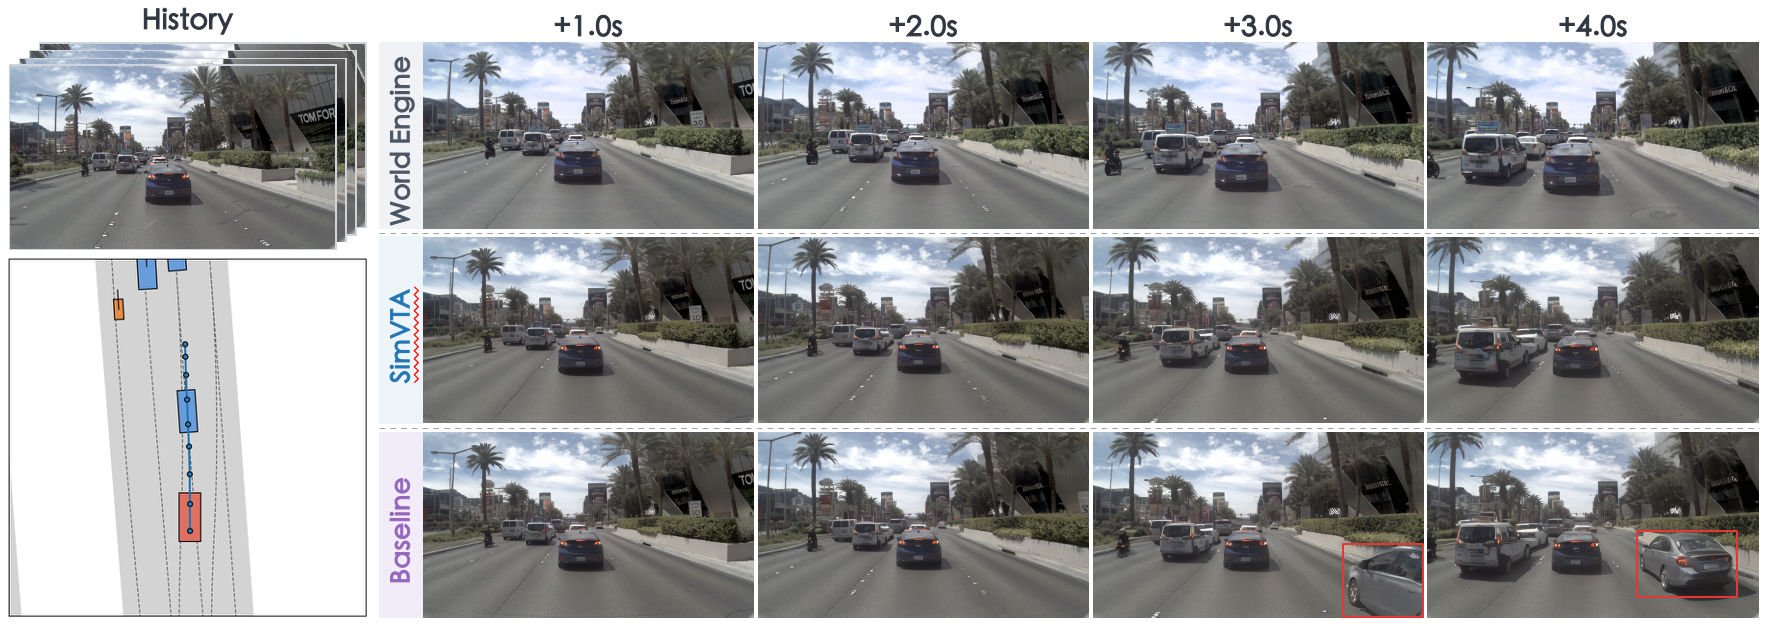
Video-trajectory alignment: World Engine renderings compared with SimVTA and Epona predictions.
This repository provides simvta.pkl, the SimVTA checkpoint post-trained from a NAVSIM-adapted Epona initialization.
pip install -U huggingface_hub
hf download OpenDriveLab-org/SimVTA simvta.pkl --local-dir ./ckpts
The checkpoint will be saved to ./ckpts/simvta.pkl. Code and detailed inference instructions are being prepared for release in the GitHub repository. Additional pretrained components and dataset preparation will be documented there.
We thank the authors and open-source contributors of the following projects for providing the models, simulation tools, and evaluation benchmarks that support this work:
We also thank the broader open-source community for its contributions to driving world models, autonomous driving, and 3D Gaussian Splatting.
The SimVTA release is licensed under Apache-2.0, subject to the retained upstream MIT notice for Epona in THIRD_PARTY_NOTICES.md.
If our paper or checkpoint helps your research, please consider citing our work and giving the GitHub repository a star.
Base model
Kevin-thu/Epona