Instructions to use NovelAI/clio-v1-legacy with libraries, inference providers, notebooks, and local apps. Follow these links to get started.
- Libraries
- Transformers
How to use NovelAI/clio-v1-legacy with Transformers:
# Use a pipeline as a high-level helper from transformers import pipeline pipe = pipeline("text-generation", model="NovelAI/clio-v1-legacy")# Load model directly from transformers import AutoTokenizer, AutoModelForCausalLM tokenizer = AutoTokenizer.from_pretrained("NovelAI/clio-v1-legacy") model = AutoModelForCausalLM.from_pretrained("NovelAI/clio-v1-legacy", device_map="auto") - Notebooks
- Google Colab
- Kaggle
- Local Apps Settings
- llama.cpp
How to use NovelAI/clio-v1-legacy with llama.cpp:
Install (macOS, Linux)
curl -LsSf https://llama.app/install.sh | sh # Start a local OpenAI-compatible server with a web UI: llama serve -hf NovelAI/clio-v1-legacy:Q4_K_M # Run inference directly in the terminal: llama cli -hf NovelAI/clio-v1-legacy:Q4_K_M
Install from WinGet (Windows)
winget install llama.cpp # Start a local OpenAI-compatible server with a web UI: llama serve -hf NovelAI/clio-v1-legacy:Q4_K_M # Run inference directly in the terminal: llama cli -hf NovelAI/clio-v1-legacy:Q4_K_M
Use pre-built binary
# Download pre-built binary from: # https://github.com/ggerganov/llama.cpp/releases # Start a local OpenAI-compatible server with a web UI: ./llama-server -hf NovelAI/clio-v1-legacy:Q4_K_M # Run inference directly in the terminal: ./llama-cli -hf NovelAI/clio-v1-legacy:Q4_K_M
Build from source code
git clone https://github.com/ggerganov/llama.cpp.git cd llama.cpp cmake -B build cmake --build build -j --target llama-server llama-cli # Start a local OpenAI-compatible server with a web UI: ./build/bin/llama-server -hf NovelAI/clio-v1-legacy:Q4_K_M # Run inference directly in the terminal: ./build/bin/llama-cli -hf NovelAI/clio-v1-legacy:Q4_K_M
Use Docker
docker model run hf.co/NovelAI/clio-v1-legacy:Q4_K_M
- LM Studio
- Jan
- vLLM
How to use NovelAI/clio-v1-legacy with vLLM:
Install from pip and serve model
# Install vLLM from pip: pip install vllm # Start the vLLM server: vllm serve "NovelAI/clio-v1-legacy" # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:8000/v1/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "NovelAI/clio-v1-legacy", "prompt": "Once upon a time,", "max_tokens": 512, "temperature": 0.5 }'Use Docker
docker model run hf.co/NovelAI/clio-v1-legacy:Q4_K_M
- SGLang
How to use NovelAI/clio-v1-legacy with SGLang:
Install from pip and serve model
# Install SGLang from pip: pip install sglang # Start the SGLang server: python3 -m sglang.launch_server \ --model-path "NovelAI/clio-v1-legacy" \ --host 0.0.0.0 \ --port 30000 # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:30000/v1/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "NovelAI/clio-v1-legacy", "prompt": "Once upon a time,", "max_tokens": 512, "temperature": 0.5 }'Use Docker images
docker run --gpus all \ --shm-size 32g \ -p 30000:30000 \ -v ~/.cache/huggingface:/root/.cache/huggingface \ --env "HF_TOKEN=<secret>" \ --ipc=host \ lmsysorg/sglang:latest \ python3 -m sglang.launch_server \ --model-path "NovelAI/clio-v1-legacy" \ --host 0.0.0.0 \ --port 30000 # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:30000/v1/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "NovelAI/clio-v1-legacy", "prompt": "Once upon a time,", "max_tokens": 512, "temperature": 0.5 }' - Ollama
How to use NovelAI/clio-v1-legacy with Ollama:
ollama run hf.co/NovelAI/clio-v1-legacy:Q4_K_M
- Unsloth Desktop
- Docker Model Runner
How to use NovelAI/clio-v1-legacy with Docker Model Runner:
docker model run hf.co/NovelAI/clio-v1-legacy:Q4_K_M
- Lemonade
How to use NovelAI/clio-v1-legacy with Lemonade:
Pull the model
# Download Lemonade from https://lemonade-server.ai/ lemonade pull NovelAI/clio-v1-legacy:Q4_K_M
Run and chat with the model
lemonade run user.clio-v1-legacy-Q4_K_M
List all available models
lemonade list
- Atomic Chat
Clio (NovelAI Legacy Model)
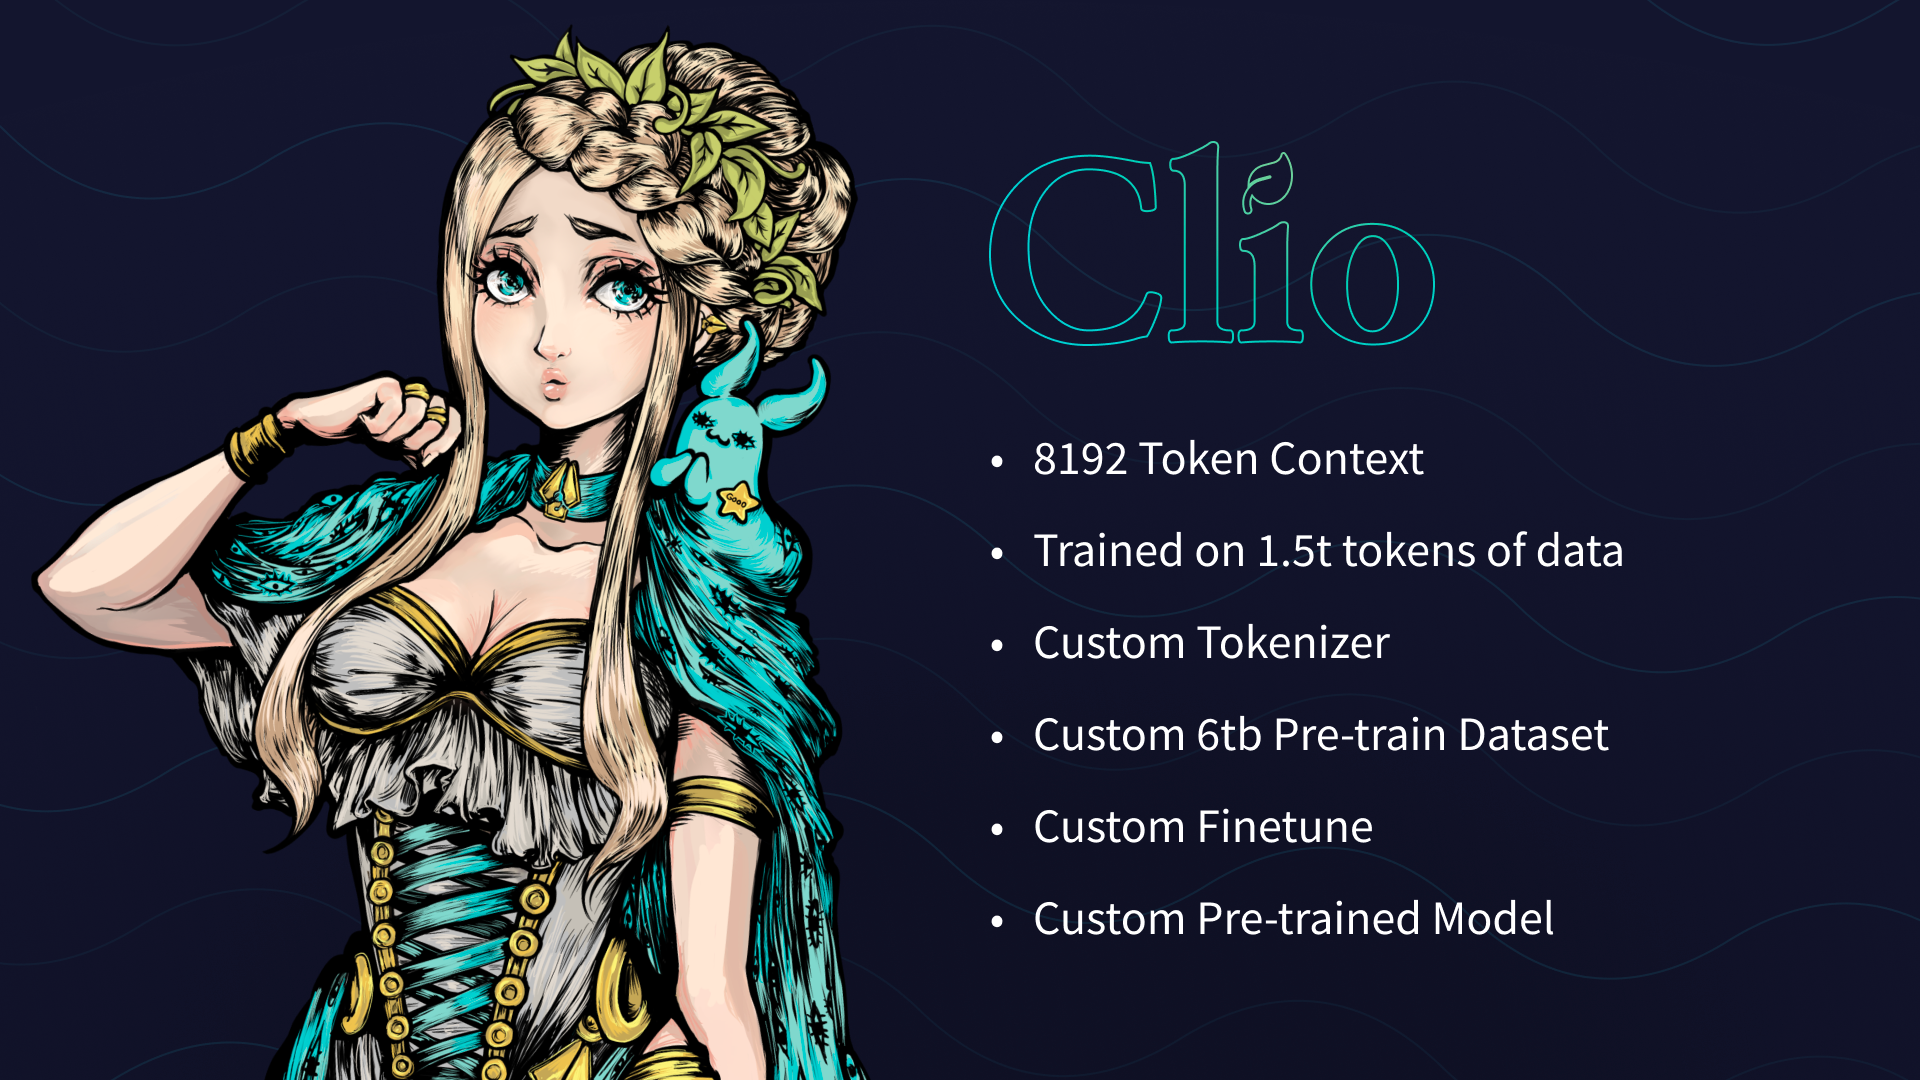
Clio is the first fully original large language model that we pretrained from scratch on our Shoggy H100 cluster. At 3 billion paramters, she runs very fast, but thanks to the, for her time, very large training volume, her writing outperforms much bigger models like Euterpe and Krake. She was trained on our custom Nerdstash dataset, with our custom Nerdstash Tokenizer V1.
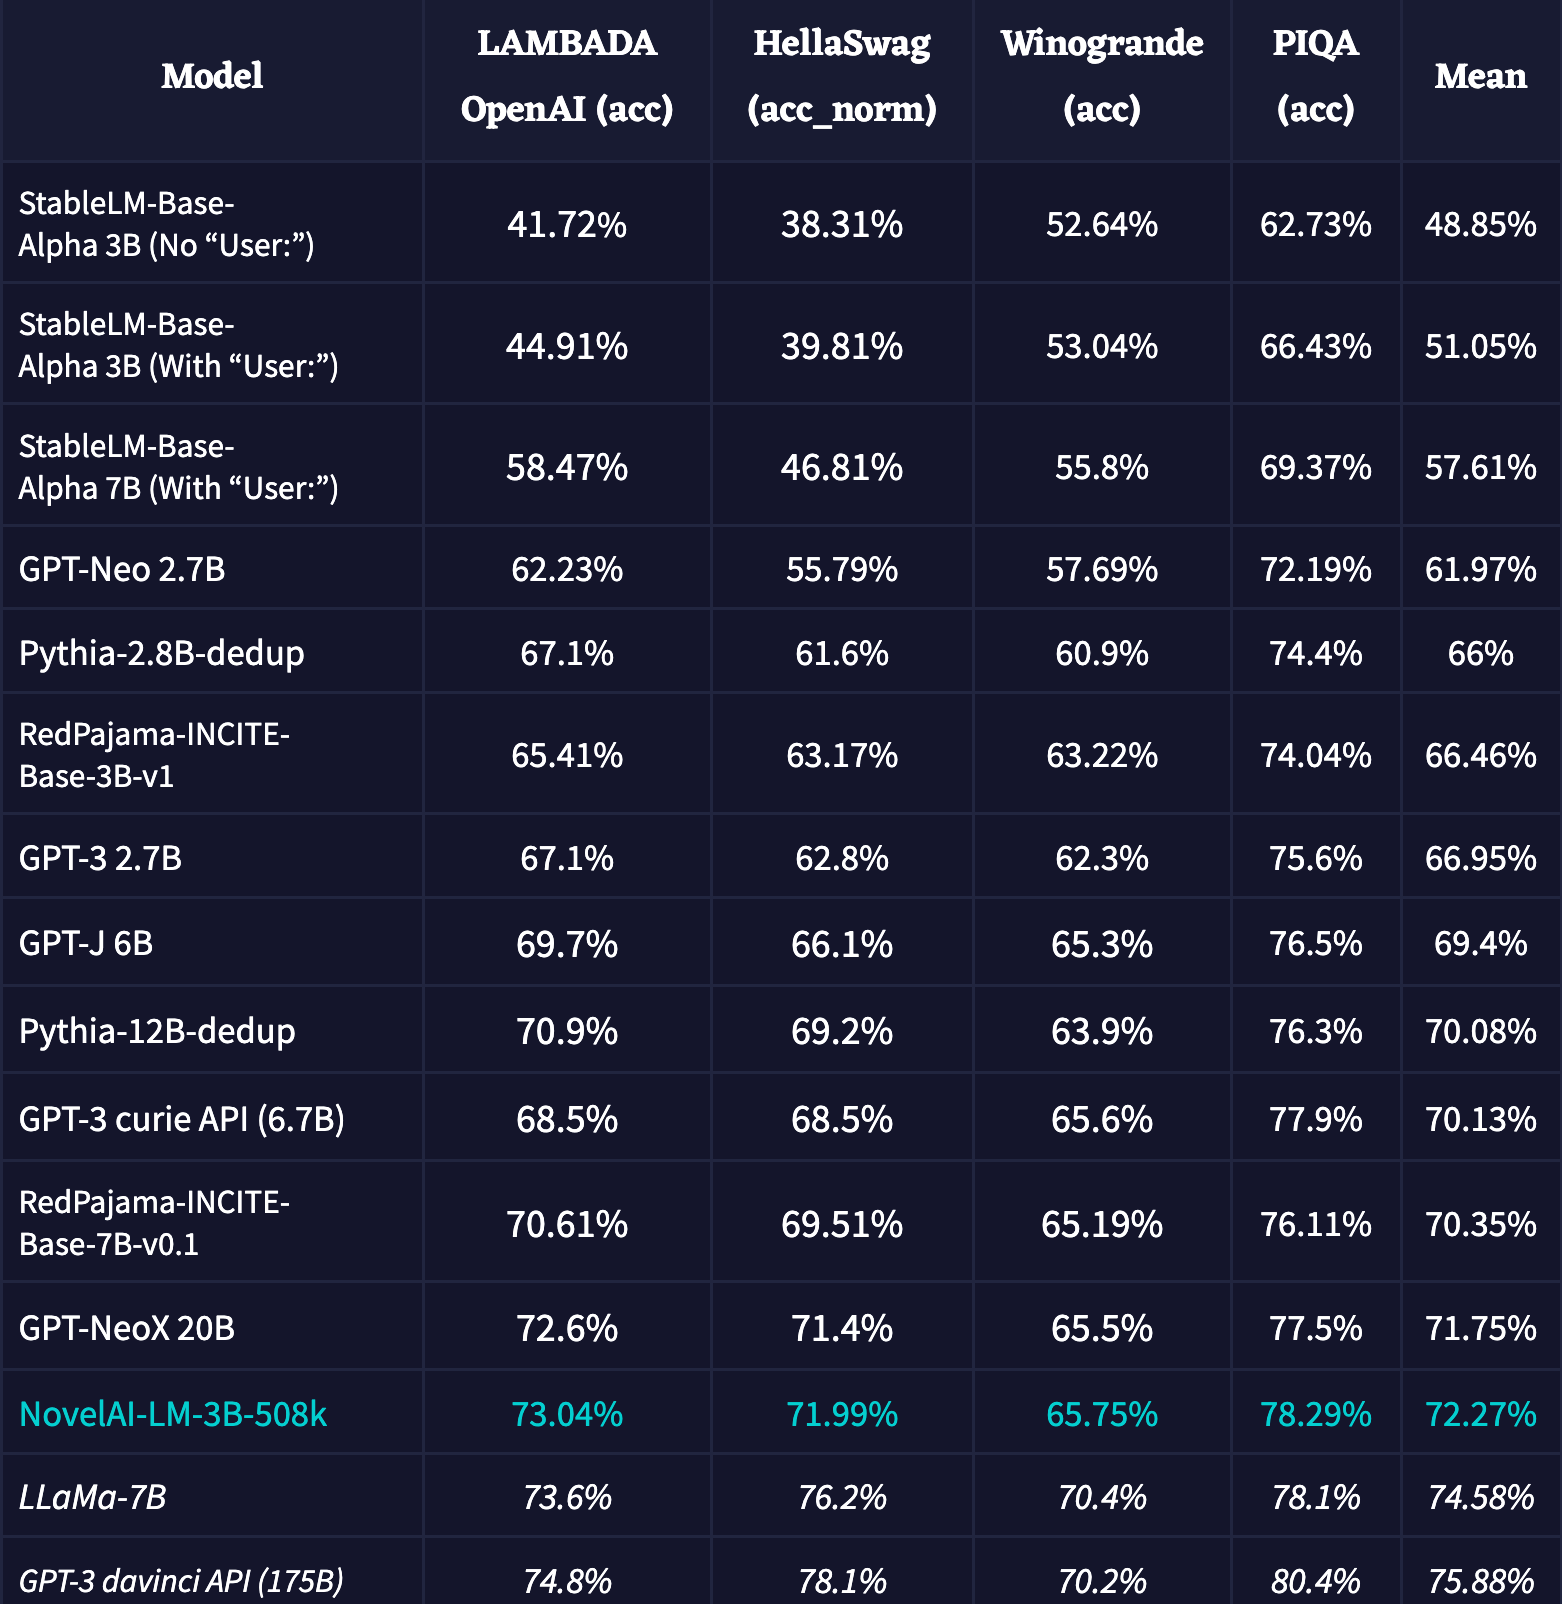
Back when she was released, Clio was very competitive across various evaluation metrics, even when compared with much bigger models. The following table shows the performance of the base model before being finetuned for story telling:
Nowadays, much stronger models, like Kayra, Erato and Xialong are available on NovelAI, so before long, Clio will get to enjoy a peaceful retirement.
So, in anticipation of this, for the sake of nostalgia, posterity, and historic preservation, we are releasing the weights of our Clio model and her modules publicly on Huggingface Hub under the GPL-2.0 (not "or later") license.
We managed to find an existing model class inside Huggingface Transformers which fits the shape of our architecture for Clio, at least once an additional config flag is set, so no custom code is needed to run Clio. Model files in GGUF format are provided as well.
You can find your very own Clio right here where you are!
- Downloads last month
- 1,569


