

Captain AEGIS Flagship
Conversational AI · Code Assistance · Wizards/Wands Architecture · Experimental Multimodal Production
Built by Henry Barton / NeVeRhOOd
Release state: Public checkpoint distribution. All five root SafeTensors shards, tokenizer, configuration files and model index are present in this repository with the expected recorded byte sizes. Basic GPU loading, short text generation, and streaming are now verified on a Tesla T4. The complete five-shard checkpoint passed the bounded smoke test. Independent quality/safety benchmarks, native tool-call verification, production serving, and uptime are still pending. The original storage bucket is preserved as a backup and research record.
Captain AEGIS is an independent AI engineering project centered on a Qwen3.5-4B-derived text-model checkpoint, a structured chat and tool-use runtime, and a wider architecture for model-assisted applications. The goal is to make a useful downloadable model accompanied by an auditable runtime and an approachable, interactive chat experience.
Start here: Explore the interactive Captain Tesseract · NeVeRhOOd Academy · GitHub profile
What Captain is
| Component | Verified source information |
|---|---|
| Architecture | Qwen3_5ForCausalLM, model type qwen3_5_text |
| Saved model | 4,205,751,296 physical parameters (historical checkpoint index) |
| Weights | Five BF16 SafeTensors shards, ~8.41 GB |
| Context configuration | Determined by the accompanying config and active runtime limits; not independently performance-verified |
| Tokenizer | Original tokenizer.json + tokenizer_config.json + chat_template.jinja |
| Development | Original merge record identifies Qwen3.5-4B source, training adapter, and a 16-step training report |
| 78.75 GB figure | Declared future body target, not downloaded learned weights |
| Inference | Private source includes a CUDA Transformers backend and streaming OpenAI-shaped API; basic real GPU smoke verified on Tesla T4; hosted API not yet verified |
Capabilities and development directions
- Conversation and code: central intended use of the saved language-model checkpoint.
- Structured tools: the separate runtime offers model/tool-call parsing, allowlisted Wizards/Wands, bounded tool rounds, and tool-result reinjection.
- Streaming chat: an OpenAI-compatible SSE interface exists in the private source; a fully verified public hosted release is still in progress.
- Learning and evaluation: training/evaluation reports and acceptance gates are part of the broader AEGIS system; they must not be mistaken for live self-training by this checkpoint.
- Video, music and image-production workflows: additional independent production-plan packs and proposed orchestration capabilities exist outside the root checkpoint. Their schemas can be generalized into tools for shot planning, characters, camera, music cues, scene continuity and video analysis. The root text checkpoint alone is not verified as a native video/audio renderer.
Explore the system design
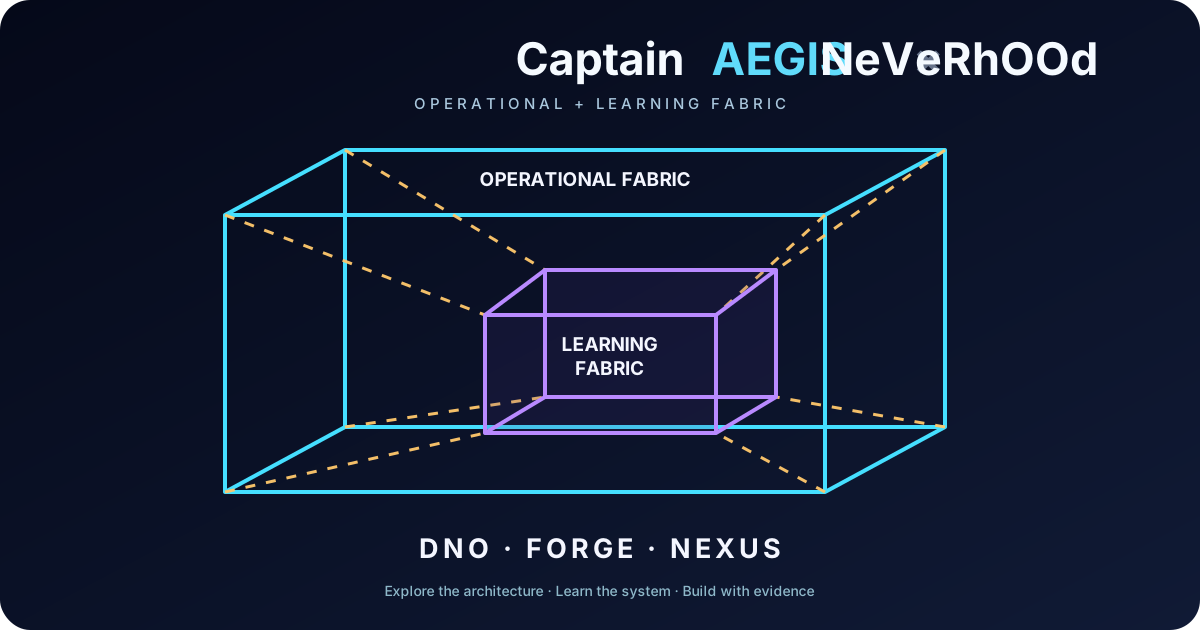
The operational/learning Tesseract organizes twelve conceptual facets:
| Operational fabric | Learning and executive fabric |
|---|---|
| F1 Perception and grounding | F7 Teachers and specialist routing |
| F2 Context and persistent memory | F8 Curriculum and education |
| F3 Reasoning and adaptive attention | F9 Neural training and weight generation |
| F4 Planning and world simulation | F10 Verification and reconciliation |
| F5 Action through Wizards/Wands | F11 Skills, organs and versioning |
| F6 Generation and production | F12 Executive coordination and compute |
These are system-design mappings, not a claim that the deployed model has already implemented or mastered all twelve facets.
Model files and bucket layout
Only the root model artifacts belong in the downloadable model repository:
config.json
generation_config.json
chat_template.jinja
tokenizer.json
tokenizer_config.json
model.safetensors.index.json
model-00001-of-00005.safetensors
model-00002-of-00005.safetensors
model-00003-of-00005.safetensors
model-00004-of-00005.safetensors
model-00005-of-00005.safetensors
The original storage bucket also holds experiments/, heavy-body-v1/, and packs/. Those are not interchangeable with root model weights and will not be bundled indiscriminately. The heavy-body folder contains archived/copied root components and planning artifacts, not proof of a complete 78.75 GB trained body.
Video direction and production-planning research
One archived creative-production pack models an end-to-end movie workflow: story beats, scene blocks, character identities, location and prop continuity, dialogue, camera plans, music direction, editorial rules, reference images and proof receipts.
A second pack describes geometric/visual concepts such as depth, fractal layers, texture, light and motion continuity. These represent research and planning artifacts, not established learned vision weights.
The planned generic Wizards/Wands production system will accept original stories and properly licensed reference media, produce structured scene/shot plans, invoke compatible renderers, inspect outputs and record corrections. Franchise-specific material and unverified third-party reference assets will not be released as part of the generic toolkit.
How to run it
A compatible CUDA-capable environment, supported Transformers release, sufficient GPU memory, and the complete model repository are required. This checkpoint has not yet passed a fresh end-to-end load and generation test from the new repository; therefore, no copy-paste inference command is labelled verified here.
Once validated, the public runtime will provide /v1/models, /v1/chat/completions, health/readiness endpoints, SSE streaming and a narrowly scoped optional tool registry.
Live chat
A public Hugging Face Space is planned for chat, code assistance, read-only educational tools and an interactive architecture explorer. An embedded model-page conversational widget additionally requires a Hugging Face Inference Provider to deploy this exact model. The text-generation metadata does not automatically activate hosted inference.
Research evidence, provenance and release conditions
The source's original merge_report.json records a saved merged checkpoint and a training history; the separate active_slice_footprint_report.json records about 8.43 GB of saved artifacts against a 78.75 GB target budget. Neither report certifies video rendering, benchmark rankings or a production-quality autonomous agent.
Before public release: verify exact upstream model license/attribution, rights to training materials, all five shard hashes and SafeTensors metadata, tokenizer/chat-template compatibility, actual model load, representative text/code/tool outputs, GPU memory usage and safety boundaries.
License: not yet declared for this derived checkpoint, pending upstream lineage verification. This is not permission to redistribute or commercialize it.
NeVeRhOOd · Independent AI engineering, software development and systems research · Cleveland, Ohio.
Upstream license and attribution
This repository is a research derivative historically traced to Qwen/Qwen3.5-4B, whose upstream license is Apache License 2.0. The original license text is preserved in this repository's LICENSE file. The checkpoint's exact base revision, adapter lineage, training data rights, and independently verified model behavior require further evidence. This attribution is not an endorsement by the Qwen team.
Verified real-GPU smoke test — November 6, 2026
An independently executed bounded inference test loaded the public 5-shard checkpoint at the immutable revision
c669285e759adb0b2508c15e1254c3e290435d62 using PyTorch 2.14.1 and Transformers 5.22.1.
| Measurement | Result |
|---|---|
| GPU | NVIDIA Tesla T4 (14.56 GiB VRAM) |
| Checkpoint | 5 SafeTensors shards, 426 tensor entries loaded |
| Model load time | 36.339 seconds |
| Prompt length | 23 tokens |
| Generated output | 16 tokens, deterministic decoding |
| Generation time | 3.371 seconds |
| Peak GPU allocation | 8,501,875,200 bytes (~8.50 GB decimal) |
| Streaming | 17 nonempty output chunks over 1.421 seconds |
| Result | gpu_smoke_pass |
Example short reply: An API is a set of rules and protocols that allows different software applications to communicate
The machine-readable receipt records model revision, runtime versions, per-shard SHA-256 hashes, token counts, GPU memory and timings. This receipt represents real checkpoint inference, not a mocked API. A tokenizer-wrapper incompatibility was discovered and corrected before the passing run.
Boundaries: This one short prompt does not establish model accuracy, long-context performance, tool safety, production reliability, external credential use, or any claimed trillion-parameter equivalence. A hosted Captain chat endpoint has not been verified by this test.
Verified native GPU API contract — November 6, 2026
The separate Captain Python runtime was loaded against the real checkpoint on an NVIDIA Tesla T4 and tested with FastAPI's in-memory HTTP client. No fake inference backend was used for these checks. The corrected Transformers 5.x tokenizer adapter returned a valid tensor.
| Native endpoint / control | Observed |
|---|---|
GET /health |
HTTP 200 |
GET /ready with loaded checkpoint |
HTTP 200 |
GET /v1/models with bearer token |
HTTP 200 |
GET /v1/models without token |
HTTP 401 |
POST /v1/chat/completions without token |
HTTP 401 |
Unregistered shell.exec tool request |
HTTP 400 |
| Real model chat completion | HTTP 200 |
| Real model streaming SSE | HTTP 200, 17 data lines |
Native run: model load 44.309 seconds, bounded chat request 4.589 seconds, SSE streaming request 1.051 seconds, peak GPU allocation 8,493,098,496 bytes.
The machine-readable native-API receipt documents these acceptance checks. This demonstrates working local in-VM model-backed HTTP request handling, authentication and transport-level tool authorization. It does not demonstrate a publicly deployed Internet endpoint, arbitrary model-generated tool execution, long-term availability, or independent model quality.
- Downloads last month
- 1,835