Instructions to use Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500 with libraries, inference providers, notebooks, and local apps. Follow these links to get started.
- Libraries
- Transformers
How to use Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500 with Transformers:
# Use a pipeline as a high-level helper from transformers import pipeline pipe = pipeline("text-generation", model="Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500") messages = [ {"role": "user", "content": "Who are you?"}, ] pipe(messages)# pip install -U transformers accelerate # Load model directly from transformers import AutoTokenizer, AutoModelForCausalLM tokenizer = AutoTokenizer.from_pretrained("Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500") model = AutoModelForCausalLM.from_pretrained("Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500", device_map="auto") messages = [ {"role": "user", "content": "Who are you?"}, ] inputs = tokenizer.apply_chat_template( messages, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt", ).to(model.device) outputs = model.generate(**inputs, max_new_tokens=256) print(tokenizer.decode(outputs[0][inputs["input_ids"].shape[-1]:])) - Notebooks
- Google Colab
- Kaggle
- Local Apps Settings
- vLLM
How to use Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500 with vLLM:
Install from pip and serve model
# Install vLLM from pip: pip install vllm # Start the vLLM server: vllm serve "Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500" # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:8000/v1/chat/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500", "messages": [ { "role": "user", "content": "What is the capital of France?" } ] }'Use Docker
docker model run hf.co/Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500
- SGLang
How to use Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500 with SGLang:
Install from pip and serve model
# Install SGLang from pip: pip install sglang # Start the SGLang server: python3 -m sglang.launch_server \ --model-path "Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500" \ --host 0.0.0.0 \ --port 30000 # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:30000/v1/chat/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500", "messages": [ { "role": "user", "content": "What is the capital of France?" } ] }'Use Docker images
docker run --gpus all \ --shm-size 32g \ -p 30000:30000 \ -v ~/.cache/huggingface:/root/.cache/huggingface \ --env "HF_TOKEN=<secret>" \ --ipc=host \ lmsysorg/sglang:latest \ python3 -m sglang.launch_server \ --model-path "Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500" \ --host 0.0.0.0 \ --port 30000 # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:30000/v1/chat/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500", "messages": [ { "role": "user", "content": "What is the capital of France?" } ] }' - Docker Model Runner
How to use Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500 with Docker Model Runner:
docker model run hf.co/Geraldxm/Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500
Math-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Math-Step500
Paper · GitHub · Project · Collection
This repository contains an on-policy distillation (OPD) student checkpoint released with Towards Understanding On-Policy Distillation through the Lens of Test-Time Scaling. Its base model, teacher, and training data are listed below.
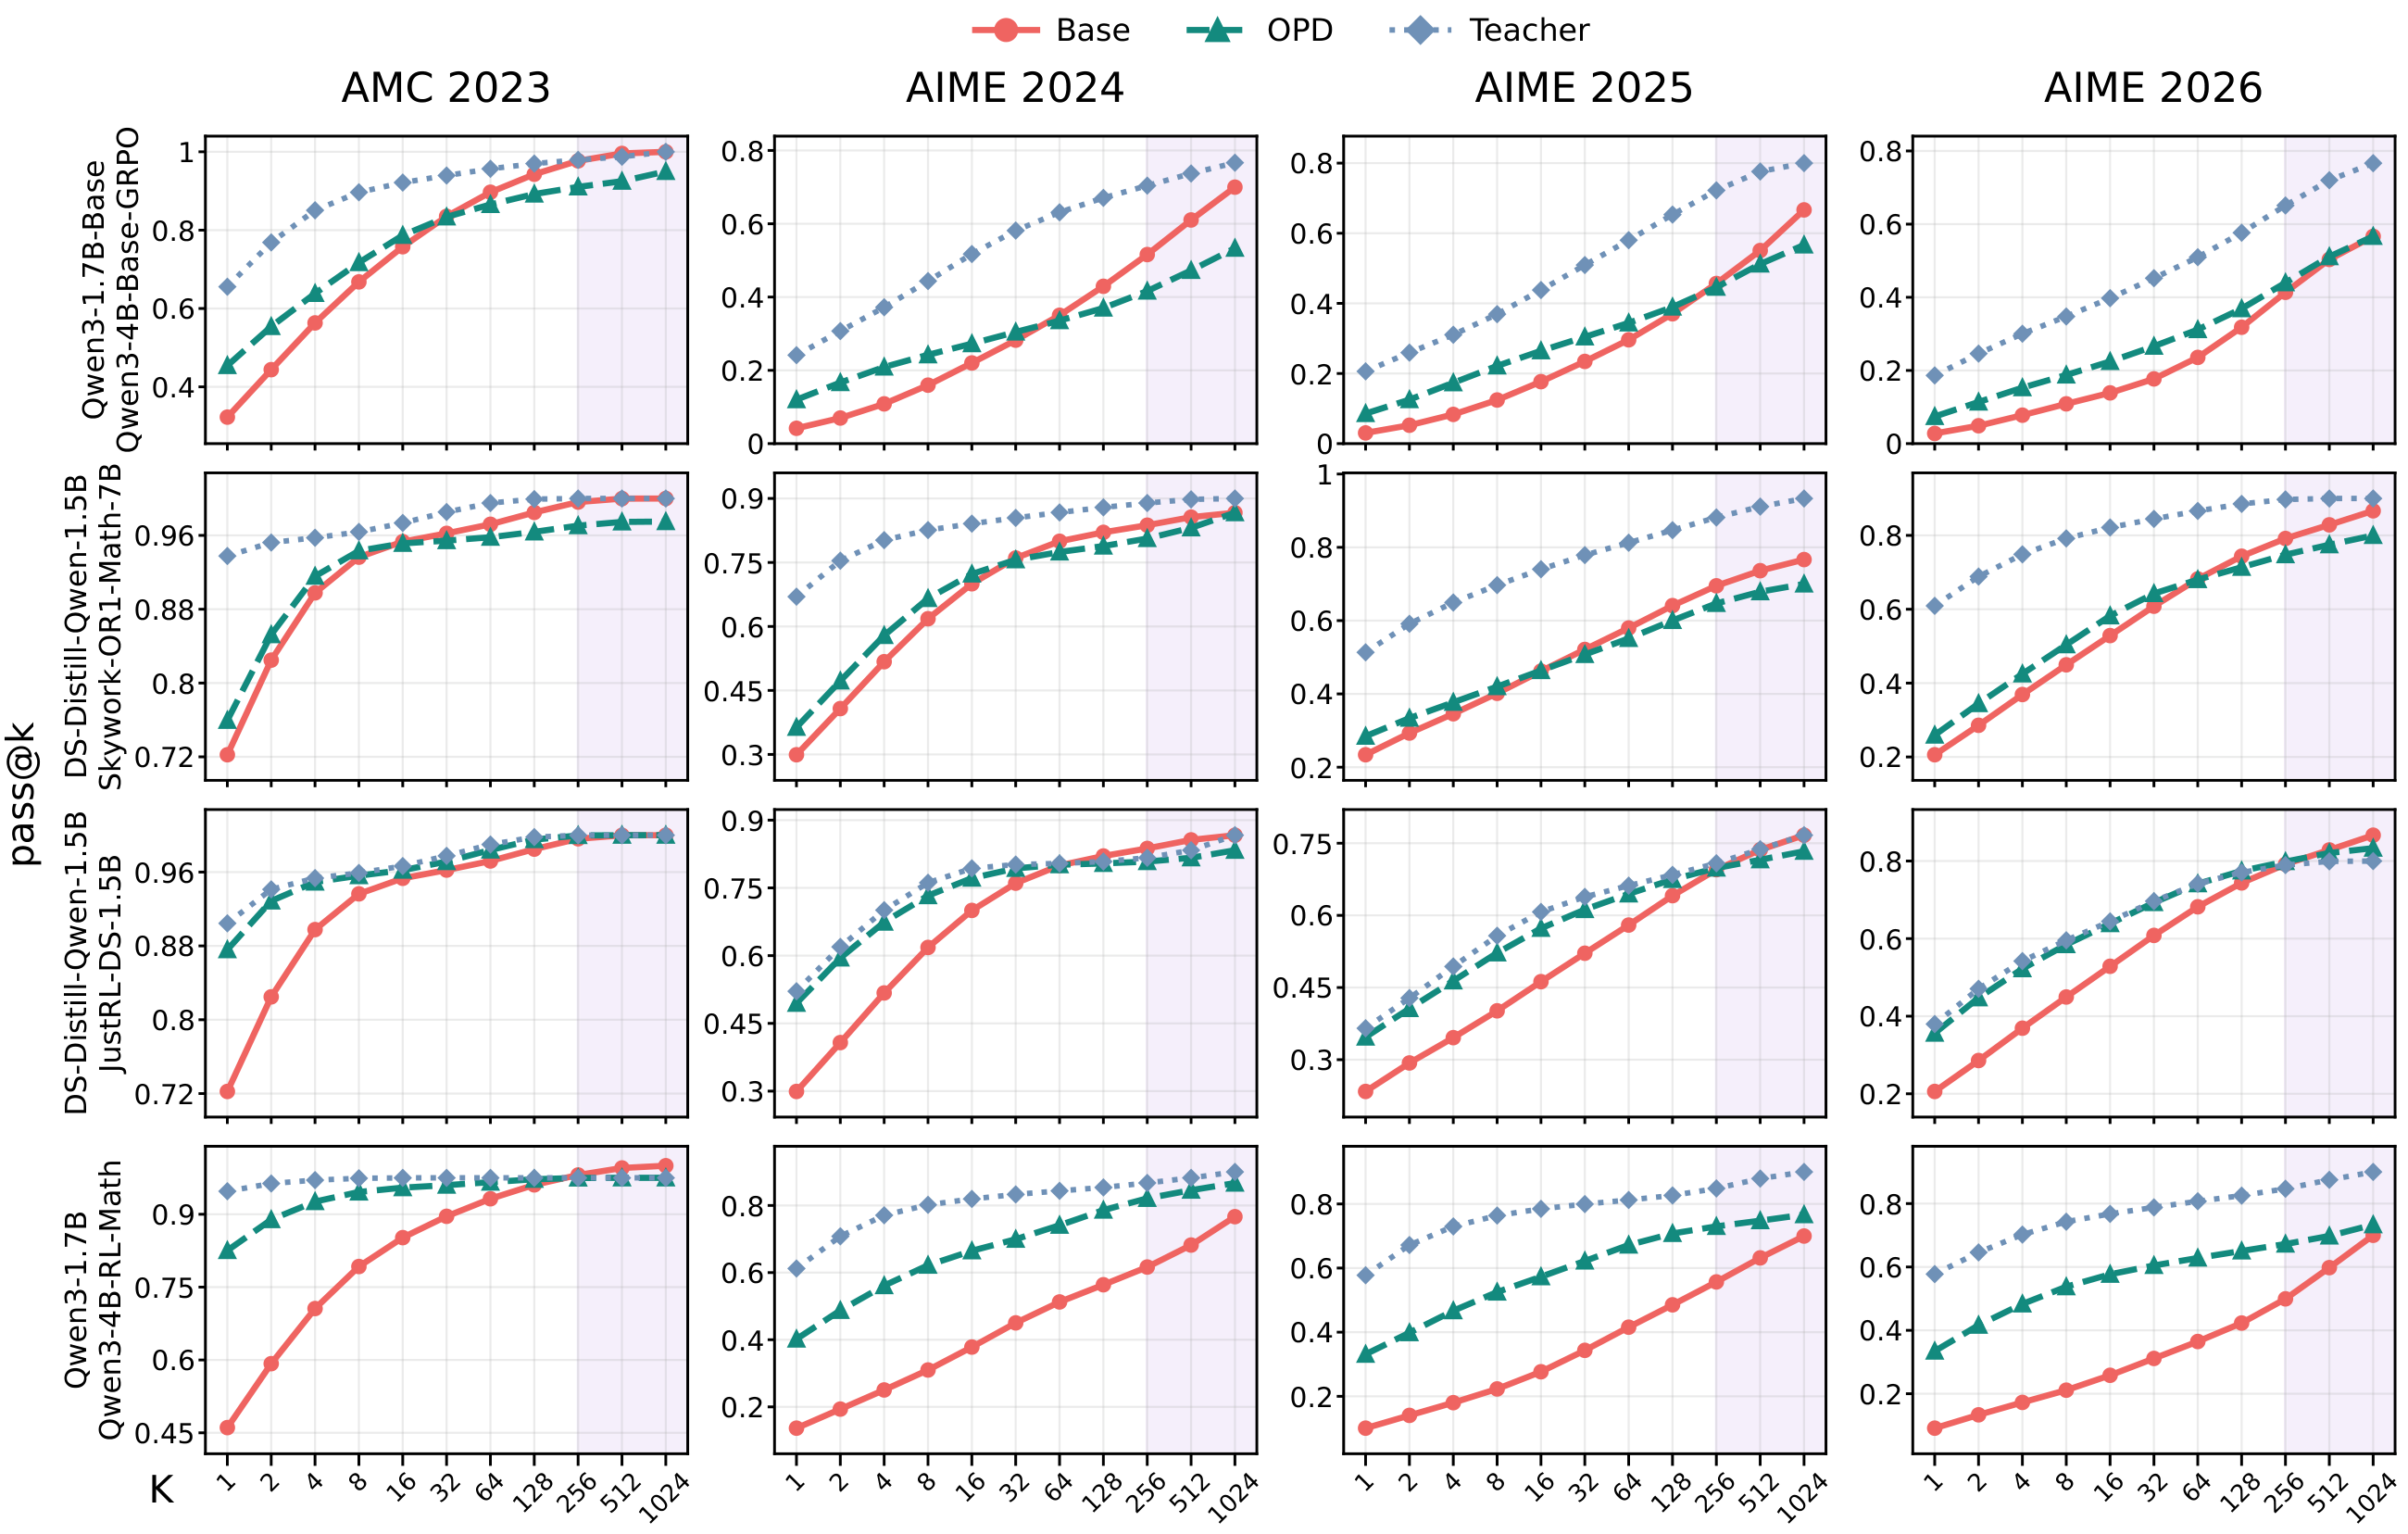
The figure reports paper results across math settings; it is not a scorecard for this checkpoint alone.
Checkpoint details
- Base model: Qwen/Qwen3-1.7B
- Teacher model: Keven16/Qwen3-4B-Non-Thinking-RL-Math-Step500
- Training data: DAPO-Math-17K, using the deduplicated OPD training set prepared in math-vault.
Step500 is part of the teacher's name, not a stated student training step.
More information
See the paper and GitHub repository for training settings, evaluation protocols, and analysis. Upstream model and data terms remain applicable; see third-party notices.
Citation
@misc{ge2026understandingonpolicydistillationlens,
title={Towards Understanding On-Policy Distillation through the Lens of Test-Time Scaling},
author={Xinmu Ge and Zizhuo Zhang and Yu Huang and Jianing Zhu and Lin Yuan and Wanli Gu and Weichang Wu and Weiran Huang and Bo Han and Xiaolu Zhang and Jiangchao Yao},
year={2026},
eprint={2608.11829},
archivePrefix={arXiv},
primaryClass={cs.LG},
doi={10.48550/arXiv.2608.11829},
url={https://arxiv.org/abs/2608.11829}
}
- Downloads last month
- 215