

Model Card for Gruyere-1.2
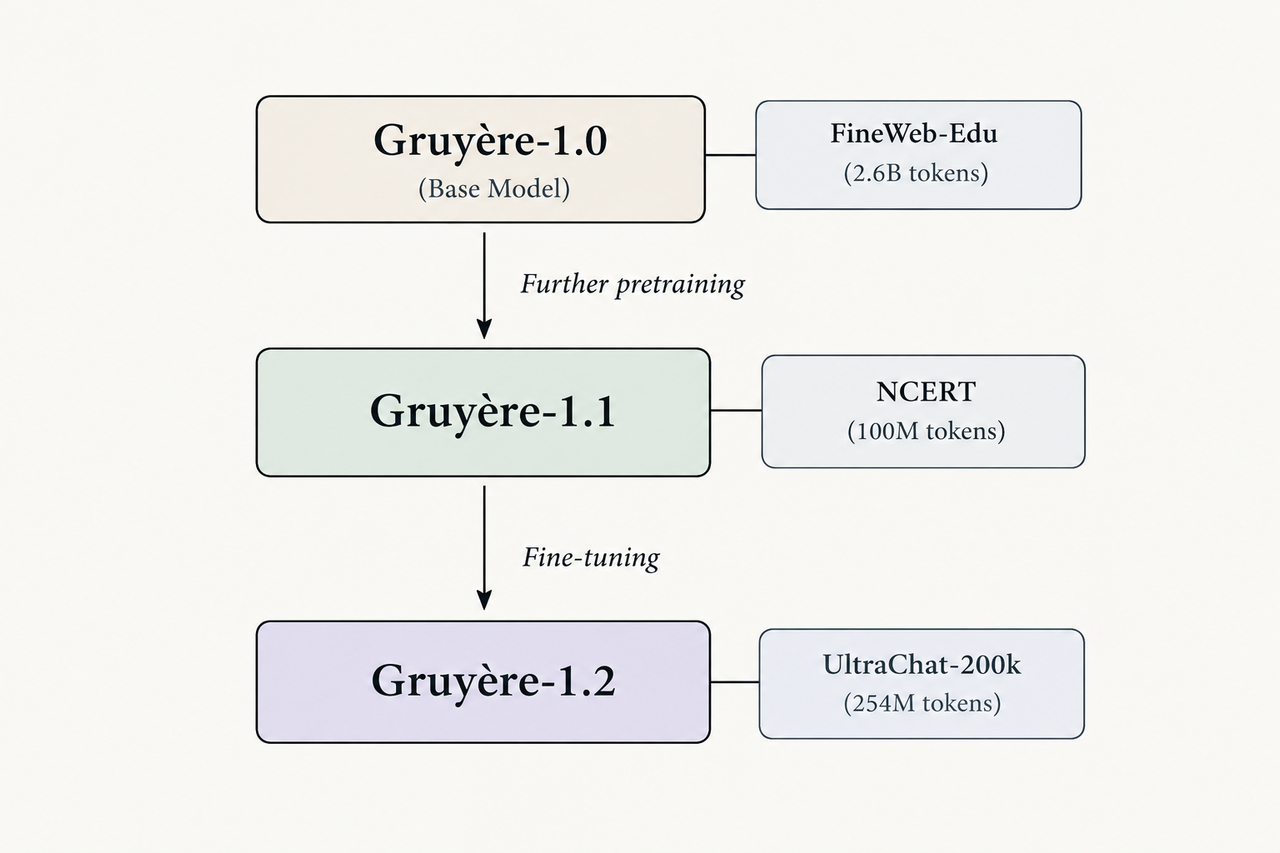
Gruyère-1.2 is an 89M-parameter autoregressive language model developed by GoudaAI. It is the third stage in the Gruyère model lineage, following pretraining on FineWeb-Edu, continued pretraining on NCERT educational material, and instruction fine-tuning on UltraChat-200k.
The model is just some fun research into designing and optimising LM's for consumer GPU's when compute scaling isnt avaliable
Model Details
Model Description
- Developed by: GoudaAI
- Model type: GPT-style autoregressive language model
- Language: English
- License: MIT
- Unique parameters: ~64M
- Model lineage: Gruyere-1.0 → Gruyere-1.1 → Gruyere-1.2
- Base model: Gruyere-1.1
- Fine-tuning dataset: UltraChat-200k
Model Sources
- Repository: Github: Gruyere-1.2
- GoudaAI: gouda-ai.vercel.app
Uses
Direct Use
Gruyère-1.2 is primarily intended for experimentation with small autoregressive language models and conversational generation.
It can be used for:
- Text generation
- Sometimes can give correct factual reasoning (albeit very rarely)
Bias, Risks, and Limitations
Gruyère-1.2 is a relatively small language model and has substantially less capacity than contemporary large language models. As a result, it may struggle with:
- Maintaining coherent long-form conversations
- Following complex or multi-step instructions
- Producing factually accurate information
- Reasoning over unfamiliar problems
- Maintaining consistency across longer contexts
- Avoiding repetition or other generation artefacts
The model was trained primarily on English-language data and has a mental breakdown when you present it with another language
As with other language models, outputs may and often do contain factual errors, biases, undesirable associations, or fabricated information. Evaluation results should therefore be interpreted as measurements on specific benchmarks rather than as a guarantee of general performance.
In early testing with the model it often strayed into conversation containing senstivie topics, as a result safe guards are likely necessary
Training Details
Training Data
Gruyère-1.2 is the result of three successive training stages:
- Gruyère-1.0 was pretrained on 2.6B tokens from FineWeb-Edu.
- Gruyère-1.1 was obtained through further pretraining on 100M tokens of NCERT educational explanations.
- Gruyère-1.2 was fine-tuned for one epoch on the full UltraChat-200k dataset, comprising approximately 254M tokens.
The NCERT dataset consisted of explanations only. Examples were shuffled before training, but were not reshuffled between epochs.
UltraChat-200k was used without additional filtering.
Training Procedure
Gruyère-1.2 was initialized from Gruyère-1.1 and fine-tuned on UltraChat-200k for one epoch.
The training process was conducted on a single consumer GPU, with the total training time across the Gruyère-1.0, Gruyère-1.1 and Gruyère-1.2 stages kept below the project's self-imposed 24-hour limit.
Training Hyperparameters
- Training objective: Causal language modelling / next-token prediction
- Fine-tuning duration: 1 epoch
- Fine-tuning dataset: UltraChat-200k
- Context length: 1024 tokens
- Training hardware: NVIDIA RTX 3080 10GB
Speeds, Sizes, Times
Training time across the model lineage:
| Stage | Dataset | Training time |
|---|---|---|
| Gruyère-1.0 | FineWeb-Edu | 17h 36m |
| Gruyère-1.1 | NCERT | 36m |
| Gruyère-1.2 | UltraChat-200k | 2h 25m |
| Total | 20h 37m |
This kept the complete training process within the project's self-imposed 24-hour model creation limit.
Evaluation
Testing Data, Factors & Metrics
Testing Data
Gruyère-1.2 was evaluated using tasks from the lm-evaluation-harness benchmark suite.
The evaluation set consists of:
- HellaSwag
- ARC-Easy
- ARC-Challenge
- PIQA
- Winogrande
- OpenBookQA
- LAMBADA OpenAI
- BoolQ
- COPA
- SciQ
- WSC273
- WikiText
- TruthfulQA MC2
The same evaluation suite is used to compare Gruyère-1.2 against Gruyère-1.1.
Metrics
Where supported by the evaluation task, length-normalised accuracy (acc_norm) is used. This adjusts likelihood comparisons for the length of candidate answers and is useful when comparing multiple-choice options of different lengths.
Tasks for which acc_norm is not applicable use their standard task-specific metric.
Results
Evaluation results will be reported using the same evaluation configuration for both Gruyère-1.1 and Gruyère-1.2.
| Benchmark | Metric | Random Chance | Gruyère-1.1 | Gruyère-1.2 |
|---|---|---|---|---|
| HellaSwag | acc_norm |
25% | 26.18% | 27.7% |
| ARC-Easy | acc_norm |
~25% | 38.34% | 38.68% |
| ARC-Challenge | acc_norm |
~25% | 25.60% | 24.66% |
| PIQA | acc_norm |
50% | 51.41% | 59.30% |
| Winogrande | acc_norm |
50% | 49.33% | 51.46% |
| OpenBookQA | acc_norm |
25% | 26.00% | 27.20% |
| BoolQ | acc |
50% / (62% 'yes' baseline) | 55.50% | 60.61% |
| COPA | acc_norm |
50% | 58.00% | 56.00% |
| SciQ | acc_norm |
25% | 46.20% | 51.70% |
| WSC273 | acc_norm |
50% | 51.08% | 51.28% |
| TruthfulQA MC2 | acc |
~20-25% | 47.24% | 45.07% |
| --- | --- | --- | --- | --- |
| WikiText | word_perplexity |
N/A | 55,167.79 | 145.55 |
| WikiText | byte_perplexity |
~15 | 7.704 | 2.538 |
| WikiText | bits_per_byte |
~3.9 | 2.946 | 1.344 |
| LAMBADA OpenAI | Perplexity |
50,304 | 6,950,578.35 (potential error) | 1,165.35 |
Model Architecture and Objective
Gruyère-1.2 is a GPT-style decoder-only transformer trained using the causal language modelling objective.
- Architecture: Decoder-only Transformer
- Layers: 12
- Attention heads: 8
- Embedding dimension: 512
- Context length: 1024 tokens
- Vocabulary size: 50,304
- Activation: ReLU
- Position encoding: Learned positional embeddings
- Objective: Next-token prediction
The model contains approximately 64M unique parameters. The Hugging Face model representation reports 89M parameters, including approximately 25M duplicated parameters.
Hardware
- GPU: NVIDIA RTX 3080
- VRAM: 10GB
- GPU count: 1
More Information
Gruyère-1.2 is part of the broader GoudaAI project, which explores the development, training and evaluation of small language models.
More information about the project, model releases and future work can be found at:
Model Card Authors
GoudaAI
Model Card Contact
Further information and project updates are available through the GoudaAI project.
- Downloads last month
- 329