

GGUF Quants of Qwen-Image-2.1 for ComfyUI.
Original model repository: https://huggingface.co/Qwen/Qwen-Image-2.1
Watch us on Youtube: @VantageWithAI
🤖 ModelScope | 🤗 HuggingFace | 📑 Blog | 🖥️ Demo | 🫨 Discord | 💬 WeChat

Introduction
We are excited to open-source Qwen-Image-2.1, a unified text-to-image generation and image editing model in the Qwen family. With just 7B parameters in its visual generation component (32 Single-Stream DiT layers), Qwen-Image-2.1 balances generation quality, inference efficiency, and versatility.
Four key improvements define this release:
- Compact and Efficient — A lightweight architecture with mixed-granularity attention and prefix KV cache reuse delivers strong image quality at low computational cost.
- Native Transparency, Unified Creation and Editing — Generate regular or transparent (RGBA) images from text, edit transparent layers, and extract subjects from photographs—all in one model.
- Versatile Editing — Support up to 10 reference images, specify local edits via circles, painted annotations, or separate masks, and preserve identity for people and products.
- Realistic Textures and Refined Aesthetics — Improved typography, portrait lighting, and fine details for more visually compelling results.
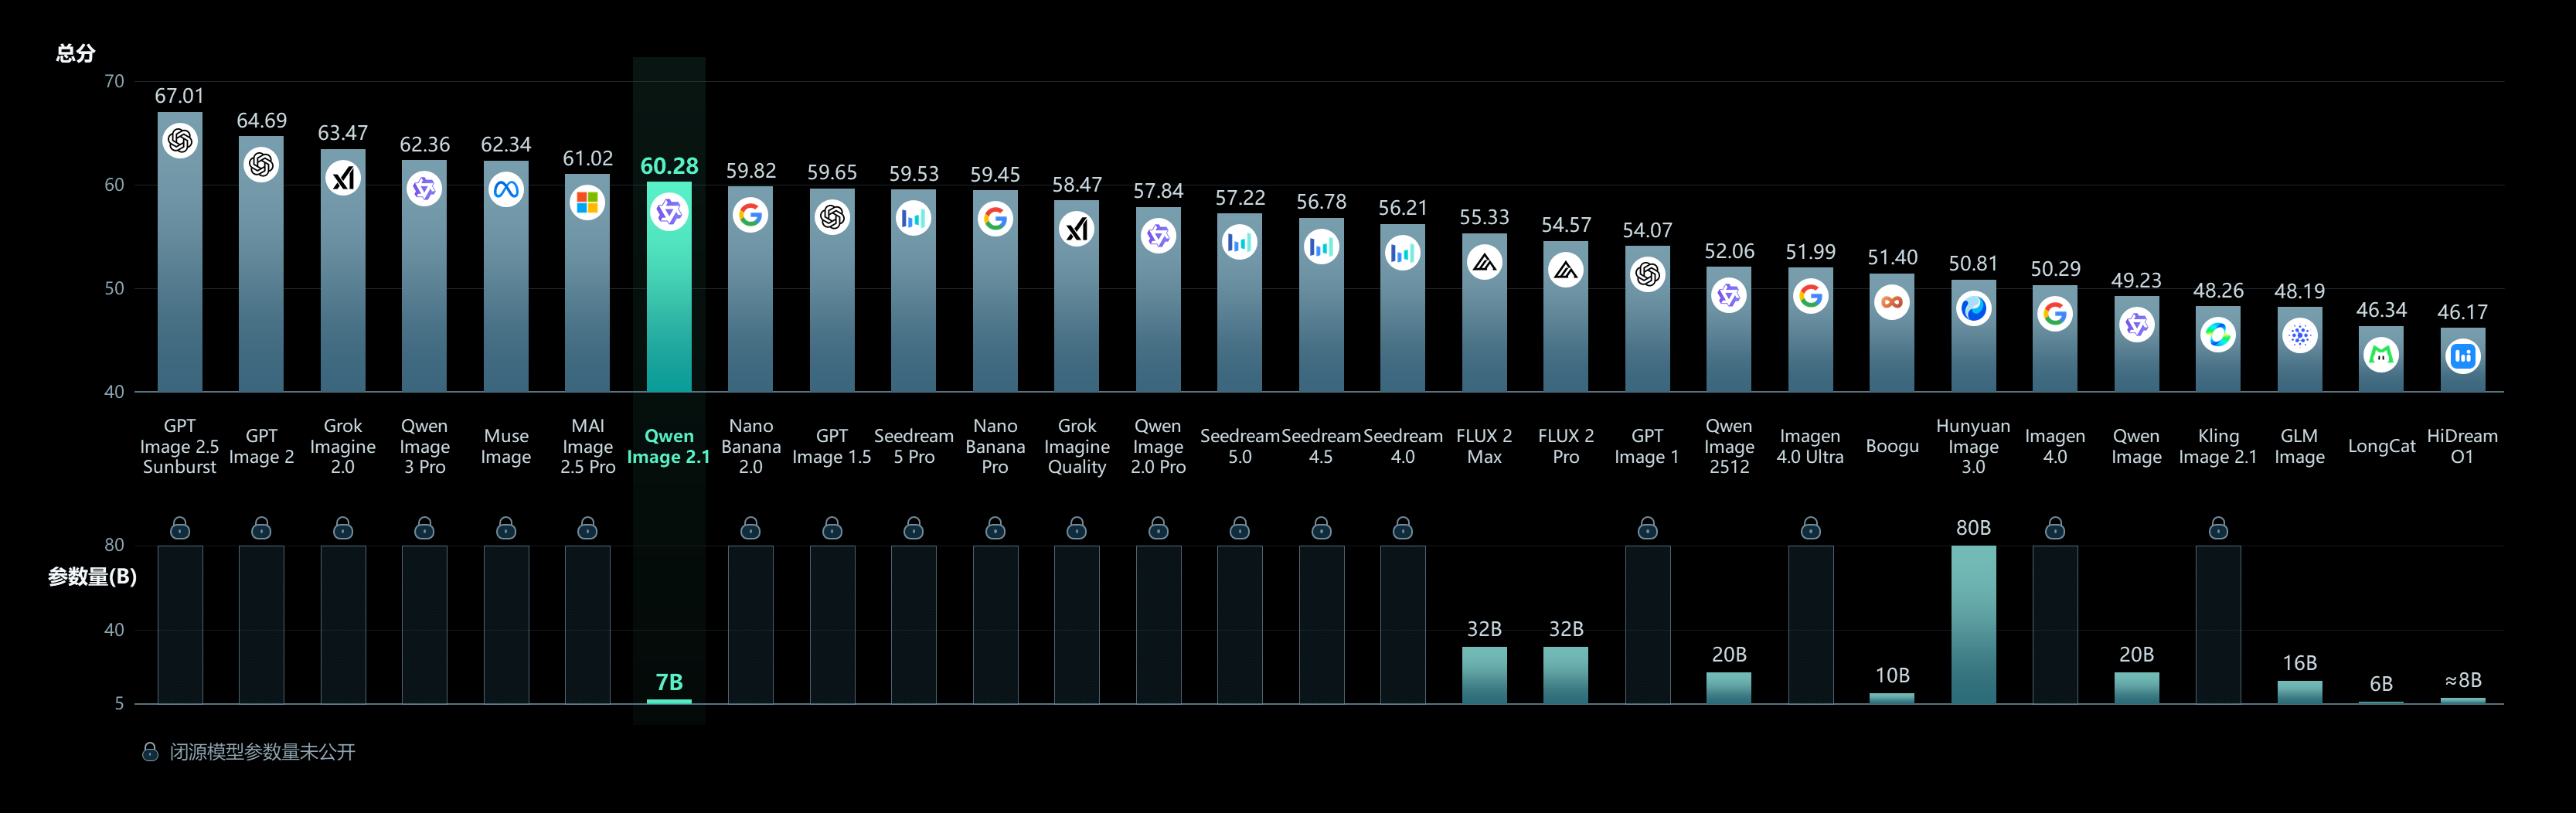
For more details, see the GitHub repo and Blog.
Supported Aspect Ratios
aspect_ratios = {
    "1:1":  (2048, 2048),
    "4:3":  (2400, 1792),
    "3:4":  (1792, 2400),
    "3:2":  (2528, 1696),
    "2:3":  (1696, 2528),
    "16:9": (2752, 1536),
    "9:16": (1536, 2752),
}
Showcase
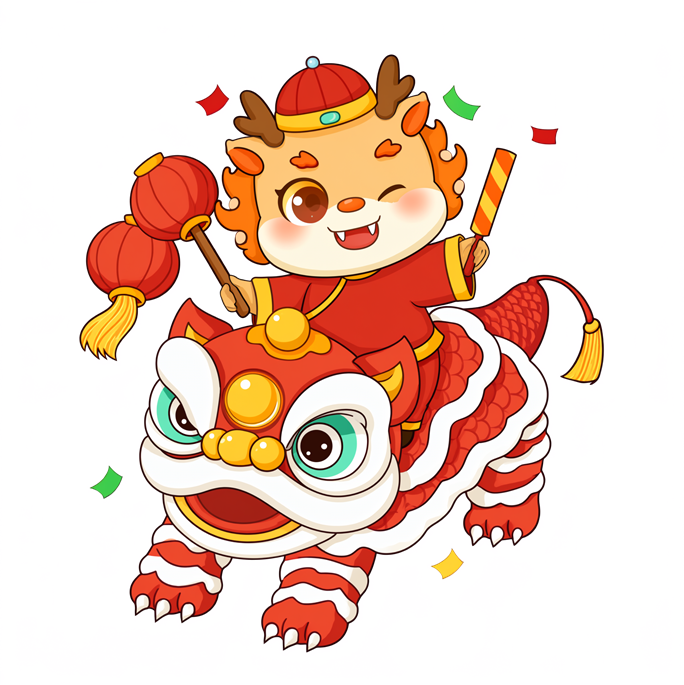
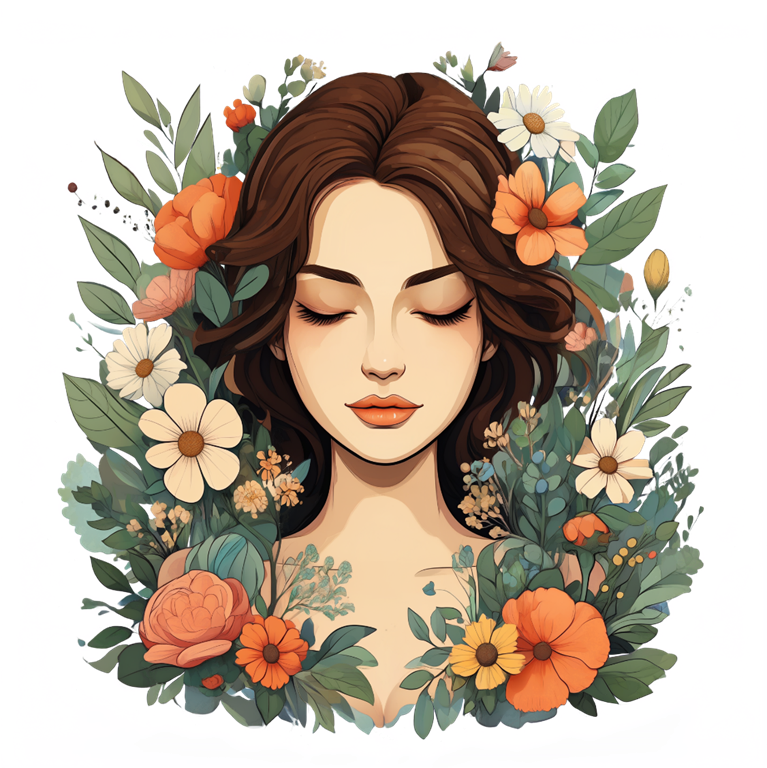
Native transparent image generation
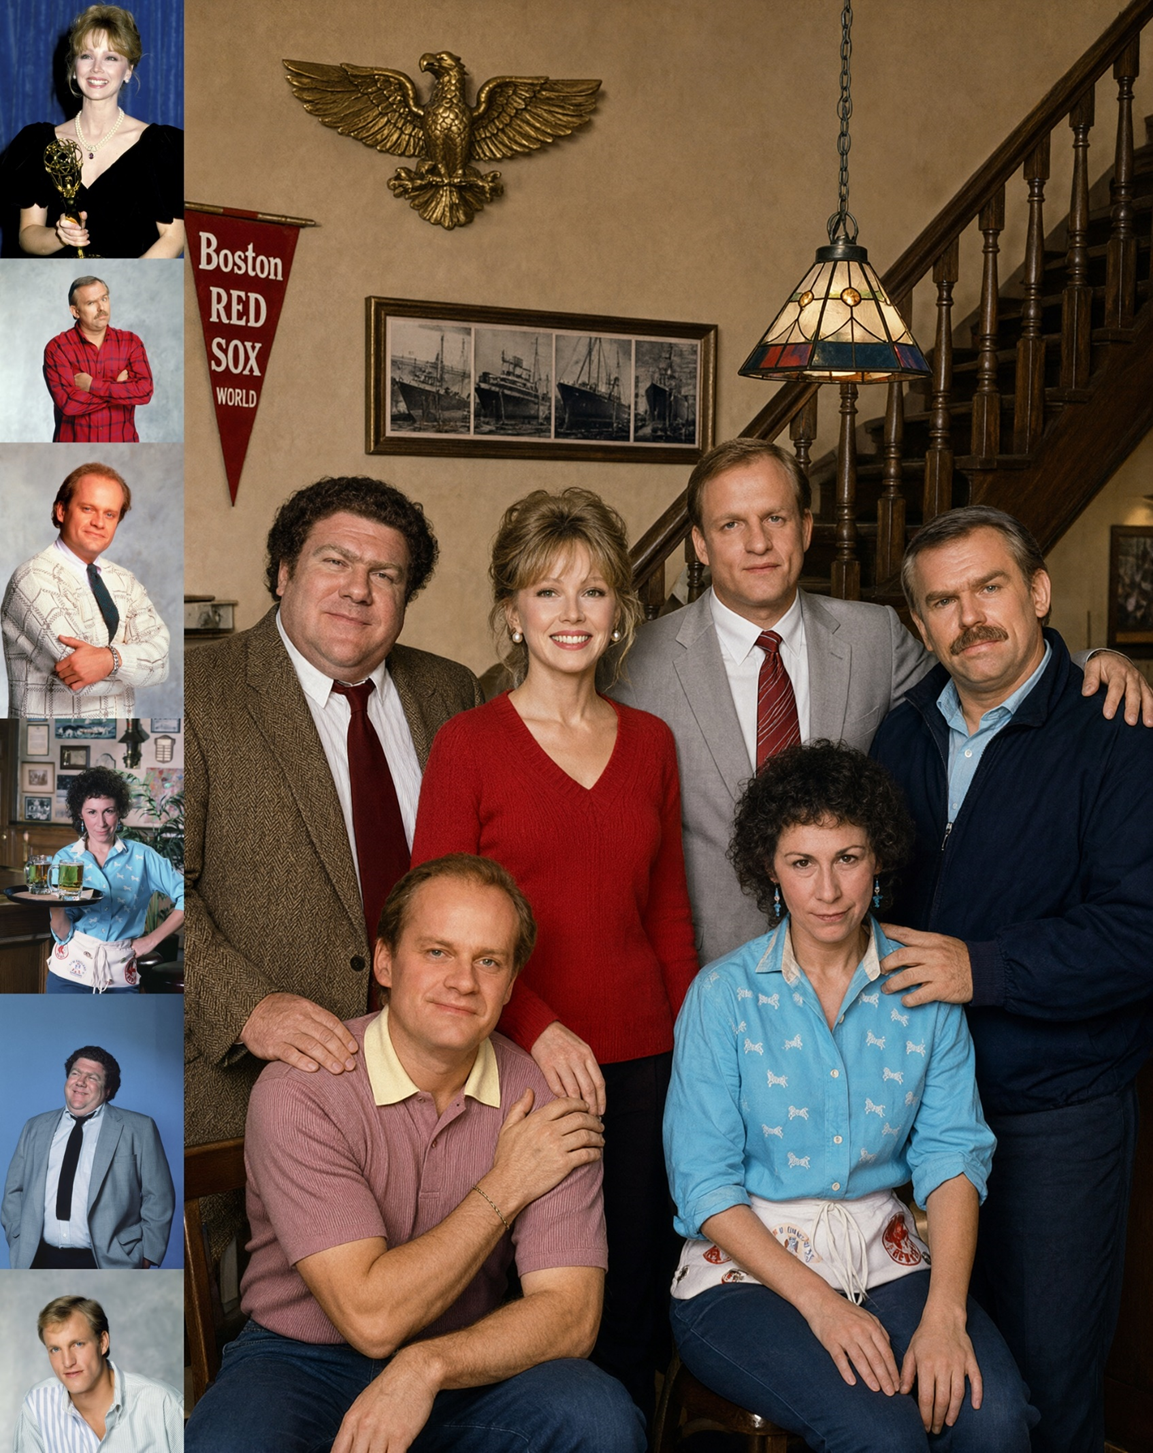
Group photograph generated from six portrait references
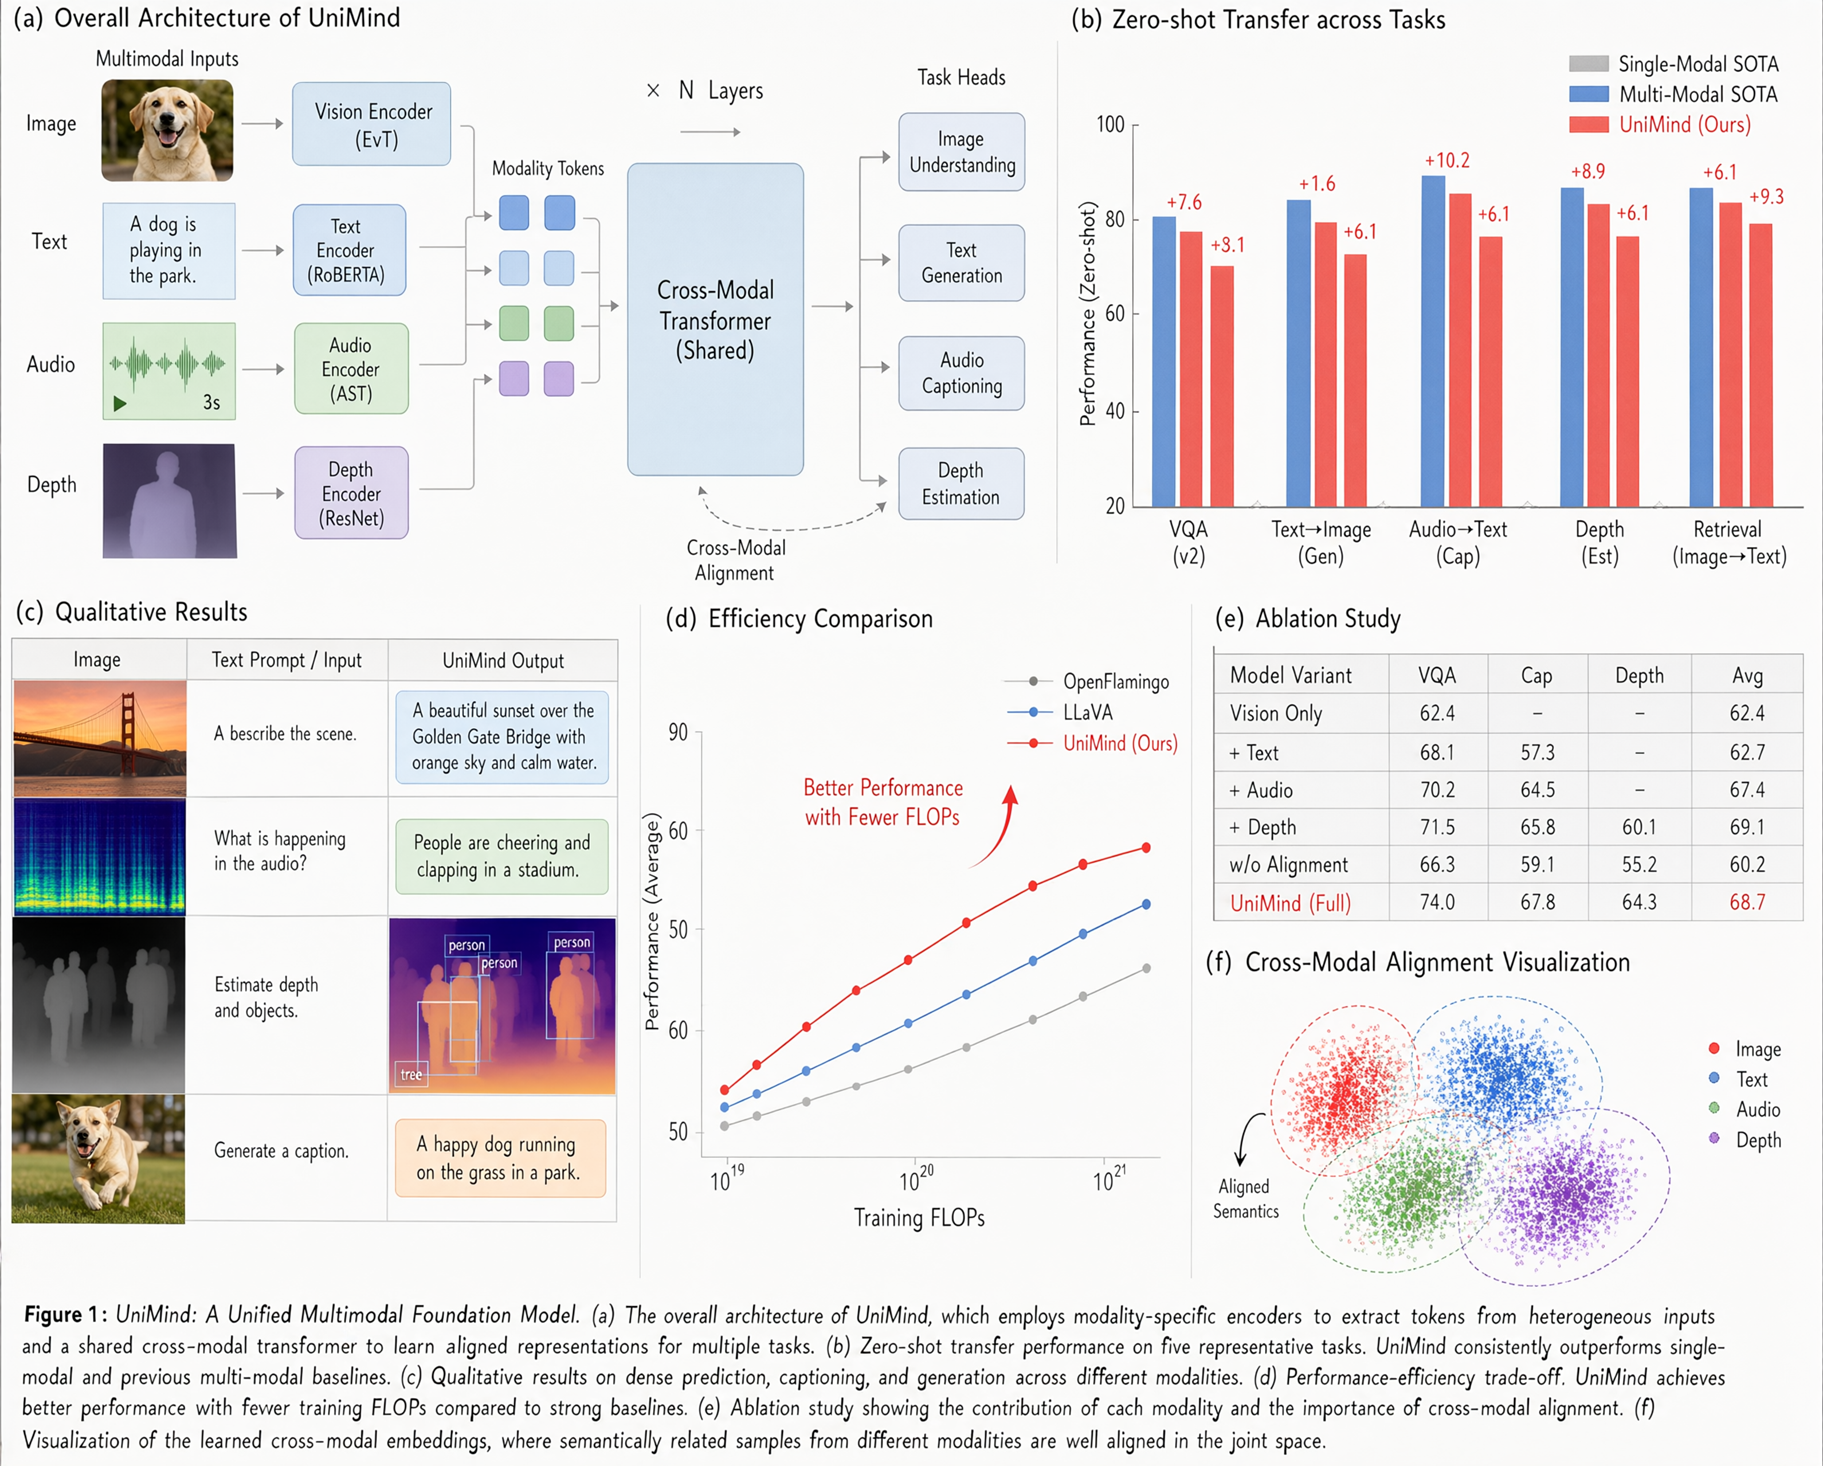
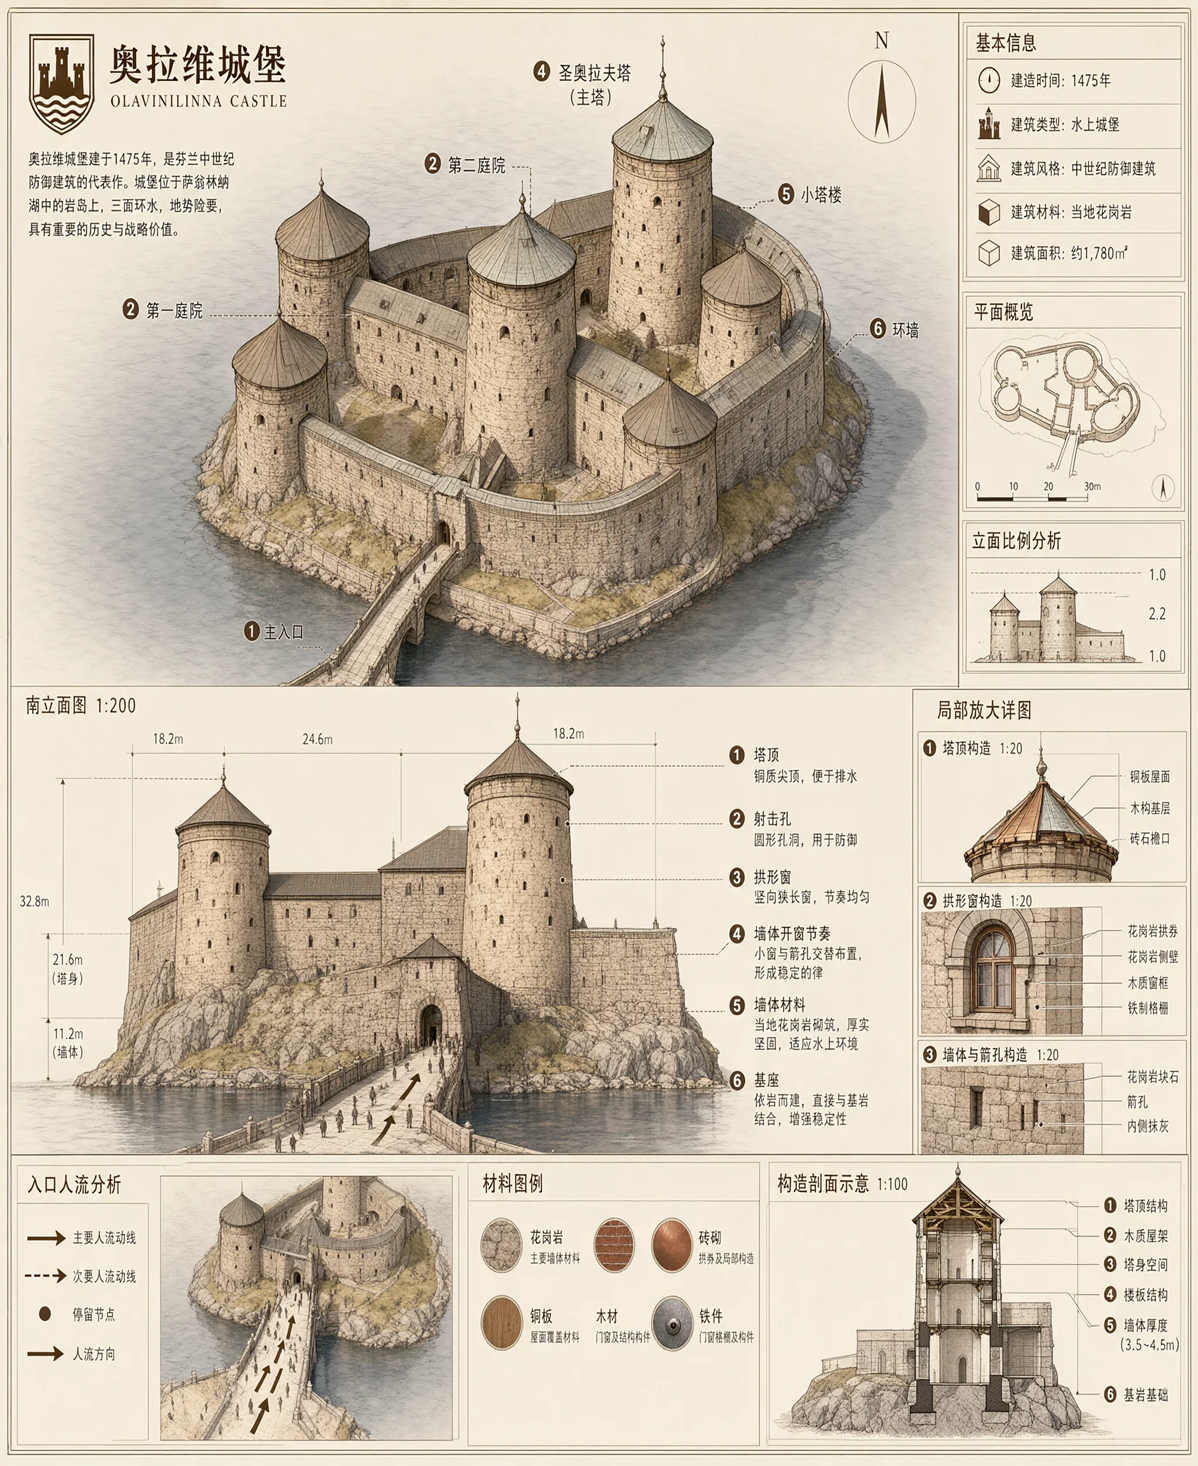
Text rendering
License
This model is licensed under the Qwen Research License Agreement.
- Downloads last month
- 546
3-bit
4-bit
5-bit
6-bit
8-bit
Model tree for vantagewithai/Qwen-Image-2.1-ComfyUI-GGUF
Base model
Qwen/Qwen-Image-2.1