

undyne
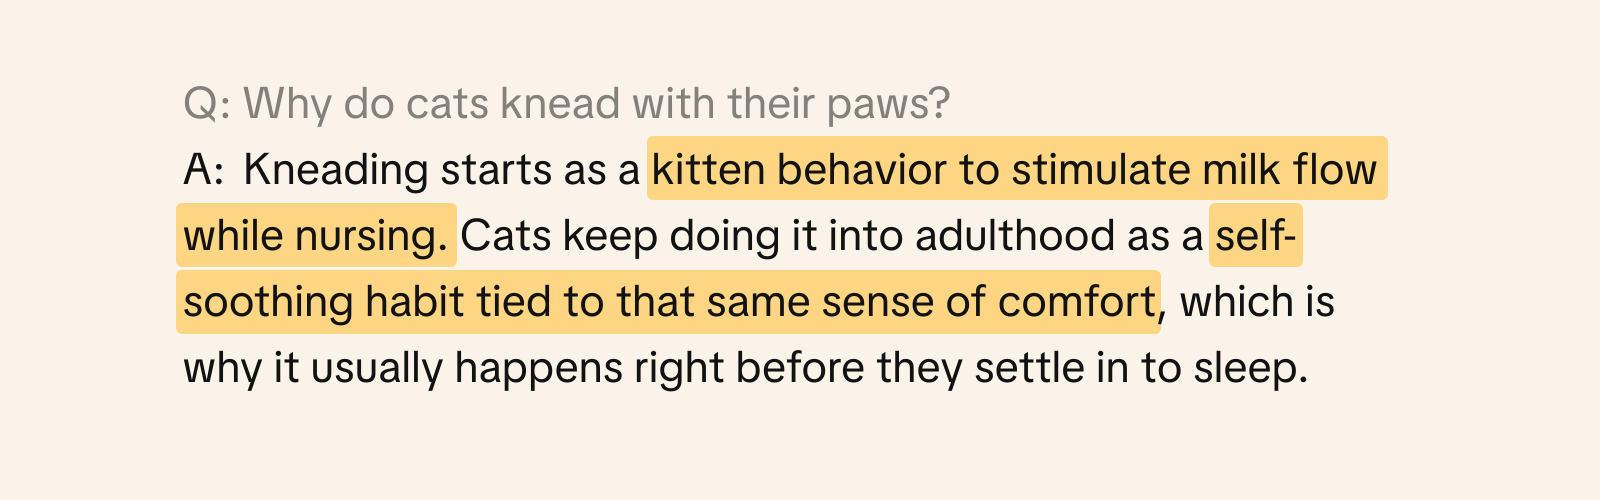
undyne is a 13.5m parameter model that highlights the answer to a question in a paragraph. if a question isn't present, it can also highlight the central claims.
examples
Why is the sky blue?
The sky is blue because of a phenomenon called Rayleigh scattering, named after the 19th-century British physicist Lord Rayleigh, who also discovered argon. Sunlight contains all colors of the visible spectrum, and when it hits molecules in Earth's atmosphere, shorter wavelengths like blue and violet scatter far more than longer wavelengths like red and orange.
Who is Rayleigh scattering named after?
The sky is blue because of a phenomenon called Rayleigh scattering, named after the 19th-century British physicist Lord Rayleigh, who also discovered argon. Sunlight contains all colors of the visible spectrum, and when it hits molecules in Earth's atmosphere, shorter wavelengths like blue and violet scatter far more than longer wavelengths like red and orange.
usage
you can find an example for usage in example.py.
from example import Undyne

m = Undyne("tiagozip/undyne")

m.spans(paragraph, "Why is the sky blue?") # [(46, 74), (210, 312)] char offsets
m.highlight(paragraph, "Why is the sky blue?") # markdown with ** ** around spans
m.highlight(paragraph) # no question, finds the central claim
i recommend using the onnx int8 version, as it's 14MB and agrees with fp32 on 98.6% of token labels while being about twice as fast.
limitations
english only. undyne sometimes works okay-ish on other languages, such as French and Spanish, but it was never trained on them.
trained on explainer prose, such as encyclopedia entries, assistant-style answers, and Wikipedia paragraphs. undyne degrades on text far from that, such as source code, dense tables, and poetry.
data provenance
training labels were scraped from multiple sources, such as Encyclopaedia Britannica article text, Wikipedia, synthetic data, and more. SQuAD v1.1: CC BY-SA 4.0, Rajpurkar et al., 2016. Base model: google/electra-small-discriminator (Apache 2.0)
- Downloads last month
- 21
Model tree for tiagozip/undyne
Base model
google/electra-small-discriminator