

t0 model family
Collection
Pretrained t0 forecasting models from The Forecasting Company, and the runtime artifacts to serve them. • 7 items • Updated • 5
t0-beta
t0-beta is an open-weights time-series forecasting foundation model from The Forecasting Company.
t0 is a transformer-based model that produces probabilistic multi-horizon forecasts and natively operates on multiple covariates. t0-beta is the second public iteration of the model.
It predicts 21 quantile levels natively, and is an incremental improvement over t0-alpha.
You can use t0 on Retrocast, The Forecasting Company's platform for forecasting on your own data and comparing forecasts across open-weight models.
Model family: t0-beta (PyTorch/MLX) · t0-alpha · Collection
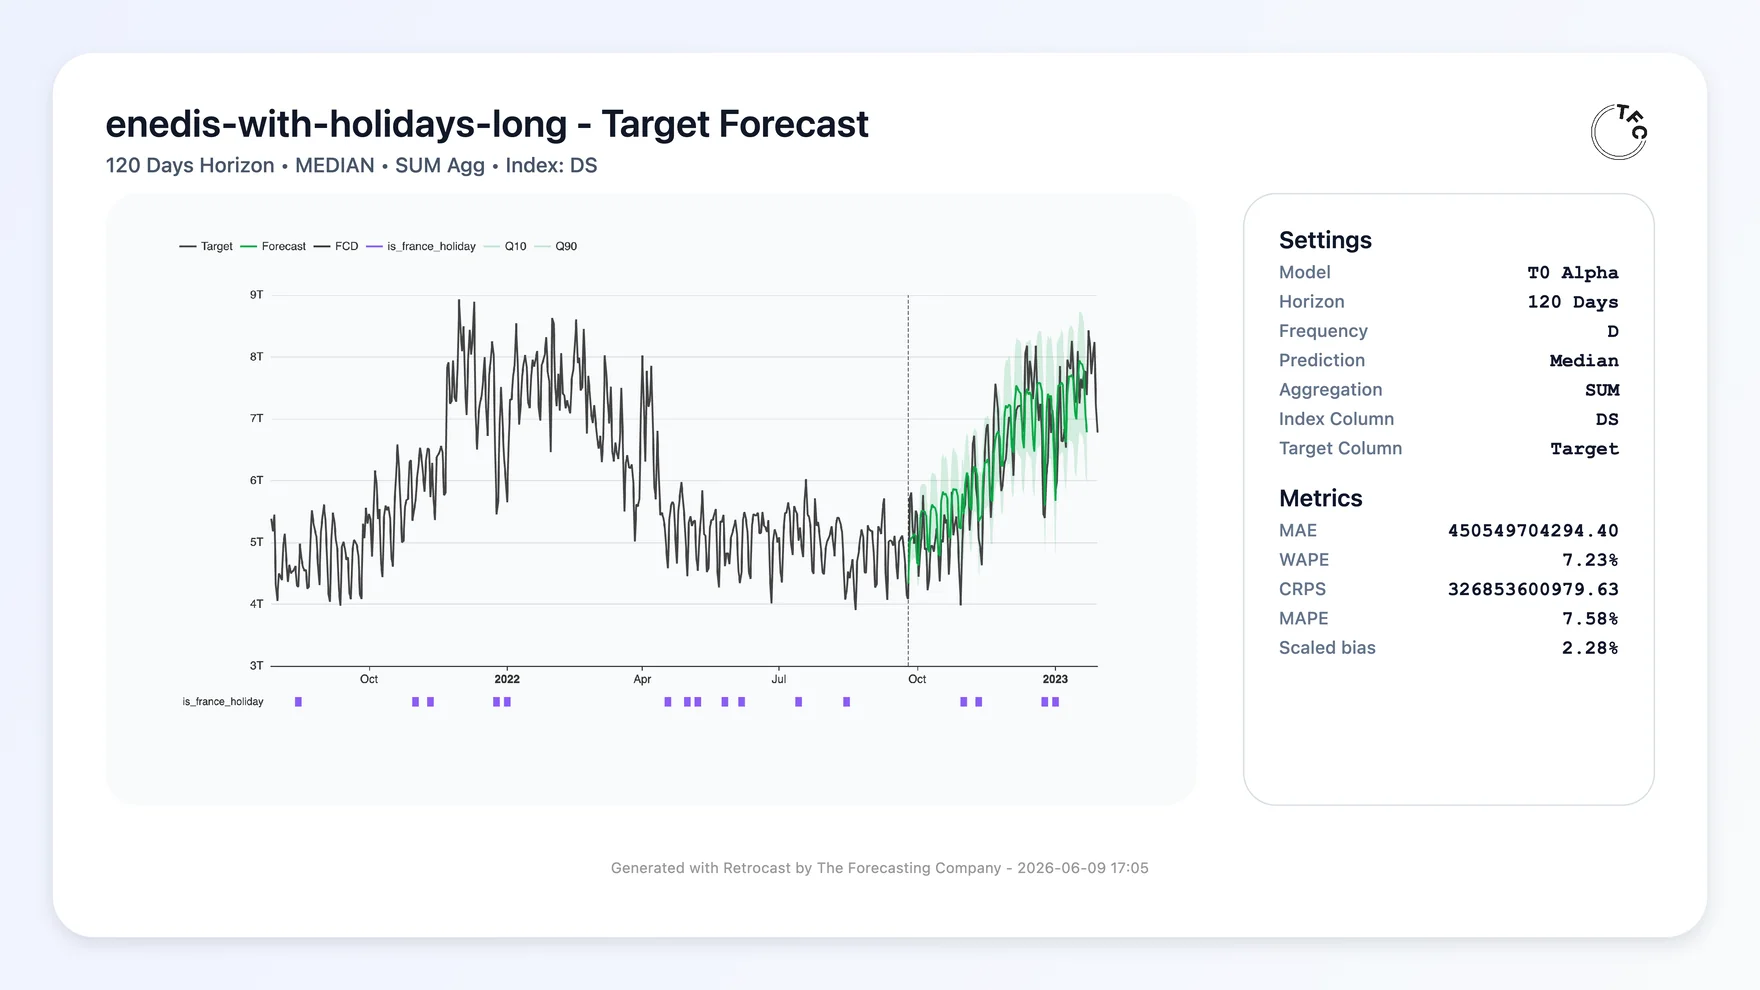
t0 forecasting French national electricity demand in Retrocast. Data: Enedis open data.
tfc-t0>=0.5.0 or tfc-t0-mlx>=0.1.0
t0-beta normalizes its inputs differently from t0-alpha, and the convention is carried in config.json as scaler_eps and scaler_eps_mode. Earlier releases of either runtime do not read those fields: they load these weights without error and run them under t0-alpha's normalization, which silently degrades the forecast. Pin the runtime:
pip install "tfc-t0>=0.5.0"        # PyTorch
pip install "tfc-t0-mlx>=0.1.0"    # MLX, Apple silicon
t0-betat0tfc-t0 >=0.5.0tfc-t0-mlx >=0.1.0t0-beta is a beta release intended for research, experimentation, and applied forecasting evaluation.
t0-beta is intended for probabilistic time-series forecasting. It can be used for univariate and multivariate forecasting, forecasting with historical or known-future covariates and multi-horizon forecasting.
Known-future covariates can include calendar features, planned events, holidays, promotions, weather forecasts, or other external signals available over the forecast horizon.
Forecasts should be treated as probabilistic estimates, not guarantees.
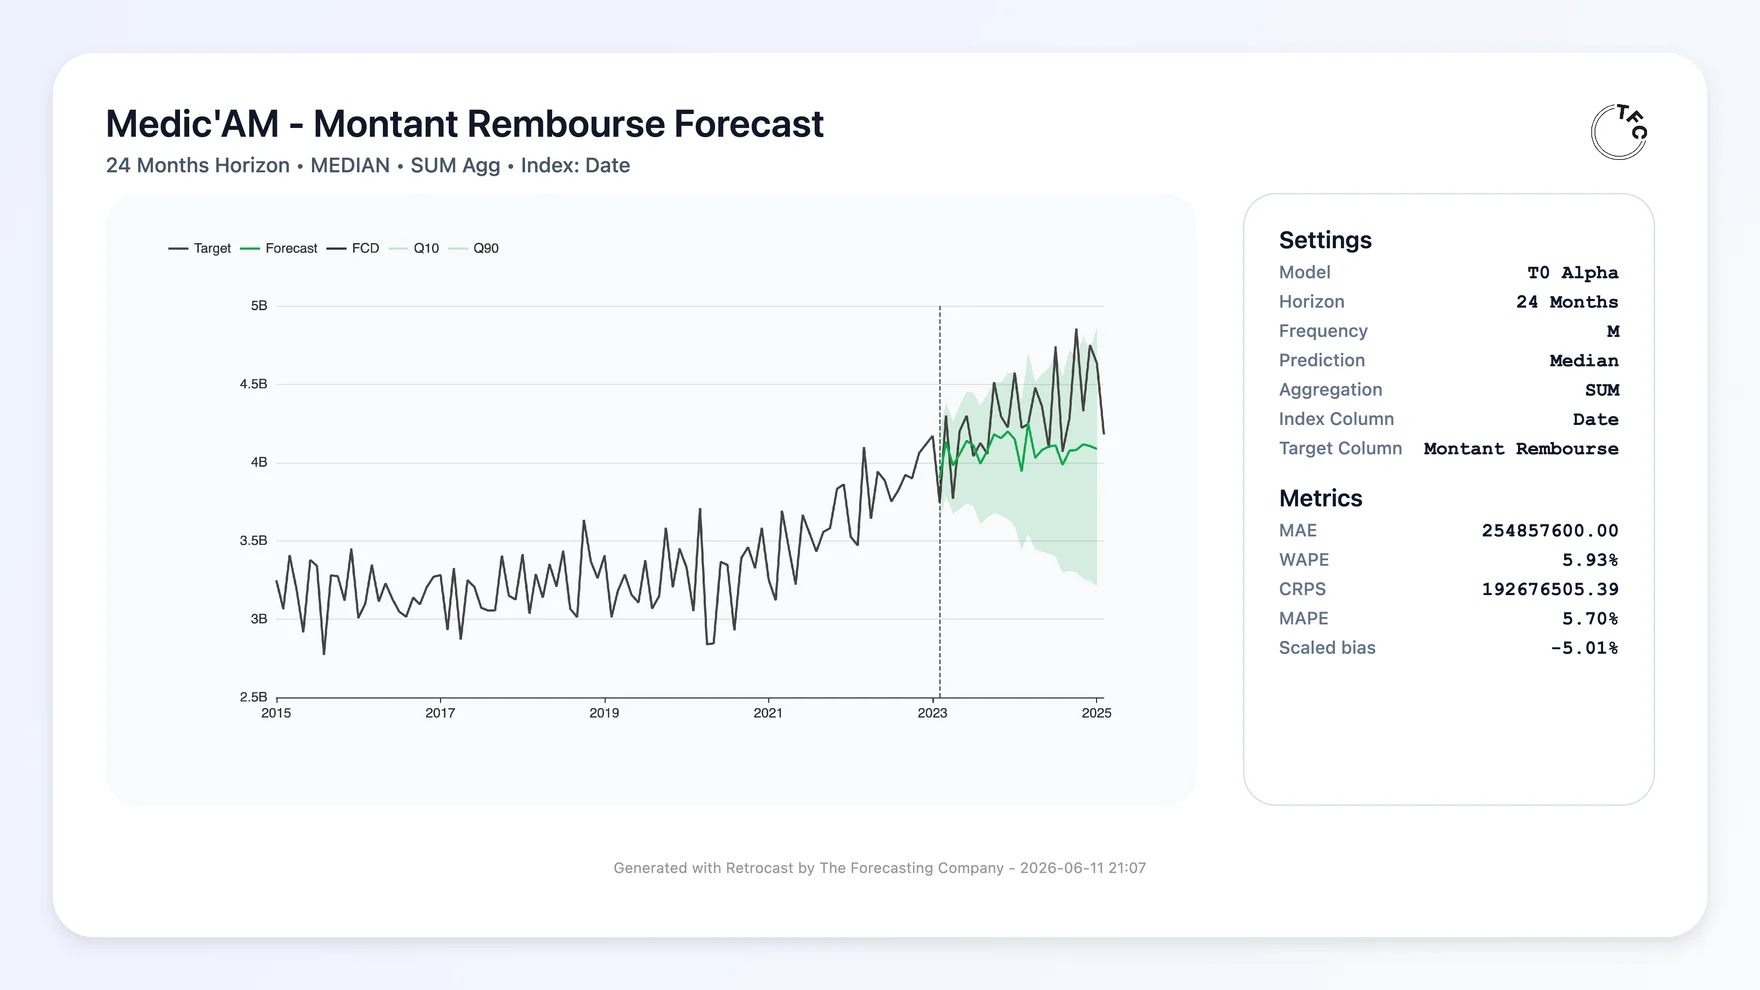
t0 leverages covariate information, in the past and future when available, to improve its forecast.
| Without covariates | With covariates |
|---|---|
 |
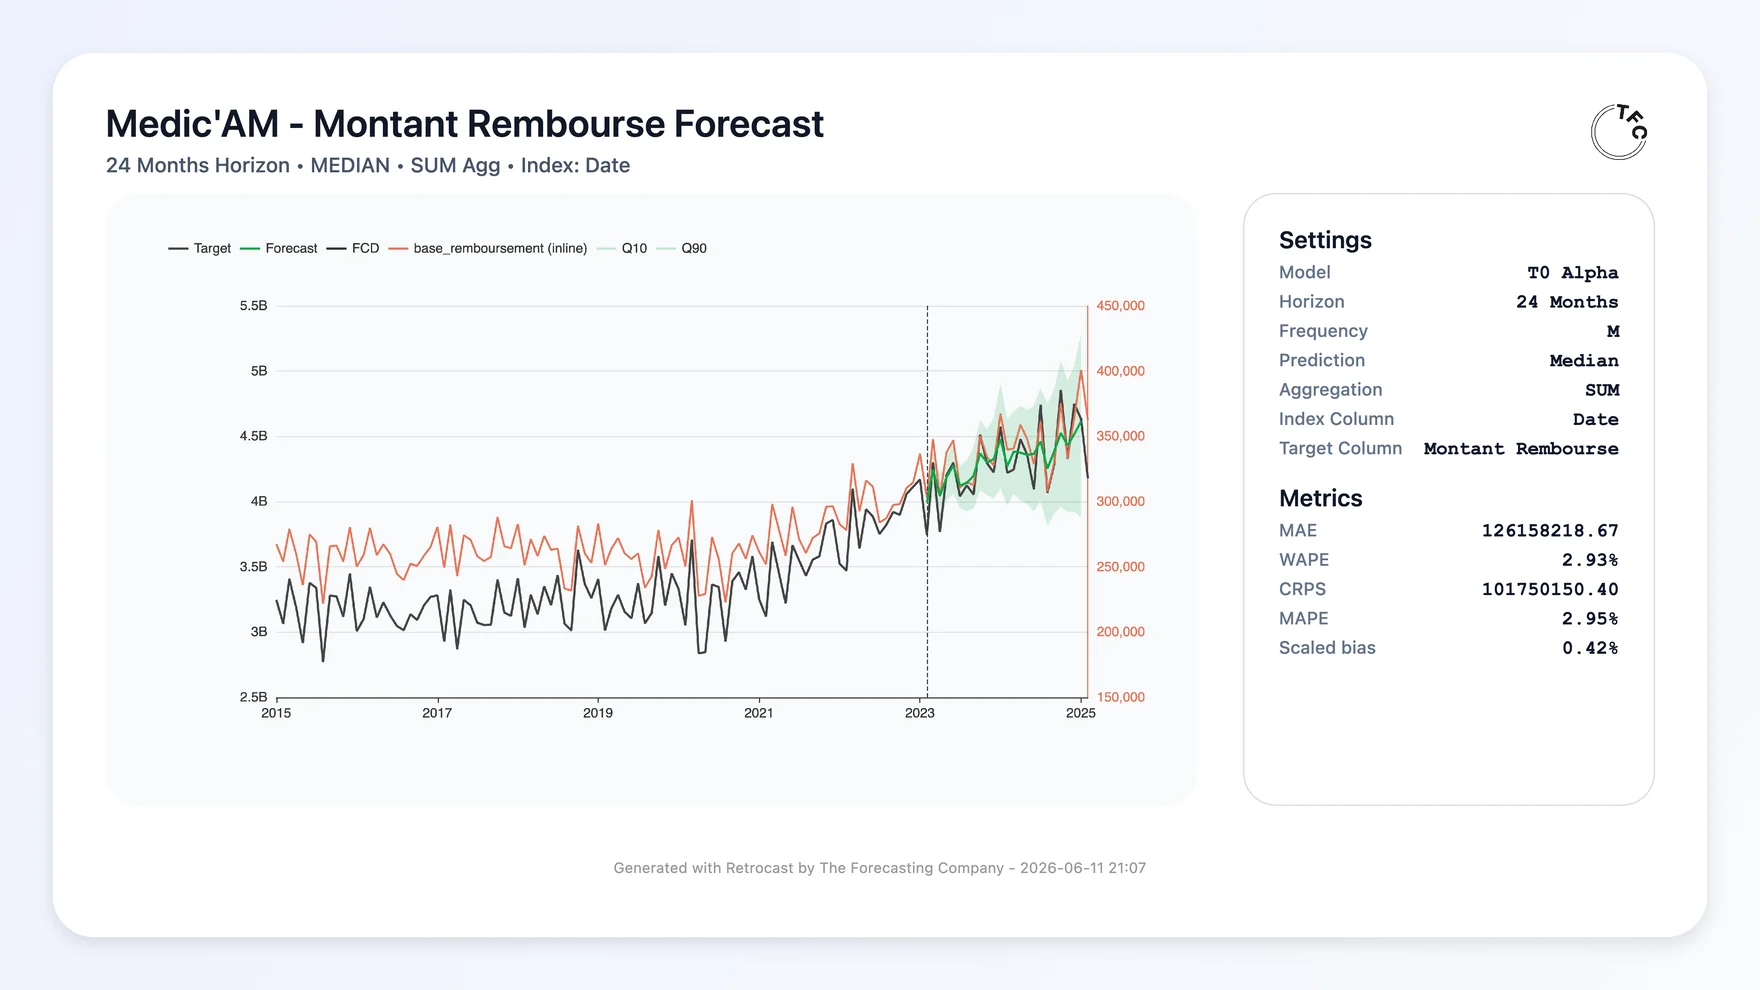 |
Data: Medic'AM, monthly drug reimbursements from the French national health insurance.
The Quickstart below shows the API for both a plain univariate forecast and a multivariate forecast that conditions on historical and known-future covariates.
Choose a runtime for the same original t0-beta checkpoint:
| Runtime | Best for | Install |
|---|---|---|
| PyTorch | Broad hardware support and the PyTorch ecosystem | pip install "tfc-t0>=0.5.0" |
| MLX | Local, inference-only use on Apple silicon | pip install "tfc-t0-mlx>=0.1.0" |
| Managed API | Hosted inference without local weights | theforecastingcompany SDK |
pip install "tfc-t0>=0.5.0"
Requirements:
>=3.10>=2.4Optional extras:
pip install "tfc-t0[evaluation]"
pip install "tfc-t0[plot]"
pip install "tfc-t0-mlx>=0.1.0"
The MLX package uses the same model repository, loads its safetensors
directly and does not install PyTorch. Authenticate with hf auth login
before the first download.
This model repository is private. Request access from The Forecasting Company, then authenticate with a token from the account that was granted it:
hf auth login
In a notebook, use from huggingface_hub import login; login() instead.
For scripts and CI, set HF_TOKEN in the environment. Signing in to the
website alone does not authenticate your Python environment.
The simplest path is a univariate forecast through predict:
import torch
from t0 import T0Forecaster

model = T0Forecaster.from_pretrained("theforecastingcompany/t0-beta", token=True).eval()

context = torch.randn(4, 512)  # 4 series, 512 past timesteps
out = model.predict(context, horizon=64, quantile_levels=[0.1, 0.5, 0.9])
out.quantiles  # (4, 64, 3)
out.median     # (4, 64)
predict accepts PyTorch tensors and NumPy arrays.
The MLX runtime deliberately follows the same forecasting interface:
import numpy as np
from t0_mlx import T0Forecaster

model = T0Forecaster.from_pretrained("theforecastingcompany/t0-beta").eval()
context = np.random.randn(4, 512).astype(np.float32)

out = model.predict(context, horizon=64, quantile_levels=[0.1, 0.5, 0.9])
out.quantiles.shape  # (4, 64, 3)
out.median.shape     # (4, 64)
See T0 for MLX for feature coverage, compilation guidance and reproducible Apple-silicon benchmarks.
Anything known over the past goes in context. Alongside the target, extra variates attend to it and are forecast together. Anything known over the future, such as calendar features, planned promotions, or weather forecasts, goes in future_covariates, shaped [B, F, context + horizon]. The model conditions on it but does not forecast it.
import torch
from t0 import T0Forecaster

model = T0Forecaster.from_pretrained("theforecastingcompany/t0-beta").eval()

context = torch.randn(2, 512)                    # 2 series, 512 past timesteps
future_covariates = torch.randn(2, 3, 512 + 64)  # 3 covariates known over context + horizon

out = model.predict(
    context,
    horizon=64,
    quantile_levels=[0.1, 0.5, 0.9],
    future_covariates=future_covariates,
)
out.quantiles  # (2, 64, 3)
out.median     # (2, 64)
import numpy as np
from t0 import T0Forecaster, batch_series

model = T0Forecaster.from_pretrained("theforecastingcompany/t0-beta").eval()

daily = np.random.randn(180)    # one series, 180 past timesteps
store = np.random.randn(2, 96)  # one series of 2 variates, 96 past timesteps
hourly = np.random.randn(1024)  # one series, 1024 past timesteps

context, mask, group_ids = batch_series([daily, store, hourly])
context.shape  # (4, 1024) — variates stacked, right-aligned to the longest series
group_ids      # [0, 1, 1, 2] — `store`'s two variates are forecast jointly

out = model.predict(context, horizon=24, quantile_levels=[0.1, 0.5, 0.9], mask=mask, group_ids=group_ids)
out.quantiles  # (4, 24, 3)
out.median[0]  # the 24-step median forecast for `daily`
Integrations that prepare complete T0 inputs, including known-future covariates, can batch the native representation directly:
from t0 import TimeSeries

first = TimeSeries.from_array(context_1, future_covariates_1)
second = TimeSeries.from_array(context_2, future_covariates_2)
batch = TimeSeries.batch([first, second])

out = model.predict(
    batch,
    horizon=64,
    context_length=max(context_1.shape[-1], context_2.shape[-1]),
)
Here each context includes its batch axis, for example [1, V, T], and each
known-future input is [1, F, T + horizon]. The output is ordered by the
flattened target rows in batch.
TimeSeries
TimeSeries is the model's native input. It holds target rows, known-future
covariate rows, a mask and group ids, all on one width. predict builds one for
you from a raw array. You only need to construct one yourself to batch inputs of
different widths, or to call forward directly.
from t0 import TimeSeries

# context only, with `horizon` marking the region to predict
model_input = TimeSeries.from_array(context, horizon=24)          # context: [B, V, T]

# with known-future covariates, whose width sets the horizon
model_input = TimeSeries.from_array(context, future_covariates)   # covariates: [B, F, T + 24]

out = model.predict(model_input, horizon=24, quantile_levels=[0.1, 0.5, 0.9])
predict infers context_length from where the forecast region starts. Pass it
explicitly when batching series of different widths. forward takes the same
TimeSeries and runs a single differentiable pass over it, with no rollout. That
is the entry point for fine-tuning.
For efficient inference at scale, look at Retrocast.
context may be shaped (B, T) for batched univariate forecasting.context may also be shaped (T,), which is promoted to a single-row batch.context may be shaped (B, V, T) for multiple target variates.future_covariates, when provided, should be shaped (B, F, context + horizon).mask, when provided, holds MaskType values shaped like context: MISSING for an absent observation, PAD for a cell that only widens a shorter series out to the batch's width.context is read as an absent observation. Padding is the case NaN cannot express, so a batch of unequal-length series needs a mask (or batch_series) to declare it.PAD stay out of attention.group_ids, when provided, holds one id per row of the context. Rows sharing an id are variates of one series and are forecast jointly.group_ids cannot be combined with future_covariates, which are addressed per sample.future_covariates is treated as missing.horizon must be at least 1.(0, 1).0.05 to 0.95 in steps of 0.05, plus 0.01 and 0.99 at the tails.float32 tensors on the model's device.t0 is a decoder-style patch transformer.
It encodes each patch from values, within-patch time index, and validity mask. The transformer alternates causal time-axis self-attention with variate-axis group self-attention. Time attention uses time-aware rotary embeddings. Variate attention lets variates in the same sample attend to one another. The stack uses pre-norm RMSNorm blocks, SwiGLU feed-forward layers, and a quantile head.
At inference, target and historical variates are normalized with causal running statistics. Future covariates use per-row global statistics.
| Field | Value |
|---|---|
| Parameters | approximately 256M |
| Layers | 24 |
| Layer pattern | 2 time-attention layers, then 1 group-attention layer |
| Time attention layers | 16 |
| Group attention layers | 8 |
| Embedding dim | 1024 |
| Feedforward dim | 2048 |
| Attention heads | 8 |
| Patch size | 32 |
| Dropout | 0.1 |
| Scaler | causal mean/std with arcsinh transform |
| Native quantile levels | 21, from 0.01 to 0.99 |
t0-beta improves on t0-alpha on every benchmark we report. Lower is better for CRPS and MASE; higher is better for skill score.
| Benchmark | Metric | t0-beta |
t0-alpha |
|---|---|---|---|
| GIFT-Eval | CRPS | 0.4738 | 0.4941 |
| GIFT-Eval | MASE | 0.6865 | 0.7240 |
| fev-bench | Skill score | 46.37 | 42.20 |
GIFT-Eval figures are the normalized geometric means over all 97 configurations, as computed by the GIFT-Eval leaderboard. The fev-bench skill score is measured against Seasonal Naive on the fev-bench leaderboard, so it does not move when other models join the board.
Users should also evaluate t0-beta on their own historical backtests. Useful checks include quantile loss, CRPS, MASE, empirical quantile coverage, calibration, and breakdowns by frequency, horizon, domain, history length, and covariate availability.
T0Forecaster: the model itself.Forecast: the object returned by the model.T0Config: the configuration of the model.MaskType: the reason a time step is masked out.VariateType: whether a row is a target, a historical covariate or a
known-future covariate.batch_series: utility to batch time series of potentially different lengths.TimeSeries.from_array / TimeSeries.batch: build the model's native input,
including known-future covariates and an explicit forecast horizon.
predict accepts either a TimeSeries or a raw context array.t0-beta continues the line started by t0-alpha, the first public iteration of t0, and keeps its architecture and interface.
t0 builds on ideas from open-source forecasting models. We gratefully acknowledge:
Code-level attributions are listed in NOTICE, all under Apache-2.0.
Training compute and carbon emissions are not currently reported.
@misc{tfc-t0,
  title  = {t0: A time-series forecasting foundation model},
  author = {The Forecasting Company},
  year   = {2026},
  url    = {https://huggingface.co/theforecastingcompany/t0-beta},
}
Apache-2.0. See LICENSE and NOTICE.
For issues and bug reports, use the tracker for the relevant runtime:
Quantized