

Diffusion Research
Collection
Research work on Guidance and test-time search for diffusion models, efficient sampling, post-training, RL, perceptual quality,HDR-UGC video quality, • 22 items • Updated • 1
Diffusers pipelines for Rectified-CFG++, a training-free guidance method for rectified-flow models (NeurIPS 2025).
This repo has no weights. It holds pipeline code that you load on top of an existing checkpoint with custom_pipeline.
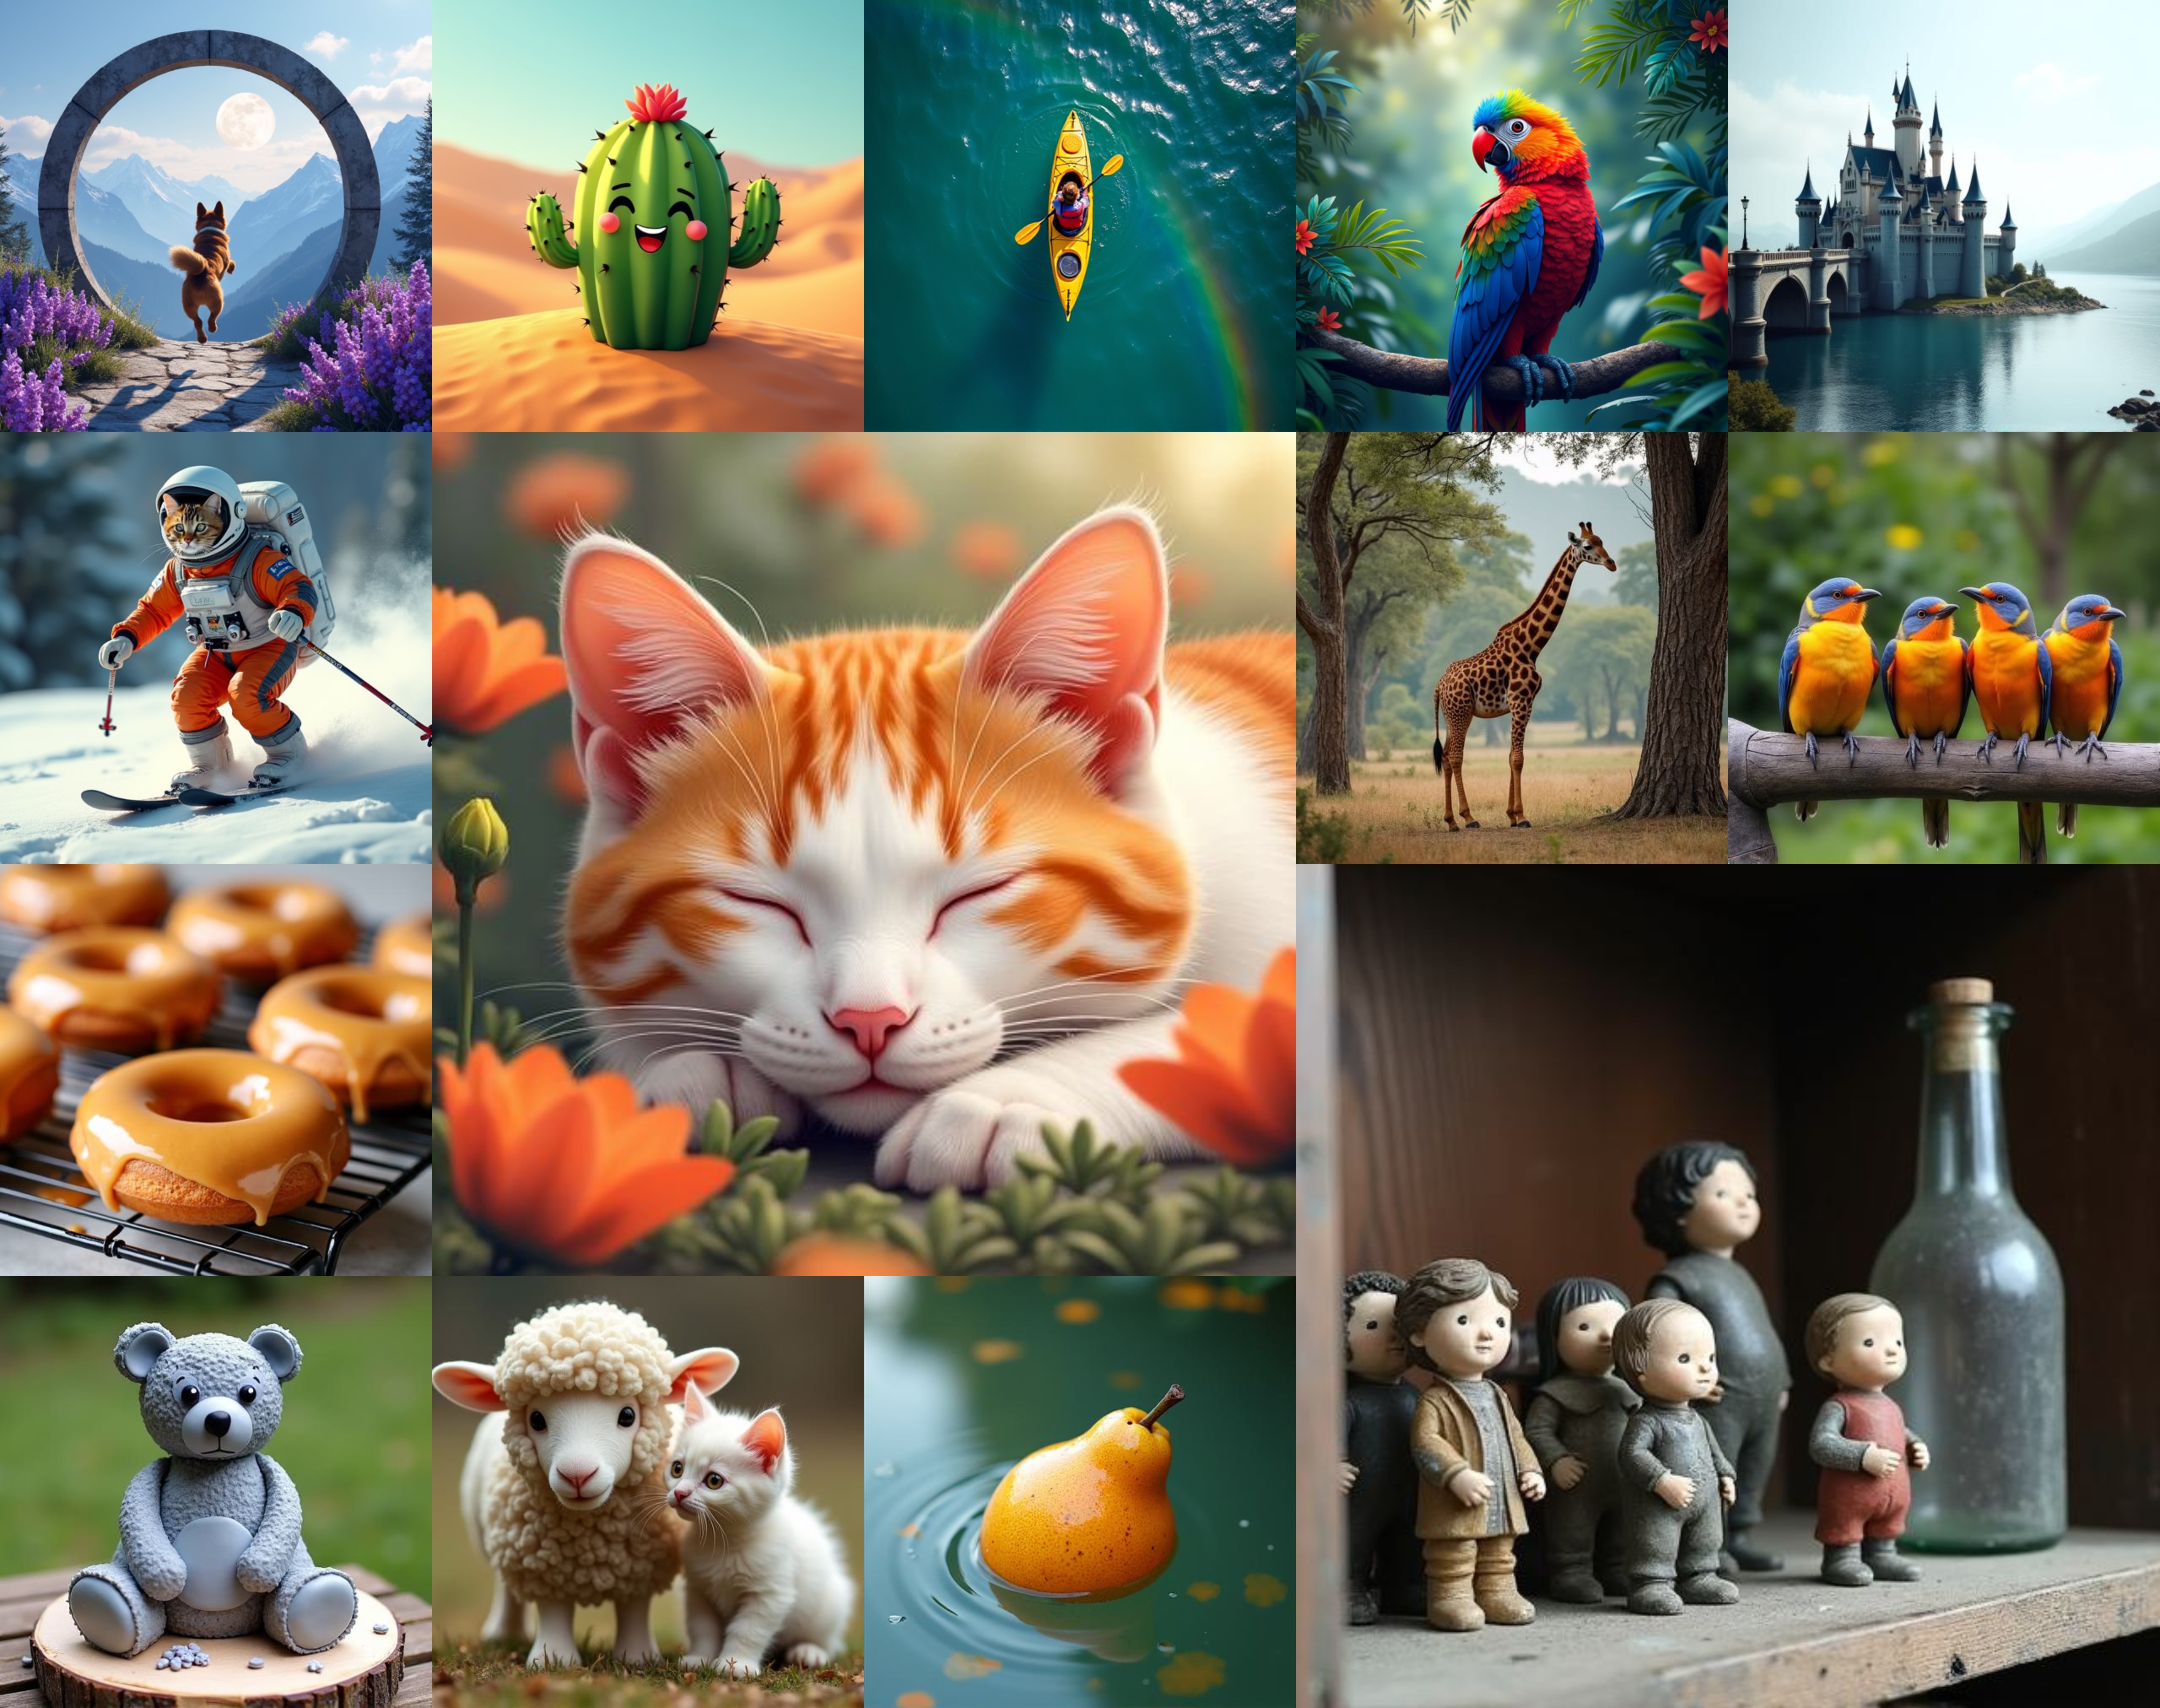
Classifier-free guidance (CFG) extrapolates from the unconditional velocity toward the conditional one at every ODE step. On rectified-flow models this extrapolation pushes samples off the learned data manifold, and at high guidance scales the images show over-saturated colours and broken structure.
Rectified-CFG++ replaces that extrapolation with a predictor-corrector update:
The update stays close to the conditional flow, so prompt alignment holds at high guidance scales without those artifacts. No training or fine-tuning is involved, and the method applies to any rectified-flow backbone.
Each step costs three model evaluations (one conditional pass at the current point, then one conditional and one unconditional pass at the predicted point), against two for standard CFG.
| Backbone | File | Pipeline class | Guidance argument |
|---|---|---|---|
| Stable Diffusion 3 / 3.5 | pipeline.py |
StableDiffusion3RectifiedCFGPlusPlusPipeline |
guidance_scale (default 4.5) |
| Flux (FLUX.1-dev, FLUX.1-schnell) | pipeline_flux_rectified_cfgpp.py |
FluxRectifiedCFGPlusPlusPipeline |
true_cfg_scale with a negative_prompt (an empty string works). guidance_scale stays the distilled guidance embedding. |
| Lumina-Image-2.0 | pipeline_lumina2_rectified_cfgpp.py |
Lumina2RectifiedCFGPlusPlusPipeline |
guidance_scale (default 4.0) |
| Qwen-Image | pipeline_qwenimage_rectified_cfgpp.py |
QwenImageRectifiedCFGPlusPlusPipeline |
true_cfg_scale (default 4.0) with a negative_prompt |
| Wan 2.1 / 2.2 (video) | pipeline_wan_rectified_cfgpp.py |
WanRectifiedCFGPlusPlusPipeline |
guidance_scale (default 5.0), and guidance_scale_2 for Wan 2.2 two-stage checkpoints |
Every pipeline keeps the arguments of its upstream diffusers counterpart and adds one: sigma_noise (default 0.005), the standard deviation of the Gaussian noise added to the predicted point before the corrector evaluation. Set it to 0 to turn the noise off. With guidance off (guidance_scale <= 1, or true_cfg_scale <= 1 for Flux and Qwen-Image) the pipelines run plain conditional sampling.
Install the dependencies:
pip install -U diffusers transformers accelerate sentencepiece protobuf
diffusers runs the pipeline file as Python code, so recent versions require trust_remote_code=True. Read the file first if you want to see what it does.
pipeline.py at the root of this repo is the SD3 / SD3.5 pipeline, so the repo id is enough:
import torch
from diffusers import DiffusionPipeline

pipe = DiffusionPipeline.from_pretrained(
    "stabilityai/stable-diffusion-3.5-large",
    custom_pipeline="shreshthsaini/Rectified-CFGpp",
    trust_remote_code=True,
    torch_dtype=torch.bfloat16,
).to("cuda")

image = pipe(
    "A magical forest at twilight with glowing fireflies",
    negative_prompt="",
    guidance_scale=4.5,
    num_inference_steps=28,
    sigma_noise=0.005,
    height=1024,
    width=1024,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]
image.save("rectified_cfgpp_sd35.png")
custom_pipeline with a repo id only reads pipeline.py. For the other backbones, download the file and pass its local path:
import torch
from diffusers import DiffusionPipeline
from huggingface_hub import hf_hub_download

path = hf_hub_download("shreshthsaini/Rectified-CFGpp", "pipeline_flux_rectified_cfgpp.py")

pipe = DiffusionPipeline.from_pretrained(
    "black-forest-labs/FLUX.1-dev",
    custom_pipeline=path,
    trust_remote_code=True,
    torch_dtype=torch.bfloat16,
).to("cuda")

image = pipe(
    "A red fox standing on a mossy log in a misty pine forest, morning light, photograph",
    negative_prompt="",
    true_cfg_scale=4.5,
    guidance_scale=3.5,
    num_inference_steps=28,
).images[0]
image.save("rectified_cfgpp_flux.png")
Swap the file name and the base checkpoint for the other backbones:
| File | Example checkpoint | Example call arguments |
|---|---|---|
pipeline_lumina2_rectified_cfgpp.py |
Alpha-VLLM/Lumina-Image-2.0 |
guidance_scale=4.0, num_inference_steps=50 |
pipeline_qwenimage_rectified_cfgpp.py |
Qwen/Qwen-Image |
negative_prompt=" ", true_cfg_scale=4.0, num_inference_steps=50 |
pipeline_wan_rectified_cfgpp.py |
Wan-AI/Wan2.1-T2V-1.3B-Diffusers |
negative_prompt="blurry, low quality", height=480, width=832, num_frames=81, guidance_scale=5.0, num_inference_steps=50 |
The predictor takes a flow-matching Euler step, so the pipelines expect FlowMatchEulerDiscreteScheduler. Wan checkpoints ship with a multistep scheduler. Replace it after loading:
from diffusers import FlowMatchEulerDiscreteScheduler

pipe.scheduler = FlowMatchEulerDiscreteScheduler.from_config(pipe.scheduler.config, shift=5.0)
The Wan pipeline returns video frames in .frames[0]. Save them with diffusers.utils.export_to_video(frames, "out.mp4", fps=16).
This runs in a few seconds without a GPU. It uses a tiny random checkpoint, so the image is noise. It only confirms that the pipeline loads and samples.
import torch
from diffusers import DiffusionPipeline

pipe = DiffusionPipeline.from_pretrained(
    "hf-internal-testing/tiny-sd35-pipe",
    custom_pipeline="shreshthsaini/Rectified-CFGpp",
    trust_remote_code=True,
)
image = pipe(
    "a photo of a cat",
    guidance_scale=4.5,
    num_inference_steps=2,
    height=64,
    width=64,
    generator=torch.Generator().manual_seed(0),
).images[0]
print(type(pipe).__name__, image.size)
# StableDiffusion3RectifiedCFGPlusPlusPipeline (64, 64)
The official demo script uses these values with stabilityai/stable-diffusion-3.5-large:
| Setting | Value |
|---|---|
| Guidance scale | 4.5 |
| Inference steps | 28 |
sigma_noise |
0.005 |
| Resolution | 1024 x 1024 |
| dtype | torch.bfloat16 |
The reference implementation on GitHub names the guidance argument true_cfg. The SD3 pipeline here uses the standard diffusers name, guidance_scale, for the same quantity.
Loading and sampling were tested on CPU with diffusers 0.41.0, torch 2.14.1 and transformers 5.19.0, two inference steps per run, against these tiny random checkpoints:
| Pipeline | Checkpoint | Load path |
|---|---|---|
| SD3 | hf-internal-testing/tiny-sd3-pipe |
repo id |
| SD3.5 | hf-internal-testing/tiny-sd35-pipe |
repo id |
| Flux | hf-internal-testing/tiny-flux-pipe |
hf_hub_download + local path |
| Lumina 2 | hf-internal-testing/tiny-lumina2-pipe |
hf_hub_download + local path |
| Qwen-Image | hf-internal-testing/tiny-qwenimage-pipe |
hf_hub_download + local path |
| Wan | hf-internal-testing/tiny-wan-pipe |
hf_hub_download + local path |
These runs check that the code loads, runs, returns finite outputs and responds to the guidance scale. They say nothing about image quality. The full-size examples above follow the same load paths but were not run as part of this check. For the experiments in the paper, use the GitHub repo.
The same pipelines are proposed for the diffusers community folder in huggingface/diffusers#14726. That pull request was open, not merged, as of October 2026.
@inproceedings{saini2025rectifiedcfgpp,
  title     = {Rectified-CFG++ for Flow Based Models},
  author    = {Shreshth Saini and Shashank Gupta and Alan C. Bovik},
  booktitle = {Advances in Neural Information Processing Systems},
  year      = {2025}
}
MIT, see LICENSE. The pipeline files are adapted from diffusers and keep its Apache-2.0 file headers.