

qwen3-4b-system-one-lora
Tree-masked multi-question inference is the defining feature of this System 1-inspired Qwen3-4B LoRA adapter: one shared record, multiple independently answered questions, one model forward pass.
Source code and verification: github.com/senna-lang/qwen3-4b-system-one is the canonical home of the inference code, packaged for pip install, together with a public fictional fixture and scripts that check branch isolation and PyTorch/MLX agreement. The Python files in this repository are a standalone copy of that code.
Accuracy
Zero-shot accuracy on public datasets that were not used for training or model selection (500 rows each, sampled with a fixed seed; protocol fixed before the run):
| Dataset | Task | Type | Accuracy | 95% CI |
|---|---|---|---|---|
| AG News | news topic | choice, 4 options | 0.896 | 0.868–0.922 |
| MASSIVE (en-US) | voice-assistant scenario | choice, 18 options | 0.604 | 0.564–0.646 |
| MNLI (matched) | entailment / neutral / contradiction | choice, 3 options | 0.860 | 0.828–0.888 |
| BoolQ | yes/no question about a passage | noul | 0.896 | 0.868–0.922 |
| SST-5 | 5-level sentiment | score, 5 levels | 0.474 | 0.432–0.516 |
SST-5 mean absolute error: 0.65 levels. Measured with the GitHub package (one canonical option order, PyTorch, RTX 4090). Protocol, base-model comparison, and row-level predictions: docs/BENCHMARKS.md and results/accuracy/.
What is distributed
This repository contains a LoRA adapter for Qwen/Qwen3-4B-Instruct-2507, standalone PyTorch and Apple Silicon MLX inference code, and an Apache-2.0 license. It does not contain Qwen base weights, training examples, teacher outputs, or private evaluations. The base model downloads from Qwen's repository on first use. The Qwen backbone and native LM head remain frozen; the LoRA adapter modifies the backbone's linear projections (rank 16, alpha 32).
Architecture: shared prefix, isolated branches
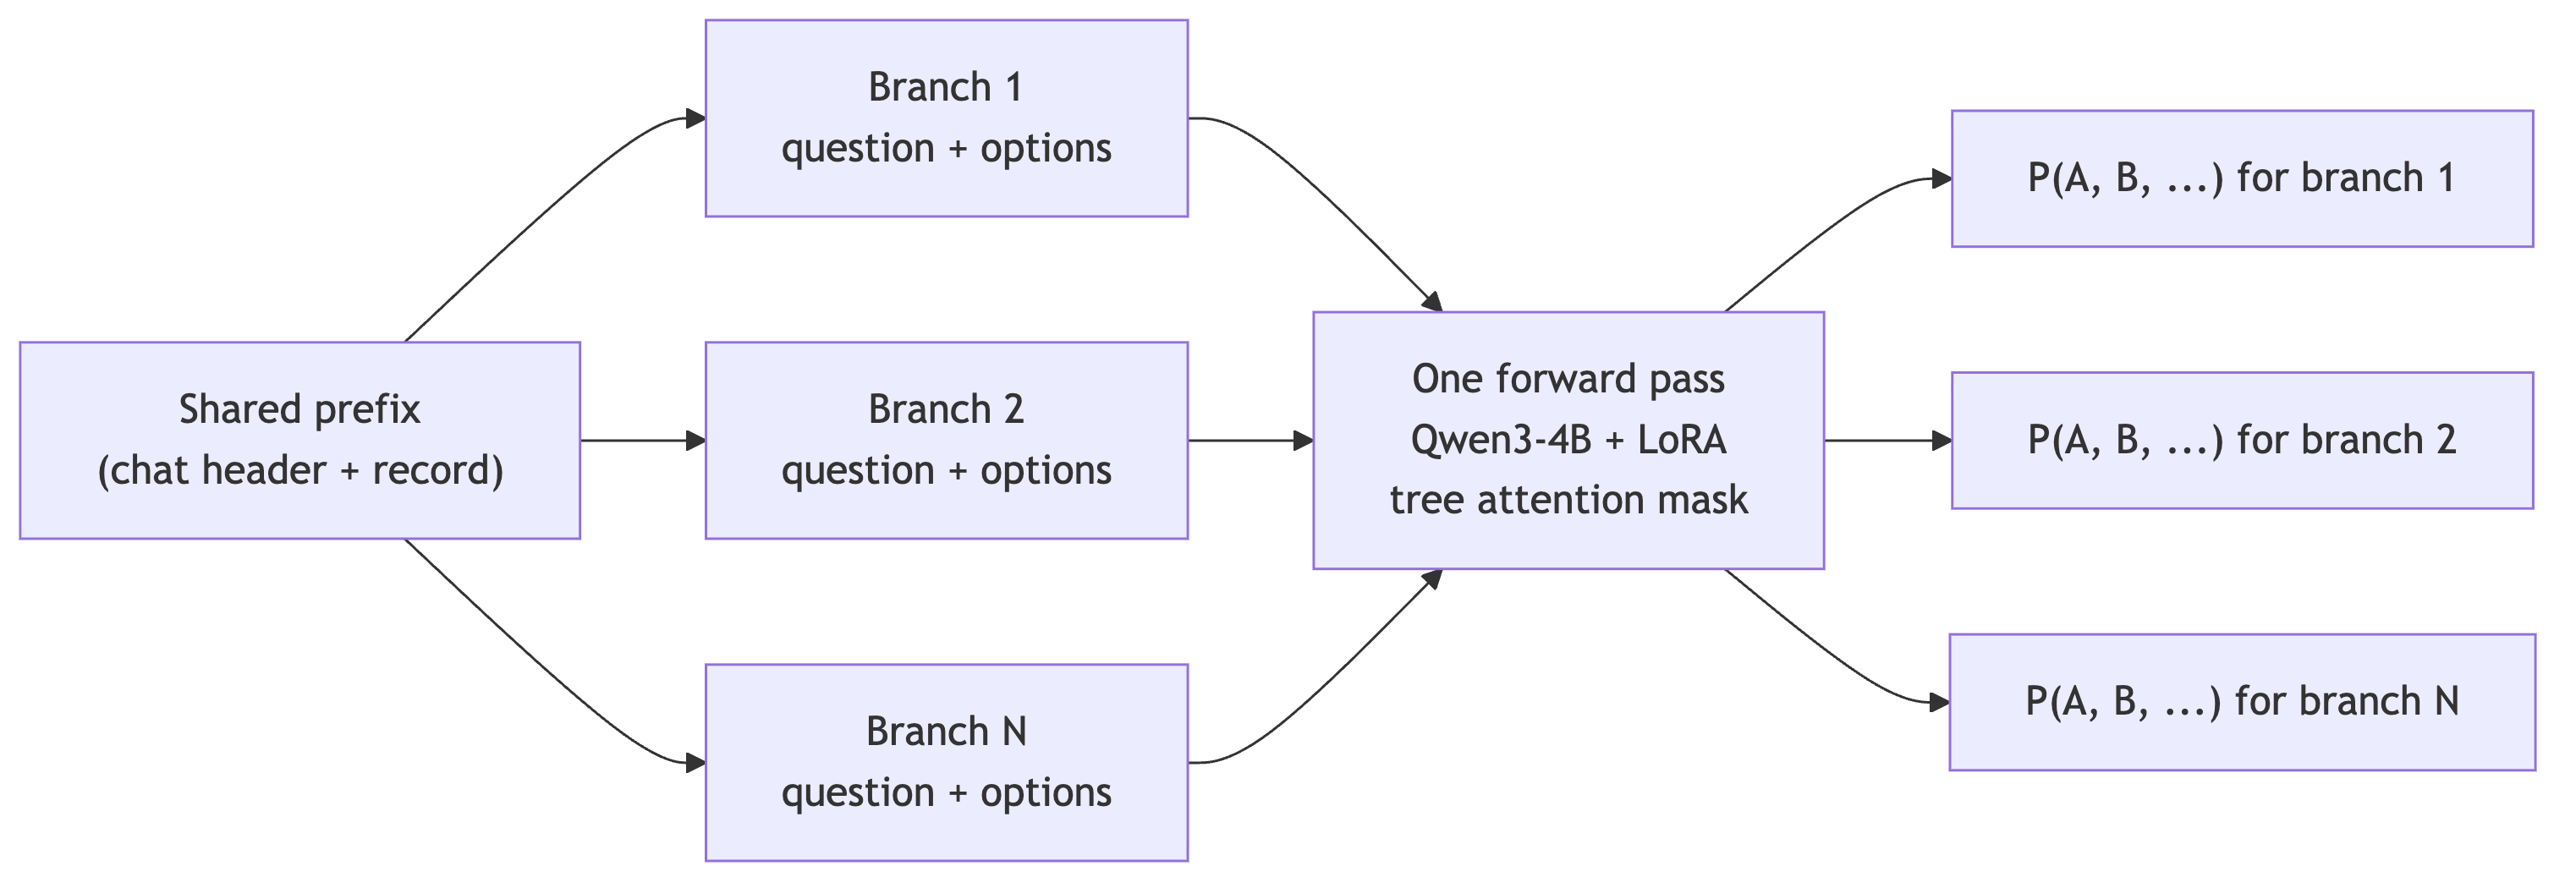
Packed sequence and attention (✓ = may attend):
| query \ key | prefix | branch 1 | branch 2 |
|---|---|---|---|
| prefix | ✓ | ||
| branch 1 | ✓ | ✓ | |
| branch 2 | ✓ | ✓ | |
| position IDs | 0 … S−1 | S, S+1, … | S, S+1, … |
Causal order applies within each cell; S is the shared-prefix length.
Each question is rendered as a Qwen Instruct prompt. The prompts' common token prefix (including the record) is stored once; their question-and-option suffixes become separate branches. A causal tree attention mask lets each branch attend to that shared prefix and its own earlier tokens, but never to another branch. Position IDs restart after the prefix for every branch. The packed request is processed in one forward pass, then the frozen native LM head provides answer-letter probabilities for each question.
This is distinct from independently re-encoding the record for every question or merely batching separate prompts. Both backends share packing.py; the tree attention masks are built in inference.py and inference_mlx.py, not encoded in the LoRA weights. Loading the adapter into an ordinary text-generation pipeline will not reproduce this behavior. Both implementations build dense attention masks, so efficiency at longer packed lengths or larger question counts should be measured rather than assumed.
Use
Download this entire repository. For PyTorch, install requirements.txt and run from the downloaded directory:
python -m pip install -r requirements.txt
python inference.py
The script loads the official Qwen base and the local adapter, then prints probabilities for two fictional questions. To call it from Python:
from inference import Branch, PackedRequest, load_model, predict_request

model, tokenizer = load_model(".")
request = PackedRequest(
    state="A customer received a replacement device after the first one stopped charging.",
    branches=[
        Branch("choice", "Which issue is described?", ["Delivery delay", "Charging failure", "Billing error"]),
        Branch("noul", "Does the record mention a replacement?"),
    ],
)
probabilities = predict_request(model, tokenizer, request)
# probabilities[0]: [P(Delivery delay), P(Charging failure), P(Billing error)]
# probabilities[1]: [P(No), P(Yes)]
Input is one state plus one or more branches. choice and score branches take an instructions string and 2–20 ordered options; for score, options describe ordered rating levels. noul uses the fixed [No, Yes] answer pair (leave options empty). The output is one probability vector per branch, aligned to input order. For an expected score, calculate sum(level * probability) over your own level values. These are conditional probabilities over listed answer letters, not calibrated unconditional probabilities.
The public path uses one canonical option order (no option-order averaging). Do not substitute a standard text-generation pipeline: it does not implement the tree packing and answer-letter readout.
Apple Silicon (MLX)
On a Mac with Apple silicon, install requirements-mlx.txt instead of the PyTorch requirements and run from this directory:
python -m pip install -r requirements-mlx.txt
python inference_mlx.py
The MLX example uses the same fictional request and the same Branch / PackedRequest and load_model / predict_request API (import them from inference_mlx instead). Both backends use the shared packing.py, single canonical option order, and one tree-masked forward pass. The base model is fetched from Qwen's repository and the local LoRA adapter is merged in memory at load time; no merged base weights are redistributed. MLX requires Apple silicon, and small probability differences from PyTorch are expected because it uses fp16 weights and a different execution backend.
Evaluation
Teacher-distribution test: 1,200 held-out branches (397 Choice, 448 Score, 355 Noul). Top-1 measures agreement with the highest-probability answer in the DeepSeek Flash teacher distribution; Brier, NLL, and ECE compare the predicted probabilities with those teacher distributions, not with human ground truth. Both rows below use the same prompts and data. For this evaluation, option-order variants (four for Choice/Score, two for Noul) were packed as extra branches into one model forward pass per request, then their probabilities were averaged; this does not mean four separate forwards or four API calls.
| Model | Teacher top-1 ↑ | Brier ↓ | NLL ↓ | ECE ↓ |
|---|---|---|---|---|
| Qwen3-4B-Instruct-2507 without adapter | 0.8417 | 0.0663 | 1.374 | 0.102 |
| Selected LoRA | 0.8792 | 0.0369 | 0.326 | 0.030 |
The prespecified E2 acceptance threshold required at least a 5 percentage point top-1 gain; the observed gain was 3.75 points, so this criterion was not met. The release's inference.py instead uses a single canonical order. On the same 1,200 branches, that LoRA path measured top-1 0.8767, Brier 0.0391, NLL 0.344, ECE 0.032; do not compare those numbers to the base row above, which uses order averaging.
Separate small final evaluation: On 60 English-translated, privately held-out records (90 branches), after the checkpoint was fixed, the order-averaged adapter scored Choice 0.950 (40 questions), Score 0.733 (30), Noul 0.800 (20). The corresponding unadapted Qwen results were 0.975 / 0.733 / 0.850. This is not a public, independently reproducible benchmark; the examples are not distributed, the sample is small, and these values do not describe the single-order release example.
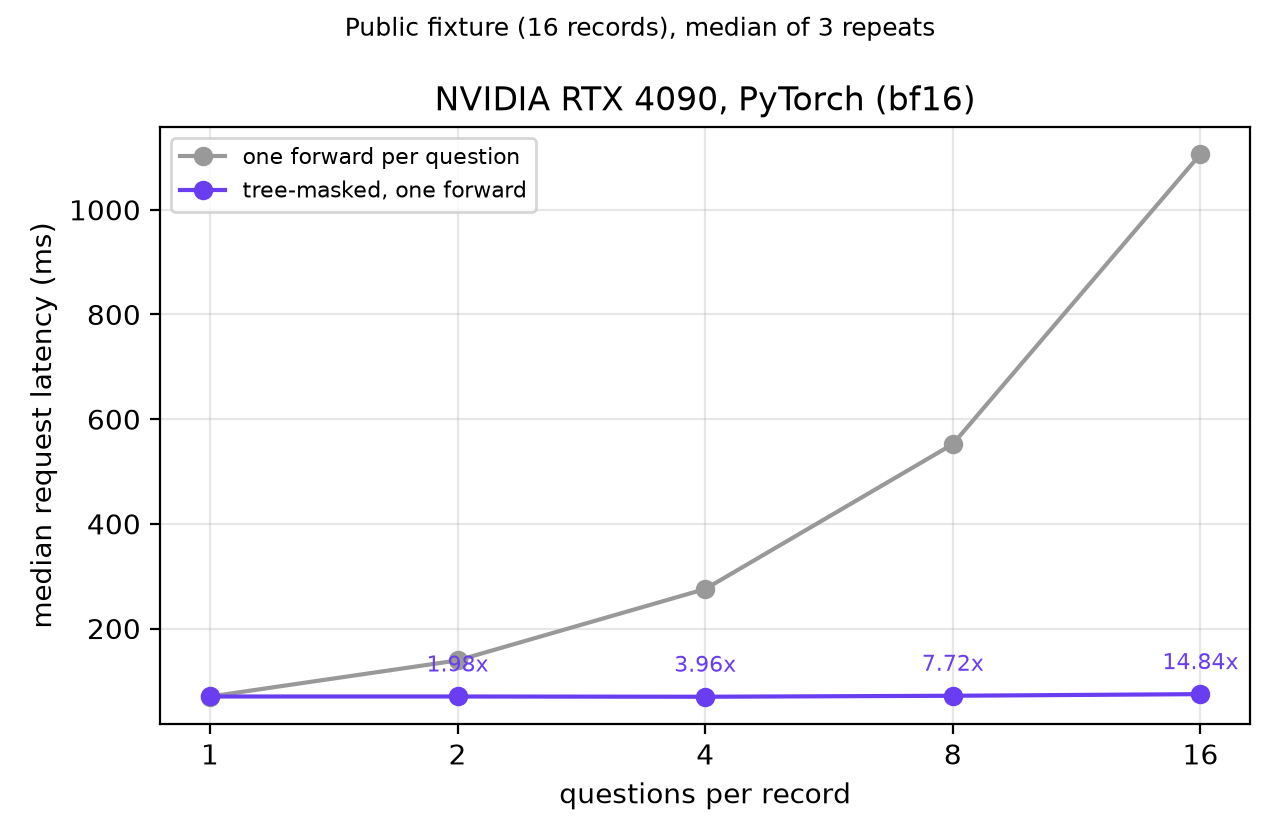
Latency (RTX 4090): Median request latency of the GitHub package on its public fictional fixture (16 records × 3 repeats, PyTorch 2.10.0+cu128, model loading excluded), answering N questions about one record:
| Questions per record | 1 | 2 | 4 | 8 | 16 |
|---|---|---|---|---|---|
| One tree-masked forward pass | 70 ms | 70 ms | 70 ms | 72 ms | 75 ms |
| One forward pass per question | 70 ms | 139 ms | 275 ms | 552 ms | 1,106 ms |
| Speedup | 1.00× | 1.98× | 3.96× | 7.72× | 14.84× |
A forward pass over a few hundred tokens costs about 70 ms regardless of length, so packed requests stay flat. Records in the fixture are short; long-document latency and network overhead are not included. Details: docs/RESULTS.md.
Training and limitations
The adapter was trained by KL distillation on soft answer distributions produced by DeepSeek Flash. It is not an official DeepSeek model. Training used 4,500 branches and training-domain validation used 500 branches; the underlying texts are not included here. Source domains include AMI/ICSI via QMSum, GitHub Archive Filtered, NASA ASRS, NHTSA, and public-domain regulations; source-specific licensing and attribution require separate review before redistributing any original texts. The selected local checkpoint was checkpoints/e2/lr-1e-4/epoch-3-quarter-3/.
The project reported that its E2 prespecified performance criteria were not met; notably Score performance remains below its intended threshold. A subsequent version focused on improving Score is planned; this release does not include that improvement. This adapter is an experimental research artifact, English-oriented, and unsuitable for high-stakes decisions. Its probabilities are not guaranteed to be calibrated.
The adapter and accompanying inference code are released under Apache License 2.0 (see LICENSE). The base model is Qwen/Qwen3-4B-Instruct-2507 by the Qwen team at Alibaba Cloud; its weights are obtained separately under the upstream license and attribution terms. This release does not claim endorsement by Qwen/Alibaba Cloud, DeepSeek, or TypeSafe.
- Downloads last month
- 54
Model tree for sennaLLMLearner/qwen3-4b-system-one-lora
Base model
Qwen/Qwen3-4B-Instruct-2507