

Deep Compression Autoencoder for Efficient High-Resolution Diffusion Models
Paper • 2410.10733 • Published • 9
ONNX builds of EfficientViT-SAM, made by Moonbox for on-device use with ONNX Runtime (CPU, CUDA, DirectML). Each
precision is one folder holding the graphs and a small Python pipeline.py that does the rest (image preprocessing,
prompt coordinates, mask upsampling); what the graphs take and return is under How to run.
The last column is the benchmark against the original PyTorch model (details under How to run): IoU of every predicted mask with the original's on the same pictures and prompts.
| Precision | File | Size | sha256 | Benchmark |
|---|---|---|---|---|
| fp32 | fp32/decoder.onnx |
0.3 MB | 72ff3fdc36d9 |
mask IoU 0.9999 mean / 0.9991 worst |
| fp32 | fp32/decoder.onnx.data |
16.2 MB | df2017f2c3fc |
mask IoU 0.9999 mean / 0.9991 worst |
| fp32 | fp32/encoder.onnx |
0.4 MB | 35d5b72c6f74 |
mask IoU 0.9999 mean / 0.9991 worst |
| fp32 | fp32/encoder.onnx.data |
229.0 MB | f5552293e854 |
mask IoU 0.9999 mean / 0.9991 worst |
| fp32 | fp32/pipeline.py |
4.2 kB | 3cee6dcd2a80 |
mask IoU 0.9999 mean / 0.9991 worst |
EfficientViT-SAM L2 (MIT Han Lab: SAM's prompt encoder and mask decoder on an EfficientViT-L2 image encoder at 512 px,
61 M parameters) as two ONNX graphs plus pipeline.py, a numpy runtime that reproduces the repository's
EfficientViTSamPredictor around them.
encoder.onnx: EfficientViT-L2 + the SAM neck: image [1, 3, 512, 512] (normalised, padded) ->
image_embeddings [1, 256, 64, 64]. Run it once per image.decoder.onnx: SAM's ONNX decoder wrapper (SamOnnxModel, all 4 masks; prompts and masks in the 1024 frame):
image_embeddings, point_coords [1, N, 2] and point_labels [1, N] (1 / 0 points, 2 / 3 box corners, -1
padding), mask_input [1, 1, 256, 256], has_mask_input [1], orig_im_size [2] -> masks [1, 4, H, W] (logits
at the image size), iou_predictions [1, 4], low_res_masks [1, 4, 256, 256].pipeline.py resizes the longest side to 512 (Pillow bilinear, as the repository's SamResize), applies SAM's pixel
mean / std and pads bottom-right to 512 x 512. It scales the prompt coordinates to the 1024 frame, and returns masks 1-3
for multimask point prompts and mask 0 for a box. It needs numpy, onnxruntime (or onnxruntime-gpu) and Pillow:
import sys, numpy as np
from PIL import Image
sys.path.insert(0, "fp32")
import pipeline
sam = pipeline.EfficientViTSAM("fp32", "cuda")
emb, size = sam.embed(np.array(Image.open("photo.jpg").convert("RGB")))
masks, scores = sam.point(emb, size, [[410, 300]])          # 3 masks [3, H, W] (bool)
box_mask, score = sam.box(emb, size, [120, 80, 700, 560])
Precisions. Only fp32/: the model doesn't survive 16 bits. 30 conv + BatchNorm pairs (every MBConv point conv of
stages 3-4, eight in the neck, the stem) have BatchNorm scales above 20, up to 602 (running variance 5.5e-7). Their
outputs are differences of terms about 1000x larger than the result. Measured here: fp16 (decoder fp32) worst mask IoU
0.12 (mean 0.89); weight-only int8 mean 0.33. Neither is published.
Benchmark. Eight photos (the first eight of the lab's DIS5K-250 set). Each gets a positive point (the ground-truth foreground pixel nearest its centroid; 3 masks) and the ground truth's bounding box (1 mask), so 32 masks per build. The original is the repository's EfficientViTSamPredictor in float32. The build gets the image it preprocesses and the same prompt coordinates (the conversion measured alone). Pass: IoU with the original's mask at least 0.95 on every mask.
| worst mask IoU | mean mask IoU | |
|---|---|---|
fp32/ |
0.9991 | 0.9999 |
Graphs checked against the original modules (largest absolute difference, float32): encoder 7.0e-5 of 0.58, decoder 2.3e-5 of 14.8 (masks).
From EfficientViT-SAM at revision de7d7733cc. The graphs were exported from the original PyTorch modules with
torch.onnx (opset 17 / 18) and checked against them. Weight-only quantization: int8 is a per-output-channel int8
weight behind DequantizeLinear, int4 is ONNX Runtime's MatMulNBits (block 32). Each card above says which precision
every graph uses. Every precision was benchmarked against the original before upload (pass: IoU at least 0.95 on every
mask, otherwise marked below threshold), and the sha256 column above is what the files must hash to.
apache-2.0. These files are a derivative of the original model and carry its license: it is copied in this repository, and it governs your use of these files. The original model card follows unchanged.

Deep Compression Autoencoder (DC-AE) is a new family of high-spatial compression autoencoders with a spatial compression ratio of up to 128 while maintaining reconstruction quality. It accelerates all latent diffusion models regardless of the diffusion model architecture.

Figure 1: We address the reconstruction accuracy drop of high spatial-compression autoencoders.

Figure 2: DC-AE speeds up latent diffusion models.

Figure 3: DC-AE enables efficient text-to-image generation on the laptop: SANA.
EfficientViT-SAM is a new family of accelerated segment anything models by replacing SAM's heavy image encoder with EfficientViT. It delivers a 48.9x measured TensorRT speedup on A100 GPU over SAM-ViT-H without sacrificing accuracy.
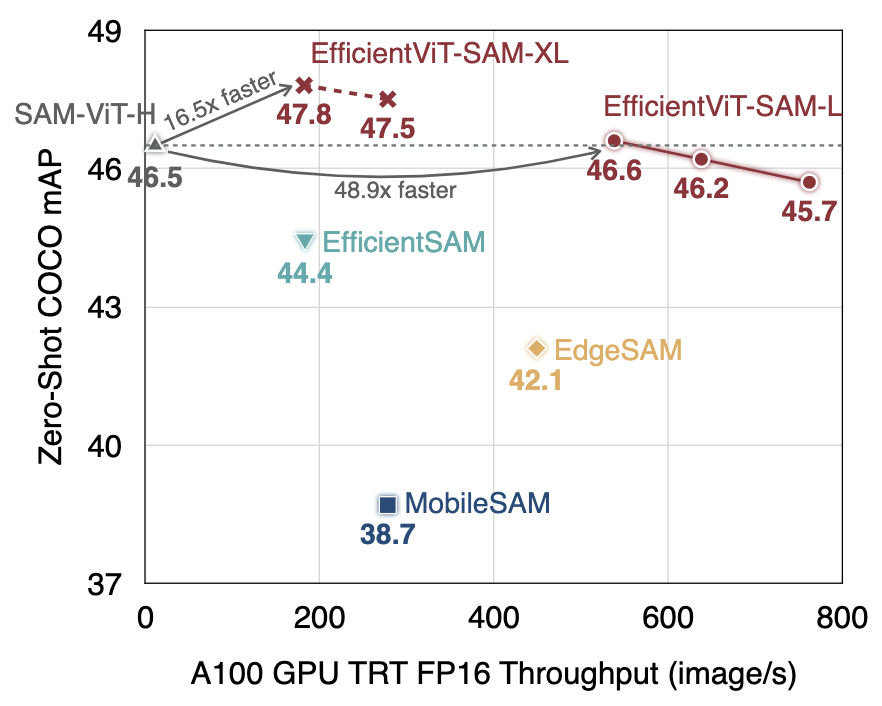
Efficient image classification models with EfficientViT backbones.

Efficient semantic segmantation models with EfficientViT backbones.

Gaze-prompted image segmentation models capable of running in real time with TensorRT on an NVIDIA RTX 4070.

conda create -n efficientvit python=3.10
conda activate efficientvit
pip install -U -r requirements.txt
If EfficientViT or EfficientViT-SAM or DC-AE is useful or relevant to your research, please kindly recognize our contributions by citing our paper:
@inproceedings{cai2023efficientvit,
  title={Efficientvit: Lightweight multi-scale attention for high-resolution dense prediction},
  author={Cai, Han and Li, Junyan and Hu, Muyan and Gan, Chuang and Han, Song},
  booktitle={Proceedings of the IEEE/CVF International Conference on Computer Vision},
  pages={17302--17313},
  year={2023}
}
@article{zhang2024efficientvit,
  title={EfficientViT-SAM: Accelerated Segment Anything Model Without Performance Loss},
  author={Zhang, Zhuoyang and Cai, Han and Han, Song},
  journal={arXiv preprint arXiv:2402.05008},
  year={2024}
}
@article{chen2024deep,
  title={Deep Compression Autoencoder for Efficient High-Resolution Diffusion Models},
  author={Chen, Junyu and Cai, Han and Chen, Junsong and Xie, Enze and Yang, Shang and Tang, Haotian and Li, Muyang and Lu, Yao and Han, Song},
  journal={arXiv preprint arXiv:2410.10733},
  year={2024}
}