

DRS-VPT: Directly Relocalizing in a Scan with Vision Point Transformers
Paper • 2609.12557 • Published • 1
Configuration Parsing Warning:Invalid JSON for config file config.json
Weights for DRS-VPT (ECCV 2026). DRS-VPT localizes a single camera image inside a 3-D point cloud map, with no pose prior. One model works for driving LiDAR scans and indoor maps. It also calibrates a camera to a LiDAR without targets.
Paper · Code · Project page · ECCV 2026 · Demo data
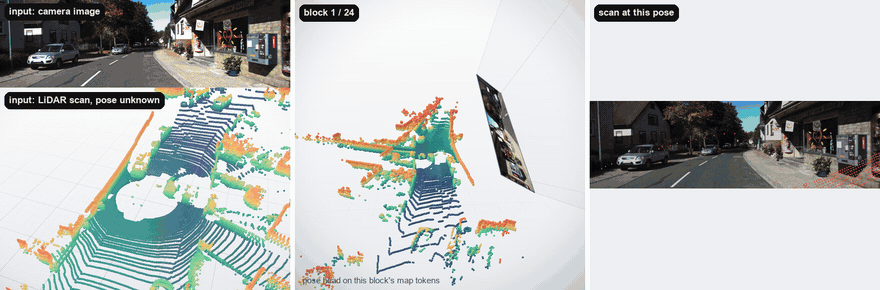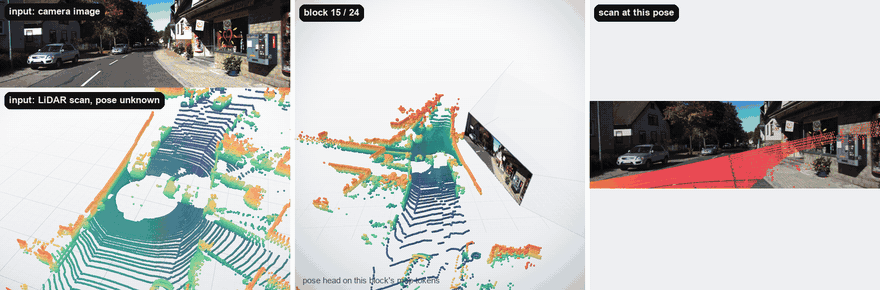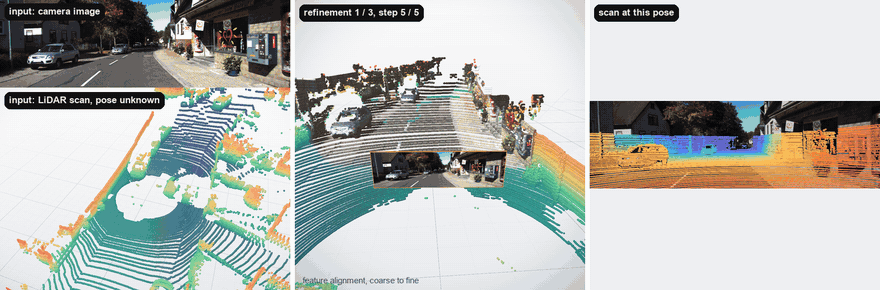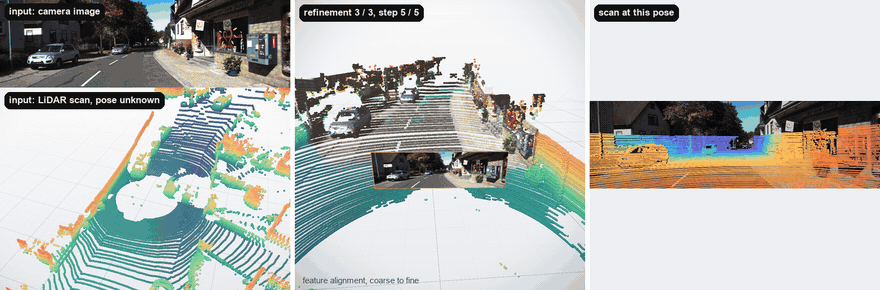
Linux with an NVIDIA GPU (CUDA 12.8 build). CPU-only and macOS instructions are in the GitHub README.
git clone https://github.com/ori-drs/drs-vpt.git && cd drs-vpt
conda create -n drs_vpt python=3.12 -y && conda activate drs_vpt
pip install torch==2.8.0 torchvision --index-url https://download.pytorch.org/whl/cu128
pip install spconv-cu126 torch-scatter -f https://data.pyg.org/whl/torch-2.8.0+cu128.html
pip install -e ".[viz,dev]"
pytest tests
The weights in this repo (2.9 GB) and the demo samples download on first use.
from drs_vpt.hub import load_model, load_sample
from drs_vpt.inference import calibrate, read_image

model = load_model(device="cuda")

sample = load_sample("kitti")
frame = sample["frames"][0]
image = read_image(frame["img_path"])   # (H, W, 3) uint8 RGB
K = frame["K"]                          # 3x3 intrinsics of the image
cloud = sample["cloud"]                 # (N, 3) float32 point cloud in metres
grid_size = sample["grid_size"]         # voxel size in metres: 0.02 outdoors, 0.005-0.01 indoors

out = calibrate(model, [(image, K, cloud)], grid_size)
print(out["T_cam_lidar"])               # 4x4 cloud-to-camera: x_cam = R @ x_cloud + t

out = calibrate(model, [(image, None, cloud)], grid_size)   # without K: the intrinsics are predicted
print(out["T_cam_lidar"])
Encode the map once, then localize each image against it:
from drs_vpt.hub import load_model, load_sample
from drs_vpt.inference import encode_map, localize, read_image

model = load_model(device="cuda")
stream = load_sample("iphone_stream")   # 37 frames in one map
map_encoding = encode_map(model, stream["cloud"], stream["grid_size"])
for frame in stream["frames"]:
    out = localize(model, read_image(frame["img_path"]), map_encoding, frame["K"])   # K=None predicts it
    print(out["T_w2c"])                 # 4x4 world-to-camera; out["K"]: the K used, at the model's resolution
With these weights and the evaluation in the code repo (scripts/eval.py). t and r are the mean / median translation
and rotation errors; accuracy is the recall at 2 m / 5°.
| t [m] | r [°] | accuracy [%] | |
|---|---|---|---|
| KITTI | 0.08 / 0.05 | 0.28 / 0.22 | 99.71 |
| nuScenes | 0.31 / 0.13 | 0.80 / 0.31 | 97.62 |
The weights are released under CC BY-NC 4.0 (non-commercial use only), because the training data includes non-commercial datasets. The code is Apache 2.0.
@inproceedings{fu2026drsvpt,
  title     = {{DRS}-{VPT}: Directly Relocalizing in a Scan with Vision Point Transformers},
  author    = {Fu, Lanke Frank Tarimo and Fallon, Maurice},
  booktitle = {Proceedings of the European Conference on Computer Vision (ECCV)},
  year      = {2026},
  eprint    = {2609.12557},
  archivePrefix = {arXiv}
}