

Accept the EmpirioLabs Model License to access Aplomb
Free for research, education, evaluation, personal use, and internal commercial use by organizations with annual revenue under US$1 million. Offering the model as a hosted service, larger commercial use, and shipping it in products sold to others need a commercial license from EmpirioLabs.ai LLC (support@empiriolabs.ai). Distilling or training other models from it or its outputs is not permitted.
Log in or Sign Up to review the conditions and access this model content.
Model page · Launch post · API docs · Playground
Aplomb
Aplomb is a decision model. It reads text, JSON, images, video and audio, and answers typed questions about them with calibrated probabilities instead of generated text. Send a state of up to one million tokens with up to 128 questions, and every answer comes back as a probability distribution with a confidence value, in one request. Aplomb has 5.3 billion parameters.
Highlights
- Every input type in one model: text, JSON objects and arrays, images, video and audio.
- One million tokens: state plus question, in a single request.
- Four question types: yes or no, a choice among 2 to 255 options, an ordered score of 2 to 10 levels, and tool
selection (which function to call, with distributions over its
enumandbooleanarguments). - Not in the state: ask for it per question, and the answer includes the probability that the state does not contain what the question needs.
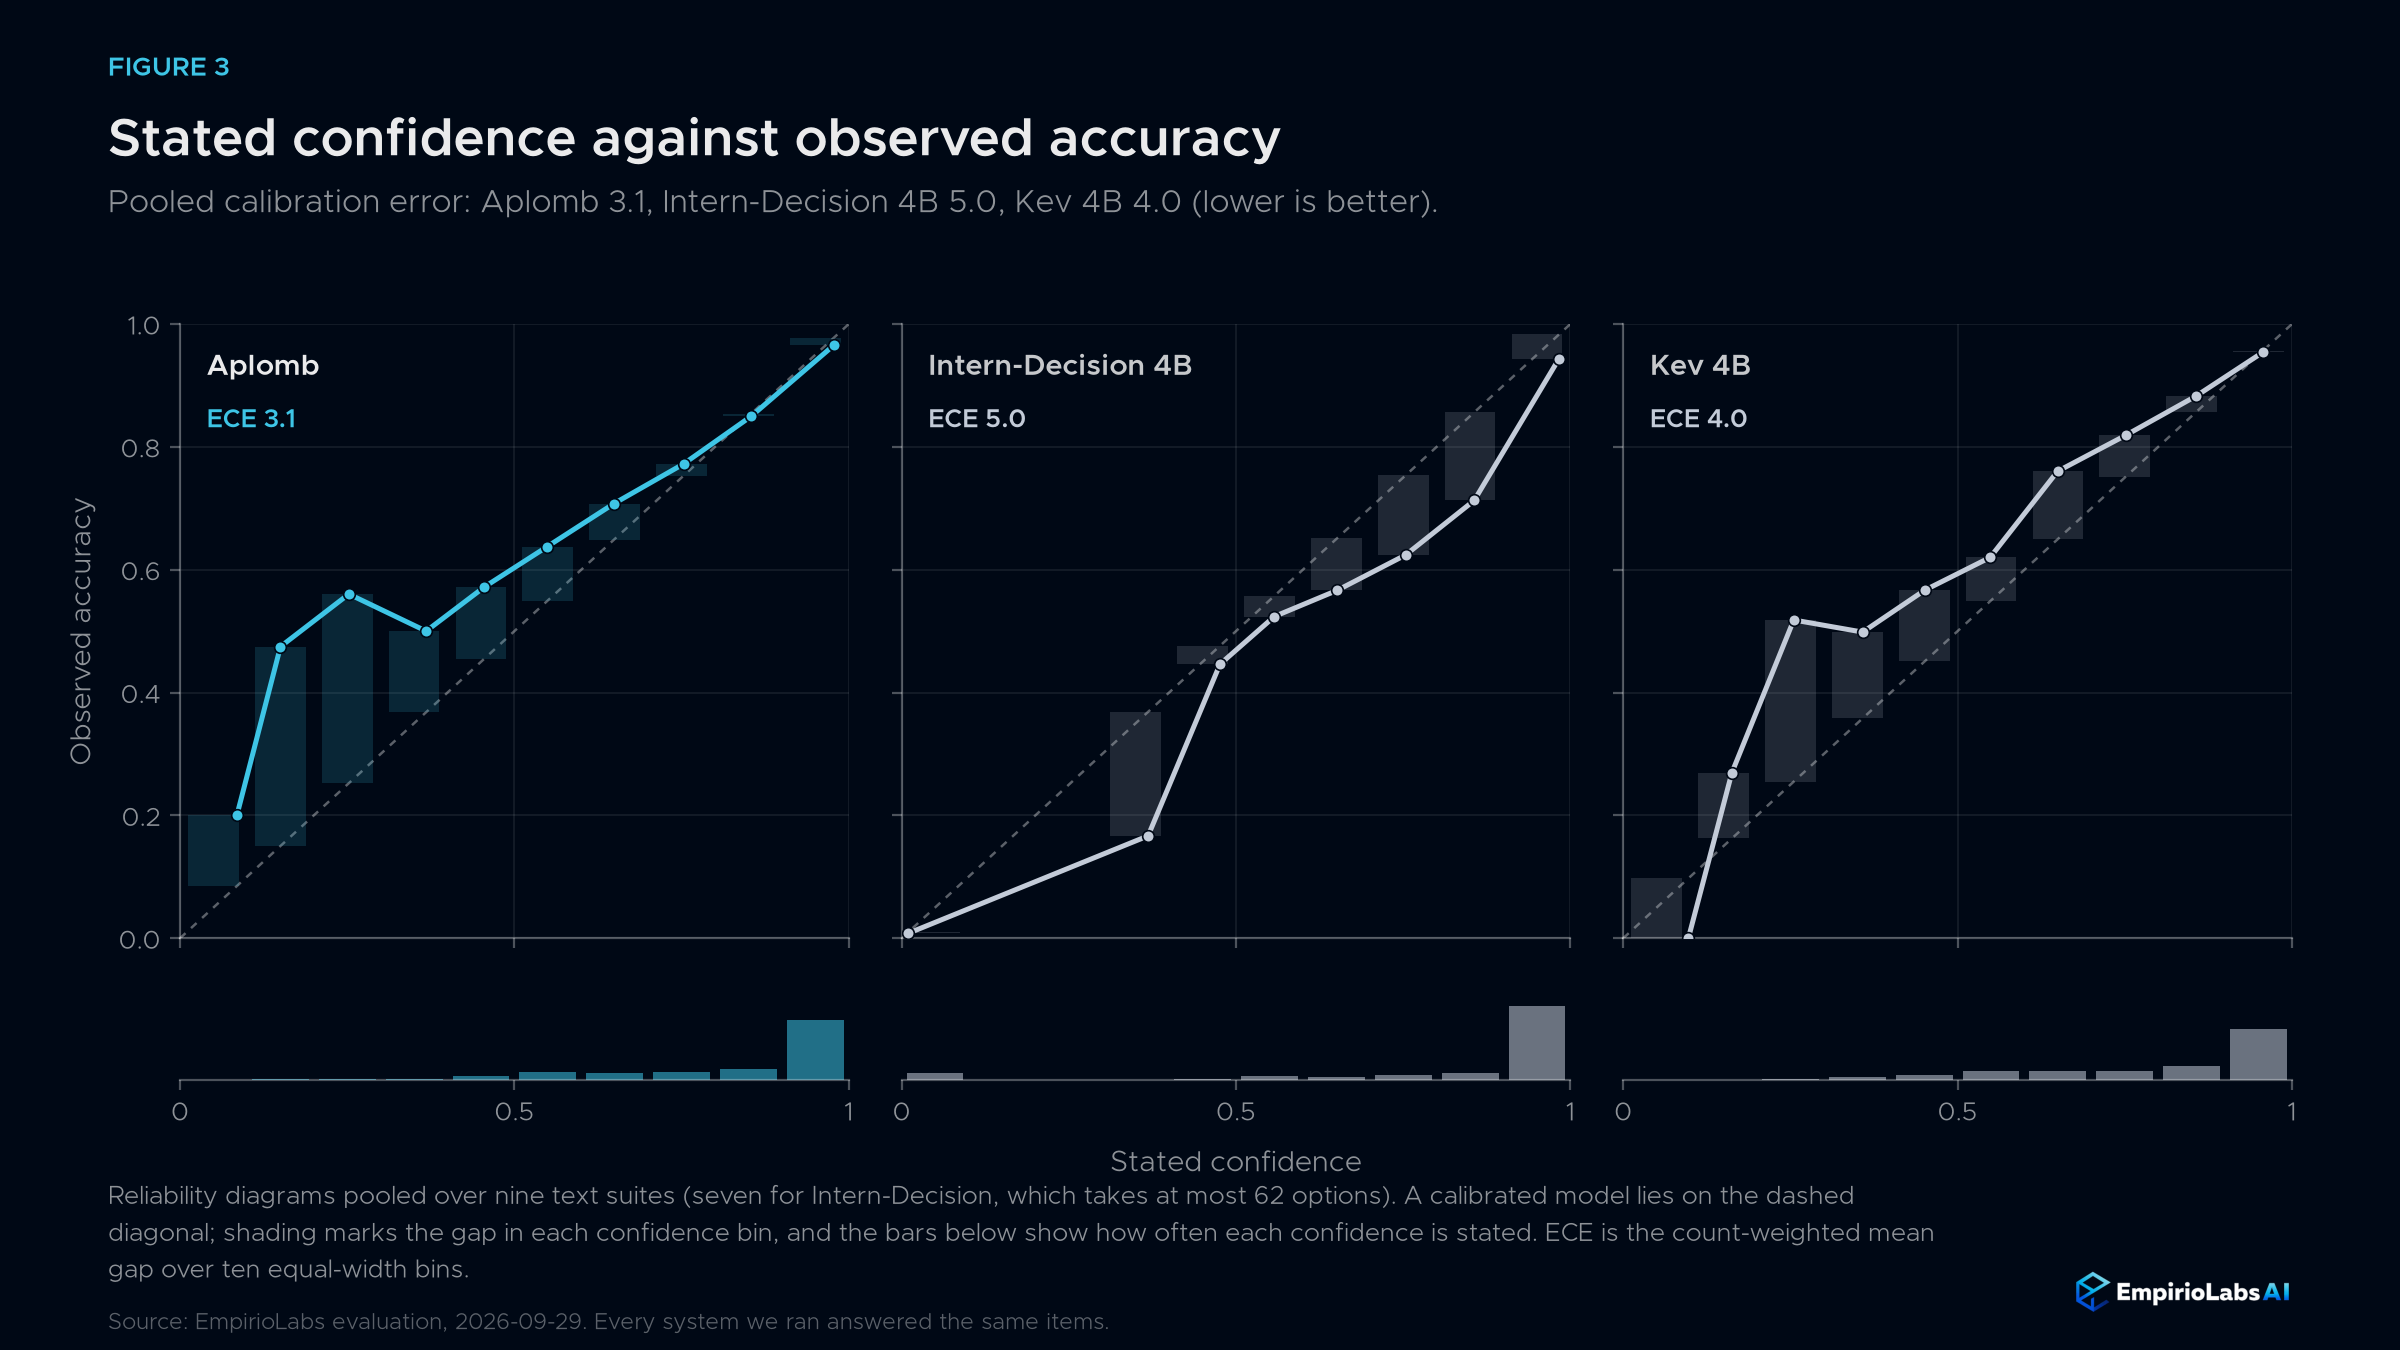
- Calibrated: a stated 80% is right about 80% of the time (Figure 3).
- Independent answers: questions never influence each other.
Results
Measured by EmpirioLabs on 2026-09-29. Accuracy is in percent; every system we ran answered the same items. Bold marks the best score in a row.
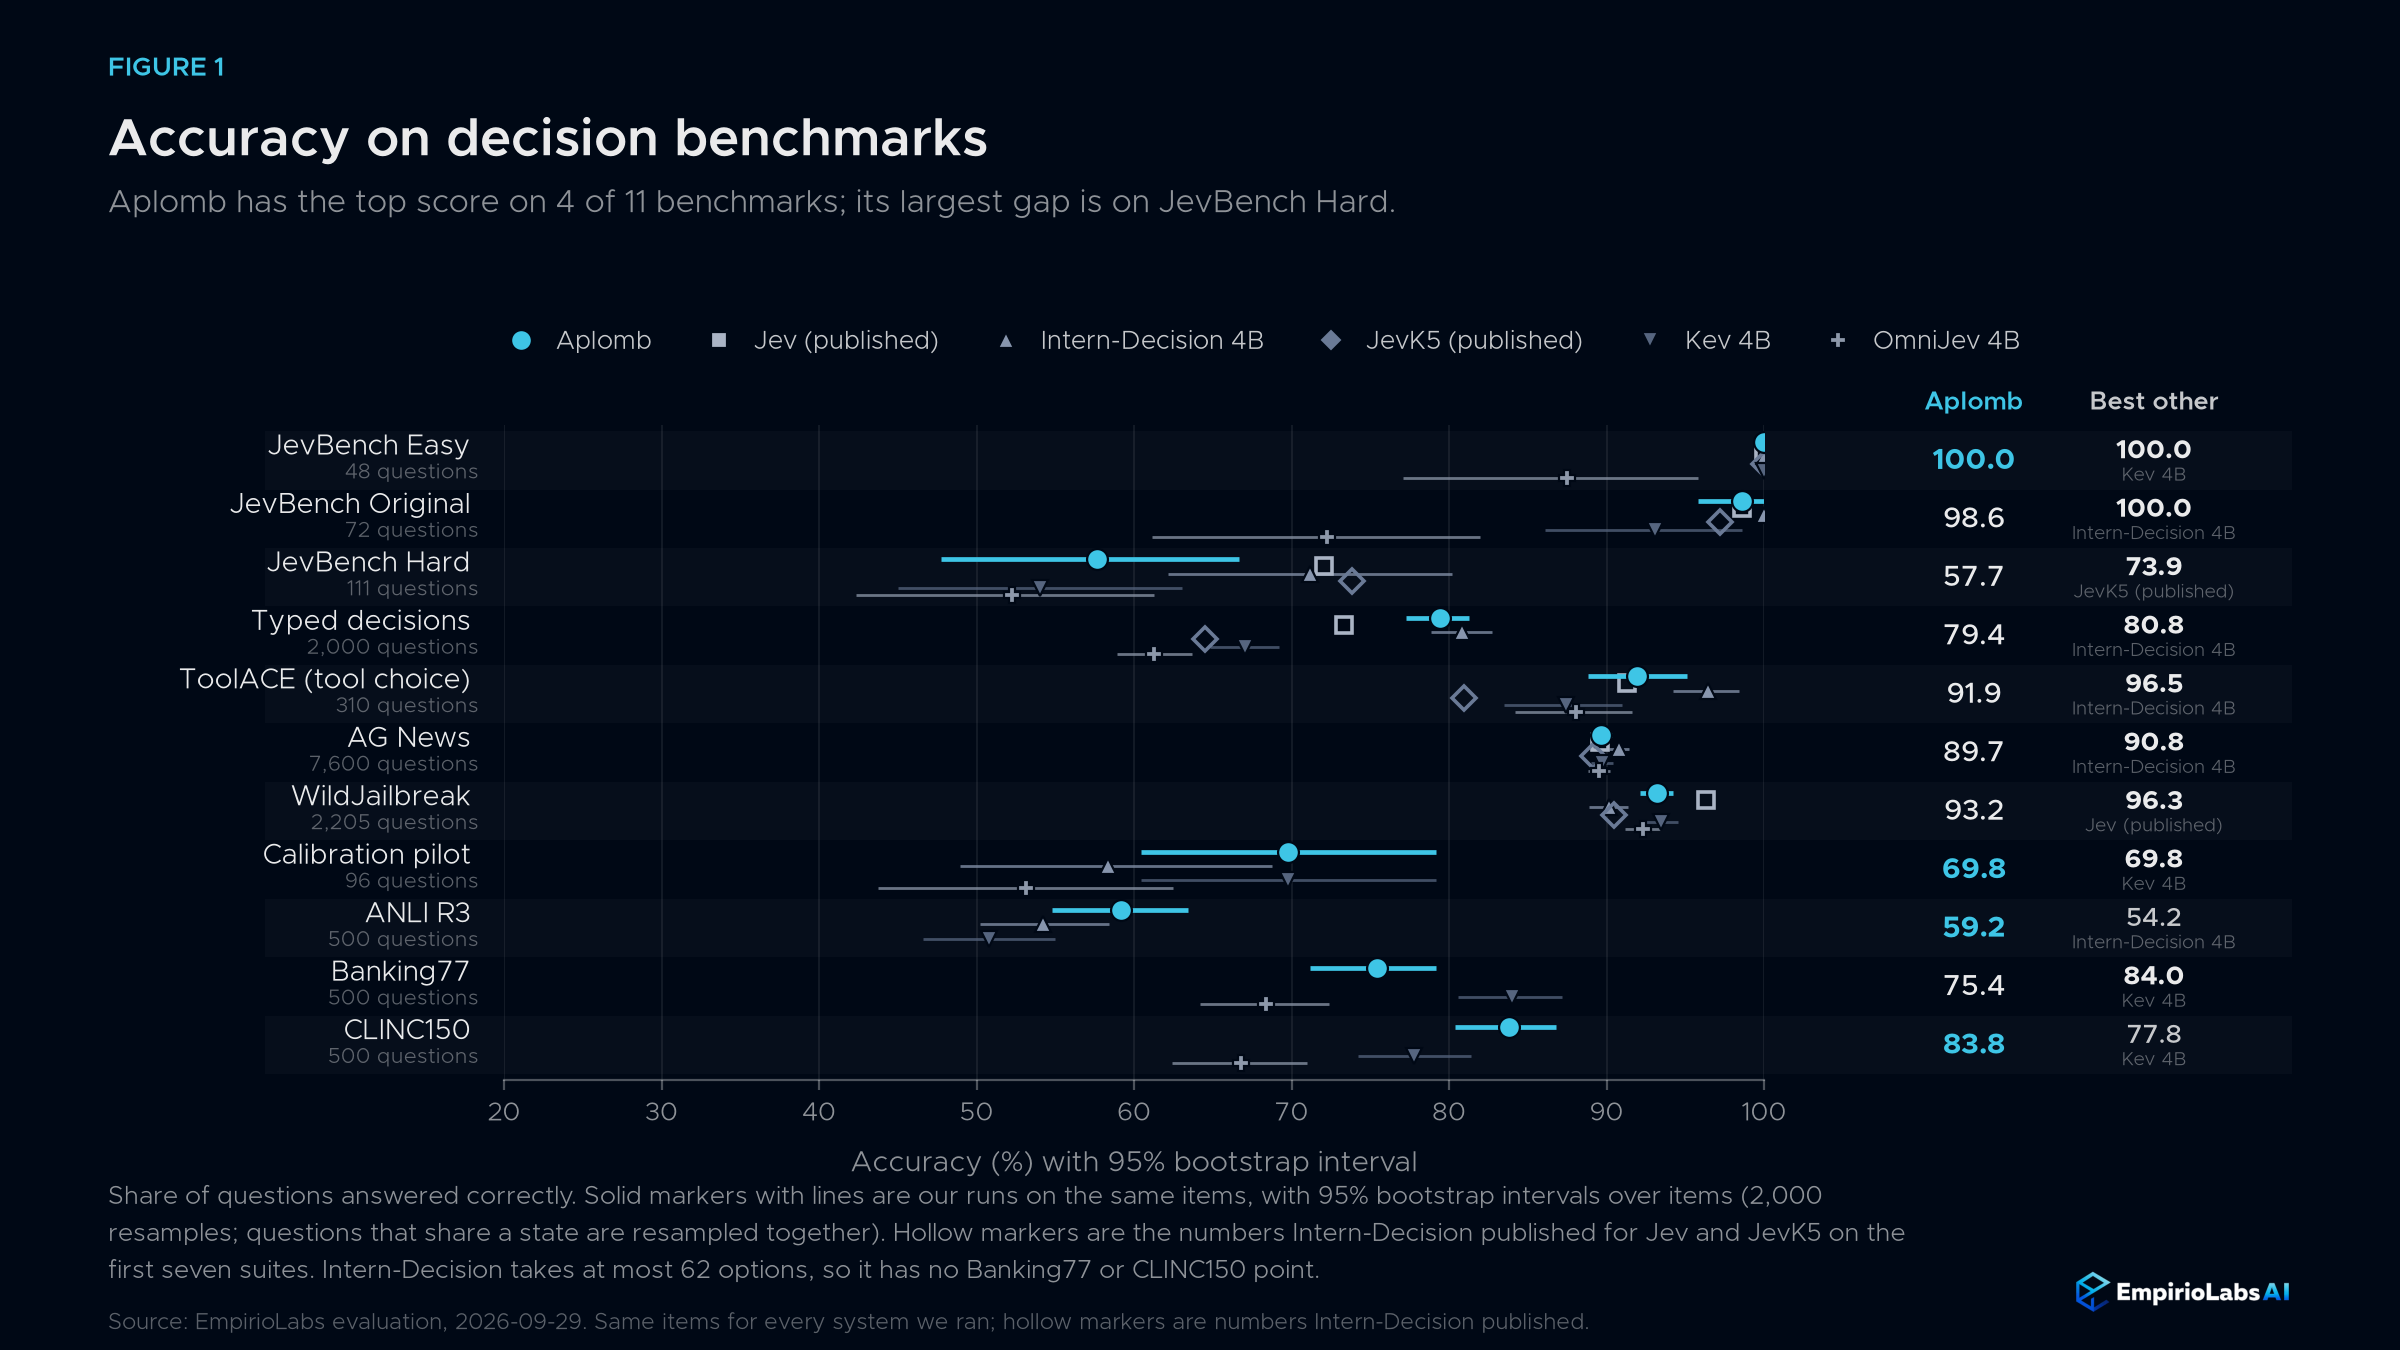
Decision benchmarks (the Intern-Decision evaluation bundle)
| Benchmark | Aplomb | Jev (p) | Intern-Decision-4B | JevK5 (p) | SemIf (p) | Kev-4B | OmniJev-4B |
|---|---|---|---|---|---|---|---|
| JevBench Easy | 100.0 | 100.0 | 100.0 | 100.0 | 100.0 | 100.0 | 87.5 |
| JevBench Original | 98.6 | 98.6 | 100.0 | 97.2 | 98.6 | 93.1 | 72.2 |
| JevBench Hard | 57.7 | 72.1 | 71.2 | 73.9 | 61.3 | 54.1 | 52.3 |
| Typed Decisions | 79.4 | 73.3 | 80.8 | 64.5 | 62.8 | 67.0 | 61.3 |
| ToolACE | 91.9 | 91.3 | 96.5 | 81.0 | 85.2 | 87.4 | 88.1 |
| AG News | 89.7 | 89.6 | 90.8 | 89.1 | 89.2 | 89.7 | 89.6 |
| WildJailbreak | 93.2 | 96.3 | 90.2 | 90.5 | 92.5 | 93.5 | 92.3 |
| Average | 87.2 | 88.7 | 89.9 | 85.2 | 84.2 | 83.5 | 77.6 |
(p) As published by Intern-Decision for the same items; not run by us. Intern-Decision reports 90.02 for Intern-Decision-4B on this bundle; its column shows our run.
More decision benchmarks
| Benchmark | Aplomb | Intern-Decision-4B | Kev-4B | OmniJev-4B |
|---|---|---|---|---|
| Calibration pilot | 69.8 | 58.3 | 69.8 | 53.1 |
| ANLI R3 | 59.2 | 54.2 | 50.8 | n/a |
| Banking77 (77 options) | 75.4 | n/a | 84.0 | 68.4 |
| CLINC150 (150 options) | 83.8 | n/a | 77.8 | 66.8 |
Images (first 500 items of each set)
| Benchmark | Aplomb | Intern-Decision-4B | OmniJev-4B |
|---|---|---|---|
| POPE | 88.6 | 89.2 | 88.4 |
| MMStar | 68.0 | 65.2 | 64.4 |
| AI2D | 86.8 | 81.0 | 83.4 |
| MMMU | 58.0 | 57.0 | 56.0 |
| HallusionBench | 81.2 | 79.4 | 71.2 |
Video
| Benchmark | Aplomb | OmniJev-4B |
|---|---|---|
| TempCompass | 76.8 | 73.6 |
| Video-MME (short) | 80.6 | 72.2 |
| NExT-QA | 84.0 | 79.8 |
Audio
| Benchmark | Aplomb |
|---|---|
| VocalSound (vocal sounds) | 90.4 |
| CREMA-D (emotion in speech) | 76.7 |
| ESC-50 (environmental sounds) | 10.1 |
| MMAU (audio questions) | 45.9 |
| MMSU (spoken language) | 43.3 |
Aplomb is strongest on speech and vocal sounds; environmental sounds (ESC-50) and open-ended questions about audio (MMAU, MMSU) are harder for it.
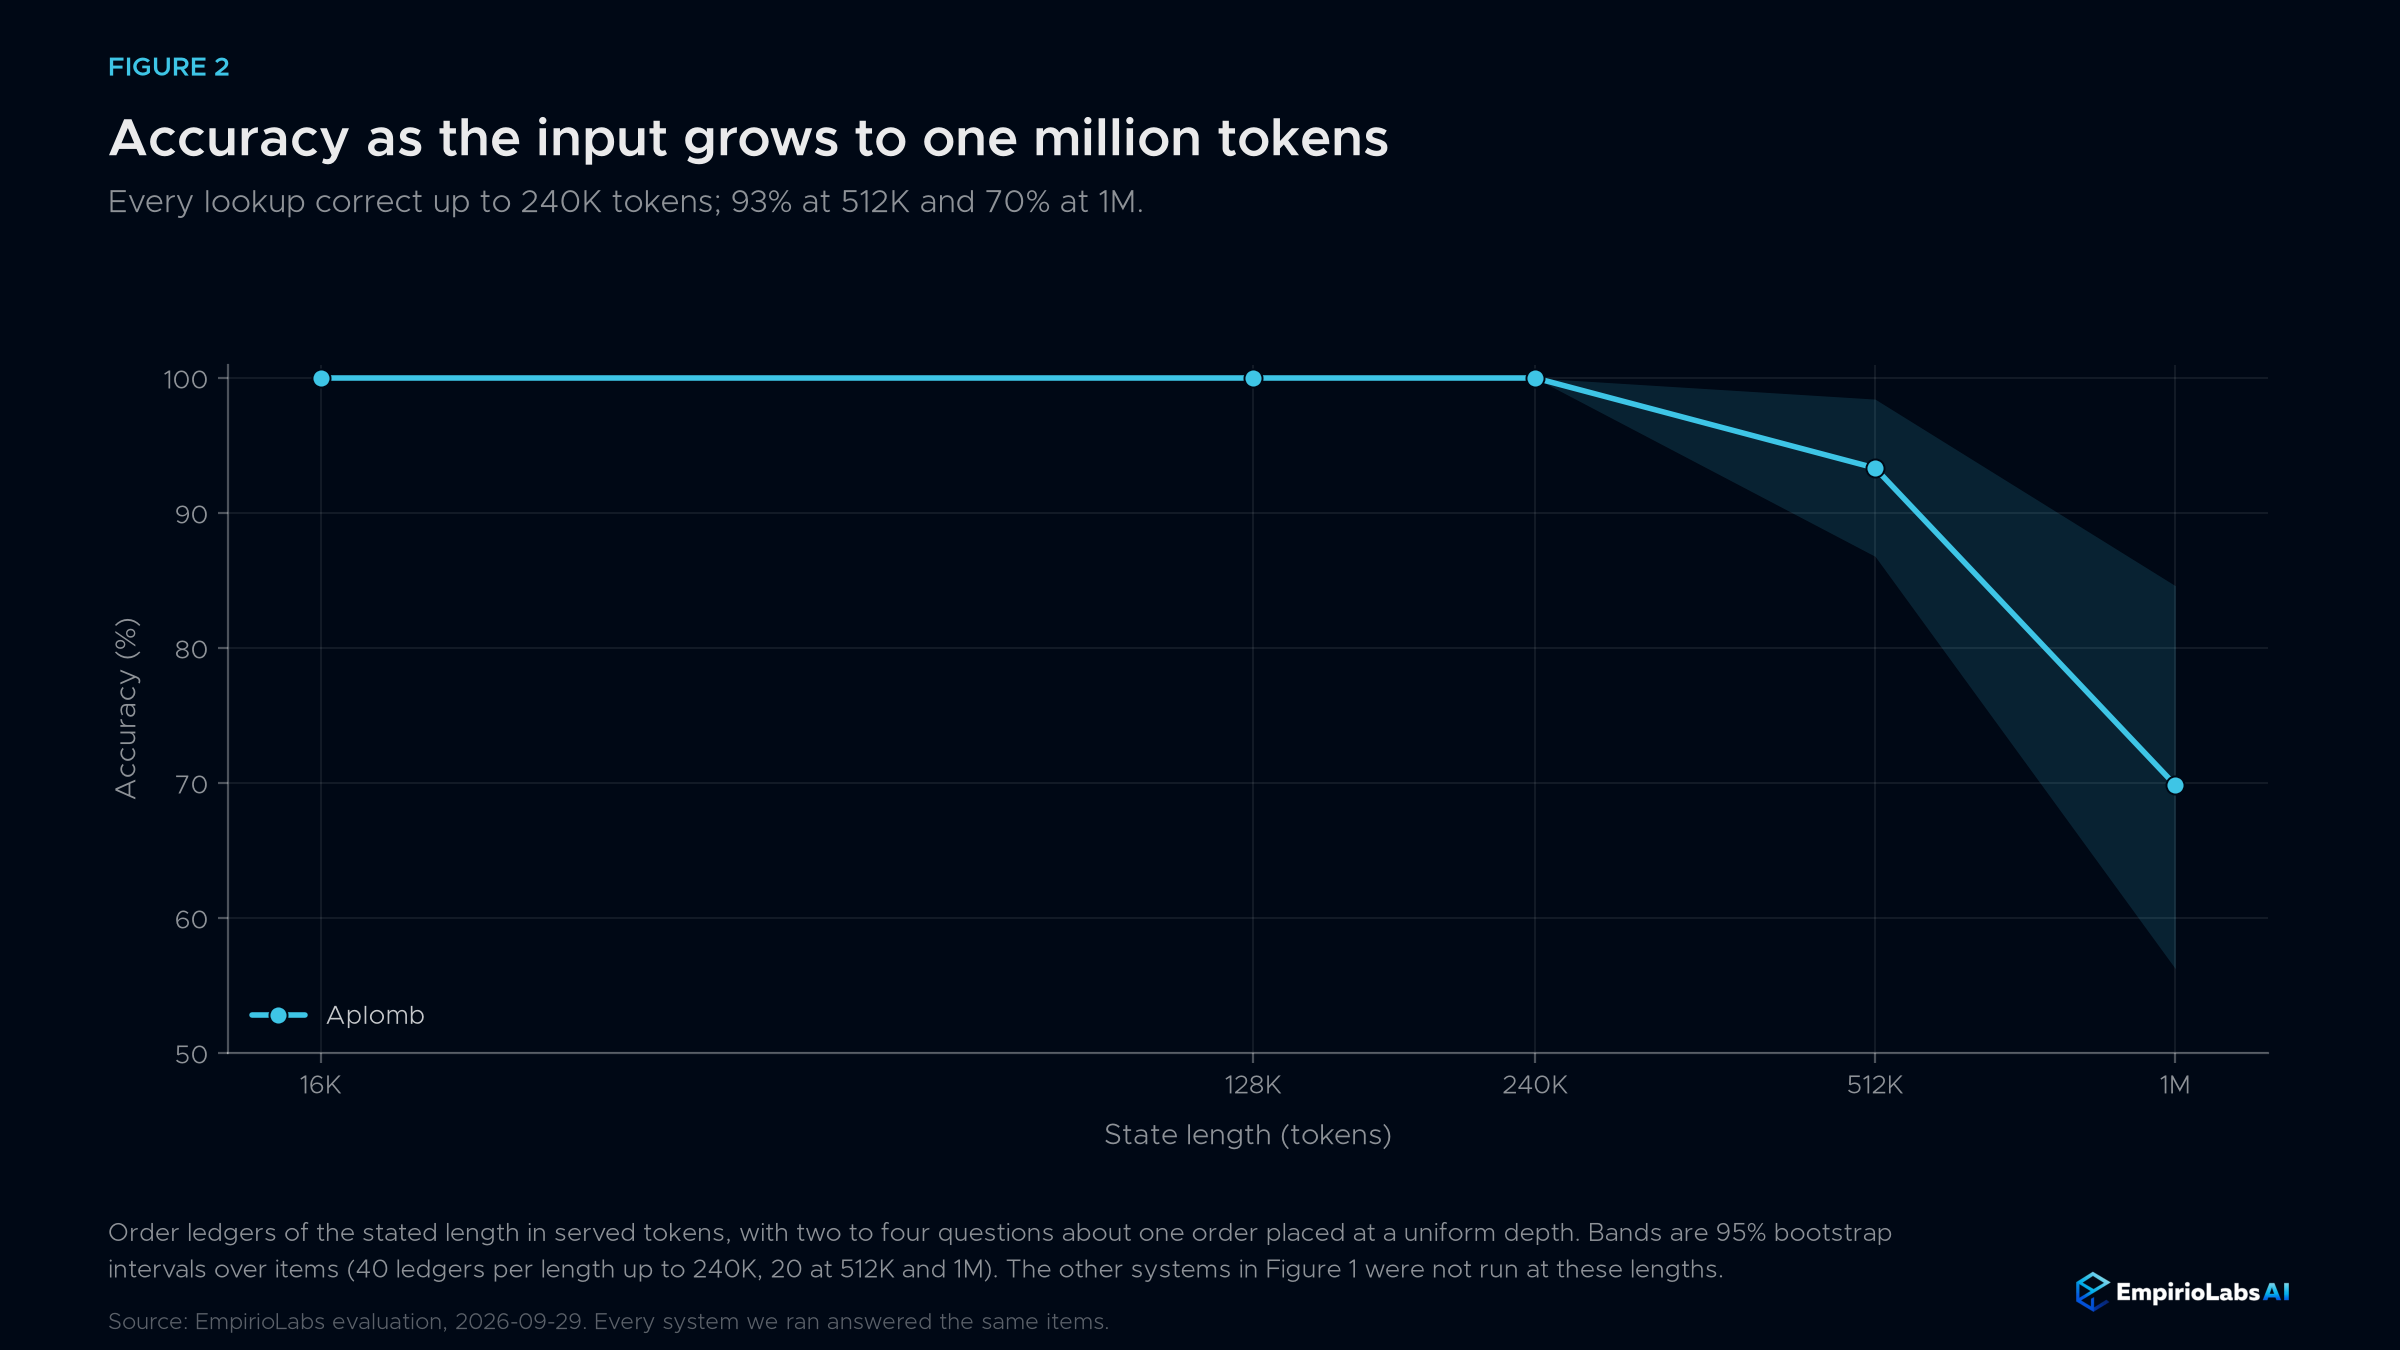
Long states (lookups in order ledgers of the given length)
| State length (tokens) | 16K | 128K | 240K | 512K | 1M |
|---|---|---|---|---|---|
| Aplomb | 100.0 | 100.0 | 100.0 | 93.3 | 69.8 |
Quickstart
curl https://api.empiriolabs.ai/v1/decisions \
  -H "Authorization: Bearer $EMPIRIOLABS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "aplomb",
    "state": {"order": {"id": "B-44120", "status": "shipped", "payment": "unpaid"}},
    "questions": {
      "paid": {"type": "noul", "instructions": "Has order B-44120 been paid?", "abstain": true},
      "carrier": {"type": "choice", "instructions": "Which carrier is delivering order B-44120?",
                  "criteria": {"ups": null, "fedex": null, "dhl": null}, "abstain": true}
    }
  }'
paid comes back as a confident no. carrier comes back with a high abstain probability, because the record
does not name a carrier. Images, video and audio go in the state as {"type": "audio", "url": "https://..."} or
{"type": "audio", "data": "<base64>", "mime": "audio/wav"}. The full schema and limits are in the
Decisions API guide.
Run locally
pip install -U "transformers>=5.17" torch accelerate torchvision torchcodec soundfile librosa flash-linear-attention
python run_aplomb.py --model empiriolabsai/aplomb --request request.json --debias
request.json is a Decisions API request body; --debias matches the hosted API. The weights are bf16 and need
about 12 GB of accelerator memory. The hosted API runs on EmpirioLabs' own inference runtime for decision models.
Intended use
Classification, routing, moderation, extraction checks, tool selection and evaluation, anywhere a program needs a probability rather than prose. Aplomb does not generate text or fill free-text tool arguments. Where a decision has legal or similarly significant effects on a person, keep a human in the loop.
Limits
- State plus the longest question: up to 1,000,000 tokens.
- Media per request: up to 16 images, 8 audio clips and 4 videos.
License
EmpirioLabs Model License 1.0. Research, education, evaluation, personal use and internal commercial use
by organizations with annual revenue under US$1 million are free. Offering the model as a hosted service, commercial
use above that threshold and distribution in products sold to others need a commercial license from
support@empiriolabs.ai. Using the model or its outputs to train another model is not permitted. Built on
Qwen/Qwen3.5-4B, with the audio encoder of Qwen/Qwen3-Omni-30B-A3B-Instruct (both Apache 2.0; see
LICENSE-APACHE-2.0 and NOTICE).
- Downloads last month
- -