

Reader v2: beats every public 9 µm ink model on the 116 keV First Letters scan protocol
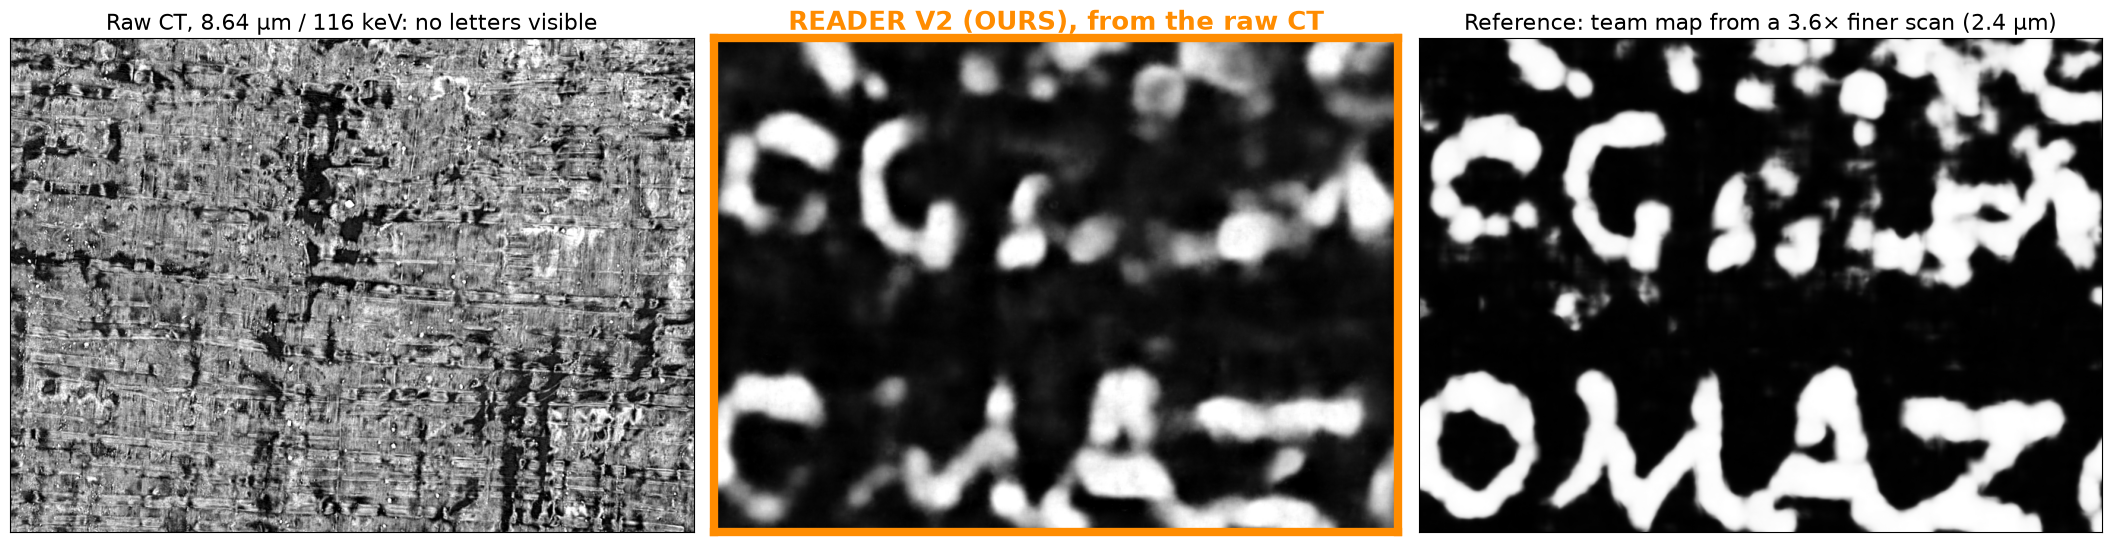
A drop-in for the team's own ink_9um inference command: only the checkpoint changes. Held out: AUC 0.834 vs 0.725
for the next best model on 116 keV scans (the protocol of 11 of the 22 First Letters scrolls), 5× less false ink than
Hecate at the same ink recall (10.4% of blank papyrus vs 58%), and on PHerc0841, a scroll it never saw, the highest AUC
of any public model against the team's map (0.858). Code, figures and every evaluation:
github.com/DomRusso2/reader-v2.
hf download domenicor046/reader-v2 reader-v2-step040000.pth --local-dir .
python -m koine_machines.inference.infer <surface_volume.zarr> reader-v2-step040000.pth out.tif \
  --overlap 0.5 --blend-mode hann --direction forward
(koine_machines = ink-detection/ on villa's merge-ink-pipelines branch; add --no-compile on Windows.)
| file | what it is |
|---|---|
reader-v2-step040000.pth |
the model (model / config / step, 138 MB, same format as scrollprize/ink_9um). sha256 654ec5acec2b6c4788d9cb326e2f0b8c2c730584949a934ef775db7f6ab5d3a6 |
reader-v2-init-ft12k.pth |
the training init (my August ink9um-dense checkpoint fine-tuned 12k steps at 116 keV), for retraining with train_config.json. sha256 6bad92971b029857f23d1ab46a623b0f2cd6c9605c05d1939c8f859b0d98f79b |
train_config.json |
the exact training config (paths relative to the project root) |
Scoreboard (held out; same data, same masks, same metric for every model)
| held-out test | Reader v2 | released ink_9um (best of 14) |
best other public model |
|---|---|---|---|
| 116 keV PHerc0009B, AUC vs team map (4 segments) | 0.834 | 0.626 | 0.725 (Hecate) |
| 116 keV PHerc0009B, AUC vs human labels | 0.927 | 0.813 | 0.901 (Nieuwlaar) |
| False alarms on blank papyrus (at 80% ink recall) | 10.4% | 43% | 10.5% (Nieuwlaar) |
| Never-seen scroll PHerc0841, AUC vs team map | 0.858 | 0.708 | 0.848 (Hecate) |
| 113 keV PHerc0139 w047, AUC | 0.893 | 0.778 | 0.898 (Nieuwlaar) |
| Never-seen scroll PHerc0841, AUC vs human labels | 0.824 | 0.733 | 0.855 (Hecate) |
First on four of the six tests, second on the other two, and ahead of the team's released checkpoint on all six.
Limits: Hecate alone leads on PHerc0841's human labels (averaging the two gives 0.866; script in the GitHub repo); one training seed; teacher maps are model outputs from finer scans; on PHerc1447 it shows one letter-like form, not readable lines.