

user_id stringclasses 557
values | item_id stringlengths 1 4 | score stringclasses 5
values |
|---|---|---|
0 | 74 | 1.0 |
0 | 36 | 0.0 |
0 | 12 | 0.0 |
0 | 34 | 0.0 |
0 | 55 | 1.0 |
0 | 69 | 0.0 |
0 | 31 | 0.0 |
0 | 64 | 0.0 |
0 | 81 | 1.0 |
0 | 58 | 0.0 |
0 | 46 | 0.0 |
0 | 4 | 0.0 |
0 | 65 | 0.0 |
0 | 67 | 0.0 |
0 | 37 | 1.0 |
0 | 54 | 0.0 |
0 | 3 | 1.0 |
0 | 51 | 1.0 |
0 | 28 | 0.0 |
0 | 71 | 0.0 |
0 | 23 | 1.0 |
0 | 68 | 1.0 |
0 | 62 | 1.0 |
0 | 21 | 0.0 |
0 | 73 | 0.0 |
0 | 30 | 0.0 |
0 | 7 | 0.0 |
0 | 27 | 1.0 |
0 | 79 | 1.0 |
0 | 82 | 0.0 |
0 | 22 | 0.0 |
0 | 29 | 0.0 |
0 | 14 | 0.0 |
0 | 70 | 0.0 |
0 | 11 | 0.0 |
0 | 41 | 1.0 |
0 | 43 | 1.0 |
0 | 35 | 1.0 |
0 | 38 | 0.0 |
0 | 56 | 1.0 |
0 | 75 | 1.0 |
0 | 42 | 0.0 |
0 | 18 | 0.0 |
0 | 59 | 0.0 |
0 | 39 | 0.0 |
0 | 72 | 0.0 |
0 | 50 | 1.0 |
0 | 15 | 1.0 |
0 | 32 | 1.0 |
0 | 13 | 0.0 |
0 | 52 | 0.0 |
0 | 76 | 0.0 |
0 | 0 | 0.0 |
0 | 2 | 0.0 |
0 | 61 | 0.0 |
0 | 47 | 0.0 |
0 | 5 | 0.0 |
0 | 44 | 1.0 |
1 | 138 | 1.0 |
1 | 45 | 0.0 |
1 | 98 | 1.0 |
1 | 54 | 0.0 |
1 | 237 | 0.0 |
1 | 259 | 0.0 |
1 | 126 | 1.0 |
1 | 12 | 1.0 |
1 | 88 | 1.0 |
1 | 161 | 0.0 |
1 | 78 | 0.0 |
1 | 23 | 1.0 |
1 | 177 | 0.0 |
1 | 200 | 1.0 |
1 | 92 | 1.0 |
1 | 163 | 1.0 |
1 | 187 | 1.0 |
1 | 164 | 1.0 |
1 | 244 | 1.0 |
1 | 85 | 1.0 |
1 | 79 | 1.0 |
1 | 151 | 1.0 |
1 | 176 | 1.0 |
1 | 80 | 1.0 |
1 | 122 | 1.0 |
1 | 261 | 0.0 |
1 | 225 | 0.0 |
1 | 89 | 1.0 |
1 | 113 | 1.0 |
1 | 4 | 1.0 |
1 | 7 | 1.0 |
1 | 206 | 1.0 |
1 | 172 | 1.0 |
1 | 192 | 1.0 |
1 | 107 | 0.0 |
1 | 160 | 1.0 |
1 | 197 | 0.0 |
1 | 0 | 0.0 |
1 | 141 | 1.0 |
1 | 127 | 1.0 |
1 | 120 | 0.0 |
1 | 194 | 0.0 |
PTADisc
This release contains 939 extracted data files (125.50 GB), with 128 configured subsets. Original-project overview statistics below are retained for context and are not recomputed counts for this distribution.
This dataset card reuses the original PTADisc README, with download links, paths, and release-specific notes adapted for this Hugging Face distribution. The original authors’ contact information is retained below. Licensed under CC BY-NC-SA 4.0.
PTADisc is sourced from PTA (Programming Teaching Assistant), a learner-based online system for universities and society developed by Hangzhou PAT Education Technology Co., Ltd.
PTADisc is a diverse, immense, student-centered dataset that emphasizes its sufficient cross-course information for personalized learning. It includes $74$ courses, $1,530,100$ students, $4,504$ concepts, $225,615$ problems, and over $680$ million student response logs.
We illustrate the characteristics of PTADisc from the following four aspects:
- Diverse: PTADisc contains rich concept-related information and fine-grained records of a large number of student behaviors.
- Immense: PTADisc is the largest dataset in personalized learning. It also includes different courses of different data scales which offer options for various studies.
- Student-centered: In PTADisc, problems and knowledge concepts are validated based on student response logs, leading to better consistency and well-maintainability in terms of diagnostic tasks.
- Cross-course: PTADisc covers a significant amount of students taking multiple courses as students are likely to take a series of courses according to their training program.
Loading the data
Select a course or experiment subset in the dataset viewer, or stream a subset with datasets:
from datasets import load_dataset

ds = load_dataset("whning0513/PTADisc", "cd_Probability_and_statistic")
logs = load_dataset(
    "whning0513/PTADisc", "non_programming_Python_programming",
    split="train", streaming=True,
)
row = next(iter(logs))
Configured CSV columns are exposed as strings to preserve source identifiers, timestamps, code, and empty fields without numeric inference. Cast columns as needed for analysis. Schemas follow each source CSV header. Unsplit source tables use the train split as a storage convention; it does not denote a curated training partition. Existing experiment train/validation/test splits are preserved. Supplementary JSON dictionaries, course information, matrices, and experimental variants are available as individual files.
To download all extracted files:
from huggingface_hub import snapshot_download
snapshot_download("whning0513/PTADisc", repo_type="dataset", local_dir="PTADisc")
Data repository structure
Data files are published directly in this dataset repository as extracted CSV, JSON, text, and model files. Browse the Files and versions tab or download individual files; no archive extraction or access request is required. The original project is available on GitHub.
The directory is organized as:
PTADisc/
├── scripts/
├── structured data/
│   ├── course_info/
│   ├── global data/
│   ├── non programming data/
│   └── programming data/
└── task specific dataset/
    ├── non_programming_dataset
    │   ├── baseline_dataset_for_CD
    │   ├── baseline_dataset_for_KT
    │   ├── cross_course_datasets
    │   └── datasets_for_CCLMF
    └── programming_datasets
| Leaf directory | Content |
|---|---|
| baseline_dataset_for_CD | $4$ selected courses' datasets for cognitive diagnosis. |
| baseline_dataset_for_KT | $4$ selected courses' datasets for knowledge tracing. |
| cross_course_datasets | datasets of $5$ courses which are simultaneously taken by $29,454$ students. |
| datasets_for_CCLMF | Java Programming datasets and pretrained NCD model on Python Programming, which is used to conduct CCLMF experiments. |
| programming_datasets | $4$ selected courses' datasets for knowledge tracing. |
Release note: The table above retains the original project’s dataset descriptions. The received source has empty baseline_dataset_for_KT and programming_datasets directories. Data files are published in extracted form, preserving their contents. Course archives lacking an enclosing directory have been placed in a directory named after the course. Embedded TAR.GZ backups are extracted under a separate _nested directory. See manifest.json for source mappings.
Detailed information of structured data
For futher information, please contact: liyahu@zju.edu.cn.
Global Data
Description
Global data includes:
| Filename | Description |
|---|---|
| knowledge_point_all.csv | The tree structure of all the knowledge concepts in PTADisc, which is in forms of knowledge_point_id, name, parent_id. |
| problem_difficulty.json | Global dictionary of problem_id to difficulty. |
| problem_knowledge.json | Global dictionary of problem_id to knowledge_id. |
| problem_reference_count.json | Global dictionary of problem_id to reference_count. |
| problem_type | Global dictionary of problem_id to problem_type. |
| psp_full_score.json | Global dictionary of problem_set_problem_id to full_score. |
| psp_problem.json | Global dictionary of problem_set_problem_id to problem_id. |
| psp_problem_set_id.json | Global dictionary of problem_set_problem_id to problem_set_id. |
The filenames above follow the received source data. The problem_type dictionary described in the original README is not provided as a separate global file in this release.
Knowledge Concept Example
parent_id=-1 indicates that it's the course's name, which is the root of its knowledge concept tree.
| knowledge_point_id | name | parent_id |
|---|---|---|
| 383 | 概率论与数理统计 | -1 |
| 384 | 随机事件和概率 | 383 |
| 393 | 随机变量及概率分布 | 383 |
| 389 | 全概率公式 | 384 |
| 390 | 贝叶斯公式 | 384 |
Problem Type
enum ProblemType {
    NO_PROBLEM_TYPE = 0;
    TRUE_OR_FALSE = 1;
    MULTIPLE_CHOICE = 2;
    MULTIPLE_CHOICE_MORE_THAN_ONE_ANSWER = 3;
    FILL_IN_THE_BLANK = 4;
    FILL_IN_THE_BLANK_FOR_PROGRAMMING = 5;
    CODE_COMPLETION = 6;
    PROGRAMMING = 7;
    SUBJECTIVE = 8;
    MULTIPLE_FILE = 9;
    }
Non-programming data
Description
Each course contains the following files:
| Filename | Description |
|---|---|
| info/info.json | Record the number of the course's concepts, students, problems and logs. |
| info/concept_list.txt | Record the course's concept IDs. |
| info/student_list.txt | Record the course's student IDs. |
| info/problem_list.txt | Record the course's problem IDs. |
| problem_info.csv | Record problems' problem_set_problem_id, problem_id, knowledge_id, full_score in the course. |
| response_log.csv | Record logs' submission_id, user_id, create_at, problem_type, score, problem_set_id, problem_set_problem_id, status in the course. |
response_log.csv fields description:
submission_id: the ID of one commit record of a problem set.problem_type: 1 represents true or false, 2 represents single-choice, 3 represents multiple-choice, and 4 represents fill-in-the-blank.score: the scoring ratio the student get on this problem.status: auxiliary field to calculate student's score on this problem, contains ACCEPTED, WRONG_ANSWER, PARTIAL_ACCEPTED, etc.
Logs Example
| submission_id | user_id | create_at | problem_type | score | problem_set_id | problem_set_problem_id | status |
|---|---|---|---|---|---|---|---|
| 178060 | 0fa9733a132497dd515d426df206b67106364354b579231879e3c8f70630e431 | 2015/10/13 16:47 | 2 | 2 | 139 | 1746 | ACCEPTED |
| 178060 | 0fa9733a132497dd515d426df206b67106364354b579231879e3c8f70630e431 | 2015/10/13 16:47 | 2 | 0 | 139 | 1747 | WRONG_ANSWER |
| 178060 | 0fa9733a132497dd515d426df206b67106364354b579231879e3c8f70630e431 | 2015/10/13 16:47 | 2 | 0 | 139 | 1748 | WRONG_ANSWER |
| 178060 | 0fa9733a132497dd515d426df206b67106364354b579231879e3c8f70630e431 | 2015/10/13 16:47 | 2 | 2 | 139 | 1749 | ACCEPTED |
| 178060 | 0fa9733a132497dd515d426df206b67106364354b579231879e3c8f70630e431 | 2015/10/13 16:47 | 2 | 2 | 139 | 1750 | ACCEPTED |
Programming data
Description
Each course contains a response_log.csv with fields: submission_id, user_id, create_at, language , score, problem_set_problem_id, problem_id, skill_id, code, response, time_consume, memory_consume. Some of the fields description:
submission_id: the same as in non_programming data.language: the programming codescore: the same as in non_programming data.code: the code submitted by the student.response: the same asstatusin non_programming data.time_consume: time consumed by the submitted code.memory_consume: memory consumed by the submitted code.
Logs Example
| submission_id | user_id | create_at | language | score | problem_set_problem_id | problem_id | skill_id | code | response | time_consume | memory_consume |
|---|---|---|---|---|---|---|---|---|---|---|---|
| 1523963863660281856 | 82e2f8cab241392f2ffae8614297ed854b6113256c5c8d31cf2d14740a68706b | 2022-05-10 17:51:13 | Java | 0.0 | 1523908485467762710 | 1013962033606774784 | 201 | import java.util.*;\npublic class Main {\n public static void main(String[] args) {\n Scanner sc = new Scanner(System.in);\n int n = sc.nextInt();\n List list = new ArrayList();\n for (int i = 0; i < n; i++) {\n list.add(sc.nextInt());\n }\n list.sort(Comparator.naturalOrder());\n System.out.println(list.get(list.size()-2));\n }\n} | WRONG_ANSWER | 125 | 18404 |
| 1523963973706231808 | 82e2f8cab241392f2ffae8614297ed854b6113256c5c8d31cf2d14740a68706b | 2022-05-10 17:51:39 | Java | 0.0 | 1523908485467762710 | 1013962033606774784 | 201 | import java.util.*;\npublic class Main {\n public static void main(String[] args) {\n Scanner sc = new Scanner(System.in);\n int n = sc.nextInt();\n List list = new ArrayList();\n for (int i = 0; i < n; i++) {\n list.add(sc.nextInt());\n }\n list.sort(Comparator.naturalOrder());\n System.out.print(list.get(list.size()-2));\n }\n} | WRONG_ANSWER | 113 | 15232 |
Course Info
Description
The files of course info provide additional information of user group and problem set. Each course contains the following files:
| Filename | Description |
|---|---|
| user_group_member.csv | Record the user group members. |
| user_group_problem_set.csv | Record the opened problem sets for user groups. |
| problem_set.csv | Record the problem set's start time and end time. |
User Group Member Example
user_group_member_id is the id of a (user_id, user_group_id) pair.
| user_group_member_id | user_id | user_group_id |
|---|---|---|
| 1041674784427282432 | e7de9a3c1163736606a53e738cdb82a29f860903e84e14c61f13b31f82706d28 | 1041661419302744064 |
| 1041680824921296896 | 95c2f1226984fee4c1748e567279808b02e5128dbd1060ebd4692dbe164000a6 | 1041661579701325824 |
| 1041680824535420928 | 8e3f445a0fae30aef3daf067d1bebf648ca84181c21a924560f9a9a1f1d1504c | 1041661579701325824 |
User Group - Problem Set Example
| user_group_problem_set_id | user_group_id | problem_set_id |
|---|---|---|
| 1053296011098509312 | 1041661579701325824 | 1053295797428080640 |
| 1053296069663563776 | 1041661419302744064 | 1053295797428080640 |
| 1057397021588357120 | 1041661419302744064 | 1057375475356430336 |
Problem Set Example
| problem_set_id | start_at | end_at |
|---|---|---|
| 1057375475356430336 | 2018-11-02 12:00:00 | 2018-11-21 12:00:00 |
| 1118521024520945664 | 2019-04-17 22:24:00 | 2019-04-18 22:24:00 |
| 1119973878406443008 | 2019-04-21 22:38:00 | 2019-04-28 22:38:00 |
Statistics
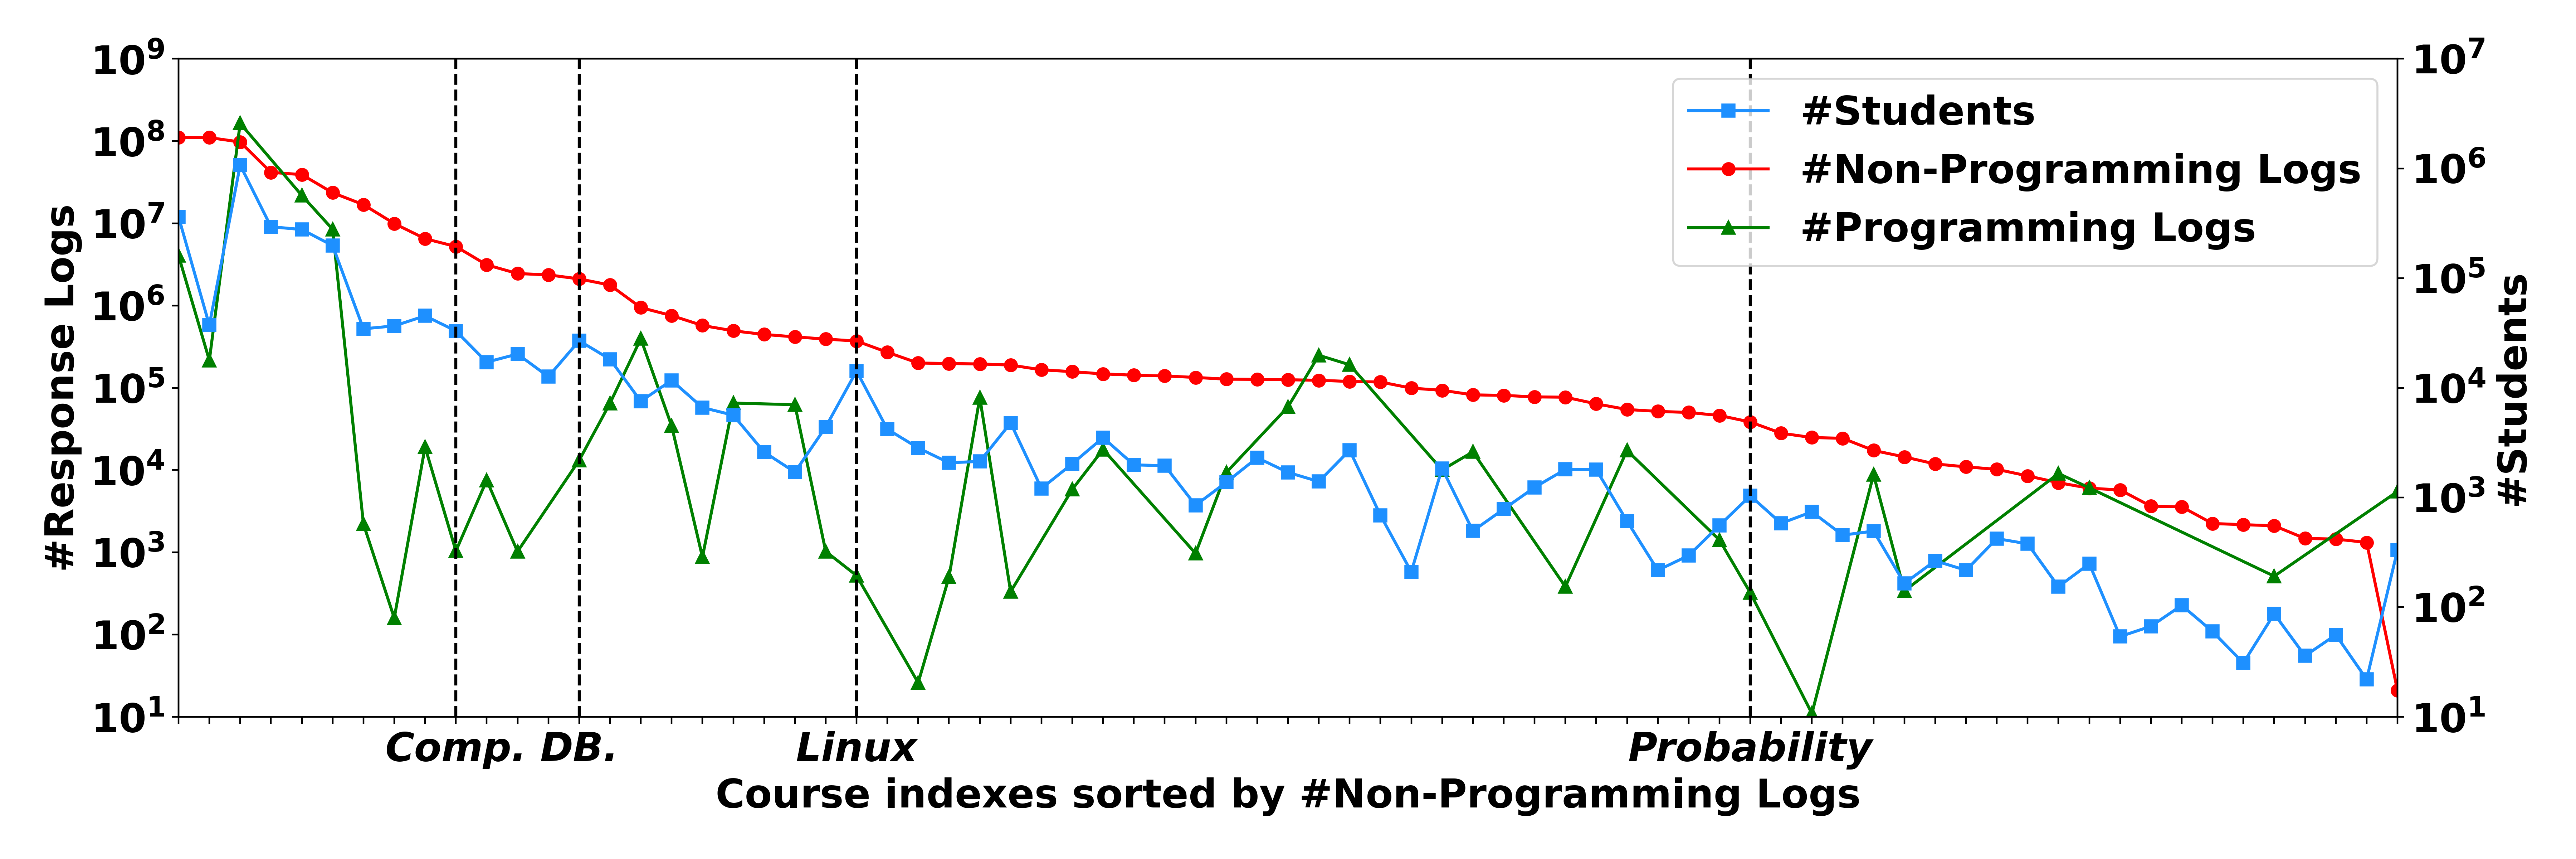
Detailed statistics of each course's students, problems, concepts, non_programming_logs and programming_logs can be found in statistics.xlsx.
CCLMF
Details can be found in README.md.
Citation
@inproceedings{hu2023ptadisc,
  title={PTADisc: A Cross-Course Dataset Supporting Personalized Learning in Cold-Start Scenarios},
  author={Hu, Liya and Dong, Zhiang and Chen, Jingyuan and Wang, Guifeng and Wang, Zhihua and Zhao, Zhou and Wu, Fei},
  booktitle={Thirty-seventh Conference on Neural Information Processing Systems Datasets and Benchmarks Track},
  year={2023}
}
- Downloads last month
- 163