

Panda-CVL Training Split
Overview
Panda-CVL is a token-level correction dataset and benchmark annotated with the onPanda tool. Given a question-response pair, the model first judges whether the response is acceptable. If correction is needed, it must locate the first inappropriate token and replace it with an appropriate one, so generation can continue from the "correct prefix + corrected token" state and ultimately produce an acceptable response.
Compared with prior data that only identifies which step an error occurs in, Panda-CVL provides two finer-grained supervision signals: token-level error localization and the correction direction itself. The model must not only point out which token is inappropriate, but also provide the token it should be changed to.
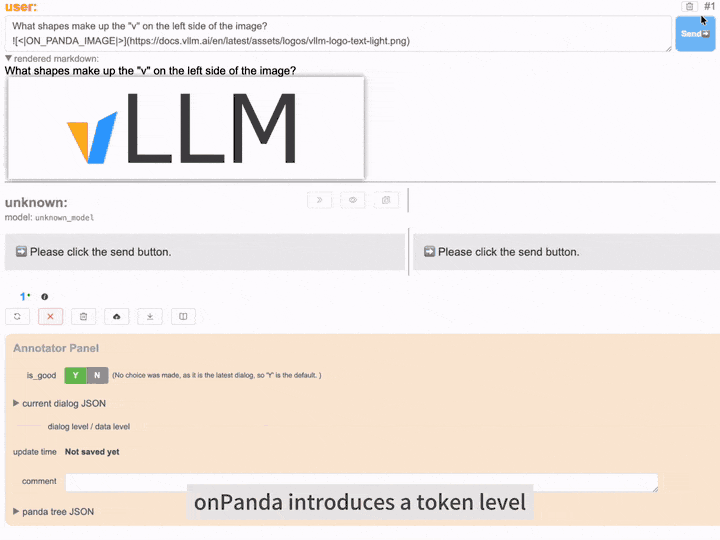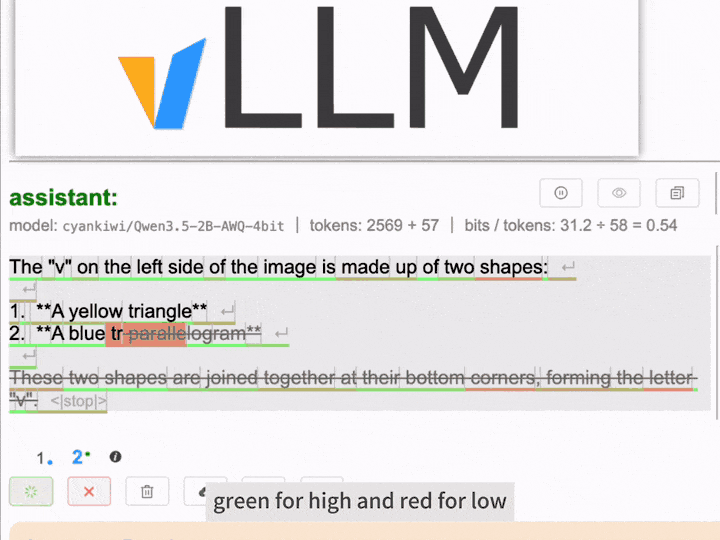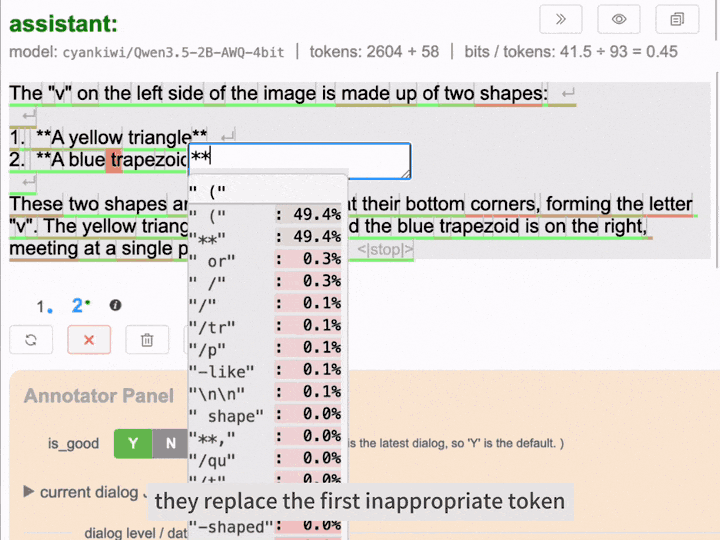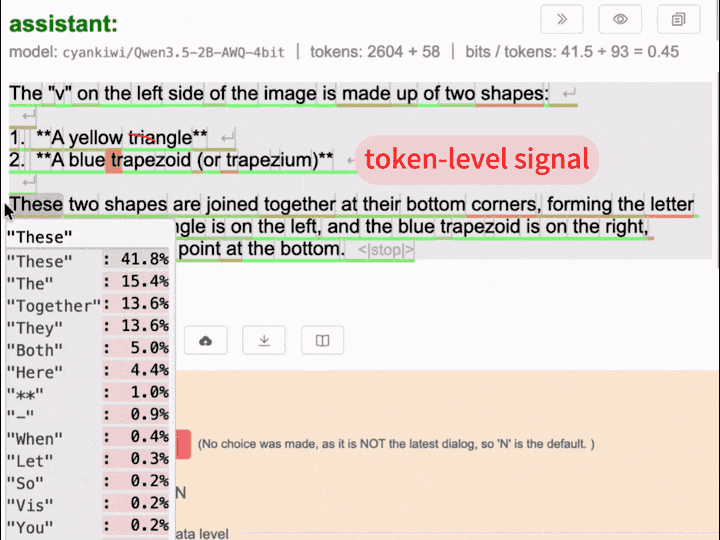
The token-level correction interface used for annotating Panda-CVL.
This directory contains the publicly released training split of
Panda-CVL.
It contains 6913 Panda JSON files.
The benchmark test split is available separately at
diyer22/Panda-CVL-test.
Download and parse
The data is distributed in the custom Panda JSON format. Each .panda.json file
stores an annotation tree with one or more dialogs and their annotations; the
number of files is not the number of exported supervision examples.
Download the files with huggingface_hub and parse them with onpanda.
pip install -U huggingface_hub onpanda
from pathlib import Path

import onpanda
from huggingface_hub import snapshot_download

root = snapshot_download(
    repo_id="diyer22/Panda-CVL-train",
    repo_type="dataset",
    local_dir="./Panda-CVL-train",
)
panda_files = sorted(Path(root).rglob("*.panda.json"))
print(f"Found {len(panda_files)} Panda JSON files.")

# Parse one annotation tree using the built-in tokenizer for this example.
panda_tree = onpanda.PandaTree(str(panda_files[0]), onpanda.utf8_tokenizer)
print(panda_tree)
When deriving token-level supervision for a model, use that model's tokenizer. See the Python parser documentation for data conversion examples and the Panda JSON format documentation for the file structure.
Publication metadata
Hugging Face repository: diyer22/Panda-CVL-train.
License: CC0 1.0 Universal (Public Domain Dedication).
- Downloads last month
- -