

The dataset viewer is not available for this dataset.
Error code:   ConfigNamesError
Exception:    TypeError
Message:      Value.__init__() missing 1 required positional argument: 'dtype'
Traceback:    Traceback (most recent call last):
                File "/src/services/worker/src/worker/job_runners/dataset/config_names.py", line 67, in compute_config_names_response
                  config_names = get_dataset_config_names(
                      path=dataset,
                      token=hf_token,
                  )
                File "/usr/local/lib/python3.14/site-packages/datasets/inspect.py", line 161, in get_dataset_config_names
                  dataset_module = dataset_module_factory(
                      path,
                  ...<4 lines>...
                      **download_kwargs,
                  )
                File "/usr/local/lib/python3.14/site-packages/datasets/load.py", line 1182, in dataset_module_factory
                  raise e1 from None
                File "/usr/local/lib/python3.14/site-packages/datasets/load.py", line 1157, in dataset_module_factory
                  ).get_module()
                    ~~~~~~~~~~^^
                File "/usr/local/lib/python3.14/site-packages/datasets/load.py", line 692, in get_module
                  config_name: DatasetInfo.from_dict(dataset_info_dict)
                               ~~~~~~~~~~~~~~~~~~~~~^^^^^^^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/info.py", line 284, in from_dict
                  return cls(**{k: v for k, v in dataset_info_dict.items() if k in field_names})
                File "<string>", line 20, in __init__
                File "/usr/local/lib/python3.14/site-packages/datasets/info.py", line 170, in __post_init__
                  self.features = Features.from_dict(self.features)
                                  ~~~~~~~~~~~~~~~~~~^^^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/features/features.py", line 2023, in from_dict
                  obj = generate_from_dict(dic)
                File "/usr/local/lib/python3.14/site-packages/datasets/features/features.py", line 1602, in generate_from_dict
                  return {key: generate_from_dict(value) for key, value in obj.items()}
                               ~~~~~~~~~~~~~~~~~~^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/features/features.py", line 1621, in generate_from_dict
                  return class_type(**{k: v for k, v in obj.items() if k in field_names})
              TypeError: Value.__init__() missing 1 required positional argument: 'dtype'
Need help to make the dataset viewer work? Make sure to review how to configure the dataset viewer, and open a discussion for direct support.
EmbodiedCLBench: Evaluating Continual Learning for Self-Evolving Embodied Agents
The first benchmark in embodied simulation for evaluating
the continual learning capability of self-evolving agents



Jie Huang★,1,2
Yanan Chen★,1
Ruixun Liu★,1
Kaichen He1
Xinyi He1
Rui Huang3
Zilong Zheng2
Zhenliang Zhang2
Yiwu Zhong1,2,†
1School of Intelligence Science and Technology, Peking University
2State Key Laboratory of General Artificial Intelligence, BIGAI, Beijing, China
3University of Hong Kong
★ Equal contribution. † Corresponding author.
Core design
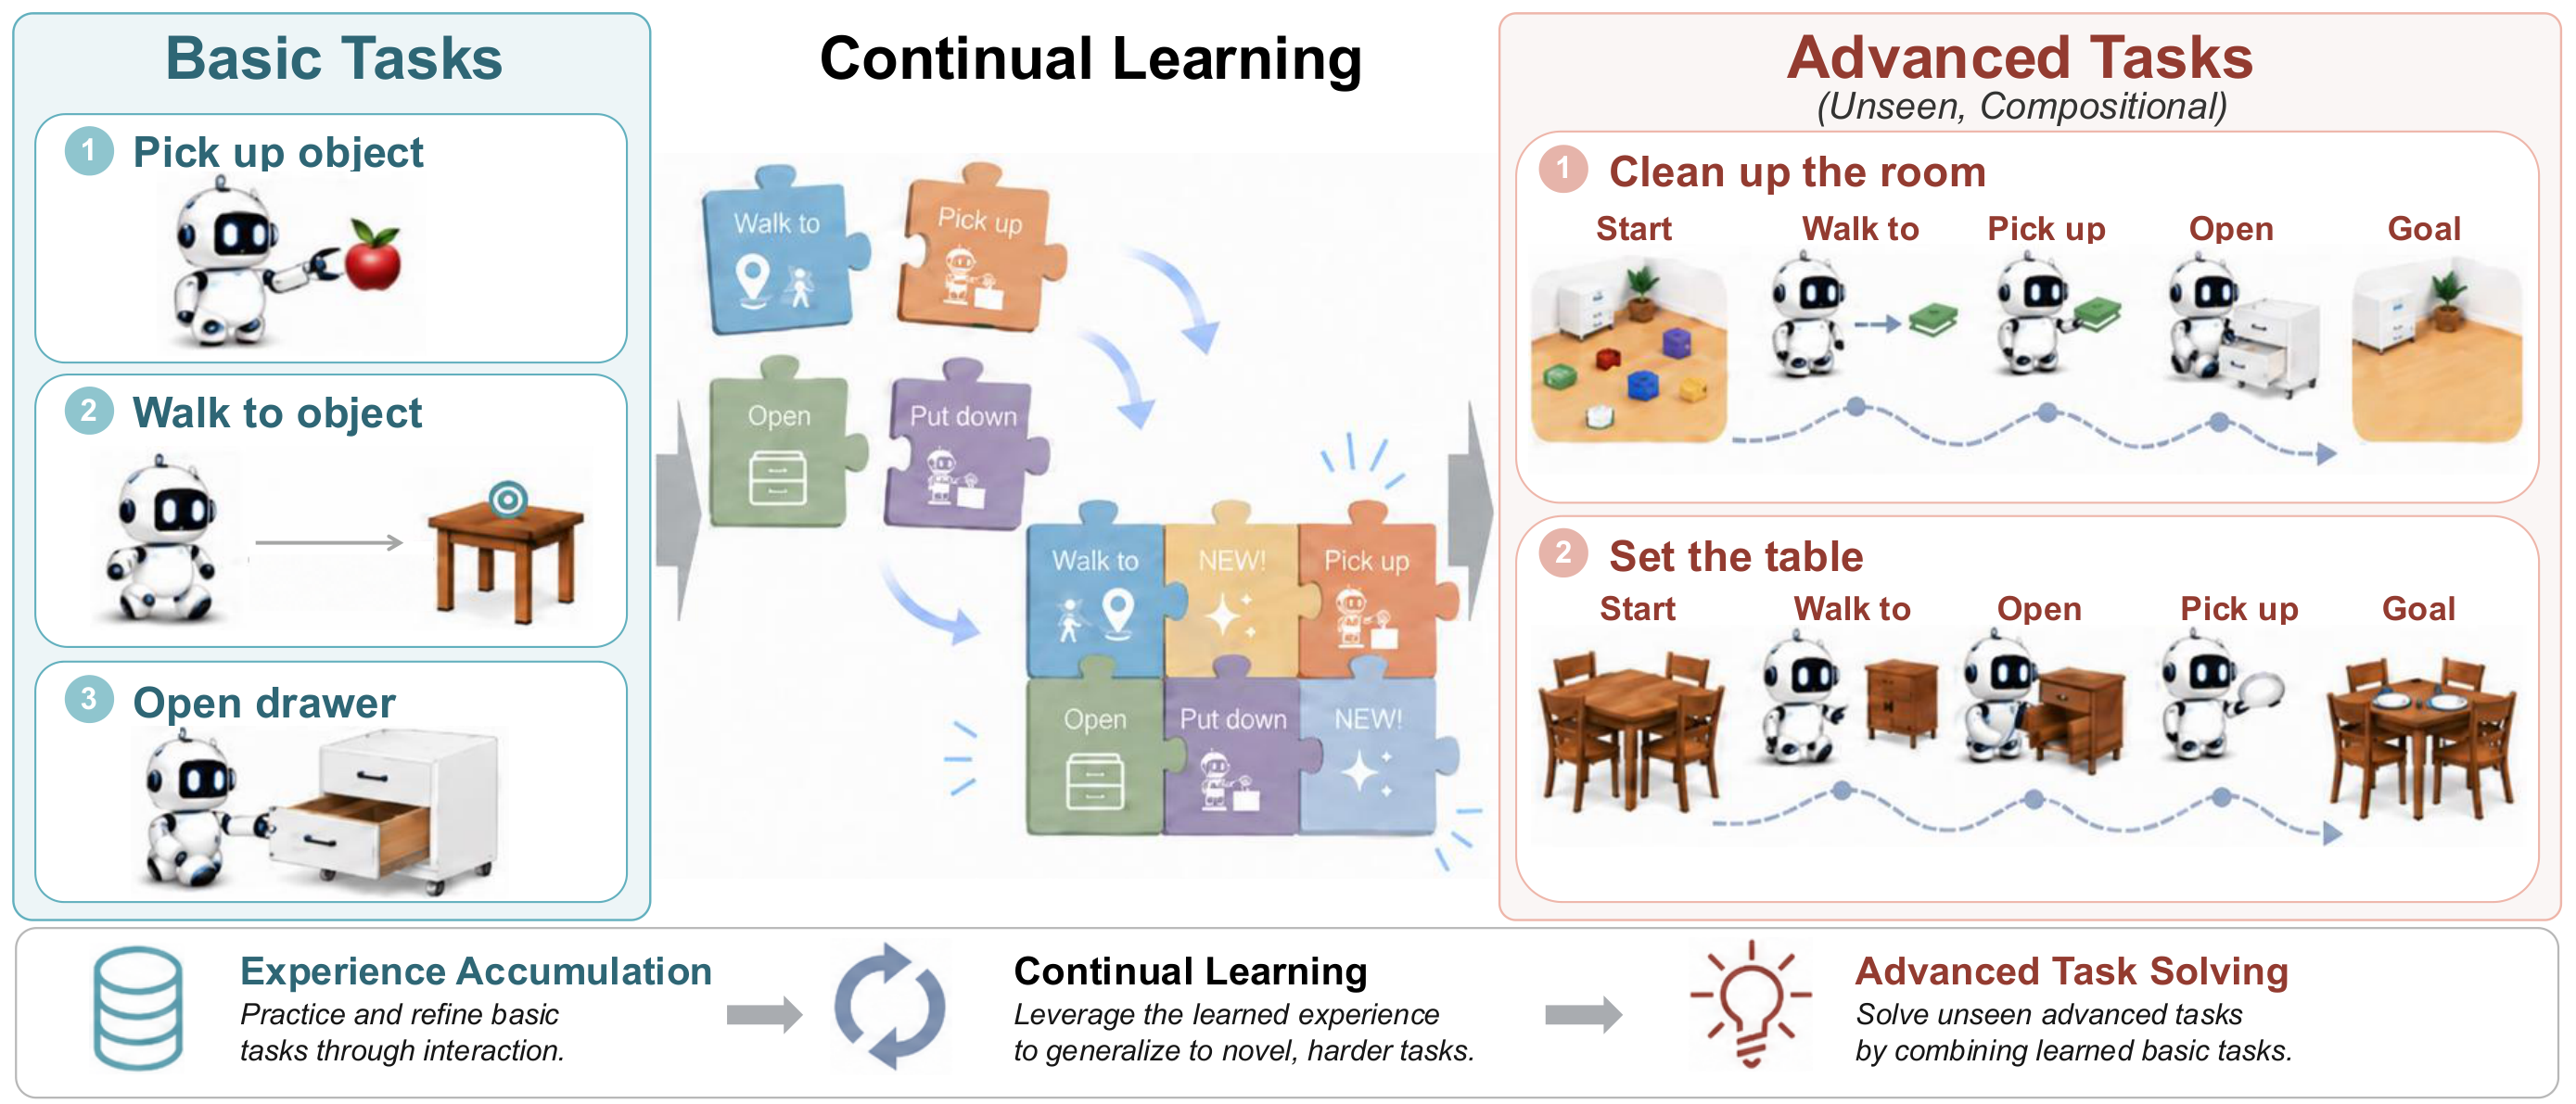
We operationalize continual learning through compositional generalization: an agent first completes simpler tasks to accumulate experience, then is tested on whether it can recombine the acquired skills to solve more complex, unseen tasks.
Abstract
Continual learning requires models to accumulate past experience and transfer it to new tasks. Despite substantial research on continual learning, existing work remains largely confined to non-embodied settings, without extending to embodied environments.
To address this gap, we introduce EmbodiedCLBench, the first benchmark in embodied simulation for evaluating the continual learning capability of self-evolving agents. With compositional generalization as the core evaluation principle, our benchmark evaluates whether agents can first learn from basic tasks and then recombine the acquired skills to solve complex, unseen advanced tasks. Based on EmbodiedCLBench, we conduct extensive experiments across multiple agent harnesses and learning methods, revealing consistent limitations and distinctive behaviors.
Our results show that while advanced tasks can be hardly solved under zero-shot setting, the experience from basic tasks enables consistent improvement. Such benefit from the experience remains stable even if the task complexity increases. However, this improvement does not scale accordingly with the number of learning samples, and current agents cannot extract meaningful information from additional experience. Collectively, our findings highlight continual learning as a fundamental yet underexplored capability, and our benchmark offers valuable resources for designing effective self-evolving agents in embodied environments.
Benchmark Construction
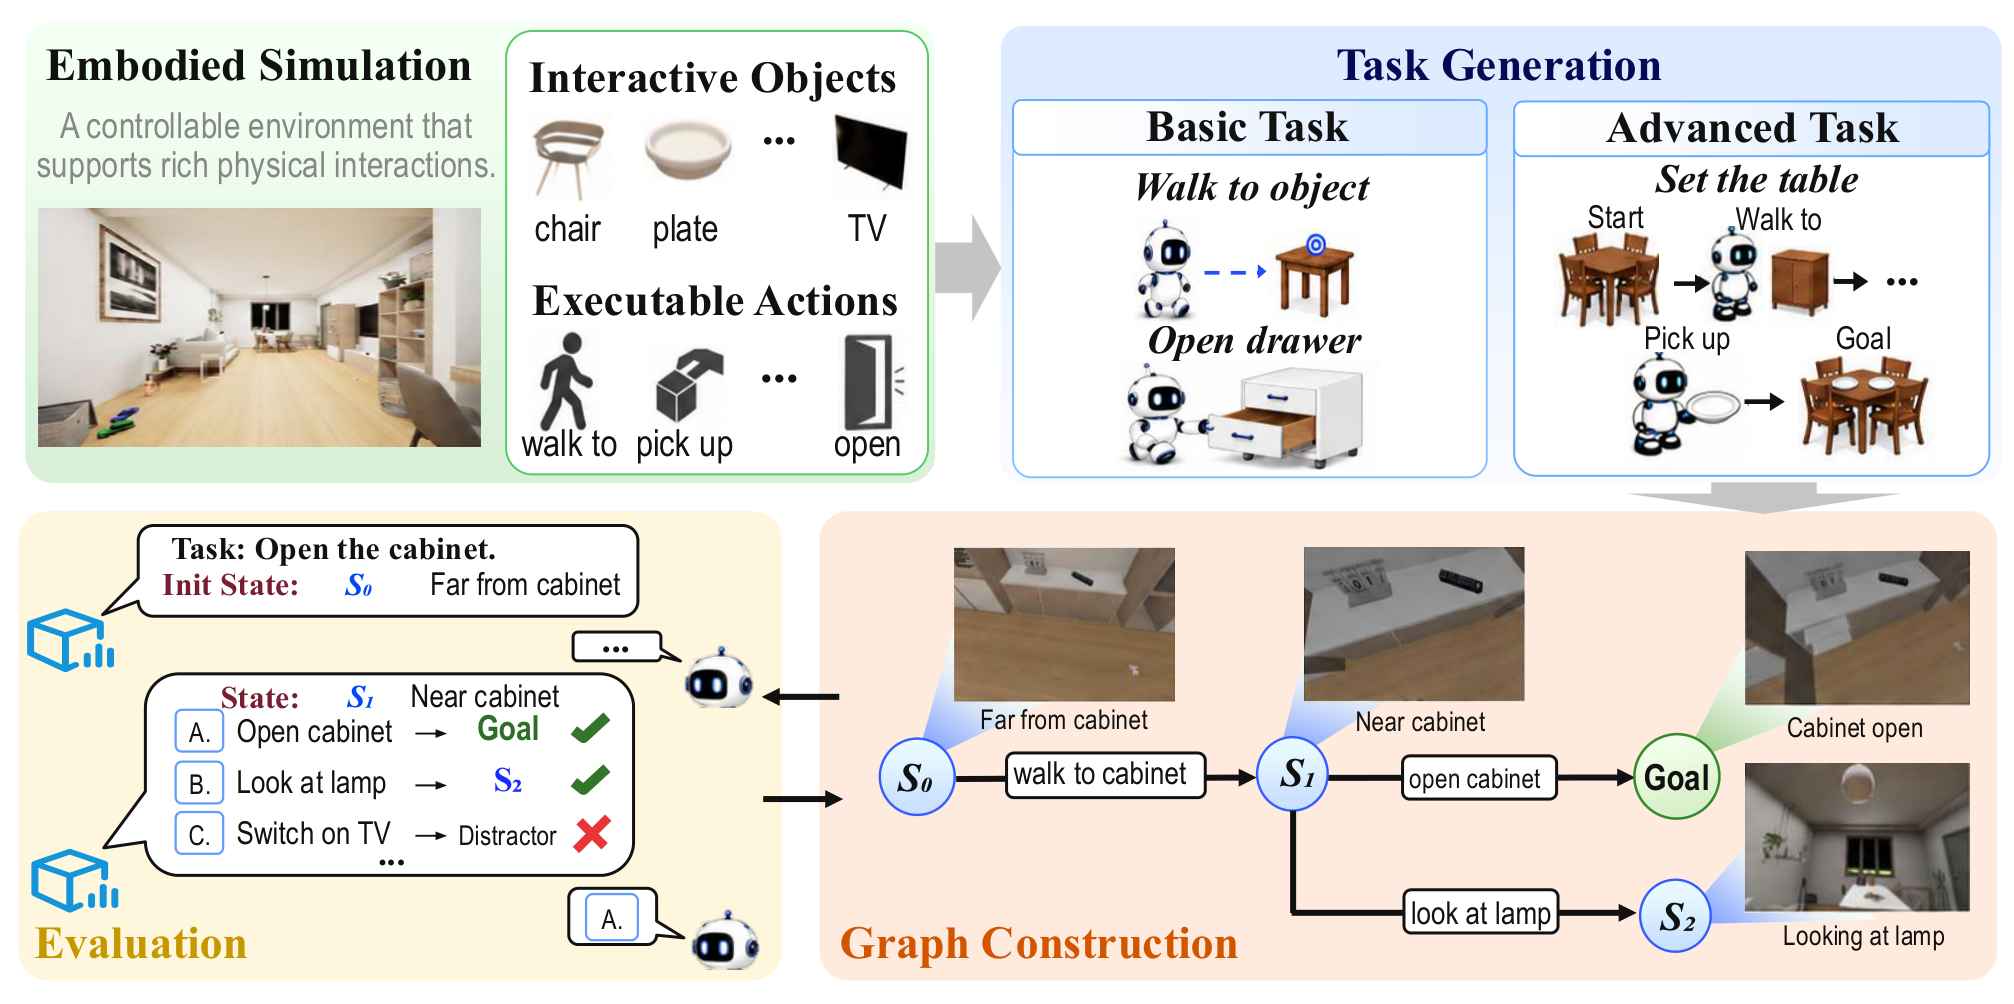
Overview of the construction process
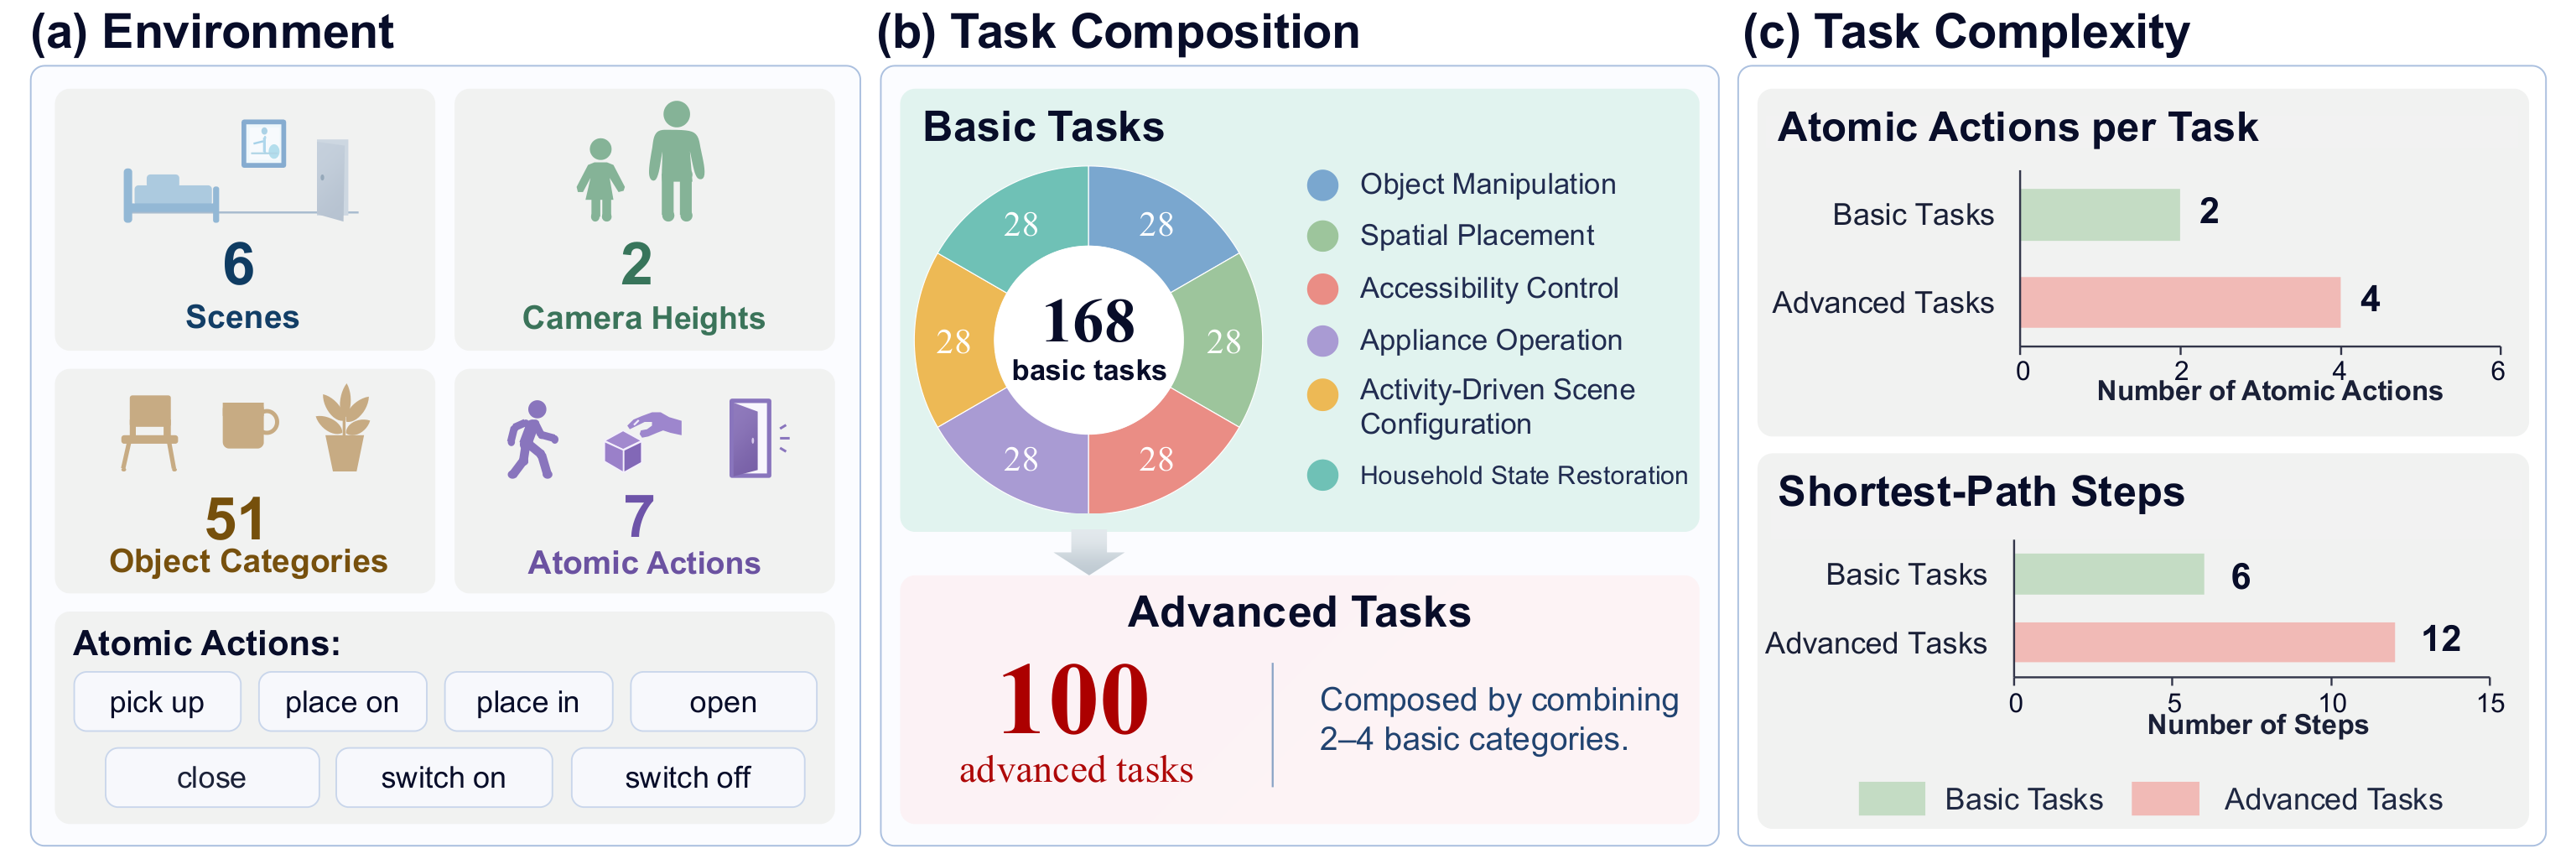
Benchmark statistics
Main Results
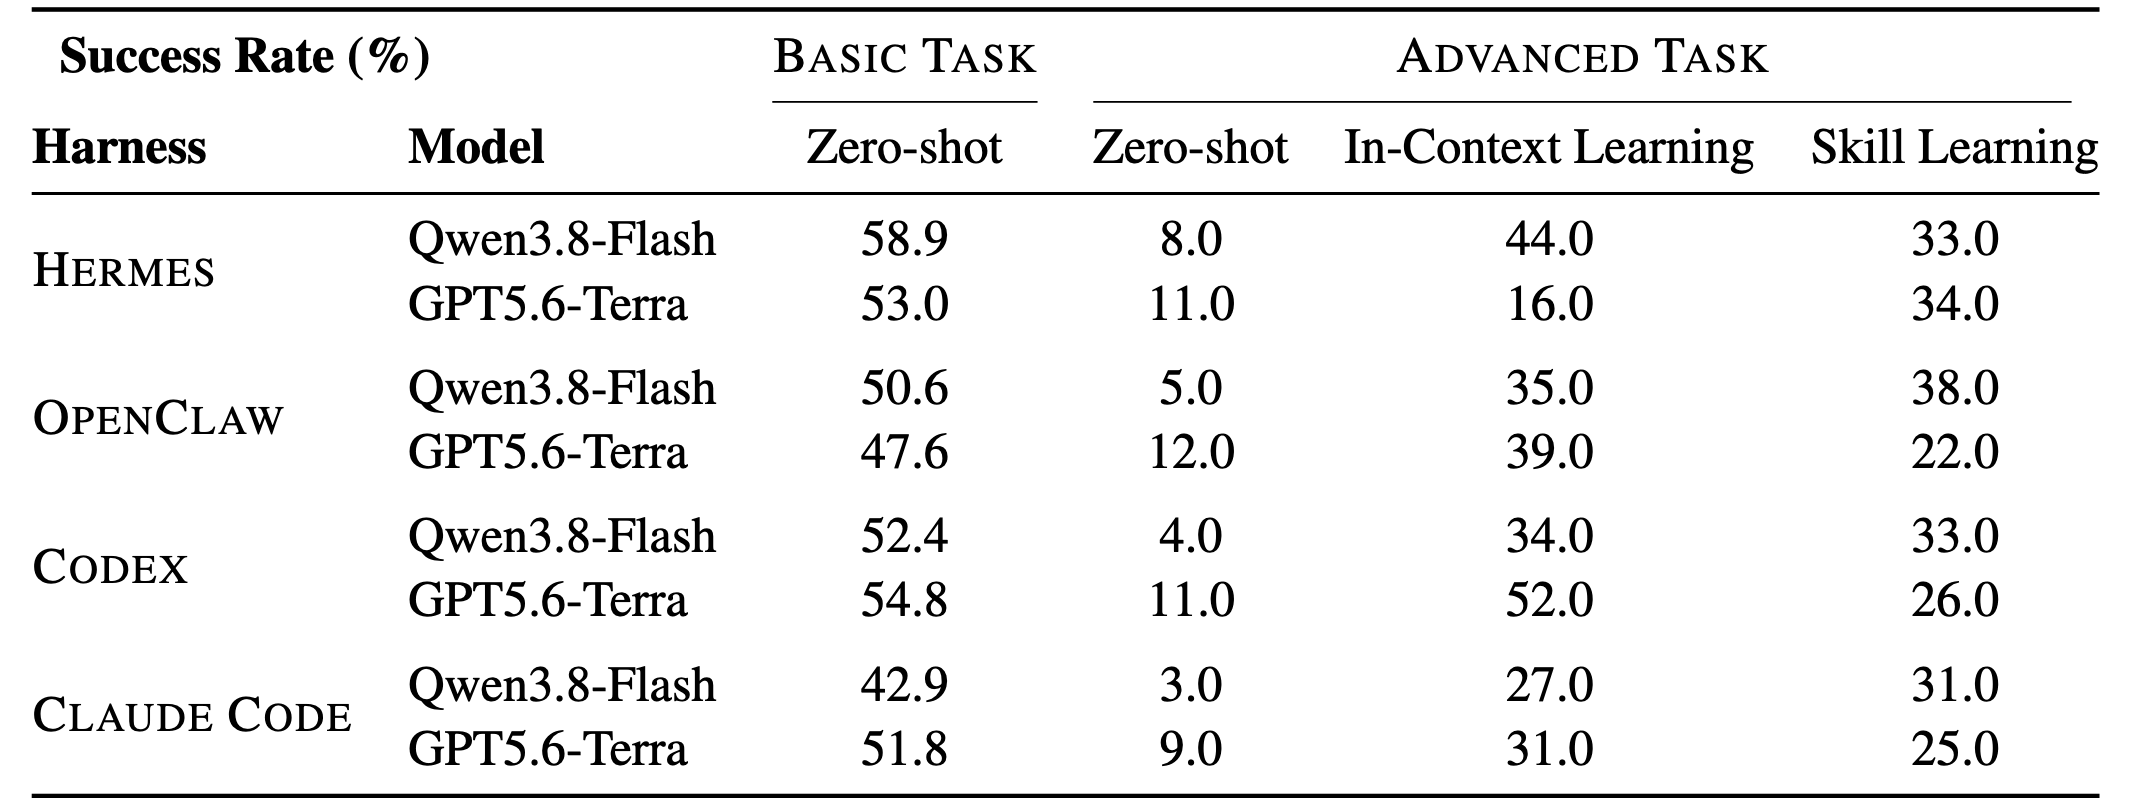
(1) Zero shot: the agent attempts tasks directly without prior experience. (2) In-Context Learning (ICL): the agent first completes two related basic tasks, retaining the full interaction history in context for the advanced task. (3) Skill Learning: the same learning phase as ICL, but the agent distills its experience into a concise skill summary, which replaces the raw trajectories at test time.
Citation
- Downloads last month
- 17