

The dataset viewer should be available soon. Please retry later.

Continual Learning Exam · CLE Lite
Evaluating how agents acquire, retain, and reuse experience across professional workflows.
CLE Team
20 professional tasks · 5 connected levels per task · 100 assignments


CLE Lite is a 20-task release of Continual Learning Exam (CLE). Each task follows a professional workflow across five assignments. Later assignments build on earlier work, add new evidence, and test whether an agent can use what it has learned.
This is the public home of CLE Lite. Browse 100 task cards in the Dataset Viewer above: each card includes the assignment, expected inputs and outputs, and an input-file inventory. Agent-facing files are available in CLE Lite Workspaces. Complete packages, including the runtime and grading material, are available in CLE Lite Full after access approval.
Start here · About CLE · Quick start · Tasks · Evaluation · Results · Citation
Start here
| I want to… | Start with | Access |
|---|---|---|
| Read the 100 assignments | Task Cards | Public |
| Inspect the files supplied to agents | Task Inputs | Public |
| Download a task package | CLE Lite Full | Approval required |
| Run an agent and score its work | Quick start and evaluation guide | Archive access, Linux, Docker, and model access |
About CLE
Continual Learning Exam (CLE) measures whether agents can learn from experience and use it in later work. Built by 50+ domain experts, the benchmark contains 120 human-authored tasks, spanning 89 professional roles across 12 domains.
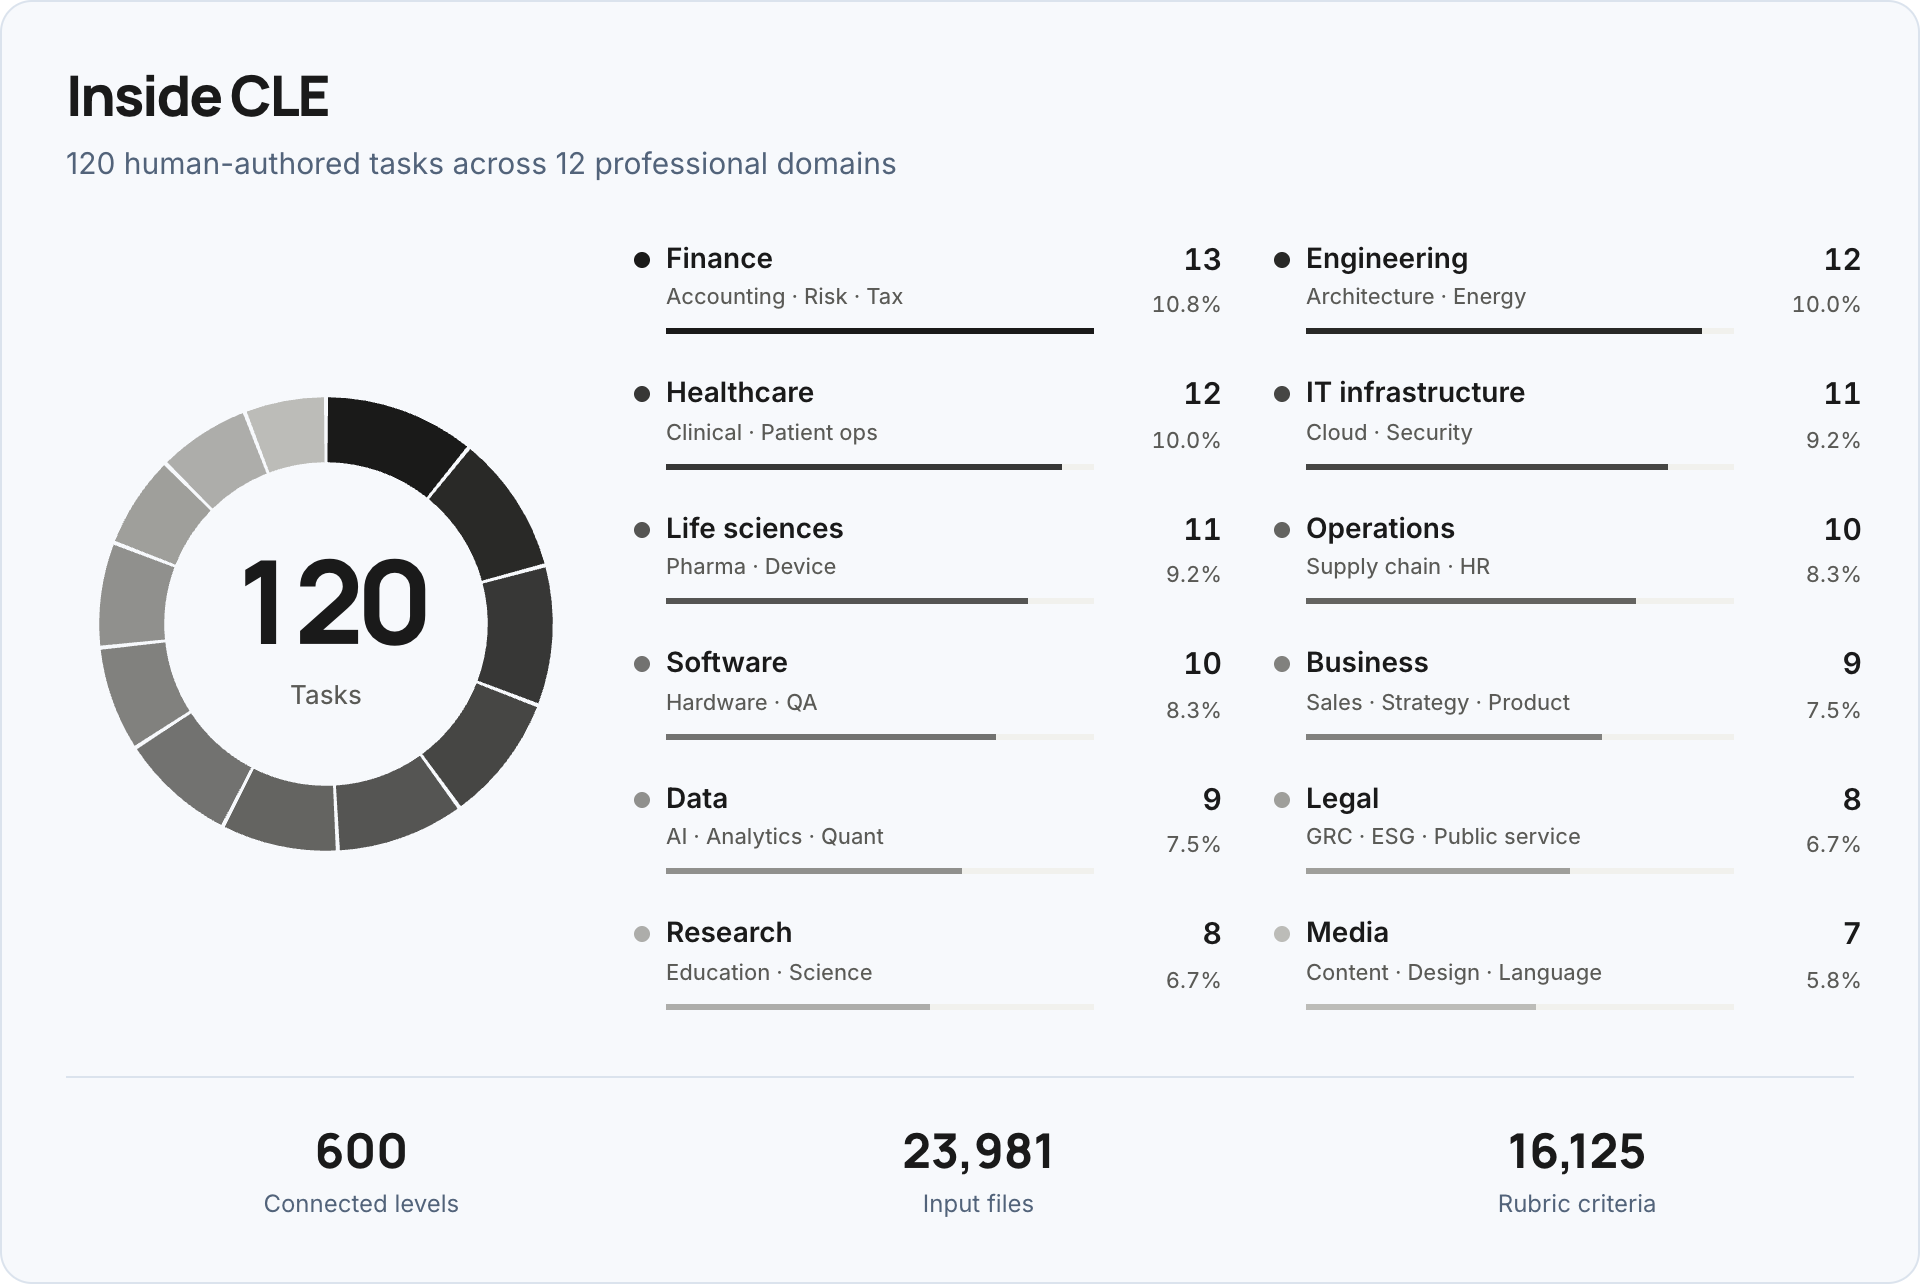
Explore the interactive breakdown →
Each task is a ladder of five connected assignments, giving 600 levels in total. Passing a level unlocks the next; files, environment state, and accumulated experience carry forward. Human-authored rubrics determine whether each submission passes.
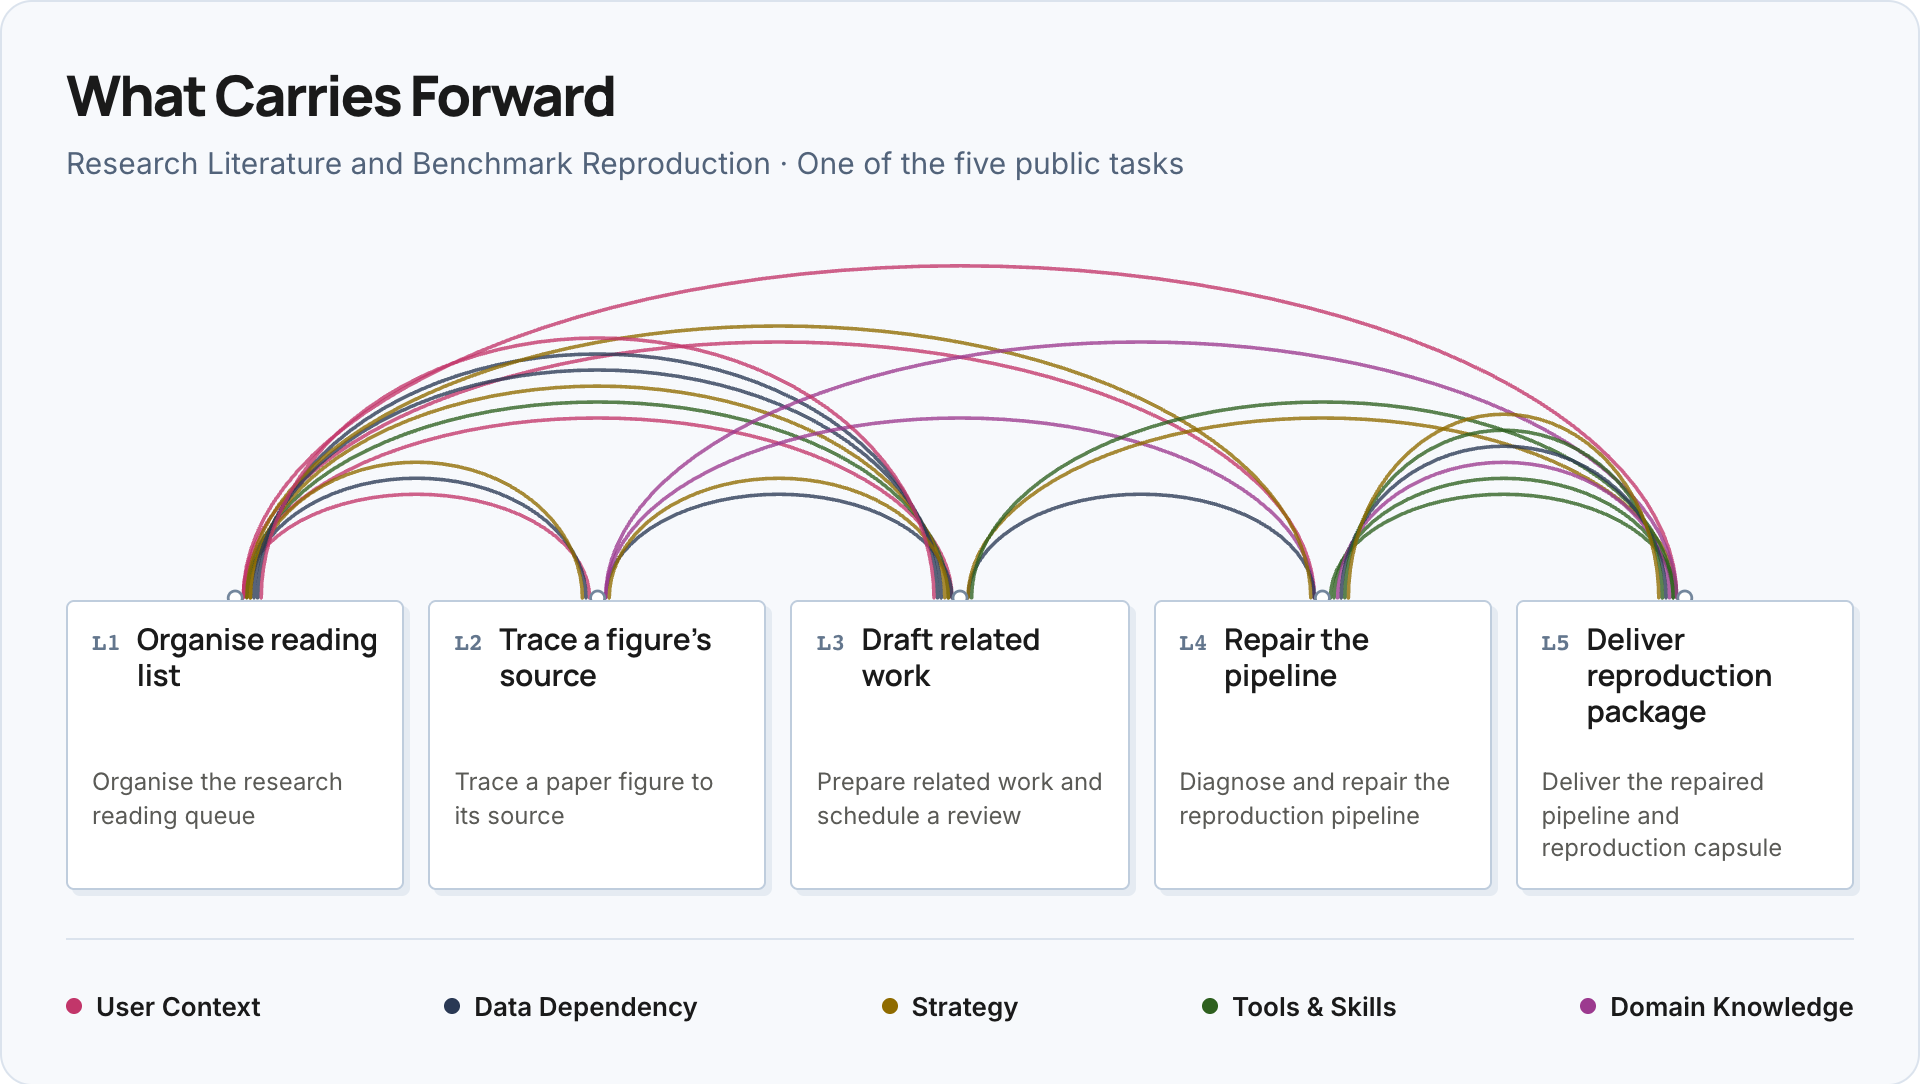
Explore this example → · Benchmark design
The overview figures describe the full CLE benchmark. This repository contains CLE Lite: 20 tasks and 100 levels.
Quick start
To inspect the assignments, open the public task cards. To run the Conversational Agent Evaluation task, first request access to CLE Lite Full, then follow the commands below. The runtime script downloads and verifies the task, prepares the grader, runs all five levels, and scores the submitted work.
Requirements: approved dataset access; Linux x86-64; Docker with Compose; curl; uv; Node.js 22 or later; and a Codex login with access to the selected model. Allow at least 30 GB of disk space for this example. A complete run can take several hours and uses model inference for both the agent and the grader.
The commands use the task and dependency versions from the maintainers' verified Linux run, with the download address updated for the repository rename. This example uses the Lite runtime protocol described under Evaluation. For setup details and regrading an existing submission, see the evaluation guide.
1. Download the runtime and task
uv tool install huggingface_hub
hf auth login

# Fetch the runtime adapter and its Linux judge-container recipe.
hf download Continual-Learning-Exam/CLE-Lite-Full \
    --repo-type dataset \
    --revision 811f03a38c894152f6df3f79ff1ebeda44a9a859 \
    --include 'runtime/*' --local-dir .

TASK=019-computer-research-scientist
DATA_REVISION=04014384175aeb218c4ba7188612b1c76e87d3fc
BUNDLE="./CLE-Lite/$TASK/harbor"
RUNTIME_ENV="./.cle-runtime-$TASK"

uv run --no-project --with huggingface_hub python runtime/cle_lite.py download \
    --task "$TASK" --directory ./CLE-Lite --revision "$DATA_REVISION"
Use the script's download command for evaluation. It verifies the recorded file hashes and restores the permissions and timestamps required by the grader. A regular hf download is suitable for browsing the archive.
2. Prepare the environment
uv run --no-project python runtime/cle_lite.py setup \
    --bundle "$BUNDLE" --env "$RUNTIME_ENV"

npm install --global --prefix ./.cle-tools @openai/codex@0.160.0
export PATH="$(pwd)/.cle-tools/bin:$PATH"
codex login --device-auth

docker build -t cle-lite-codex-worker:0.160.0 \
    -f runtime/codex-worker.Dockerfile runtime

export RSI_CODEX_DOCKER_IMAGE=cle-lite-codex-worker:0.160.0
export RSI_CODEX_AUTH_FILE="$HOME/.codex/auth.json"
export RSI_CODEX_TRANSPORT=https
export RSI_CODEX_REASONING_EFFORT=high
setup installs the task's recorded Python version, dependencies, and Harbor 0.22.0 in a separate environment. If you already have a Codex login, skip the login command and set RSI_CODEX_AUTH_FILE to that login's auth.json.
3. Run and inspect the result
uv run --no-project python runtime/cle_lite.py run \
    --bundle "$BUNDLE" --env "$RUNTIME_ENV" \
    --agent codex --model openai/gpt-6.1-sol \
    --judge-backend codex --judge-model gpt-6.1-sol \
    --codex-auth "$RSI_CODEX_AUTH_FILE" \
    --results ./results/019-gpt-6.1-sol-01
Use a new results directory for each run. The script also runs two controls: a reference submission that checks the grader, and an empty submission that should fail. Results are written to results/019-gpt-6.1-sol-01/run.json, with per-level checks, control outcomes, and paths to the detailed grading reports.
See how to inspect results and how to interpret the scores. Record both the runtime revision and DATA_REVISION with your experiment.
Tasks
For a guided introduction to the broader benchmark, the interactive task browser presents selected public examples with file previews. Use this dataset's Task Cards to browse all 100 CLE Lite assignments.
Related datasets
| Dataset | Contents | Access |
|---|---|---|
| CLE-Lite — this repository | 100 level records with instructions, expected inputs and outputs, software, and file inventories | Public |
| CLE-Lite-Workspaces | Files supplied to agents, level instructions, source notices, and provenance | Public |
| CLE-Lite-Rubrics | Evaluation rubrics and reference answers | Approval required |
| CLE-Lite-Full | Complete task packages, container environments, simulated workplace services, runtime, evaluation material, and reference solutions | Approval required |
Package layout
In CLE Lite Full, task directories are named <number>-<occupation>. Each contains three versions of the task:
| Directory | Purpose |
|---|---|
harbor/ |
A Harbor package with container environments, five task steps, verifier hooks, and reference material |
cle/<package>/ |
Instructions, input files, rubrics, and reference data organised by level |
cle-mock/<package>/ |
A version with simulated workplace services, such as email, chat, drives, and issue trackers |
Each task also includes final.json, which records acceptance of the released package.
View the equity research task's directory structure
001-equity-research-analyst/
├── harbor/
│   ├── task/
│   │   ├── task.toml          # Harbor configuration, resources and five linked steps
│   │   ├── instruction.md     # Initial assignment
│   │   ├── steps/             # Per-level instructions: t1/ through t5/
│   │   ├── environment/       # Dockerfile, Compose configuration and workspace assets
│   │   ├── tests/             # Verifier entry point and separate verifier environment
│   │   └── solution/          # Reference-solution entry point
│   ├── private/               # Judge-side checks, reference material and task metadata
│   ├── build.json             # Build record
│   └── freeze.json            # Frozen-file hashes
├── cle/software-cash-ownership/
│   ├── test/                  # Agent-facing instructions: t1.md through t5.md
│   ├── workspace/             # Input files organised by level
│   ├── eval/                  # Rubrics, ground truth and isolated-level seeds
│   ├── _meta/                 # Package metadata and reference programs
│   ├── NOTICE.md              # Third-party sources and terms
│   └── PROVENANCE.md          # Source retrieval details
├── cle-mock/software-cash-ownership/
│   ├── fixtures.yaml          # Mock-service fixture configuration
│   ├── fixtures/              # Workplace-service data and setup scripts
│   └── ...                    # Instructions, evaluation material and package metadata
└── final.json                 # Release acceptance record
Evaluation
The CLE main experiment evaluates 120 tasks in a fixed serial order, retaining the agent's harness state across tasks. Each level is graded when submitted and passes only when every rubric item is satisfied. Passing unlocks the next level. A failure after the submission budget is exhausted ends that task; unreached levels count as failed.
- Trial 1: one submission per level, without diagnostic feedback.
- Trial 2: a failed first submission receives feedback identifying unmet rubric categories, followed by one opportunity to revise and resubmit.
The full CLE results below use these metrics:
| Metric | Definition |
|---|---|
| Completion | Levels cleared divided by all 600 levels, expressed as a percentage. |
| L1–L5 | For each level k, the percentage of the 120 tasks whose first k levels are all cleared. L5 is full-task completion. |
| Gain | Trial 2 completion minus Trial 1 completion, in percentage points. |
CLE Lite runtime
The Quick Start runs one task through all five levels, then grades the collected deliverables. It uses the grader archived with the task and verifies its identity, dependencies, and task files. It reports an all-checks task reward, a check fraction, per-level pass results, and a post-hoc count of consecutive passing levels from t1.
This runtime example does not reproduce the full main-experiment protocol. It does not implement the main experiment's per-level feedback and resubmission, stop-on-failure execution, or serial evaluation across tasks with retained harness state. The example also uses GPT-6.1-Sol for model-based grading; the paper's main experiment uses DeepSeek V4 Flash. Its check fraction and post-hoc gated count should be reported as Lite runtime diagnostics, separately from the full CLE leaderboard.
Keep rubrics, reference answers, and grader files outside the evaluated agent's workspace. The evaluation guide explains result fields, control rules, regrading, and the verified example run.
Full CLE results
These results cover the full CLE benchmark: 120 tasks and 600 levels. They are reproduced from the project README. Scores for the 20-task CLE Lite subset are not reported in these tables.
The full CLE evaluation compares 17 configurations spanning 11 model variants and 4 harnesses: Claude Code, Codex, Hermes-Agent, and OpenClaw. Each row identifies the model and its harness; results reflect the complete configuration.
Trial 1 allows one submission per level. Trial 2 adds diagnostic feedback after a failed submission and one opportunity to revise.
Completion Rate
Ranked by Trial 2 completion across all 600 levels.
| Rank | Model | Harness | Completion Rate |
|---|---|---|---|
| 🥇 | Claude Opus 5 | Claude Code | 47.67% |
| 🥈 | Claude Sonnet 5 | Claude Code | 40.17% |
| 🥉 | Gemini 3.7 Flash | Hermes-Agent | 33.67% |
| 4 | GPT-5.6-Sol | Codex | 33.17% |
| 5 | GPT-5.6-Terra | Codex | 33.17% |
| 6 | Doubao-Seed-Evolving | Hermes-Agent | 30.00% |
| 7 | DeepSeek V4 Pro | Hermes-Agent | 27.33% |
| 8 | Hy3 | Hermes-Agent | 27.33% |
| 9 | Qwen3.8-Max | Hermes-Agent | 26.67% |
| 10 | GPT-5.6-Luna | Codex | 25.33% |
| 11 | Gemini 3.7 Flash | OpenClaw | 24.00% |
| 12 | GLM 5.3 | Hermes-Agent | 24.00% |
| 13 | Doubao-Seed-Evolving | OpenClaw | 21.17% |
| 14 | Qwen3.8-Max | OpenClaw | 19.83% |
| 15 | Hy3 | OpenClaw | 14.00% |
| 16 | GLM 5.3 | OpenClaw | 11.50% |
| 17 | DeepSeek V4 Pro | OpenClaw | 10.00% |
Gain
Ranked by Trial 2 − Trial 1, in percentage points. Ties are ordered by Trial 2 completion, then model name.
| Rank | Model | Harness | Gain (pp) | Trial 1 | Trial 2 |
|---|---|---|---|---|---|
| 🥇 | Claude Sonnet 5 | Claude Code | +13.17 | 27.00% | 40.17% |
| 🥈 | Doubao-Seed-Evolving | Hermes-Agent | +9.67 | 20.33% | 30.00% |
| 🥉 | Gemini 3.7 Flash | Hermes-Agent | +8.33 | 25.33% | 33.67% |
| 4 | Hy3 | Hermes-Agent | +7.00 | 20.33% | 27.33% |
| 5 | Doubao-Seed-Evolving | OpenClaw | +6.67 | 14.50% | 21.17% |
| 6 | Claude Opus 5 | Claude Code | +5.50 | 42.17% | 47.67% |
| 7 | DeepSeek V4 Pro | Hermes-Agent | +5.50 | 21.83% | 27.33% |
| 8 | GPT-5.6-Sol | Codex | +5.33 | 27.83% | 33.17% |
| 9 | GPT-5.6-Terra | Codex | +5.33 | 27.83% | 33.17% |
| 10 | Gemini 3.7 Flash | OpenClaw | +5.33 | 18.67% | 24.00% |
| 11 | GLM 5.3 | OpenClaw | +5.33 | 6.17% | 11.50% |
| 12 | GPT-5.6-Luna | Codex | +5.00 | 20.33% | 25.33% |
| 13 | Hy3 | OpenClaw | +4.17 | 9.83% | 14.00% |
| 14 | Qwen3.8-Max | OpenClaw | +1.67 | 18.17% | 19.83% |
| 15 | GLM 5.3 | Hermes-Agent | +1.50 | 22.50% | 24.00% |
| 16 | Qwen3.8-Max | Hermes-Agent | +1.00 | 25.67% | 26.67% |
| 17 | DeepSeek V4 Pro | OpenClaw | −1.33 | 11.33% | 10.00% |
Explore the interactive leaderboard → · Download results (CSV)
Data sources and terms
Task inputs draw on public source data and documents. The people, organisations, and correspondence used to frame the scenarios are fictional. Third-party materials retain their original terms; consult each package's NOTICE.md and PROVENANCE.md for sources, permissions, and retrieval details.
To preserve the benchmark for evaluation:
- Do not include the tasks or reference material in training corpora.
- Do not expose evaluation rubrics or reference answers to an agent being evaluated.
- Do not publicly redistribute the rubrics or reference answers.
Questions and contributions
Use GitHub Issues for setup questions, documentation improvements, and reproducibility reports. Include the task directory, level, dataset revision, and relevant error message so the maintainers can reproduce the issue. Keep evaluation answers and private reference material out of public reports.
The project repository tracks release milestones. The CLE Team page lists contributors.
Citation
If you use CLE Lite, cite the CLE manuscript with this provisional citation:
@misc{cle2026continual,
  title  = {Continual Learning Exam},
  author = {{CLE Team}},
  year   = {2026},
  note   = {Manuscript},
  url    = {https://haoyu-zhao.github.io/CLE/}
}
Please also identify CLE Lite, the dataset revision, model, and evaluation harness used in your experiments.
- Downloads last month
- 1