

Adversarial Gradient Forcing for Robust Few-Step Autoregressive Video Generation
Paper • 2610.14553 • Published
Robust Few-Step Autoregressive Video Generation
Zhejiang University · Alibaba Group · Nanjing University


AGF improves long-video generation by training models to withstand adversarial perturbations in their generated history. Trained on five-second rollouts, it supports generation up to four minutes with the same four-step sampler.
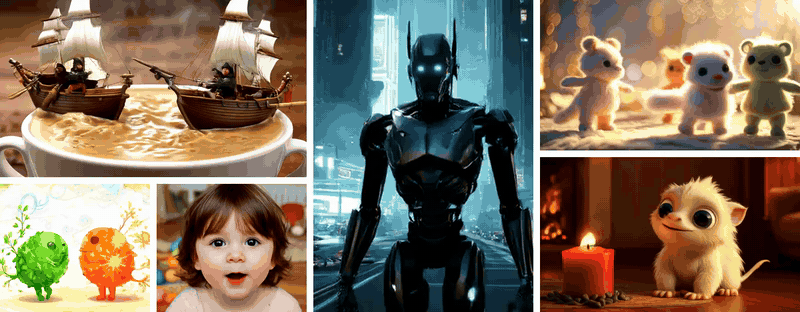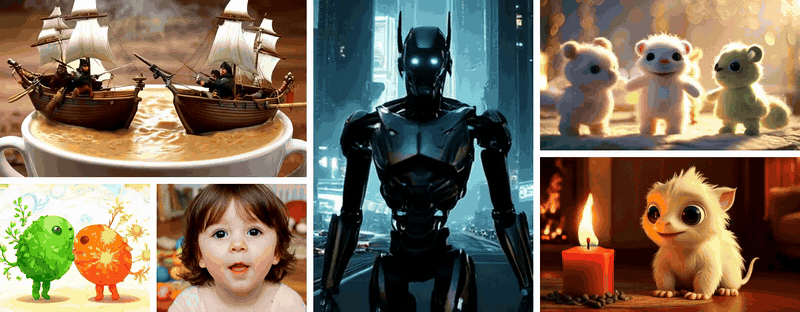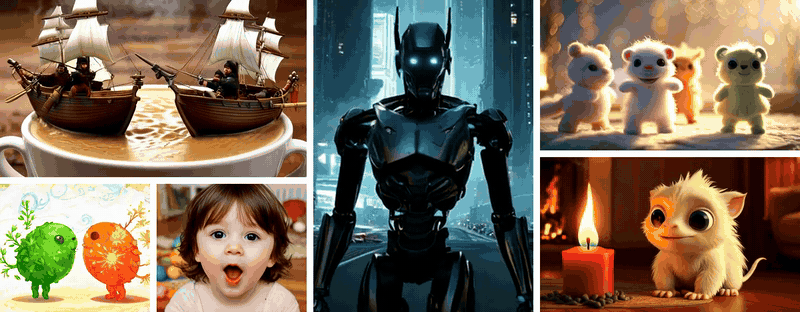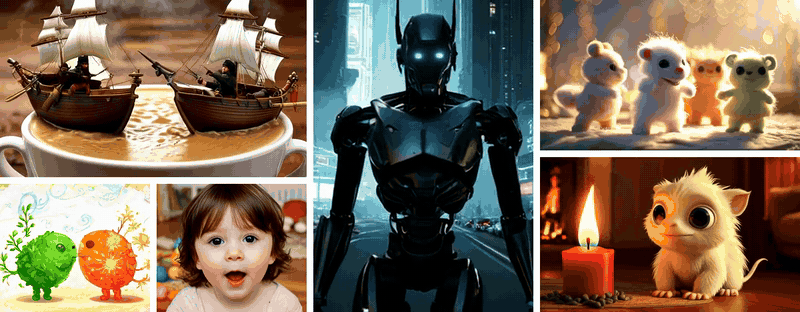
Generated with AGF · Selected video excerpts
| 1.3B Wan2.1 backbone |
4 steps Denoising per block |
Up to 4 min Video generation |
AGF selects adversarial history perturbations using distribution-matching gradients from later video blocks, then trains jointly on clean and perturbed histories. A first-step prediction consistency regularizer helps preserve scene structure during the initial training stage.
| Property | Paper checkpoint |
|---|---|
| Architecture | Wan2.1 1.3B autoregressive video generator |
| Initialization | Self-Forcing ODE initialization |
| Training | 200 regularized AGF + 200 pure AGF outer iterations |
| Selected weights | Global step 400, generator_ema |
| Training rollouts | 5 seconds; effective batch size 64 |
| Training prompts | Filtered, LLM-extended VidProM prompts used by Self-Forcing |
| Inference | 832 × 480, 16 fps, four denoising steps per block |
Iterations count outer training loops; the full schedule contains 80 generator updates.
The paper checkpoint is available as model.pt (17.03 GB). Download it with the Hugging Face CLI:
hf download Wuli-art/Adversarial-Gradient-Forcing model.pt \
  --local-dir checkpoints/AGF
Follow the installation and inference guide for the Python/CUDA environment and Wan 1.3B assets. Place the downloaded checkpoint at checkpoints/AGF/model.pt and run from the code repository root:
AGF_RUN_ID=preview bash scripts/infer.sh \
  --checkpoint checkpoints/AGF/model.pt \
  --prompts prompts/examples.txt --latent-frames 21 --gpus 0
The script selects generator_ema by default, matching the paper. Use --latent-frames 21, 240, or 960 for approximately 5 seconds, 1 minute, or 4 minutes. The default policy uses 12 latent frames of local attention, including 3 persistent sink frames, with relative sink positions enabled. See the training guide for the full training and checkpoint-resumption workflow.
Paper results under the shared evaluation protocol (higher is better). The 5-second and 60-second evaluations use 944 and 240 VBench prompts, respectively; the 240-second evaluation uses 120 MovieGenVideoBench extended prompts.
| Model | 5 s · VBench Total | 60 s · VBench Total | 240 s · Quality 5 |
|---|---|---|---|
| AGF | 82.03 | 81.47 | 84.82 |
Quality 5 (Q5) is the arithmetic mean of subject consistency, background consistency, motion smoothness, aesthetic quality, and imaging quality. It excludes dynamic degree and is not an official VBench Total score. See the evaluation protocol for metric definitions and reproducibility details.
AGF is intended for text-to-video generation and research on autoregressive video models. Long sequences may exhibit visual artifacts, motion inconsistencies, or prompt drift.
@misc{xia2026adversarial,
  title         = {Adversarial Gradient Forcing for Robust Few-Step Autoregressive Video Generation},
  author        = {Chenxi Xia and Yixuan Xu and Shan Liu and Jiapeng Wang
                   and Maohua Li and Hanlin Tang and Kan Liu and Tao Lan
                   and Weiyi Lu and Xinggao Liu},
  year          = {2026},
  eprint        = {2610.14553},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CV},
  url           = {https://arxiv.org/abs/2610.14553}
}
License: Apache 2.0. Third-party models, datasets, and other assets retain their respective licenses.
Base model
Wan-AI/Wan2.1-T2V-1.3B