

fragment-1 (v2.29)
A 9.0M-parameter System-One decision model. Give it a state (any text) and typed questions; it returns typed answers with calibrated probabilities in a single forward pass — no autoregression, no text generation, no chain-of-thought, nothing to parse and nothing to hallucinate. Trained entirely from scratch on a 2-thread cloud CPU (own BPE tokenizer, own encoder, own RLCD loop — no pretrained weights, no GPU), which is the point: small enough to run anywhere, including a browser tab.
Live demo → FrameXlabs/fragment-demo — a fully static Space: the model downloads into your browser and every
decide()runs locally. No server, no GPU, nothing leaves your machine.
One name, two versions. This repo keeps the name fragment-1 forever. This release replaced v1 in place — better weights at the same URL, one model, no graveyard:
| version | params | status | notes |
|---|---|---|---|
| v1 | 4.96M | superseded by this release | SST-2 + AG News + Yelp-5 · supervised + RLCD + calibration |
| v2.29 (this checkpoint) | 9.0M | live | adds BoolQ · 326k items · supervised + RLCD + calibration |
The three question types
| type | question | answer |
|---|---|---|
choice |
which of these options? | the option + a probability for every option |
score |
where on this rubric? | expected level + the full distribution |
noul |
is this true? | a single calibrated probability |
Every question in a call is answered in one pass; options and rubrics are defined at request time, so new schemas need no retraining.
Quickstart
The repo ships a self-contained runtime — f2.py (needs only torch + safetensors):
from f2 import Fragment

m = Fragment.from_pretrained("FrameXlabs/fragment-1")  # v2.29 — same name as v1, replaced in place

state = "Hi, we were billed twice for March. Please refund the duplicate today."

questions = {
    "urgency": {"type": "score", "instructions": "How urgent is this request?",
               "criteria": ["not urgent", "soon", "critical or blocking"]},
    "refund": {"type": "noul",
               "instructions": "Does the user explicitly request a refund?"},
}

res = m.decide(state, questions)
print(res["answers"]["refund"]["noul"])   # calibrated P(yes)
print(res["answers"]["urgency"]["score"]) # expected level + level distribution
Architecture
| Type | System-One typed-decision model (non-autoregressive) |
| Encoder | 6 bidirectional pre-norm transformer blocks, d=256, 4 heads, ff=1024 |
| Decision head | per-position logit head; softmax over @option marker tokens |
| Params | 8,982,785 (9.0M) |
| Context | 192 tokens (input text is budgeted so the options always survive truncation) |
| Tokenizer | fragment-bpe-v2 — from-scratch BPE, 16384 vocab |
| Calibration | per-qtype temperature scaling on held-out data |
| Format | [CLS] <instruction> input: <state> options: @0 ...; @1 ... [SEP] |
Training: supervised warmup + RLCD
- Supervised warmup — cross-entropy on the gold marker over 326k typed items built from SST-2, AG News, BoolQ and Yelp Review Full, with instruction paraphrases and choice-option shuffling (anti position-bias). bf16 autocast, AdamW, cosine schedule.
- RLCD (gated improvement program) — reinforcement learning for calibrated decisions: GRPO-style Gaussian logit-noise exploration (G=6), group-normalized advantage, and strictly proper scoring rules as reward (log score for choice/noul; RPS for ordinal score questions). Honest probabilities are the unique reward maximiser. Every RLCD round is gated by the held-out benchmark and promoted only when it beats the incumbent checkpoint — v2.29 ships the warmup + calibration checkpoint.
- Calibration — per-question-type temperature scaling fitted on a held-out calibration split (NLL for choice/noul, RPS for score).
Evaluation (held-out: official validation/test splits, never trained on)
| task | n | accuracy | ECE | Brier | RPS |
|---|---|---|---|---|---|
| noul_sst2 | 872 | 0.7878 | 0.0397 | 0.2982 | — |
| noul_boolq | 1000 | 0.612 | 0.0733 | 0.4887 | — |
| choice_agnews | 2000 | 0.8875 | 0.024 | 0.1677 | 0.0456 |
| score_yelp | 2000 | 0.491 | 0.0435 | 0.6214 | 0.1155 |
Summary: {"noul_acc": 0.6939, "choice_acc": 0.8875, "score_acc": 0.491, "avg_acc": 0.6907, "avg_ece": 0.0451}
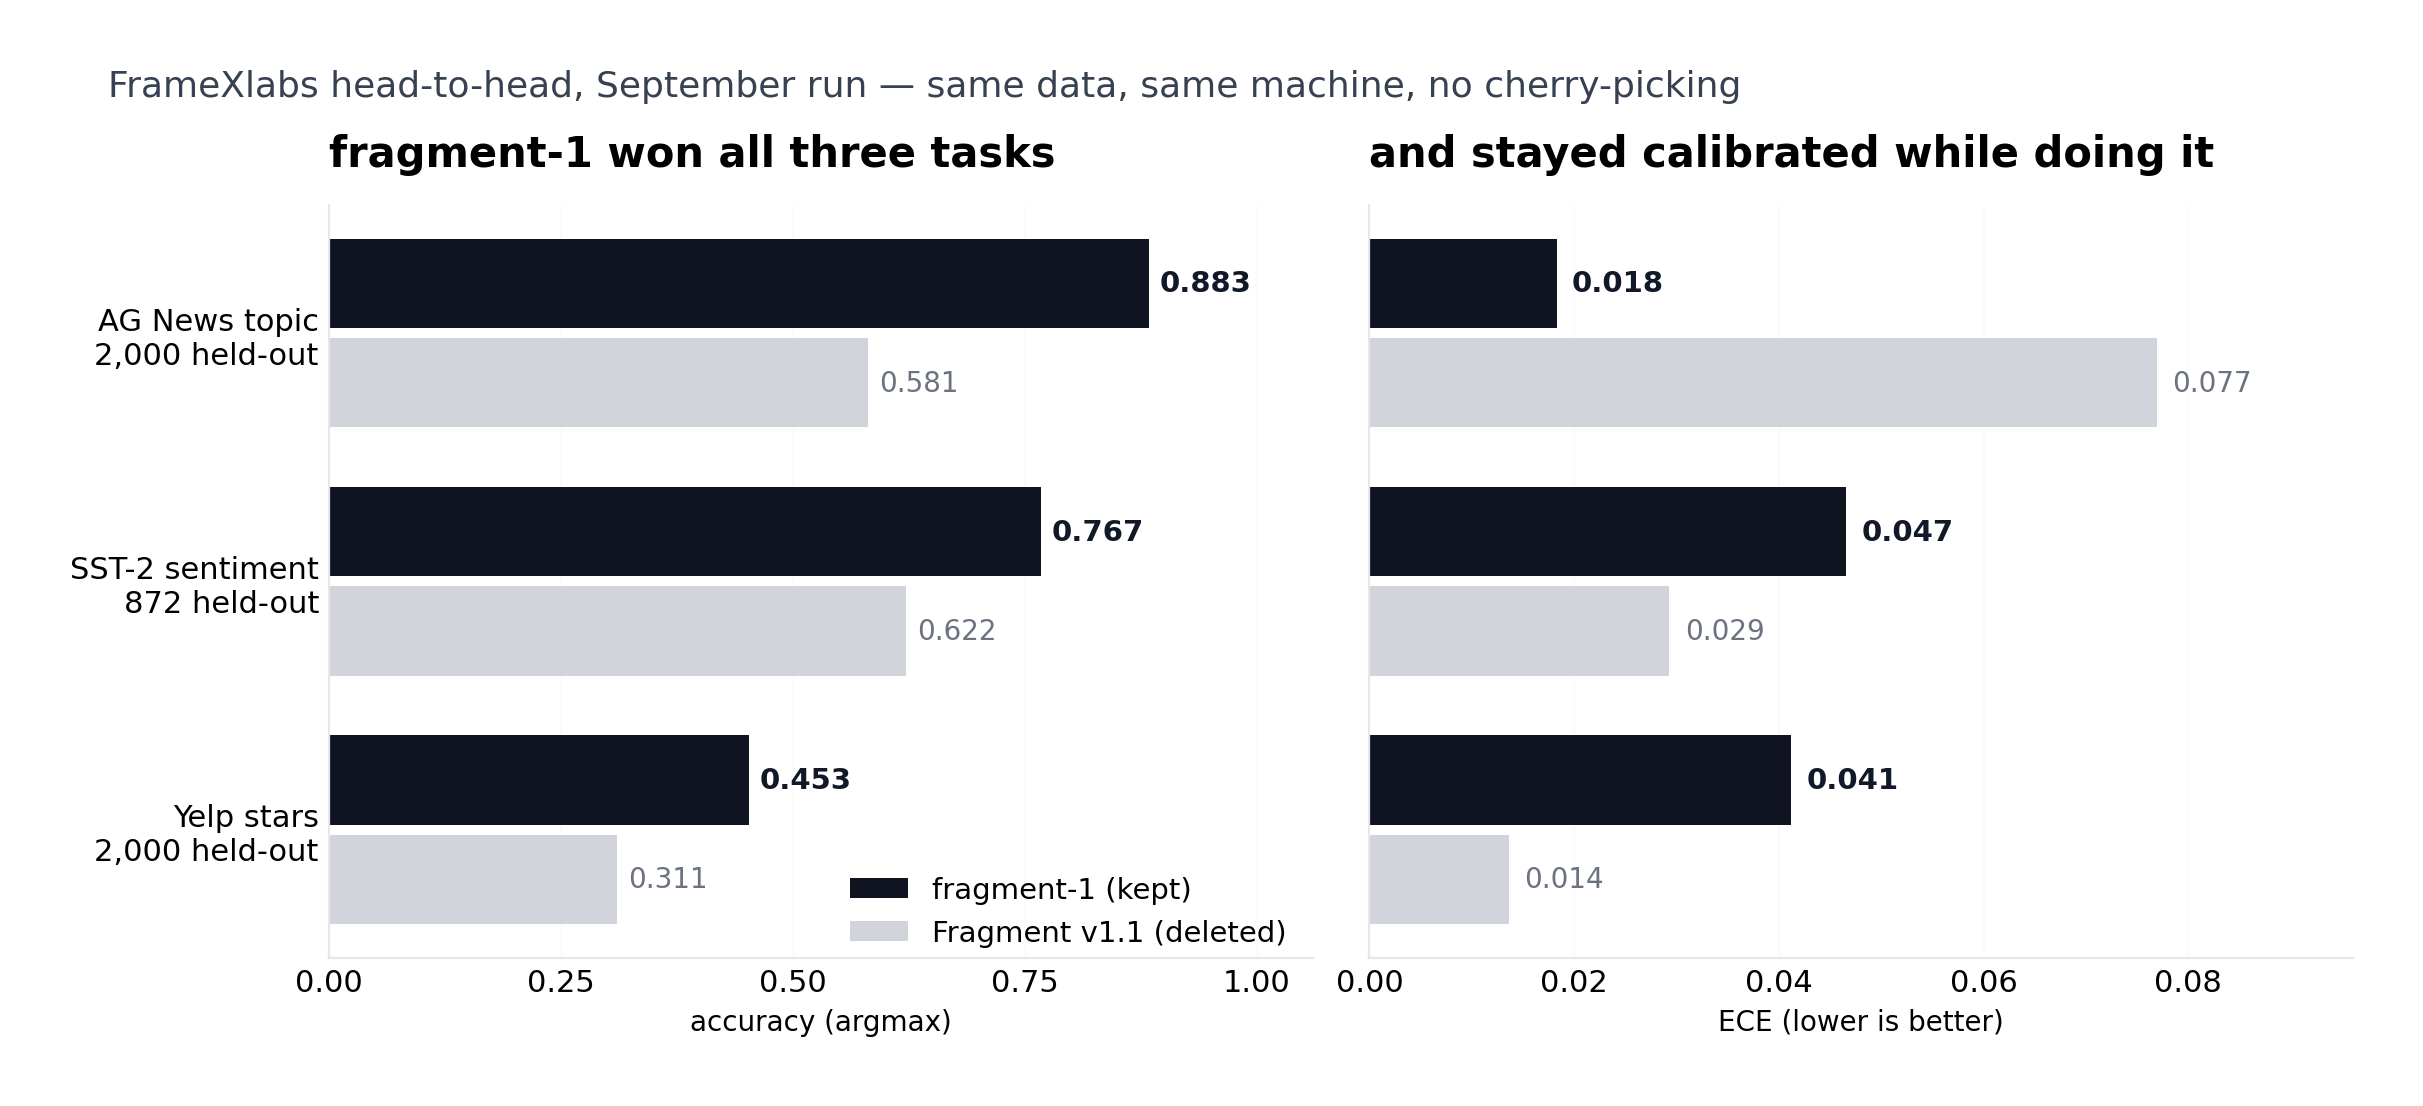
Reference points on the same protocol: fragment-1 v1 (the previous release under this same name, superseded in place by v2.29) reached 0.70 average accuracy and the deleted weak model 0.50. fragment-1 v2.29 measures 0.6907 — level with v1 overall, ahead of it on the weakest primitive (score: 0.491 vs 0.453), with the tightest calibration in the family (ECE 0.0451) and +20% context (192 vs 160 tokens). Laya (ModernBERT-large, 421M params, ~47x larger) remains stronger in absolute terms; gated improvement rounds keep running against the benchmark.
Honest limits
- Four in-domain task families only: SST-2-style sentiment, AG News-style topics, BoolQ-style reading-comprehension yes/no, Yelp-style ratings. Not a general NLU system.
scoreis the weakest primitive — ordinal rubric questions stay hard at this scale; calibration on them is what RLCD + temperature scaling target.- Out-of-distribution text degrades quietly: watch the probabilities, gate on them, and fine-tune before trusting picks in a new domain.
- English only. No instruction-following, no generation. It makes decisions.
Links
- GitHub: https://github.com/aryanthegamedev3465-collab/Fragment (runtime, benchmarks, pipeline)
- Live demo: https://huggingface.co/spaces/FrameXlabs/fragment-demo (runs in your browser)
- Benchmarks: BENCHMARKS.md
Apache-2.0 · FrameXlabs — students with no GPUs.