
 # UIGEN-X-8B — Streamlined UI Generation
Tesslate's optimized UI model, built for direct and efficient code generation. Optimized for popular web develpment stacks such as:
React Ecosystem
- React + Tailwind CSS: shadcn/ui, NextUI, DaisyUI, Headless UI, Flowbite React, Tremor, Park UI, Catalyst
- React Standalone: Material-UI (MUI), Ant Design (AntD), Chakra UI, Mantine, PrimeReact
- Meta Frameworks: Next.js, Remix, Vite, Create React App
Vue.js Ecosystem
- Component Libraries: Vuetify, PrimeVue, Tailwind CSS direct integration
- Meta Framework: Nuxt.js
- Styling: Material Design, comprehensive component suites
Angular Enterprise
- Libraries: Angular Material, PrimeNG, ng-bootstrap
- Styling: SCSS, CSS, Bootstrap integration
- Framework: Angular CLI with enterprise-grade state management
Supported Frameworks: React, Vue.js, Angular, Svelte, Vanilla JS, and more
Styling Engines: Tailwind CSS, Material-UI, Emotion, Bootstrap, SCSS, CSS-in-JS
Component Libraries: 50+ including shadcn/ui, NextUI, Vuetify, Angular Material
Demos
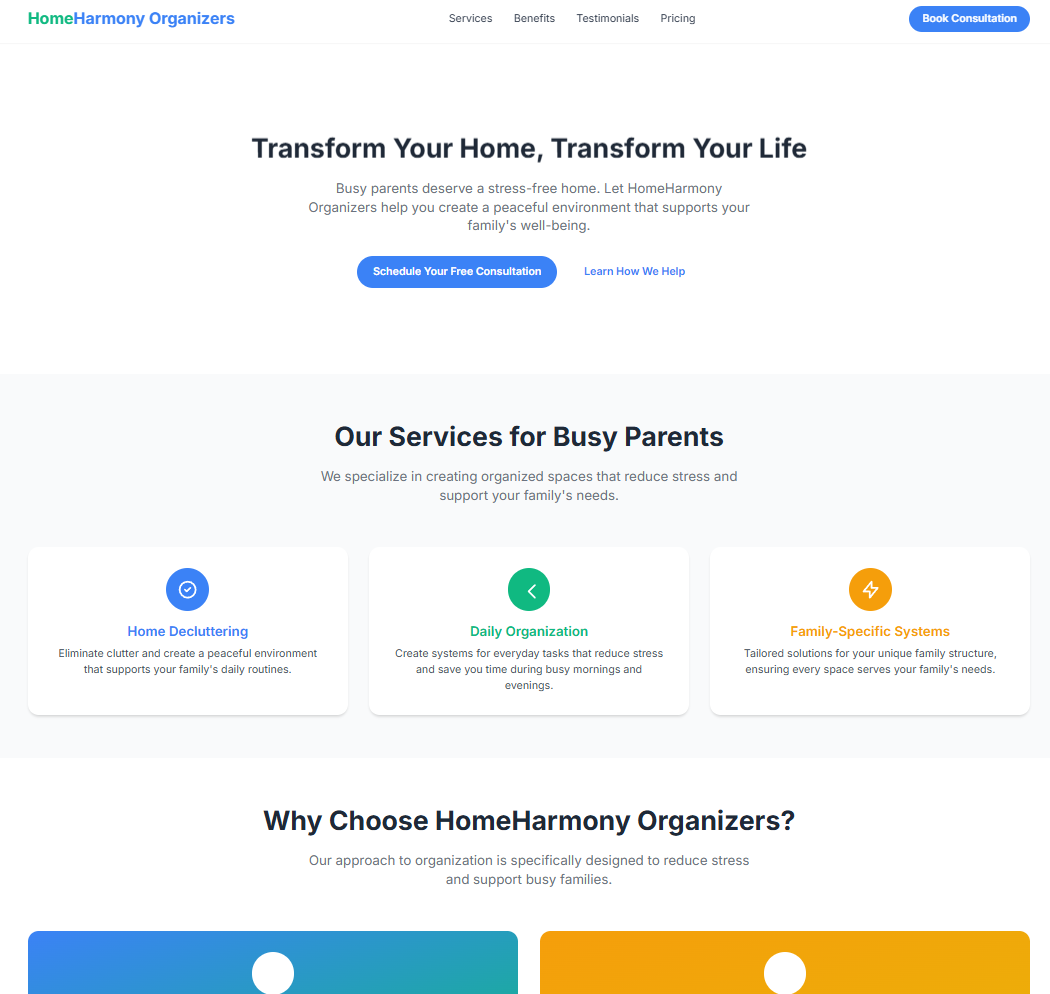
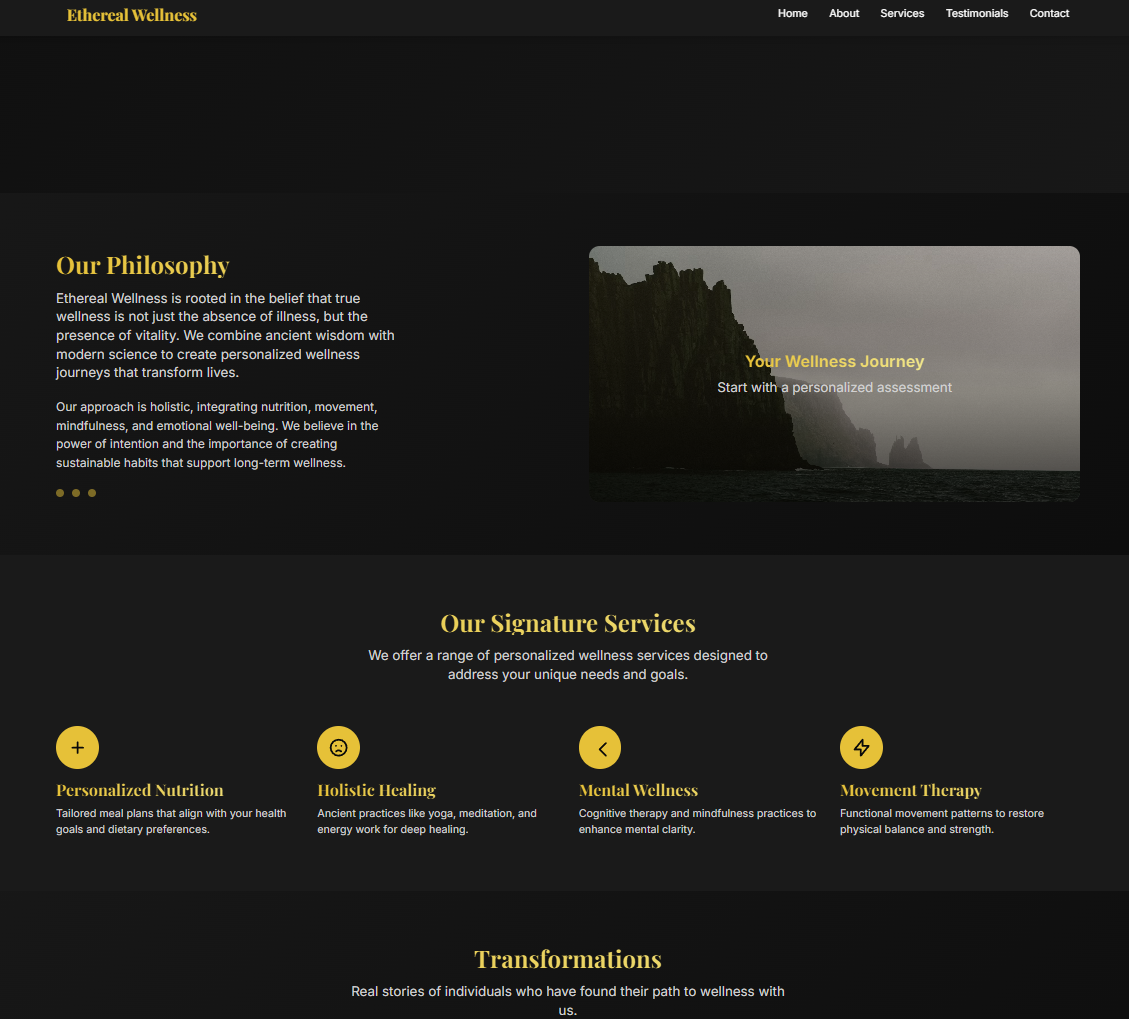
Explore New UI generations: 📂 https://uigenoutput.tesslate.com
Join our Discord: https://discord.gg/GNbWAeJ4 Our Website: https://tesslate.com
Quick Information
- UI generation model built on Qwen3 architecture
- No-reasoning variant for faster, direct code generation
- Supports both components and full web pages
- 116 web tech stacks supported across React, Vue, Angular, Svelte, and more
- Most popular stacks: React+Tailwind (27 variants), Material-UI ecosystem, Vue+Nuxt
- Streamlined output: Pure HTML and Tailwind CSS without reasoning overhead
- Powered by UIGenEval, a first-of-its-kind benchmark for UI generation
- Released under Apache 2.0 license for research and commercial use
Model Details
- Base Model: unsloth/Qwen3-8B-unsloth-bnb-4bit
- Reasoning Style: No reasoning (direct generation)
- Tokenizer: Qwen default, with design token headers
- Output: Components + Full pages (with
<html>,<head>) - Images: User-supplied or placehold.co – no images in the dataset due to licensing concerns
- License: Apache 2.0 (permissive commercial use)
Architecture System
UIGEN-T3.1-8B-Full-Demo-No-Reasoning was trained using a streamlined architecture optimized for direct code generation.
Unlike hybrid reasoning variants, this model focuses on:
- Direct code generation → Fast, efficient HTML/CSS output without reasoning blocks
- Consistent formatting → Standardized structure for production-ready code
- Optimized inference → Reduced latency compared to reasoning-enabled models
Outputs include design tokens at the top of each generation for easier site-wide customization.
Inference Parameters
For optimal performance with this no-reasoning variant:
| Parameter | Value |
|---|---|
| Temperature | 0.6 |
| Top P | 0.95 |
| Top K | 20 |
| Max Tokens | 40k+ |
Evaluation: UIGenEval Framework
UIGenEval is our internal evaluation suite, designed to bridge the gap between creative output and quality assurance. (Learn more in our upcoming paper: "UIGenEval: Bridging the Evaluation Gap in AI-Driven UI Generation" - August, 2025)
UIGenEval evaluates models across four pillars:
- Technical Quality — Clean HTML, CSS structure, semantic accuracy
- Prompt Adherence — Feature completeness and fidelity to instructions
- Interaction Behavior — Dynamic logic hooks and functional interactivity
- Responsive Design — Multi-viewport performance via Lighthouse, Axe-core, and custom scripts
This comprehensive framework directly informs our GRPO reward functions for the next release.
Example Prompts to Try
Design a multi-vendor marketplace homepage with live product carousels, seller spotlight cards, and a dynamic filters sidebar using React + Next.js + Tailwind CSS + shadcn/ui. Include loading skeletons and dark mode support.Generate a subscription management dashboard for a SaaS product (with plan comparisons, usage analytics, billing history, and upgrade modal) in Vue + Nuxt.js + Vuetify. The dashboard should support both admin and user views.Build an enterprise-grade analytics dashboard with filterable data tables, export buttons, real-time chart widgets (Tremor + Recharts), and user management features. Use React + Next.js + Tailwind CSS + Tremor. Add role-based sidebar navigation and mobile responsiveness.Create a healthcare metrics dashboard with multi-level drill-down, interactive graphs, and secure login using Angular + Angular Material + SCSS. Support light/dark themes and modular cards.Design a customizable headless CMS editor panel (fields: text, images, rich embeds, SEO settings) in SvelteKit + Tailwind CSS + Skeleton UI. Embed drag-and-drop section reordering and inline editing.
Use Cases
| Use Case | Description |
|---|---|
| Rapid Prototyping | Quick UI mockups without reasoning delays |
| Production Templates | Clean, ready-to-use HTML/Tailwind components |
| Batch Generation | Efficient processing of multiple UI requests |
| API Integration | Streamlined for REST API and automated workflows |
| Educational Tools | Teaching HTML/CSS without complex reasoning explanations |
Limitations
- No reasoning explanations — Pure code output without design rationale
- Limited complex logic — Best suited for UI structure, not interactive features
Technical Requirements
- GPU: ≥8GB VRAM for 8B inference
- Libraries:
transformers,torch,unsloth - Python: 3.8+
- Compatible with Hugging Face inference APIs and local generation pipelines
Community & Contribution
- Join our Discord: https://discord.gg/GNbWAeJ4
- Chat about AI, design, or model training
- Want to contribute UIs or feedback? Let's talk!
Citation
@misc{tesslate_UIGEN-X,
  title={UIGEN-X: Efficient UI Generation model built on Qwen3},
  author={Tesslate Team},
  year={2025},
  publisher={Tesslate},
  note={Non-commercial Research License},
  url={https://huggingface.co/tesslate/UIGEN-T3}
}
- Downloads last month
- 767
1-bit
2-bit
3-bit
4-bit
5-bit
6-bit
8-bit
16-bit