
Bedrock-RL: a deterministic Minecraft framework for training and benchmarking VLM agents


Minecraft is close to an ideal testbed for embodied vision-language agents: open-ended, spatial, and full of long-horizon tasks with programmatically verifiable outcomes. Historically, however, it has been a challenging environment to optimize RL in. The Java client is slow, non-deterministic, and hostile to parallel rollouts, so most prior work settled for behavior cloning on human video.
bedrock-rl fixes the plumbing. It couples Netherite, a deterministic C/CUDA reimplementation of the Minecraft simulation, with verl for distributed RL, and wraps both in a framework of replaceable components. You define a world and its reward once in YAML, generate reproducible seed-disjoint train/dev/test episodes, and train a VLM with GRPO, RLOO, REINFORCE++, ReMax, GSPO, SFT, SDFT, SDPO, or on-policy distillation, all against the same unchanged verifier.
Everything is a component
There is no registry, no plugin API, and no fork. Every piece of an experiment is a package.module:object import path selected in YAML, and each layer only depends on the layer below it (architecture tests enforce the import directions):
| Layer | What you replace | Example |
|---|---|---|
| Task | world reset, instruction, budgets, reward | success: {type: my_project.rewards:ReachedStructure, config: {block: beacon, radius: 6}} |
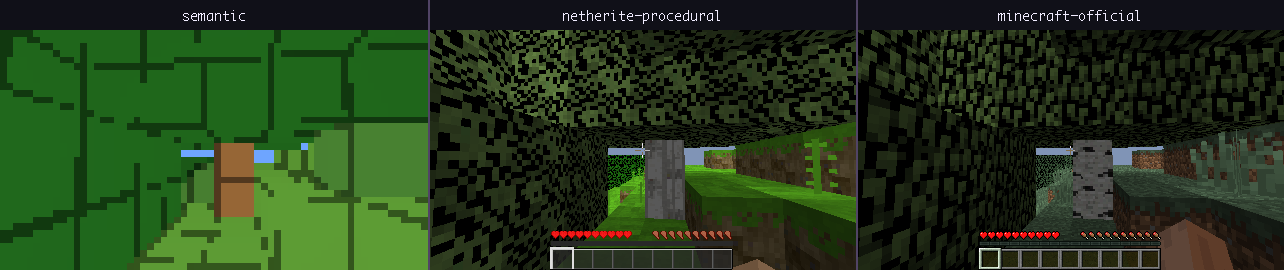
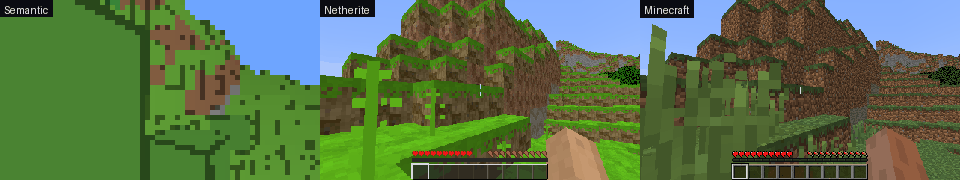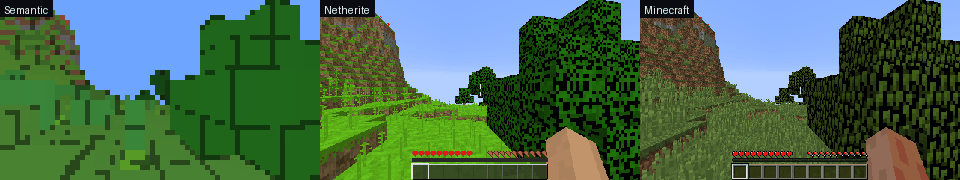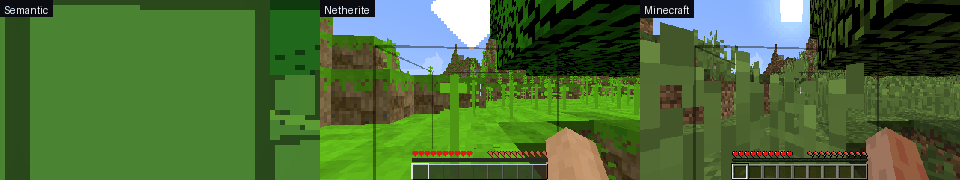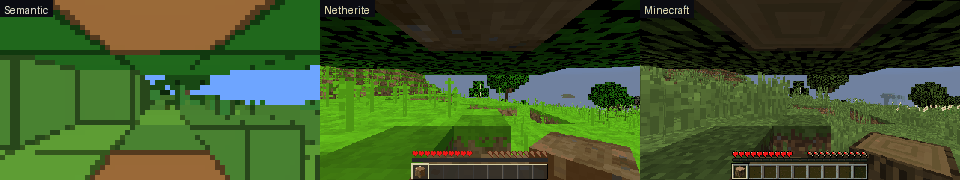
| View | the pixels the model sees | view: semantic / netherite-procedural / minecraft-official / your renderer |
| Tools | what the model can call | NetheriteComputerTool plus my_project.tools:RecipeBookTool |
| Context | how history is shown | KeepLastImages, KeepLastTurns, or your own policy |
| Guidance | private per-turn hints for a teacher | StaticGuidance, TurnHinter, or custom |
| Data | sampler, qualifier, policy, executor, writer | RandomCases / SeedCases / CaseFile; ProcessExecutor / Modal scout; ParquetWriter / TrajectorySFTWriter |
| Model | any supported VLM family | qwen3-vl-2b, a Hub id, a local checkpoint, a LoRA dir; new families are one ModelSpec |
| Trainer | the learning method | rl / sft / sdft / sdpo / opd / mopd |
Swap one row and nothing else moves. A new reward check reads the live engine; a new tool is a name, an OpenAI function schema, and execute; a new scripted expert subclasses MinecraftController or SurvivalPolicy and gets hazard avoidance, pickups, and GUI crafting for free; a new objective is a stage graph in SurvivalProgressionSpec. Navigation, crafting, mining, combat, redstone, GUI, building, memory tasks, teacher-student setups with a different tool set for the teacher: all of them are YAML plus, at most, one small Python module you own. The included examples are demonstrations of the framework, not built-in assumptions.
A complete task:
name: farm_one_log_sdg
goal: Find a nearby tree, harvest one natural log, and collect it.
initial_state:
  spawn:
    constraints:
      - {block: log, min_distance: 4, max_distance: 12}
success: {type: item_gained, item: log, count: 1, reward: 1.0}
Synthetic data
A generation job is task + sampler + qualifier + policy + executor + writer. Scripted survival experts plan from each natural world's snapshot and emit the same computer actions the model will emit. The executor runs isolated C-engine episodes across every CPU, or across a Modal fleet as a headless seed scout followed by exact pixel replay on a smaller machine. The writer keeps only trajectories that passed the unchanged task verifier, publishes parquet and a rejection ledger atomically, and every row carries the world seed, decision seed, snapshot hash, and provenance needed to reproduce it.
One design point we care about: a scripted expert can see the whole voxel map, a frame-only VLM cannot. Policies declare per-turn grounding, and the SFT writer refuses privileged decisions (for example, a clairvoyant route to underground iron) by default. Behavior-cloning targets are only actions the model could have inferred from what it saw.
Training
trainer |
Method |
|---|---|
rl |
GRPO, RLOO, REINFORCE++, or ReMax advantages, with vanilla or GSPO policy loss (distributed via verl) |
sft |
supervised on verified successes, full causal image history, LoRA/QLoRA/DeepSpeed |
sdft |
on-policy self-distillation from demonstrations (EMA teacher, forward KL at visited states) |
sdpo |
self-distilled policy optimization with static or per-turn private guidance |
opd / mopd |
on-policy distillation from one or several routed teachers |
Switching trainers never changes the reset, tools, pixels, or verifier. Sibling RL rollouts share the same world and hotbar, so the group-relative advantage compares decisions at the same state instead of folding world difficulty into the baseline.
Worked example
examples/equip_pickaxe_grpo randomizes all nine hotbar items and asks Qwen3-VL 2B to press the number key for the iron pickaxe. GRPO from the unmodified base, no warm start, ten steps, every checkpoint evaluated on 288 frozen dev prompts:
| Policy | Dev success (temp 0) | pass@3 (temp 1) |
|---|---|---|
| Base | 27/288 (9.4%) | 31/288 (10.8%) |
| GRPO step 10 | 39/288 (13.5%) | 64/288 (22.2%) |
The single-attempt gain is not statistically conclusive (paired exact ); the pass@3 gain is (37 fixed, 4 regressed, ). We ship it as an end-to-end pipeline check with raw records and seed-clustered intervals, not a benchmark claim. The sealed test split was not opened because no dev checkpoint earned it. bedrock eval enforces that discipline: paired trials on frozen prompts, Wilson and seed-clustered CIs, exact paired tests, test sealed until selection.
uv sync --extra netherite --extra data
uv run bedrock setup --runtime-only
uv run bedrock generate examples/equip_pickaxe_grpo/data.yaml --check
uv run bedrock train examples/equip_pickaxe_grpo/train.yaml --dry-run
The same manifest launches on Modal with --modal --gpu H100, with durable resumable run directories and multinode support.
Come build with us
We built bedrock-rl to train agents and we want all the help we can get. Issues, tasks, and PRs welcome: github.com/michaelbf16/bedrock-rl.


